Supermemory: a hosted memory API, an MCP server and a 0.0.x local binary
Memory and context engine + app that is extremely fast, scalable, and can be run fully locally. The Memory API for the AI era.
At a glance
- What is it?
- supermemoryai/supermemory is an MIT-licensed TypeScript monorepo for a memory and context engine, reachable three ways: plugins and an MCP server for AI tools, an npm and pip API for builders, and a curl-installed local binary. This piece separates what each route needs and what each one cannot do.
- Who is it for?
- Use Supermemory if you want persistent memory in Claude Code, Cursor or Codex through a hosted MCP URL, or a single API call for memory plus RAG in your own app. Hold off on the local binary for anything critical until you have checked a 0.0.x release yourself, and treat the benchmark claims as the vendor's numbers until you have read the research page and run your own recall test.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
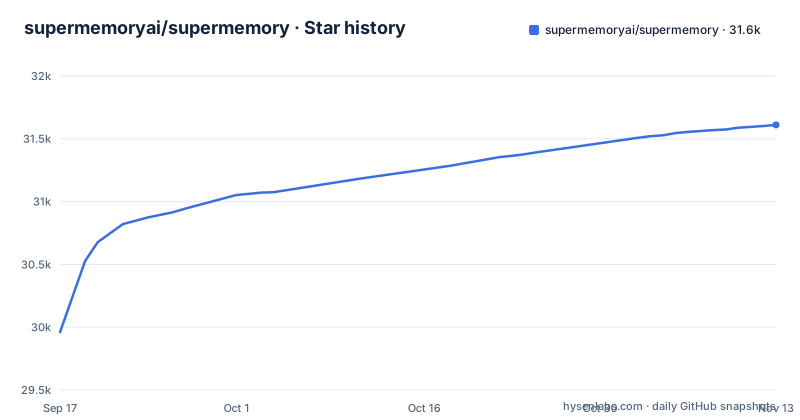
- supermemoryai/supermemory31,611 ★ · +1,651
| Repository | 2026-09-17 | 2026-11-13 |
|---|---|---|
| supermemoryai/supermemory | 30k | 31.6k |
1,651 Stars in the last 57 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One engine, three doors, and each door has a different dependency
The repository describes Supermemory as a memory and context layer for AI. It says it extracts facts from conversations, builds user profiles, handles knowledge updates and contradictions, forgets expired information, and also covers RAG, connectors and file processing. The top of the README then splits readers into three groups.
People who use AI tools are pointed at plugins or the MCP server. People building products are pointed at an API installed from npm or pip. People who want to run it themselves are pointed at a one-line installer for Supermemory Local. The practical consequence is that these are not three views of the same deployment. The MCP route needs the hosted URL, the API route needs the SDK and a client, and the local route needs a binary on your machine. Pick the door first, because the failure modes differ.
The MCP config is only a URL, so it cannot work without reaching mcp.supermemory.ai
The manual MCP configuration is short enough to quote in full:
{
  "mcpServers": {
    "supermemory": {
      "url": "https://mcp.supermemory.ai/mcp"
    }
  }
}
There is no command, no arguments and no local process in that block. Your client connects to a remote address. If your editor runs offline or behind a network that blocks that host, the memory tools will not load, and the config gives you no local fallback. The listed clients are Claude Desktop, Cursor, Windsurf, VS Code, Claude Code, OpenCode, OpenClaw and Hermes.
The server exposes three tools. memory saves or forgets information and is called automatically when you share something worth remembering. recall searches memories by query and returns relevant memories plus a user profile summary. context injects your full profile, meaning preferences and recent activity, at the start of a conversation. In Cursor and Claude Code you can type /context to trigger it.
Container tags are the only isolation boundary between work and personal memory
Memory is scoped with projects, which are container tags. The README suggests using them to separate work and personal context, or to organize by client or repo. The same idea shows up in the API example, where content is stored with containerTag set to user_123.
The consequence is that separation is something you configure, not something you get. If two clients or two repos share one tag, they share one memory pool, and recall can surface facts from either. The tool descriptions say the AI decides on its own when something is worth remembering, so a loose tag choice means personal preferences and client details can end up in the same profile. Decide your tag scheme before the first conversation, so you never need to untangle a mixed pool afterwards.
The plugins live in seven other repositories, not in this one
The plugins for Claude Code, Muse Code, Cursor, Codex, OpenClaw and OpenCode each have their own repository under the supermemoryai organization: claude-supermemory, muse-supermemory, cursor-supermemory, codex-supermemory, openclaw-supermemory and opencode-supermemory. The Hermes integration is a Supermemory memory provider inside NousResearch/hermes-agent. The README calls them implementations of the Supermemory API and says they are open source.
That has two consequences. Issues and release notes for a plugin are in its own repository, so a quiet commit history here says nothing about the plugin you actually installed. And the plugin you choose is a separate piece of software with its own version, so check that repository's last push before you rely on it. This repository itself was last pushed on 2026-11-02 and is not archived.
The API route: install, a containerTag, and one call for profile plus memories
Builders install the SDK with a single line that covers both ecosystems:
npm install supermemory # or: pip install supermemoryThe quickstart imports Supermemory from the supermemory package, constructs a client, and calls client.add with a content string and a containerTag. A following call returns the user profile together with relevant memories in one request. The pitch is that you skip vector database configuration, embedding pipelines and chunking strategies.
What comes with the API is wider than memory. Connectors listed are Google Drive, Gmail, Notion, OneDrive and GitHub, synced with real-time webhooks. The extractors handle PDFs, images with OCR, videos with transcription, and code with AST-aware chunking. Search is hybrid, combining RAG and memory in one query. If you only need a key-value store of user preferences, this is far more surface than you asked for, and you pay for that surface in an extra dependency on a hosted service.
Supermemory Local is installed by piping a script into bash, and its releases are 0.0.x
The self-hosting entry point is this command:
curl -fsSL https://supermemory.ai/install | bashThe README pitches it as one binary, zero config, with any model you bring, or fully offline with Ollama. Two cautions follow from the repository itself. First, piping a remote script into a shell runs whatever that URL serves at that moment, so read the script before you run it on a machine that matters. Second, the releases are numbered server-v0.0.9 (published as Supermemory Local 0.0.9 on 2026-10-12), server-v0.0.9-rc.3 on the same day, and server-v0.0.8 on 2026-08-17. A 0.0.x version number is a signal to expect change between releases, so pin what you install and re-test recall after upgrades.
The README also links a self-hosting overview in the docs. The binary is the local route, not a replacement for the hosted MCP URL in your client config.
The headline benchmark numbers are the project's own claims
The README opens with a claim of first place on LongMemEval, LoCoMo and ConvoMem, plus 95% Recall@15 with a 99.4% context reduction and roughly 50ms user profiles. It links a research page for the details. Those figures are published by the project about itself, and this article did not run any benchmark or measure any latency.
For a decision, that means two things. A benchmark rank on public datasets does not tell you how recall behaves on your own conversations, where contradictions and expired facts look different. And the 50ms figure is attached to the profile call, so it does not cover a slow connector sync or a large file extraction. Run a small recall check with your own data before you commit, and read the research page rather than relying on the badge line.
Building the monorepo needs bun 1.3.6, Node 20 or newer, and a stack tied to Cloudflare and Postgres
The root package.json is private and names [email protected] as the package manager, with Node at version 20 or above. Workspaces cover apps/* and packages/*, and Turborepo drives the scripts: build runs turbo run build, dev runs turbo run dev, dev:local runs turbo run dev:app, and check-types runs turbo run check-types. Formatting goes through bunx biome check --write. A postbuild step uploads Sentry sourcemaps, so a plain build expects sentry-cli to be available.
The dependency list shows what the server side is built from: Hono with zod validation and OpenAPI tooling, drizzle-orm with pg and postgres, better-auth, alchemy and the cloudflare client, and AI SDK providers for Anthropic, Google, OpenAI and Cerebras. The top level also holds AGENTS.md, CLAUDE.md, CONTRIBUTING.md and a skills directory. Contributors should expect a Postgres and Cloudflare-flavoured setup rather than a single-file service, and the build alone will not give you a running memory server without the rest of that stack.
Editorial conclusion
Use Supermemory if you want persistent memory in Claude Code, Cursor or Codex through a hosted MCP URL, or a single API call for memory plus RAG in your own app. Hold off on the local binary for anything critical until you have checked a 0.0.x release yourself, and treat the benchmark claims as the vendor's numbers until you have read the research page and run your own recall test.
Frequently asked questions
What is Supermemory?
Supermemory is a memory and context engine for AI that extracts facts from conversations, builds user profiles, handles contradictions and forgetting, and also provides RAG, connectors and file processing. The repository is MIT-licensed TypeScript.
Can Supermemory be self-hosted?
Yes, through Supermemory Local, installed with curl -fsSL https://supermemory.ai/install | bash. The README says it can run with any model or fully offline with Ollama, and the latest release listed is server-v0.0.9.
how to install supermemory
For the API, run npm install supermemory or pip install supermemory. For AI tools, add the MCP URL https://mcp.supermemory.ai/mcp to your client config or use a plugin, and for a local binary use the curl installer.
is supermemory open source
The repository is licensed under MIT. The README also says the client plugins are open source and that the MCP server source is available.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/supermemoryai-supermemory)Star history chart for your README
[](https://hysenlabs.com/projects/supermemoryai-supermemory)Was this useful?