SwanLab can store the log file locally and upload it later
⚡️SwanLab - an open-source, modern-design AI training tracking and visualization tool. Supports Cloud / Self-hosted use. Integrated with PyTorch / Transformers / verl / LLaMA Factory / ms-swift / Ultralytics / MMEngine / Keras etc.
At a glance
- What is it?
- SwanLab is a Python library and service for tracking AI training runs, used either against the hosted platform or a self-hosted deployment. What the repository shows is a product surface that keeps widening: more than fifty framework integrations, hardware monitoring for a long list of GPU vendors including several non-NVIDIA ones, two similarly named public APIs about nine months apart, and a Makefile that symlinks documentation skills into a dot directory for coding agents.
- Who is it for?
- SwanLab fits a team training models on hardware the team does not control, especially one running several processes against a single experiment, because parallel logging and custom experiment identifiers arrived together and the complete log file can be stored locally and synced later. It does not fit someone who wants a stable 1.0 API surface to build against today, since the package still classifies itself as alpha development status.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
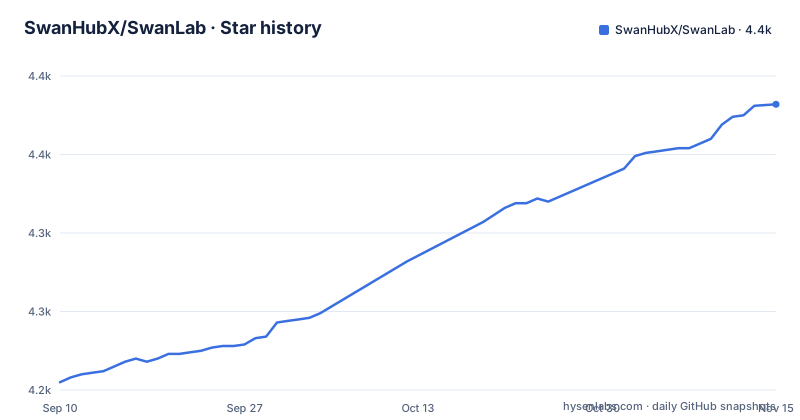
Star history
- SwanHubX/SwanLab4,382 ★ · +177
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| SwanHubX/SwanLab | 4.2k | 4.4k |
177 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Hardware monitoring reaches past NVIDIA to seven other vendors
The dependency list contains a direct NVIDIA management library alongside a system metrics library, which means GPU telemetry is part of the client rather than something bolted on later.
The changelog then shows how far that reaches. Support is recorded for AMD ROCm and an Iluvatar GPU in January 2026, a Hygon DCU in June 2025, a MetaX GPU in the same month, Moore Threads in May 2025, a Cambricon MLU in March 2025 and a Kunlunxin XPU in April 2025. Seven vendors besides NVIDIA, each arriving as its own dated entry with its own integration.
The SDK was rewritten for logging throughput in June 2026
On 2026.06.05 the changelog records a refactored SDK at version 0.8.0, with the stated purpose of greatly improving metric recording performance and making large scale training a better experience. The same entry adds a command line interface and a Skill, both aimed at what the entry calls the AutoResearch paradigm.
The Skill lives in a separate repository under the same organisation, and the entry links a documentation page for the command line API. So the project is extending past a library into an agent-facing surface, and treats both as first class.
Notice the version arithmetic. The newest SDK version named anywhere in the changelog is 0.8.0, while the newest release is v0.10.3. The changelog is a feature log rather than a version log, so it is the wrong place to look for which version you have.
Fifty framework integrations, most contributed from the other side
The README pitches integration with more than fifty mainstream frameworks, and the repository description names PyTorch, Transformers, verl, LLaMA Factory, ms-swift, Ultralytics, MMEngine and Keras among them.
The changelog fills in the shape of that claim. HuggingFace Transformers integrated in March 2025 for versions from 4.50, credited to a pull request into that project. Ray and ROLL in July 2025. accelerate in June 2025, again as a pull request into the other project. AREAL in June 2025. PaddleNLP, MLX-LM and SpecForge through 2025. NVIDIA NeMo RL in December 2025. EvalScope in April 2025, framed as a joint integration for evaluating large model performance.
The pattern matters. Several of these are changes made inside somebody else's repository, and those entries link pull requests into the other project. The cost of that approach is that an integration can lag behind a breaking change upstream, and the changelog gives you no way to tell which ones have.
Two public API surfaces, one letter apart, seven months apart
Two API announcements sit in the same changelog with almost identical names.
On 2025.05.14 the entry adds an open interface named with the letters OpenApi after the package prefix. On 2026.02.06 another entry says the object-oriented open API is officially available, described as more powerful, with a documentation page for the Python API.
So for about nine months the project advertised one open interface and then shipped a differently named one with the claim of being stronger. Nothing in the changelog says the earlier name is retired, and both are described as open interfaces.
For anyone writing integration code this is the first thing to resolve, because the two names are easy to confuse and the documentation page linked from the newer entry is the only pointer to a specific one. The package metadata gives you no hint either: its description is generic, covering streamlined tracking and management of AI training processes.
The log file is written locally and uploaded when you can
The entry from 2025.06.08 adds the option to store the complete experiment log file locally, then upload local log files to the cloud or to a private deployment with a sync command.
Two later entries harden that path. In July 2025 the sync command gained better compatibility with log file integrity, explicitly adapted to scenarios where training crashed. In March 2026 a parallel mode arrived, allowing metrics to be recorded into the same experiment from different processes, and at the same time experiment identifiers became customisable.
Together those are the design for distributed training: many writers, one experiment, a durable file on disk, and an upload step that can happen after the fact.
The Makefile symlinks documentation skills into a dot directory
One build file feature is unusual enough to read closely. Two variables set the source and the destination: skills live under a docs directory and are linked into a dot directory reserved for agents.
The linking recipe refuses to run at all if the source directory is missing, creates the destination, then walks each skill in turn. For each one it checks whether the target already exists and is not a symlink, and refuses to replace it, because a real directory sitting there would be destroyed by a blind link. The removal recipe deletes only things that are symlinks, which is the other half of that guarantee.
The target list and the protobuf recipe look like this:
.PHONY: init sync format proto unit bench clean build publish backport link-skills unlink-skills relink-skills core-lint core-fmt core-test core-build core-tidy

proto:
	uv run scripts/generate_protos.py
Two more recipes guard themselves rather than trusting the caller. The backport recipe refuses to run unless a pull request number and a release branch are both supplied, and its error prints the expected form plus a worked example with a numbered pull request and a branch under v0.8. The init recipe syncs all extras and installs the pre-commit hooks. A set of core-prefixed targets covers the second package directory.
Alpha in the classifiers, Kubernetes in the docs
The package metadata classifies the project at alpha development status, under an Apache 2.0 licence, requiring Python 3.9 or newer, with classifiers running through 3.14. The readme and the version are both dynamic fields rather than literal values.
Against that, the documentation advertises a Kubernetes deployment path, published in December 2025, and a Prometheus with Grafana option for monitoring and logging on Kubernetes, which went live in June 2026. The readme badges point at Docker Hub, a hosted notebook and PyPI download counts alongside the release and licence shields.
So the same project ships an alpha package and a documented production deployment. That is not necessarily contradictory, since the deployment story belongs to the server side of the service, but it does mean the version of the client you install tells you nothing about the maturity of the platform behind it.
The rest of the tree is consistent with a modern Python project: a lock file, a pre-commit configuration, an editor formatter configuration, a security policy and a separate code of conduct.
Editorial conclusion
SwanLab fits a team training models on hardware the team does not control, especially one running several processes against a single experiment, because parallel logging and custom experiment identifiers arrived together and the complete log file can be stored locally and synced later. It does not fit someone who wants a stable 1.0 API surface to build against today, since the package still classifies itself as alpha development status. Before adopting it, check five things. Which of the two public API surfaces you should call, since an object-oriented one and an earlier open interface were both announced and the names differ. Where your hardware monitoring will come from, because the NVIDIA management library is a hard dependency and every other vendor listed in the changelog arrived as its own integration. Whether you need the hosted service at all, since self-hosting including a Kubernetes deployment is documented. Which release you are on, given that the changelog mentions an SDK at 0.8.0 while the newest release is v0.10.3. And whether local logging plus a later sync fits your training loop, since that is the path the crash compatibility work was written for.
Frequently asked questions
What is SwanLab?
An open source AI training tracking and visualization tool, usable against the hosted service or a self-hosted deployment, aimed at model training teams. The Python library is published on PyPI as swanlab, and the project states that it integrates with more than fifty mainstream frameworks.
How do I keep a SwanLab experiment after a training crash?
The complete experiment log file can be stored locally and uploaded later with the sync command, to the cloud or to a private deployment. That path gained better compatibility with log file integrity for training crash scenarios in July 2025, and since March 2026 a parallel mode lets several processes record metrics into the same experiment.
Which GPU hardware can SwanLab monitor?
Beyond NVIDIA, whose management library is a direct dependency, the changelog records support for AMD ROCm, Iluvatar, Hygon DCU, MetaX, Moore Threads, Cambricon MLU and Kunlunxin XPU, each added as its own integration.
Can I run SwanLab without the hosted service?
Yes. Self-hosting is a documented path, with a Kubernetes deployment page and a Prometheus plus Grafana option for monitoring logs. Locally stored log files can be synced to a private deployment rather than to the cloud.
Which licence is SwanLab released under?
Apache 2.0, declared in the package metadata with the licence file at the repository root. The project keeps four readmes, with the Chinese one alongside English, Japanese and Russian versions.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/swanhubx-swanlab)Star history chart for your README
[](https://hysenlabs.com/projects/swanhubx-swanlab)Was this useful?