The quickstart calculator runs eval on the model's answer
AdalFlow: The library to build & auto-optimize LLM applications.
At a glance
- What is it?
- AdalFlow is a PyTorch-style library for building and auto-optimizing LLM workflows, and its hello world agent is the readable part. The part worth pausing on is the first tool it defines, which passes a string straight to Python's eval. Around that sit a root pyproject that describes a test harness rather than the library, two package names pinned to the same constraint, and a Makefile that formats the entire tree twice.
- Who is it for?
- AdalFlow is worth a look if you want one library covering pipelines, agents and prompt optimization with the tracing and human-in-the-loop parts built in rather than bolted on, and the three call modes give you a clean shape for sync, async and streaming. Two things to check before you copy anything.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 14 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
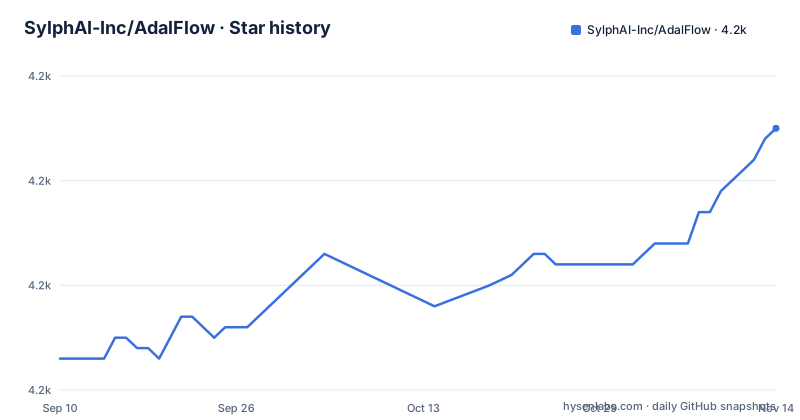
- SylphAI-Inc/AdalFlow4,235 ★ · +22
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| SylphAI-Inc/AdalFlow | 4.2k | 4.2k |
22 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The first tool in the quickstart calls eval on its argument
The hello world agent defines several tools, including a calculator, a web search and a counter, and the first one is short enough to quote in full:
def calculator(expression: str) -> str:
    """Evaluate a mathematical expression."""
    try:
        result = eval(expression)
        return f"The result of {expression} is {result}"
    except Exception as e:
        return f"Error: {e}"
That is a Python evaluator, not an arithmetic parser, and the argument is whatever the model decides to send. In an agent loop the input to a tool is chosen by the language model, which means the example wires a code evaluator into a loop whose input is generated text. The failure path catches exceptions and returns the message as a string, so the model sees the error and can retry, which is friendly behaviour and does not change what the tool does.
The three call modes that follow are worth reading; the calculator tool is an illustration that should be rewritten before it touches anything real.
Three call modes share one result shape
After the tools, the example offers the same runner three ways. The synchronous form takes prompt keyword arguments and returns a result object:
# Sync call - returns RunnerResult with complete execution history
result = runner.call(
    prompt_kwargs={"input_str": "Calculate 15 * 7 + 23 and count to 5"}
)

print(result.answer)
The asynchronous form awaits runner.acall and has a similar output structure. The streaming form asks for a streaming result and then iterates its event stream, checking each event against the run item types imported at the top of the file: a tool call, a tool call activity, and a tool output, each carrying a name or data payload.
The history the sync result exposes is worth noting for anyone building a UI, because it is per step and it names the function:
for step in result.step_history:
    print(f"Step {step.step}: {step.function.name} -> {step.observation}")
So the object carries a step index, the function that ran and what it observed. That is enough to render a trace without instrumenting anything yourself, which is the argument the README makes about not needing a separate service for tracing.
The root pyproject describes a test harness, not the library
The manifest at the repository root is not the manifest of the published package:
[tool.poetry]
name = "adalflow-project"
version = "0.1.0"
description = "A project to develop and test the adalflow library"
authors = ["Your Name <[email protected]>"]
license = "MIT"
Four things follow from those five lines. The project is named for the repository rather than for the library, so anything that reads metadata from this checkout sees a different name than the one on the package index. The version is 0.1.0, which is the version of the harness, not the 1.1.4 that appears in the release history. The description says outright that it exists to develop and test the library. And the author field is still the placeholder text a template ships with.
The library itself enters as a path dependency marked for development, and the packaged directories listed are the use cases, tutorials and benchmarks rather than the library source. The Python requirement is 3.11 or newer, below 4.0.
If you are building on AdalFlow, install the package rather than pointing a build at this repository.
Two package names for the same constraint, and a formatter in the runtime group
The dependency list is where the development harness shows its seams. Two entries sit next to each other with the same version constraint and the same environment marker:
dspy = { version = "^2.6.27", markers = "python_version < '3.14'" }
dspy-ai = { version = "^2.6.27", markers = "python_version < '3.14'" }
Both are installed, and both are gated on the same Python version. Whatever the relationship between the two names, requiring both means one of them is redundant in every environment the marker allows.
The grouping is loose as well. A formatter with the Jupyter extra is listed among the runtime dependencies of the project rather than in the development group, and the same formatter is then listed again in the development group. Most other tools are in the development group where they belong.
The provider coverage is genuinely broad, which is the point of the model-agnostic claim: clients for Anthropic, Groq, Cohere, Ollama, Google, Together, Mistral, Fireworks and OpenAI, plus the OpenAI agents package and an MCP package. Alongside them sit retrieval and evaluation tooling, a vector store extension, a metrics library, an experiment tracker, a charting library and notebook support. Two dependencies, mistralai and fireworks-ai, are pinned to exact versions with no range at all.
The Makefile formats the whole tree, then formats it again
The build entry points are six targets driven through poetry, and two of them are worth reading closely.
format:
	$(PYTHON) black $(SRC_DIR)
	git ls-files | xargs pre-commit run black --files
The source directory variable is set to a single dot, so the first line runs the formatter over the entire checkout rather than over the library package. The second line then runs the same formatter again, this time through the pre-commit hooks, over every file git is tracking. Two passes, two tools with the same name, one of them scoped by a file list.
The lint target has the same shape, checking everything with Ruff, and the test target runs pytest with no arguments, so its scope is decided by the project's test configuration rather than by the Makefile.
The clean target is the tidiest of the set in intent and the most redundant in practice: it removes the pytest cache, the type checker cache and Python bytecode directories, then repeats the bytecode removal with two find expressions, one for directories named for bytecode and one for files ending in that suffix.
The three reasons on the page are research claims
The page argues for the library in three numbered points, and each one has a shape worth reading.
The first is a scope claim: a fully open source agents SDK that is lightweight and needs no additional service to set up human-in-the-loop work and tracing. That is a claim about what is included rather than about performance, and it matches what the quickstart actually shows, since the runner exposes a step history without any external component.
The second is a research claim. The library is described as a unified auto-differentiative framework for both zero-shot and few-shot prompt optimization, and the page attributes the highest accuracy among auto-prompt optimization libraries to two pieces of work, LLM-AutoDiff and Learn-to-Reason Few-shot In Context Learning.
The third is the architectural claim, model-agnostic building blocks that let an application switch models through configuration rather than code, spanning RAG, agents and classical NLP tasks.
The page also states that the library powers an AI coding agent, AdaL CLI,, which is a deployment fact rather than an argument for the design.
A README that is mostly commented-out markup
The source of the README is full of HTML that has been switched off rather than deleted. There is a commented header block, a commented line about who the library is for, a second commented copy of the headline, two commented Colab links including one for a building quickstart and one for an optimization quickstart, a commented download badge for a different package, a commented paragraph claiming the highest accuracy with manual prompting starting at 82 percent, and a commented row of documentation links for models, retrievers, agents and evaluation.
That is not damage, it is editing history, and for a page of this size it is useful context: the emphasis has moved from prompt optimization towards agents, and the old positioning is still sitting in the file a few lines above the new one.
The repository root tells the same story about how the project is worked on. There is a CNAME file for the documentation domain, a notes file, a file describing automatic releases, an environment example file, a pre-commit configuration, a Makefile, a poetry lock file and the usual directories for the library, benchmarks, docs, notebooks, scripts, tutorials and use cases.
The research section opens with a September 2025 paper on robot planning from formal methods feedback, described as fine-tuning-free and built on automatic differentiation of the model calls.
Editorial conclusion
AdalFlow is worth a look if you want one library covering pipelines, agents and prompt optimization with the tracing and human-in-the-loop parts built in rather than bolted on, and the three call modes give you a clean shape for sync, async and streaming. Two things to check before you copy anything. The quickstart's calculator tool evaluates a string with Python's eval, and in an agent the string is something the model produced, so treat that example as a demonstration of tool wiring rather than as something to paste into anything with real access. And the root pyproject is a development harness with a placeholder author field, so install the package from the index rather than by pointing your build at this repository.
Frequently asked questions
What is AdalFlow used for?
Building and auto-optimizing LLM workflows, from chatbots and RAG to agents. It describes itself as a PyTorch-like library and positions itself as an agents SDK that needs no additional service for human-in-the-loop handling and tracing, with model-agnostic building blocks for task pipelines.
How do I install AdalFlow?
The quickstart says to run pip install adalflow, and the examples need an OPENAI_API_KEY environment variable set. The repository root is a development project that pulls the library in as a path dependency and requires Python 3.11 or newer.
Does AdalFlow work with providers other than OpenAI?
The README claims model-agnostic building blocks with a config-level switch, and the hello world example uses the OpenAI client. The development dependencies install clients for Anthropic, Groq, Cohere, Ollama, Google, Together, Mistral and Fireworks, plus the OpenAI agents and MCP packages.
What does the AdalFlow quickstart agent return?
The runner can be called synchronously, awaited, or streamed. The synchronous result carries an answer and a per-step history with a step index, the function name and its observation, while streaming yields typed events for tool calls, tool activity and tool output. The calculator tool in that example evaluates its string argument with eval.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sylphai-inc-adalflow)Star history chart for your README
[](https://hysenlabs.com/projects/sylphai-inc-adalflow)Was this useful?