fast-jev-compaction deletes tool calls instead of summarizing them
Claude Code plugin that replaces the compaction summary with Jev decisions: every tool call and result is scored in one fast request, stale ones are dropped or truncated, everything kept stays verbatim.
At a glance
- What is it?
- A Claude Code function hook and npm library that scores every tool call against a model, drops the ones a session no longer needs, and hands the caller every failure instead of a fallback summary.
- Who is it for?
- Adopt it if your sessions drown in tool output and you can point TypeSafe at the same transcript the agent already has: the pinned tail, the verbatim text and the delete-only rule make it a good fit for read-and-inspect work. Skip it when the bulk of your context is conversation rather than command output, when re-running a tool is expensive, or when a silent fallback to Claude Code's built-in summary would hide a misconfigured key.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 58 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
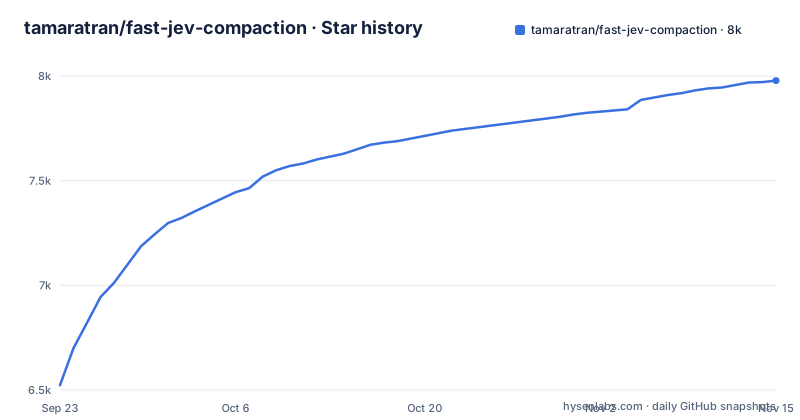
Star history
- tamaratran/fast-jev-compaction7,978 ★ · +1,455
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| tamaratran/fast-jev-compaction | 6.5k | 8k |
1,455 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Every call gets a verdict, and kept text is never rewritten
Most context compaction hands an old transcript to a model and asks for a summary. A summary is lossy by construction: a file path, an exact error, or a constraint such as never edit src/generated can disappear even when it matters three turns later. fast-jev-compaction refuses that trade. It never rewrites anything. It removes only the tool calls and tool results that Jev, the TypeSafe model behind it, says are no longer needed, and whatever survives comes back verbatim and in the original order.
The unit of judgement is the call, not the message. Each `tool_use` is matched to its `tool_result` through `tool_use_id`, and the pair is decided together. Claude Code's built-in compaction, the alternative this project ships a fallback to, works the other way round: it writes new prose standing in for the old turns, so a reader cannot tell which parts were measured and which were inferred.
One request sees the whole conversation, oldest message first. Tool inputs and text go in as they are, and tool results go in as a short note such as `ok, 4213 chars (omitted)`. Nothing is summarized before the decision is made, which is what lets a delete decision be checked against the task instead of against a compressed copy of it.
Pinned calls and the two rebuild invariants
Some calls never enter the scoring loop. Calls in the first message, and calls inside the newest `preserveRecentMessages` messages (6 by default), are pinned and never touched. Everything else is judged.
Decisions resolve against `keepThreshold`, 0.5 by default, in three steps. If `keepResult` reaches the threshold, the call and its result both stay. If the result falls short but `keepCall` clears it, the call stays and the result is cut to its first `truncateHeadChars` characters (300 by default) plus a one-line note, so the command survives and the payload does not. Below both thresholds the call goes with its result.
Rebuilding the list has two invariants worth knowing. A message that loses all of its content is dropped rather than left empty, and untouched messages are returned as the same objects rather than copies, so a caller holding references into the transcript does not have to chase identity changes. The second invariant keeps transcripts valid: no result is ever returned without its call. That one is enforced during the rebuild instead of being left to the scoring step, so a malformed answer cannot produce an orphaned result block.
The state fits in seven ordered stages, then it throws
The state Jev reads has a ceiling: `maxStateTokens`, 25,000 estimated tokens by default. Fitting is staged, and each stage applies only if the previous one was not enough. Tool inputs are truncated to 1000 characters, then 200, then 60. Long texts are abridged to head plus tail, oldest non-pinned messages first. Old non-pinned messages collapse to a `[… N chars omitted …]` note. Old tool calls shrink to one line each, for example `t12 Read file_path=src/a.ts → ok 480ch`. Old call-less messages leave the state entirely, and runs of old call-only messages fold into a single entry.
If the transcript still does not fit after all of that, compaction throws. There is no last-resort truncation and no silent loss of a third of the history.
Token counts come from characters rather than a tokenizer: roughly one word per six letters, half a token per digit, about one per other symbol. The estimate is calibrated to land a little above what Jev reports, so the ceiling errs toward a smaller state. The price is precision. A history can be pushed through fitting stages it did not strictly need, and `result.stats` reports the estimated size, so the number in your logs is likely a little high.
Two questions per call, with the whole state resent each time
Each non-pinned call gets two `noul` questions. The first asks whether the call should stay, knowing it was made, with its input, still mattering. The second asks whether the result should stay verbatim, meaning its contents are still needed and re-running the tool would not do the job. Those are deliberately different questions: a command worth remembering and an output worth keeping are separate decisions, and the second one is what stops a stale `Read` payload from surviving on the strength of a useful command line.
Requests are split so state plus questions stays under `maxRequestTokens`, 30,000 by default, chosen to sit under Jev's 32k request limit. The same full state goes out with every request, the requests run concurrently, and the answers merge back per call. That design has a direct cost. Near the state ceiling a few questions fit per request, so a long transcript becomes many round trips, each paying again to send a state that has already been judged once.
Options move that arithmetic rather than the mechanism. `model` defaults to `jev-latest`, `baseUrl` to `https://api.typesafe.ai/v1/systemone`, and `goal` to the last 3 user prompts so the model carries a description of the task in flight. `apiKey` falls back to `process.env.TYPESAFE_API_KEY`, and `fetch` can be replaced for tests. To send these questions somewhere other than TypeSafe, implement `JevAsker`, a single `ask(state, questions)` method, and call `compact(messages, asker, options)`.
Installing the package, then opting into the function hook
Two install paths ship in one repository: an npm package built from `src/`, and a Claude Code plugin made of `hooks/` and `.claude-plugin/`. The package is what you want when you wire compaction into your own agent. The plugin is what replaces Claude Code's own summary.
The package asks for Node 18 or newer through the `engines` field in package.json, and the key arrives through the environment:
npm install fast-jev-compaction
export TYPESAFE_API_KEY=...
A first call takes a transcript and returns the messages it kept, the decisions behind them and stats on what changed. `Message` is a subset of Claude Code's `SessionMessage`, so a session transcript can be passed in as is:
import { compactMessages, reductionRatio, type Message } from 'fast-jev-compaction';const result = await compactMessages(transcript, { preserveRecentMessages: 4 });Two repository scripts are worth running before you wire anything: `npm run demo` executes `tsx examples/demo.ts`, and `npm run validate:plugin` executes `claude plugin validate .claude-plugin/plugin.json`.
The plugin path has one gate. Function hooks are an early-access feature, so Claude Code 2.1.274 or newer has to be told to allow them, in `~/.claude/settings.json` or wherever Claude Code runs:
{ "env": { "CLAUDE_CODE_ENABLE_FUNCTION_HOOKS": "1", "TYPESAFE_API_KEY": "<your key>" } }Then the marketplace and the plugin, from the shell or as slash commands inside a session:
claude plugin marketplace add tamaratran/fast-jev-compaction
claude plugin install fast-jev-compaction@fast-jev-compaction
What it cannot delete, and what a probability cannot prove
Text is out of scope in both directions. Only tool calls and tool results are candidates. User and assistant text is never removed or shortened in the output, and it is only abridged in the state Jev reads. A session that is mostly prose, a design discussion with three tool calls in it, leaves compaction nearly the length it arrived at, and `reductionRatio` is where you will see that rather than in the token count of your model.
The second boundary is calibration. Decisions are probabilities produced at the request level, and a probability is not proof that a result is safe to delete. The stated counterweight is that the assistant can always re-run the tool. That holds for a `Read` and holds much less well for a migration, a deploy or a `git push`, where repeating the command is not the same operation twice. Nothing in the pipeline separates those tools: `keepThreshold` is one number applied to every call, and the model is never told which calls the session cannot afford to repeat.
Third, both ceilings rest on character estimates, so `maxStateTokens` and `maxRequestTokens` are targets rather than guarantees about what a request contains.
Where it throws, and who chooses the fallback
Four conditions throw instead of returning a partial result: a Jev failure, a malformed answer, a missing key, and a history that cannot be fitted. The library catches none of them. The caller, or the hook, decides what happens next.
`hooks/fast-jev.ts` is that decision in code. It is a thin adapter that feeds `session.compact` transcripts through `src/` and falls back to Claude Code's built-in summary on errors and on reductions it judges too small. So a missing key degrades to the very summarization this project set out to avoid. Configuration for the adapter, plus the Claude Code 2.1.274 type reference, sits in `hooks/README.md`.
The package is MIT licensed and sits at version 0.2.0, with no GitHub releases, so there is no release note to diff and no channel to watch. The last push was on 2026-09-18, on the default branch `main`. Development scripts are conventional: `build` runs `tsc`, `test` runs `vitest run`, and the hook has its own `tsconfig.hooks.json` so adapter type errors surface separately from the package.
Editorial conclusion
Adopt it if your sessions drown in tool output and you can point TypeSafe at the same transcript the agent already has: the pinned tail, the verbatim text and the delete-only rule make it a good fit for read-and-inspect work. Skip it when the bulk of your context is conversation rather than command output, when re-running a tool is expensive, or when a silent fallback to Claude Code's built-in summary would hide a misconfigured key. Verify first that `TYPESAFE_API_KEY` reaches the process and that `result.stats` shows a reduction you consider worth the round trips.
Frequently asked questions
What is compaction in AI agents, and what does fast-jev-compaction replace?
Compaction is the step where an agent shortens an old transcript to fit a context window. Claude Code's built-in version writes a summary of the old turns. fast-jev-compaction replaces that summary with the original messages, deleting only tool calls and tool results that Jev says are no longer needed.
Does fast-jev-compaction rewrite the messages in my transcript?
No. User and assistant text stays verbatim and in order, and only tool calls and tool results are candidates. A call can be kept while its result is truncated to truncateHeadChars, 300 by default, and a dropped result never leaves its call behind.
What happens when fast-jev-compaction fails or cannot fit a long history?
Jev failures, malformed answers, a missing key and a history that cannot be fitted all throw. The Claude Code hook catches that and falls back to Claude Code's built-in summary on errors and on reductions it judges too small.
Can I use fast-jev-compaction with something other than the TypeSafe endpoint?
Implement JevAsker, a single ask(state, questions) method, and call compact(messages, asker, options). buildJevRequest and parseJevResponse give you the request body and the response validation, and collectToolCalls, fitState, batchCalls, decideCall and applyDecisions are exported as well.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tamaratran-fast-jev-compaction)Star history chart for your README
[](https://hysenlabs.com/projects/tamaratran-fast-jev-compaction)Was this useful?