TOON: a lossless JSON encoding for LLM prompts that wins on uniform data and says plainly where it loses
🎒 Token-Oriented Object Notation (TOON) – compact, human-readable serialization of JSON data for LLM prompts. TypeScript SDK, CLI, benchmarks.
At a glance
- What is it?
- Token-Oriented Object Notation (TOON) re-encodes the JSON data model with YAML-style indentation and CSV-style rows, declaring array lengths and field lists in headers. It pays off on arrays and maps of uniform objects; on deeply nested data, purely tabular data or latency-bound local models, its own documentation tells you to use something else.
- Who is it for?
- TOON is a sound choice for feeding LLMs arrays or keyed maps of uniform objects, where its tabular forms cut tokens and its declared lengths and field lists catch truncated output. It is the wrong choice for deeply nested or non-uniform data, where compact JSON often wins, and for purely tabular data, where CSV is smaller.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
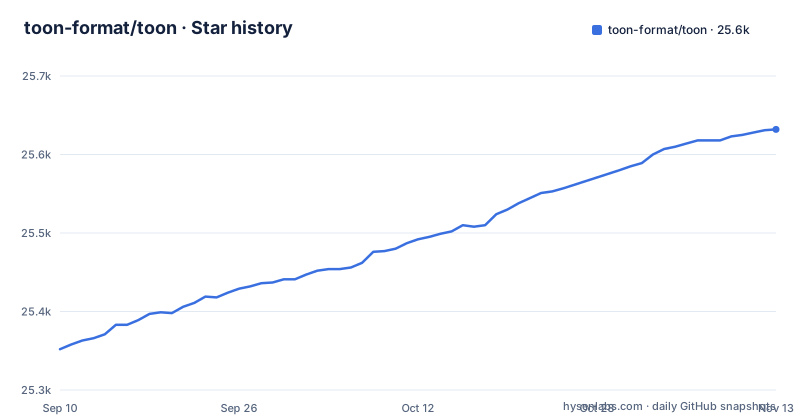
- toon-format/toon25,632 ★ · +280
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| toon-format/toon | 25.4k | 25.6k |
280 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Four forms, chosen automatically from the shape of the data
TOON is a compact, human-readable encoding of the JSON data model. It takes YAML's indentation for nested objects and CSV's rows for uniform data, and the encoder picks one rendering per value based on the data's shape. The project's weather forecast shows three of the mechanisms at once:
location:
  city: Berlin
  country: DE
  units: metric
alerts[2]: frost,wind
forecast[3]{day,temp{min,max},condition,rainChance}:
  Mon,-2,4,snow,80
  Tue,1,7,cloudy,20
  Wed,3,11,sunny,5
`alerts[2]: frost,wind` is inline form, a primitive array written on its header line. `forecast[3]{...}:` is tabular form: the field list appears once in the header and each element becomes one row. Inside that header, `temp{min,max}` is a nested field group, so the uniform nested `temp` objects fold into the header while the rows stay flat.
The same data as JSON comes to about 117 tokens against TOON's 66. The savings come entirely from not repeating keys, braces and quotes for every array element. Anything that fits none of the compact shapes, such as mixed types or non-uniform objects, falls back to list form: one `- ` item per element, or a bare `-` for an empty object. Inline, tabular, keyed tabular and list are the four forms; the Format Overview at toonformat.dev covers the remaining details.
Keyed tabular rows for config maps and records by ID
Arrays are not the only place uniform objects appear. Configuration maps, feature flags and records indexed by ID are objects whose values all share the same fields, and JSON repeats those field names under every key. TOON's third form, keyed tabular, handles this case. A colon after the length marks it, and each row carries its own key in front of the values:
environments[2:]{region,replicas,debug}:
  production: eu-central-1,6,false
  staging: eu-central-1,2,true
In JSON, the same structure is an `environments` object with `production` and `staging` keys, each holding an object with `region`, `replicas` and `debug`. The difference between `[2]` and `[2:]` is therefore significant: the first declares an array of two rows, the second an object with two keyed rows. A reader or a model that ignores that colon will misread the structure.
This form matters for how far TOON's advantage reaches. The project frames its sweet spot as uniform objects with the same fields across items, whether in an array or keyed by ID. Without keyed tabular, a large share of real prompt payloads, from environment configs to lookup tables, would drop to list form and lose most of the savings.
Declared lengths and field lists as guardrails on model output
TOON's headers do more than save tokens. In `forecast[3]{day,temp{min,max},condition,rainChance}`, the `[3]` declares how many rows follow and the `{fields}` list declares how wide each row is. The project's stated purpose for this is that truncated or malformed output cannot slip through: if a model is asked to produce TOON and stops after two rows, or drops a column, the count and the field list no longer match the data.
The format also keeps a strict relationship with JSON. It encodes the same objects, arrays and primitives as JSON, with deterministic, lossless round trips. The intended architecture is a translation layer: your code keeps working with JSON, and you encode to TOON only for the LLM boundary. Nothing upstream or downstream of the prompt needs to change.
These guardrails have a cost that the project states openly. On purely tabular data, TOON carries roughly 5 to 10 percent overhead compared with CSV, because of the declared lengths, field lists and delimiter scoping. That overhead buys reliability, not size. If you only care about the smallest possible payload of flat rows, CSV is smaller; if you care about detecting broken output, the headers are what you are paying for.
Nested, semi-uniform and latency-bound workloads lose the advantage
The project publishes its own list of cases where TOON is the wrong tool, and each has a concrete consequence for anyone considering a migration.
When structures are deeply nested or non-uniform, tabular eligibility is close to 0 percent, and compact JSON often wins outright. Encoding such data as TOON costs you a conversion step and buys nothing, or makes the prompt larger.
When arrays are semi-uniform, with roughly 40 to 60 percent eligibility, the savings shrink. If your pipeline already speaks JSON, the guidance is to stay on JSON rather than add a format for a marginal gain.
When data is purely tabular, CSV is smaller, as covered above.
When latency dominates, the token count is the wrong metric. Some deployments, notably local or quantized models, process compact JSON faster despite its higher token count. The project's benchmarks quantify tokens and accuracy, but latency is the one dimension you have to measure yourself: time to first token and total time, on your own setup. A team running a quantized model on local hardware cannot read TOON's token savings as a speed improvement and should test both encodings before switching.
Measuring the savings on your own payloads with --stats
Because savings depend so heavily on the shape of the data, the useful number is the one from your own payloads, not the weather example. The CLI can be run without installing anything first:
cat data.json | npx @toon-format/cli --statsIt prints the TOON output alongside what the conversion saved. On the weather forecast, the report shows token estimates of about 117 for JSON and about 66 for TOON, a saving of about 51 tokens, or 43.6 percent. The tilde on each figure matters: these are estimates, so treat them as a guide for comparing encodings, not as a billing figure for a particular provider.
The practical use of `--stats` is triage. Run it over a sample of each payload type your application sends. Payloads that are arrays or keyed maps of uniform records will show large savings; deeply nested documents will show little or none, which is the signal to leave them as JSON. Mixing encodings by payload type is consistent with the translation-layer design, since everything round-trips to the same JSON on your side.
The library itself is published on npm as `@toon-format/toon`, and the CLI as `@toon-format/cli`.
Two benchmark tracks so CSV is compared only where it can compete
The benchmarks are split so that every comparison is like for like. The Mixed-Structure Track uses nested and semi-uniform datasets and compares TOON with JSON, YAML and XML. CSV is excluded there because it cannot represent those structures without lossy flattening. The Flat-Only Track uses flat, fully tabular-eligible datasets, where CSV is a fair competitor.
Retrieval accuracy is tested with 244 data retrieval questions across 4 models. The dataset catalog states each dataset's tabular eligibility, which is the number to compare with your own data: uniform employee records with 100 rows at 100 percent eligibility, e-commerce orders with nested structures at 50 rows and 33 percent eligibility with no CSV support, time-series analytics data at 60 rows and 100 percent, and the top 100 GitHub repositories as another uniform set.
The headline claim is that TOON matches JSON's retrieval accuracy with fewer tokens. Read it alongside the eligibility column: the benchmark datasets range from fully uniform to one-third eligible, so the result speaks for data in that range. Results live in `benchmarks/results/retrieval-accuracy.md` in the repository, and the `benchmarks/` directory sits at the top level, so the setup can be inspected and rerun against your own models.
A spec that is stable but explicitly not set in stone
TOON is defined by a specification, `SPEC.md`, maintained in the separate toon-format/spec repository and mirrored at the top of this one. The project describes the format as stable but also an idea in progress, with nothing set in stone, and invites changes through the spec repository. Official implementations and dozens of community ports all target that one spec and share a conformance test suite.
The consequence for adopters is that a format described as open to change needs version pinning. If an encoder in one language and a decoder in another follow different revisions of the spec, the shared conformance suite is what tells you whether they agree, so check that any community port you depend on passes it.
This repository is a pnpm monorepo, `@toon-format/monorepo`, at version 4.4.0, using `[email protected]`. Packages live under `packages/` and are built with `pnpm -r --filter='./packages/**' run build`; tests run with `pnpm -r test`, type checks with `tsc --noEmit`, and the docs site under `docs/` has its own dev, build and preview scripts. Releases are frequent: v4.1.0 on July 26, 2026, v4.1.1 on August 5, 2026, and v4.4.0 on October 8, 2026. The repository is not archived, and the last push was on November 1, 2026.
Editorial conclusion
TOON is a sound choice for feeding LLMs arrays or keyed maps of uniform objects, where its tabular forms cut tokens and its declared lengths and field lists catch truncated output. It is the wrong choice for deeply nested or non-uniform data, where compact JSON often wins, and for purely tabular data, where CSV is smaller. Before switching a pipeline, run the CLI with --stats on your real payloads, measure time to first token on your own model, and pin a version, since the format is described as stable but not set in stone.
Frequently asked questions
What is TOON?
TOON, Token-Oriented Object Notation, is a compact, human-readable encoding of the JSON data model designed for LLM input. It combines YAML-style indentation for nested objects with CSV-style rows for uniform data and round-trips losslessly to JSON.
Is TOON the same as CSV?
No. TOON uses CSV-style rows for uniform data but also encodes nested objects, keyed maps and mixed arrays, which CSV cannot represent without lossy flattening. On purely tabular data, CSV is smaller; TOON adds roughly 5 to 10 percent for declared lengths, field lists and delimiter scoping.
Is TOON an alternative to JSON for LLMs?
Yes, TOON is meant as a translation layer: keep JSON in your code and encode it as TOON for LLM input. It saves the most on arrays and maps of uniform objects, while for deeply nested or non-uniform data compact JSON often wins.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- Build a BPE Tokenizer in 80 Lines of TypeScript and Watch JSON Eat Your Tokensdev.to · Nov 2, 2026 · 3 points · 4 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/toon-format-toon)Star history chart for your README
[](https://hysenlabs.com/projects/toon-format-toon)Was this useful?