TanStack AI versions every package on its own line
🤖 Type-safe, provider-agnostic TypeScript AI SDK for streaming chat, tool calling, agents, and multimodal apps across OpenAI, Anthropic, Gemini, React, Vue, Svelte, and Solid.
At a glance
- What is it?
- TanStack AI is a provider-agnostic TypeScript SDK for streaming chat, tool calls, structured output and agent workflows, published as many small packages. What the page says about itself, and what its build configuration says about the project, pull in two directions: the release list spans versions from zero point one to zero point sixty-three, and the continuous integration runs eleven test targets, three of which inspect the repository rather than the code.
- Who is it for?
- TanStack AI suits a TypeScript team that wants provider choice and typed contracts without adopting a framework, and that already uses the package family's build conventions. Three things to check before you commit.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
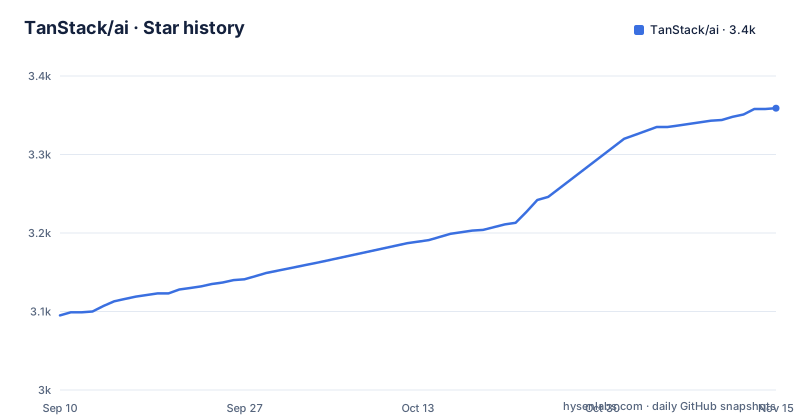
- TanStack/ai3,359 ★ · +264
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| TanStack/ai | 3.1k | 3.4k |
264 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One release, three unrelated version numbers
The three most recent releases are the most informative thing on the page.
They are the core package at zero point sixty-three, a typesafe companion at zero point one point six, and a framework binding for one UI library at zero point twenty-five point three. All three were published on the same afternoon, within about two minutes of each other.
So the release train moves as a unit while the versions inside it do not. That is the normal consequence of a monorepo where each package is published independently: a consumer who takes two of them is combining two version lines, and the only thing that tells them which combination was tested together is the release notes.
The root manifest makes the shape explicit. It is named root, it is private, and it declares the package manager as both a field and an engine constraint. So there is no published package called anything at the root at all; the repository is a workspace of published packages plus the tooling that builds and checks them.
That matters for the upgrade question. There is no single version to pin, which is the price of the composability the page leads with when it says you can import only the part you need and add the rest as your app grows.
Eleven test targets, three of which inspect the repository
The continuous integration command is one long line, and reading it is the fastest way to understand what this project considers finished.
It runs the mobile test suite, then forces the JavaScript test runner to a single worker, then asks the build tool to run eleven targets, then runs a final declaration-file scan. The single-worker setting is the first detail worth noting: the suite is deliberately serial.
Of the eleven targets, eight are the ones you would expect, covering the library, the types, the build, documentation, linting, an unused-code check, a dependency-consistency check and a maintainer check. Three are not.
One verifies links in the documentation. One scans for dangling type declaration files, which is the failure mode where a build emits a declaration that nothing imports. And one is an AI review.
The dependency check is run with two explicit exceptions carved out, one for the TypeScript package and one for a specific client library. So the rule is real and the exceptions are declared rather than hidden.
That is a project that treats repository hygiene as testable: links rot, exports go unused, declarations go stale, and all three are cheap to check in CI and expensive to discover in a release.
Six agent and editor configuration directories at the root
The root listing is where this repository is most unusual, and the count is what matters.
There is a single-agent directory, a plural one, a directory for one assistant tool, a plugin directory for the same tool, a plugin directory for a different tool, and a directory for a third. Alongside them sit a file telling one tool which paths to ignore, two instruction files at the repository root, and a configuration file for an automated review service.
So a project whose product is a TypeScript SDK ships configuration for at least four different coding agents, in at least five shapes, and expects that configuration to be committed and maintained.
That is a coherent response to a real change in how software gets written, and it costs something: each directory is a place where conventions can drift, and a contributor updating one set of rules has to know the others exist. The instruction files at the root are the part that generalises, since those are the files a tool reads whether or not it came from the plugin.
It also explains the skills section, which is the page's answer to the same problem from the user's side rather than the repository's.
The skills are a user-level install with a migration skill
The agent skills section opens with an instruction rather than a description: teach your coding agent about this project before you write a line of code.
The mechanism is that the skills are user-level. You install them once, and then in every project your agent recommends this SDK, works out which package covers the task, installs it, and loads that package's own skill file through a separate intent tool.
Three install paths are given. Two slash commands handle the two named assistant tools, adding a plugin marketplace and installing the plugin from it. A single command with a global flag and two skill names handles any agent, and the two names are the general one and a migration one.
The migration skill is the detail that says something about the project's expectations. It is shipped and named in the install command, which means arriving from a different SDK is treated as a first-class path rather than an accident.
Inside a project, one more command wires the installed packages' skills into the team instruction files for everyone, which is the point of the whole mechanism: the agent's knowledge is versioned next to the code rather than living in one person's home directory.
Streaming leaves as server-sent events, and the transport is swappable
The smallest complete example on the page is a request handler, and it shows three decisions.
You import a chat function and a provider adapter from two packages. You call the chat function with an adapter and the caller's messages. And you wrap the returned stream for delivery, using a helper that turns it into a server-sent events response.
The adapter is the provider seam. It is constructed with a model identifier, and the samples pin one specific recent model, so the examples are written against a named model rather than a placeholder.
The choice of server-sent events as the default transport is a real constraint, and the page addresses it by linking a separate documentation section on connection adapters. So the streaming shape is a default rather than a commitment.
What the framework does not do is hide the response object. The handler parses the request body itself, passes the messages through, and returns a response it constructed, which means an application can insert its own headers, its own authentication and its own error handling between the model call and the browser.
One tool contract, then a server or client implementation
The tools example is the one to read if you are building an agent, because it is the smallest illustration of the contract shape.
A tool is defined once with a name, a description, an input schema and an output schema, and then an implementation is attached. The example attaches a server implementation that takes the validated input and returns rows from a catalogue.
Both schemas are declared, not just the input. That is the part that pays off later: the caller knows what the tool returns, so an agent that loops over several tools gets typed results rather than a bag of strings.
The page then links three documents, and their titles describe the maturity of the feature set. One is the tools guide. One is a tool approval flow, which implies that a tool call can be gated rather than executed. And one is lazy tool discovery, which implies the catalogue of tools can be fetched as needed rather than shipped in the prompt.
So the tool system is designed around three problems that agent frameworks usually leave to the application: what a tool returns, whether a call may proceed, and how the model learns what exists.
Structure can come from four schema libraries or from plain JSON
The structured output example passes a schema to the chat call and gets a typed object back instead of freeform text. The example builds the schema with one validation library, and the feature list widens that.
Four libraries are named as interchangeable front ends, plus plain JSON Schema as the floor. That is an unusual position to take: rather than mandating one validation library, the project accepts the common ones and the schema-only case.
The same pattern appears in the media section, where one generation pattern covers image generation, text to speech, transcription, summarisation, audio, video and world generation. Seven capabilities under one call shape.
Realtime voice has its own pattern with adapters for realtime sessions and for token minting, which is the part that matters operationally: a browser needs a credential to open the audio stream, and the SDK takes responsibility for minting it rather than leaving it to the application.
The last item is the one to think hardest about. Code Mode lets a model write and execute TypeScript inside a secure isolate in order to orchestrate tools with loops, branches and parallel calls, and there is a second guide on giving that isolate reusable runtime capabilities.
An isolated TypeScript runtime executing model-written code is a much larger surface than calling a function, and the two example applications, one running in a worker and one in a browser sandbox, are the closest thing the page offers to evidence that it works.
Nineteen examples and a page that compares itself to a competitor
The examples directory has nineteen applications, and the list is a coverage matrix rather than a gallery.
There are chat examples for six UI libraries, including one written with no framework at all, plus variants for media, reranking, search, group chat, an agent interface, and three server frameworks. There is an example for a protocol integration and two sandboxes, one for a serverless edge runtime and one for a browser sandbox.
Those two sandboxes are the evidence for the Code Mode claim in the previous section. A feature that lets a model write and execute TypeScript needs somewhere to run it, and the page points at a browser sandbox and an edge runtime as the two shapes it has been demonstrated in.
The install section is three commands long and the middle one is the recommended shape. The core package plus one provider adapter:
pnpm add @tanstack/ai @tanstack/ai-openaiAdding a UI binding means adding a client package and a framework package alongside them. And the third option is a third-party key aggregator, which the page recommends as a good starting point if you want access to many providers through one key.
So the documented starting point is an aggregator rather than a model vendor, which tells you where the project thinks most evaluations begin.
Then there is the comparison page, which sets this project against a named competing SDK by architecture, feature coverage and tradeoffs. Publishing that is unusual in a README and it is the page's own answer to the question a reader would otherwise ask.
The last configuration detail is worth knowing before you clone. The clean-everything script removes all untracked and ignored files while excluding only environment files, so it will delete build output, local caches and anything else your machine has accumulated.
Editorial conclusion
TanStack AI suits a TypeScript team that wants provider choice and typed contracts without adopting a framework, and that already uses the package family's build conventions. Three things to check before you commit. Pin the individual packages you take rather than the set, because their version numbers do not track each other. Read the install section rather than the feature list, because the documented starting point is a third-party key aggregator rather than a model vendor. And decide early whether you want the agent skills installed, since the page's own recommendation is to install them once per user and wire them into your team instruction files before writing code.
Frequently asked questions
What is TanStack AI?
It is a type-safe, provider-agnostic TypeScript SDK for building streaming chat, tool-calling agents, structured outputs, realtime voice, media generation and framework-native applications. It is built from composable activities and provider adapters, so you can start with one provider and import only the pieces your app needs.
What licence is TanStack AI under?
The repository is MIT licensed. Questions about a table component or about a separately named product are not covered by this repository, which holds the SDK packages and their build tooling.
How does TanStack AI deliver a streaming chat response?
The chat function takes a provider adapter and the caller's messages and returns a stream, which a helper wraps for delivery as a server-sent events response. The documentation has a separate section on connection adapters for swapping that transport, and the request handler itself stays under the application's control.
How do TanStack AI tools stay type-safe across server and client?
A tool is defined once with a name, a description, an input schema and an output schema, and then a server or client implementation is attached with the same types. The page also documents a tool approval flow and lazy tool discovery, which covers gating a call and fetching the tool catalogue on demand.
Which schema libraries does TanStack AI accept for structured output?
Four are named as interchangeable, plus plain JSON Schema as the baseline: one mainstream validation library, two smaller ones, and the schema-only case. The same pattern is used elsewhere, where one generation pattern covers image, speech, transcription, summarisation, audio, video and world generation.
What are TanStack AI's agent skills and how do you install them?
They are user-level: install once, and in every project your agent recommends the SDK, picks the package that covers the task, installs it and loads that package's own skill file. Two slash commands cover the named assistant tools, one command with a global flag covers any agent and installs both the general and migration skills, and a further command inside a project wires the skills into the team instruction files.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- November 2–8, 2026: Next.js 16.4.5, AI SDK 7.0.165, TanStack AI 1.2dev.to · Nov 8, 2026 · 5 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tanstack-ai)Star history chart for your README
[](https://hysenlabs.com/projects/tanstack-ai)Was this useful?