The Makefile exits before it installs a browser, and the manifest caps Playwright at 1.49 with no floor
Hercules is the world’s first open-source testing agent, enabling UI, API, Security, Accessibility, and Visual validations – all without code or maintenance. Automate testing effortlessly and let Hercules handle the heavy lifting! ⚡
At a glance
- What is it?
- An open-source testing agent that turns Gherkin steps into end-to-end tests and advertises itself as needing no code, while its dependency list carries two model clients, a graph agent framework, a deep learning stack, and a captcha-solving library. Its escape hatch is arbitrary Python with the page object injected, gated by a tenant identifier on the command line.
- Who is it for?
- The pitch and the dependency list disagree, and the dependency list is the more honest document. This is marketed as a no-code agent that writes your tests, and what it actually ships is a browser driver capped at a late-2024 version, two model vendor clients, a graph-based agent framework, a deep learning stack for visual comparison, and a document parsing library for every known file format.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 17, 2026, and from our analysis. They are not legal advice.
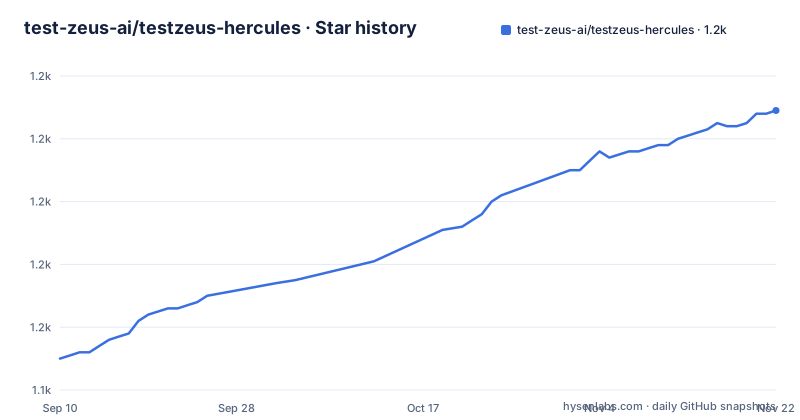
Star history
- test-zeus-ai/testzeus-hercules1,224 ★ · +74
| Repository | 2026-09-10 | 2026-11-17 |
|---|---|---|
| test-zeus-ai/testzeus-hercules | 1.2k | 1.2k |
74 Stars in the last 68 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The manifest caps the browser driver at 1.49 and never sets a floor
The dependency list of a testing tool is where its real design shows, and this one is worth reading end to end.
The entry that governs everything else is the browser driver, and it is written as an upper bound with no lower bound at all. So the resolver will accept that version and nothing newer. For a tool whose entire job is driving a browser, that is a decision with consequences: the driver is old enough that it predates current browser behaviour, and nothing in the file stops an older one being chosen either.
Two more lines are about version discipline. A transformer library has a pre-release as its floor, and two audio packages are conditional on an interpreter version at or above a specific minor release. Those two will simply not install on the older interpreters the same file permits.
Then the shape of the stack. Two model vendors' client libraries are present, plus a gateway client, plus a graph-based agent framework. The agent loop is therefore a state machine, not a prompt in a loop. The tool is also an MCP client in its own right, and there are example server configurations at the repository root for that.
The rest explains the feature list. A deep learning framework with a matching computer-vision library is there for the visual validations. A document parser configured for every known format is there for file inputs. A test result parser plus an HTML report generator produce the standard output a pipeline expects. A telemetry protocol, an error-reporting client, and a process introspection library cover the operational side.
One dependency deserves a question rather than a paragraph. There is a library whose entire purpose is solving one specific class of challenge that appears on ordinary login pages. For a testing agent pointed at a protected page that is a reasonable thing to need; for a distributed tool it is a signal worth asking the project about directly, because nothing in the README says when it engages.
The install target exits before it installs a browser
The build file is short, and one target does not do what its name says.
There are two install targets, one plain and one that includes optional dependencies. Both are written as a dependency sync, then an unconditional exit, then a browser installation with its system dependencies. Because the exit runs first and succeeds, the browser step never executes. The target reports success having installed the Python package and no browser, and the first run of the tool fails on a missing browser binary rather than on a missing dependency.
That is a two-character bug with a long tail, and it is the kind that survives because a contributor running the target has a browser from a previous install and never sees the failure.
So the browser arrives the way the documentation says it should, by hand:
pip install testzeus-hercules
playwright install --with-deps
Two other things in the same file point the same way. The lint target depends on the format target, so a lint run rewrites your files before checking them, and its type-check line is present but commented out, so type errors are not part of lint at all.
And at the top, two variables are computed while the file is being parsed: one that detects whether the project uses the modern Python installer by grepping the project file for a word, and one that inspects the virtual environment for a pip binary. Neither appears in any target shown. They are the residue of a previous setup path, and they are evaluated on every single make invocation regardless.
The help target, meanwhile, is built by searching the Makefile itself for comment markers, which is the only documentation the build system has.
The image installs Chromium's libraries by hand and then tells Playwright to skip them
The container file contains its own contradiction, and it is worth reading as two halves written at different times.
The first half is careful. It starts from a slim interpreter image and installs build tools plus a list of system libraries: audio, accessibility bridge, direct rendering, three different X extension sets, generic memory mapping, keyboard, and screen saver. That list is not arbitrary; it is the shared library set a headless browser needs. A font package comes with it, which matters for a tool that renders pages and compares screenshots, since missing fonts produce different glyphs rather than errors.
The second half is the browser install, and it is invoked explicitly without the flag that would install those same system dependencies. The comment beside it says the system dependencies will be installed at runtime if needed.
So the image installs the libraries by hand, then instructs the browser installer not to install them, on the stated assumption that anything missing will be handled later at runtime. Anything missing will be missing at runtime too, because nothing in the entrypoint is described as installing them.
The interpreter version is the third detail. The image pins a specific minor release of Python, and the project file declares a range that includes two older minors. Two of the declared dependencies are conditional on an interpreter at or above the newer minor, which means they can never install in this container. That is a harmless pair of packages today and a confusing debugging session the first time somebody wonders why an audio path is missing.
The no-code pitch is reconciled with arbitrary Python by a tenant string
The headline is that you write plain-language Gherkin steps and get end-to-end tests without coding skills. The most prominent documented feature is the opposite of that, and the way the project holds both is the interesting part.
The feature is a sandbox. From inside a step in your feature file you name a function and a script file and its arguments, and the tool runs it. The example is an async function that waits for a selector, tries two selector strategies in turn so it works whether the page labels the filter as an input value or as a label wrapping an input, clicks the first that exists, and returns a dictionary. The comment in the example says the page object and the logger are available automatically.
So a test author who cannot write a selector can call a function someone else wrote, and the sandbox is where reusable automation lives: advanced selector strategies, conditional logic, and data processing, exactly as the description says.
Now the access model. There is a tenant identifier, set by an environment variable or by a command line flag, and the documentation annotates the full-access value with the libraries it grants. Other values exist: the feature list names executor, data, API, and restricted modes. So what a sandboxed script may import is a configuration value rather than a sandbox boundary.
That is a defensible choice for a locally-run tool, and it is also the honest reading of the tension. The no-code claim holds because the sandbox is optional; the power claim holds because when you use it you are writing Python again. What the tenant string adds is a way to hand someone a restricted script without handing them an unrestricted interpreter, which is useful precisely as far as it is configured.
Three small version disagreements, none of them load-bearing on their own
Collected together, because individually each is a footnote.
The project file declares one version. The newest release tag declares a later one. The tagged releases are the first three of a 1.0 line shipped within about three weeks in July 2026, and the branch has not been pushed to since early August, which for a project whose value depends on tracking browser and model behaviour is the number that will age fastest.
The interpreter requirement excludes the oldest minor version that its own classifier list advertises. Anyone reading the package index sees support claimed for a version the resolver will refuse.
Two dependencies are conditional on an interpreter version that the requirement permits but the container does not use, which was covered above.
And one documentation line is cut off mid-sentence. The parameter that takes a project base directory is described as optional and as superseding three other path parameters, with the explanation of what it assumes existing ending in the middle of a clause. So the one parameter that simplifies your command line is the one whose behaviour is least documented.
None of these would stop anyone using the tool. Together they are the shape of a project moving faster than its documentation, which is entirely normal and worth knowing before you rely on the numbers in a release note.
The example environment file is named so that nothing will load it
Three files at the repository root exist to be copied and renamed, and all three are named in a way that works against that.
The environment example is prefixed with a dot and suffixed with a hyphen and a word. That is neither of the two conventional names for such a file. It will not be picked up by a hosting platform's configuration reader, it will not be discovered by a documentation generator looking for an example, and a developer told to copy it has to be told exactly what to call the copy.
Then there are two example server configuration files, one of which is named as a copy of the other. A copy left in the root is a small thing, except that it is ambiguous which one is current, and a reader who edits the copy has changed nothing.
And the example model configuration has a text extension appended to its name, which keeps it from being parsed as configuration by anything that globs for JSON files. That one is deliberate and defensible. The other two look like accidents of the same kind of workflow.
The pattern extends to the directory layout. There is a frontend directory, a statics directory, an optional directory, an additional tools directory, a helper scripts directory, and a documentation directory that contains a migration subdirectory. The optional directory is the same one the sandbox documentation points at for user scripts, so scripts a user writes share a namespace with the project's own optional content, which is a place where a naming collision would be invisible until runtime.
The README is a funnel to a notebook, and the behaviour is in the docs it links
The front page is written as a pitch and the substance is one click away, which is fine as long as you know to click.
Three routes in. A hosted notebook for a quick taste, which the document warns may ask you to restart the session after installing, and which it then says does not give you the full picture. The package index, followed by an explicit instruction to install the browser driver and its dependencies separately, because the tool drives a browser. And the source tree.
The parameters come next, and there are four paths. One for the feature file to test. One for the output directory, which is where the XML result and the HTML report land. One for test data, with the note that all test data used in a run should be present there. And one for a project base directory, described as optional and as superseding the other three, with the sentence about what it then assumes ending unfinished.
Two documents are called out for a detail that matters more than it sounds: migration-specific runtime behaviour, and a migration architecture document. Their existence says a version transition changed something observable at runtime, which is exactly the kind of thing that turns a green suite red after an upgrade.
The teaching surface is eight videos across four headings, covering installation, writing test cases, integrations, community tools, API testing, security testing, visual validations, and the sandbox. That is a substantial amount of video for a tool whose README explains its configuration in four bullets, and it is a reasonable balance for a project whose claim is that the interface is simple enough to demonstrate in ninety seconds.
Editorial conclusion
The pitch and the dependency list disagree, and the dependency list is the more honest document. This is marketed as a no-code agent that writes your tests, and what it actually ships is a browser driver capped at a late-2024 version, two model vendor clients, a graph-based agent framework, a deep learning stack for visual comparison, and a document parsing library for every known file format. That is what doing five kinds of validation in one agent costs. Before building on it, check three things. The browser driver upper bound with no lower bound means your install can pull whatever matches, and a driver that old will not track current browser behaviour. The lint target has its type check commented out and the install target short-circuits before the browser is installed, so neither the type layer nor a clean clone is a reliable starting point. And the sandbox that lets a test call arbitrary Python with the page object injected is gated by a tenant string on the command line rather than by an isolation boundary, which means the permission model is a configuration value you set yourself rather than something the tool enforces.
Frequently asked questions
What is testzeus-hercules?
An open-source testing agent, licensed under AGPL-3.0, that turns plain-language Gherkin steps into end-to-end tests for a web application, covering user interface, API, security, accessibility and visual validations. It drives a real browser through Playwright, can run in a continuous integration pipeline, and installs from a package index or from source.
Do I really not need to write code to use testzeus-hercules?
For the test cases, no: you write Gherkin steps in a feature file. The most prominent documented feature is the opposite, though. A sandbox lets a step call a named function from a script file, with the page object and logger injected automatically, for advanced selectors, conditional logic and data processing. The script has to be written by somebody, so the no-code claim holds when you use the sandbox and stops holding when you do not.
What can the Python sandbox in testzeus-hercules import?
That is controlled by a tenant identifier set through an environment variable or a command line flag, rather than by an isolation boundary. Several access modes are named, including executor, data, API and restricted, and the full-access mode is documented as granting specific libraries including an HTTP client, a dataframe library, a numeric library and an HTML parser.
What does installing testzeus-hercules require beyond the package?
A browser. The tool drives pages through Playwright, so the install is followed by an explicit browser installation command with its system dependencies. In the container image, the Chromium shared libraries are installed by hand and the browser installer is invoked without its dependency flag, with a comment saying anything missing will be handled at runtime.
What licence is testzeus-hercules under and how active is it?
AGPL-3.0. The first three releases of the 1.0 line were published within about three weeks in July 2026, and the default branch was last pushed on 2026-08-04. The project file declares a version behind the newest release tag, and its interpreter requirement excludes a minor version its own classifier list advertises.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/test-zeus-ai-testzeus-hercules)Star history chart for your README
[](https://hysenlabs.com/projects/test-zeus-ai-testzeus-hercules)Was this useful?