wechat-download-api documents its own HTTP endpoints as unauthenticated
A fully open-source API service for fetching WeChat official-account articles and RSS subscriptions, supporting one-click export of an entire account's articles in 7 formats (Markdown/HTML/Word/PDF/EPUB/Excel/JSON), an IP proxy pool for anti-blocking, and MCP integration with various AI Agent tools.
At a glance
- What is it?
- wechat-download-api turns WeChat Official Accounts into RSS feeds, an MCP endpoint for AI clients and a whole-account export in seven formats, authenticated by a QR scan of an account you own. Two things about it deserve reading before anything else: the plain HTTP API is documented as needing no token at all, and the image label, the compose tag and the release version are three different numbers.
- Who is it for?
- wechat-download-api fits a reader who wants their own subscribed accounts in a feed reader, or wants a whole archive exported to Markdown for a notes tool, and it runs happily on a laptop over localhost. Before you put it anywhere else, settle two things.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 110 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
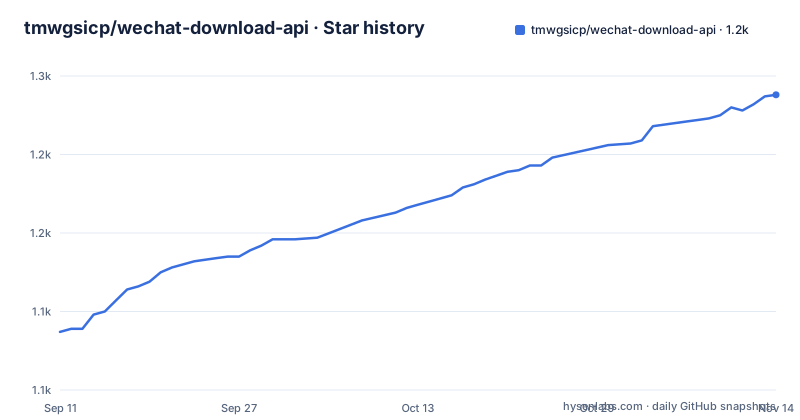
- tmwgsicp/wechat-download-api1,238 ★ · +151
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| tmwgsicp/wechat-download-api | 1.1k | 1.2k |
151 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The HTTP API is documented as needing no token
This is stated, not inferred. Before the endpoint reference, the documentation says the HTTP interfaces require no authentication: the caller passes no token and no Authorization header, and the WeChat login state is held internally by the server after the administrator scans the QR code on the management page. The note adds that MCP_TOKEN and the Authorization bearer header apply only to the MCP client integration and are unrelated to those HTTP routes.
So the security model is: one QR login authorises the whole service, and the only locked door is the MCP mount. If you expose this beyond localhost, every article fetch, account search, subscription change and export route is open to whoever can reach the port. The documentation does offer a way out, in the form of an Nginx reverse proxy example, but it is presented as optional and the sample server block adds no authentication of its own.
There is a second convention worth knowing before you write monitoring. Article parsing and the account search, list and search endpoints all return a wrapper object with a success boolean, a data field and an error field, and business failures such as an expired login come back as HTTP 200 with success set to false. A client that only checks the status code will treat a dead login as a success. The incremental feed endpoint, the health endpoint, the RSS endpoints and the markdown endpoint all return bare payloads instead.
Credentials go to .env in one file and to ./data in another
There is a direct contradiction about where your WeChat credentials are stored after login.
The quick start says the credentials are saved automatically to the .env file, with a validity of about four days, after which you scan again. The Compose file, meanwhile, mounts that same .env read-only and annotates it as the config file with credentials saved to the data directory, and a note aimed at NAS users repeats that credentials are automatically saved to ./data. The compose file also persists ./data as the location of the SQLite database.
Both can be true at different moments, since the file you copy is the template and the directory you mount is the volume, but the documentation does not say which one wins after a scan, and that matters when you are deciding what to back up, what to keep out of a git repository, and what to rotate when the four-day window closes.
The expiry window is handled for you in one direction. Webhooks fire on login expiry, with warnings 24 hours and 6 hours ahead of the deadline plus a notification once it has already expired, along with events such as a verification being triggered. Push targets are described as WeCom robots, which is the corporate WeChat bot rather than a general webhook receiver.
The image is labelled 1.0.5 while the release is 1.7.0
Three version numbers describe the same software and none of them agree.
The Dockerfile carries a label with the version set to 1.0.5, which is six minor releases behind. The release history has v1.7.0 from 2026-07-20, v1.6.0 from 2026-07-05 and v1.5.1 from 2026-06-23, and the last push to the default branch was 2026-07-27. And the compose file pins nothing at all, pulling the latest tag from the registry, with a commented alternative to build locally.
So the practical version of what you are running is whatever the registry's latest tag currently is, and the label inside the image will tell you it is 1.0.5 whether or not it is. Anyone auditing a deployment cannot use that label.
The build itself is a two-stage one on python:3.11-slim, with a builder stage that installs gcc and libffi-dev and builds wheels for every dependency, and a runtime stage that installs from those wheels and adds curl purely so the health check has a client. The runtime sets the host to 0.0.0.0, the port to 5000 and debug off, exposes 5000, and runs uvicorn against the application object in app.py. Note the final copy step copies the whole build context into the image, which is why the .dockerignore next to it matters more than usual.
Export caps differ by an order of magnitude between formats
The whole-account export is the feature the project leads with, and its limits are given as a table rather than a promise. Markdown, HTML, Excel and JSON each cap at 3000 articles per export. Word caps at 500, EPUB at 500, and PDF at 200.
The difference is explained by how images are handled. The text and spreadsheet formats reference images, so they are fast and consume no image bandwidth. The offline self-contained formats, Word, PDF and EPUB, fetch the images from WeChat at export time and embed them, which is why PDF, with a fixed layout and a bundled Chinese font so nothing has to be installed locally, is the smallest cap of the seven.
Two constraints apply to all of them. Only articles whose body text has already been fetched are exported, so the export reads what the service already holds rather than scraping on demand, and the documentation is explicit that this means no WeChat requests are triggered by an export. And the selection is by time range, with all, last N days, a window, and incremental options.
The interface is a download button beside each subscription on the RSS management page, or a direct call to the account export endpoint with a format suffix. Single-article markdown export is a separate path that adds YAML frontmatter for Obsidian or Logseq.
Rate-limit resistance is a TLS fingerprint, a proxy pool and throttling
The project describes a three-layer approach to not getting blocked, and it is worth being precise about what that means rather than repeating it as a feature.
The layers are Chrome TLS fingerprint simulation, rotation through a SOCKS5 proxy pool, and automatic rate limiting at three levels. The dependency that implements the first one is visible in the requirements file: curl_cffi, a library that impersonates browser TLS signatures, sits alongside httpx, which does not. The image proxy is a separate feature with a different purpose, serving WeChat CDN images so that hotlink protection does not blank them in a reader.
This is the layer where the project's own framing and the platform's rules meet, and the honest position is that automating subscriptions against a service whose terms you have not read is a decision you make, not one the code makes for you. What the code does is reduce the chance of a block, which is not the same as being permitted.
What is unambiguous is the credential model. You need a WeChat Official Account of your own, subscription or service type, you scan the login page with the administrator account, and after that the service can fetch public articles from any account rather than only yours. That is the design: your account is the key, other people's publications are the data.
One requirements file, exact pins for some and ranges for the rest
The dependency file opens with a dated comment explaining a choice: MCP support needs newer FastAPI, pydantic and starlette, and the versions are aligned to what has been verified. That comment is dated 2026-07-05, which matches the v1.6.0 release a fortnight later.
The pins are exact for the web stack:
fastapi==0.137.1
pydantic==2.13.4
with uvicorn, httpx and python-dotenv also pinned to exact versions, and the MCP library pinned exactly at 1.27.2. The parsing and conversion libraries use floors instead: curl_cffi, beautifulsoup4 and markdownify.
The export libraries are the inconsistency. The comment says the Markdown, HTML, xlsx and JSON formats need no extra dependencies and that PDF, Word and EPUB need Pillow, xhtml2pdf, python-docx, openpyxl and EbookLib. All five are listed unconditionally, so an installation that will never export a PDF still downloads a font toolkit, a PDF engine, a Word library, a spreadsheet library and an EPUB writer.
For a container that is a fair trade, since the whole image is one deployment anyway. For anyone who installs the dependencies into an existing environment it is five packages they did not ask for.
The MCP mount is six tools behind one bearer token
The agent-facing surface is the part with authentication, and it is small. Six tools are exposed: search accounts by name to get a fakeid, subscribe, unsubscribe, list subscriptions, fetch recent articles with a time cursor for incremental reads and a filter by account, and read one article in full.
Enabling it takes two environment variables, and the documentation is explicit that both are required: a flag to enable the service and a long random token, without which MCP stays off. The service mounts at /mcp over streamable HTTP, and there is a third variable, MCP_RESOURCE_URL, meant to be set when you deploy to a public domain as a DNS-rebinding allowlist.
Client configuration is given for both worlds. For Claude Code it is a single command adding an HTTP transport server with an Authorization header carrying the token. For Cursor and Cline it is a JSON block with the same URL and a headers object holding the bearer value. Locally the endpoint is tested on localhost port 5000, and an unauthenticated request returns 401.
The rest of the operational surface is conventional and documented well enough to copy: a management panel, Swagger and ReDoc documentation, a health endpoint the container probes every 30 seconds, a start script that registers a systemd service when run with sudo on Linux, status and stop scripts alongside it, and the Nginx reverse proxy sample that forwards Host, client IP and the forwarded-for chain.
Editorial conclusion
wechat-download-api fits a reader who wants their own subscribed accounts in a feed reader, or wants a whole archive exported to Markdown for a notes tool, and it runs happily on a laptop over localhost. Before you put it anywhere else, settle two things. Exposure: the documentation states plainly that the HTTP endpoints need no token, because the WeChat login state lives inside the server after the administrator scans, so anything that can reach port 5000 can fetch articles and manage subscriptions. Reverse proxy with an authenticating layer, or keep it on localhost. And terms: the project is built around official platform credentials and describes a stack for reducing the chance of being rate-limited, which is exactly the part you should check against WeChat's own rules before automating subscriptions at scale rather than after a block. The MCP endpoint is the one surface with real authentication, which is convenient for agent use and worth keeping that way.
Frequently asked questions
Does the wechat-download-api HTTP API need a token?
No. The documentation states that the HTTP endpoints take no token and no Authorization header, because the WeChat login state is held inside the server after the administrator scans the QR code. MCP_TOKEN guards only the MCP endpoint at /mcp.
What do I need before I can use wechat-download-api?
A WeChat Official Account of your own, subscription or service type. After starting the service you open the login page and scan with the account administrator's WeChat; the credentials are saved automatically and are valid for about four days, after which you scan again.
How many articles can one wechat-download-api export contain?
Markdown, HTML, Excel and JSON cap at 3000 per export, Word at 500, EPUB at 500 and PDF at 200. Only articles whose body was already fetched are included, so an export does not trigger new WeChat requests.
How do I enable the MCP integration?
Set both ENABLE_MCP and MCP_TOKEN, without which MCP stays disabled, and set MCP_RESOURCE_URL when deploying to a public domain as a DNS-rebinding allowlist. The service mounts at /mcp over streamable HTTP and exposes six tools, and an unauthenticated request returns 401.
Which version of wechat-download-api am I running?
The compose file pulls the latest tag, so you get whatever the registry serves. The newest release is v1.7.0 from 2026-07-20 and the last push was 2026-07-27, while the image label inside the Dockerfile still reads version 1.0.5, so the label is not a reliable indicator.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tmwgsicp-wechat-download-api)Star history chart for your README
[](https://hysenlabs.com/projects/tmwgsicp-wechat-download-api)Was this useful?