Unstract: prompt a schema, get JSON from PDFs, scans and spreadsheets
LLM-Driven Extraction of Unstructured Data — Built for API Deployments & ETL Pipeline Workflows
At a glance
- What is it?
- Unstract is a self-hosted, AGPL-3.0 licensed platform that pulls structured JSON out of documents with natural language prompts, then exposes that one extraction core over REST, an ETL pipeline, an MCP server and an n8n node. The install is a single script on four services, and the documentation is wide on connectors while giving no accuracy or latency figures.
- Who is it for?
- Unstract suits teams that already run Docker and want a single extraction core shared by an API, a warehouse load and an agent. Verify three things before committing: that your Python is exactly 3.12 if you develop against the repository, that you can restore the ENCRYPTION_KEY from backend/.env, and that a sample of your own documents yields the fields you need.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
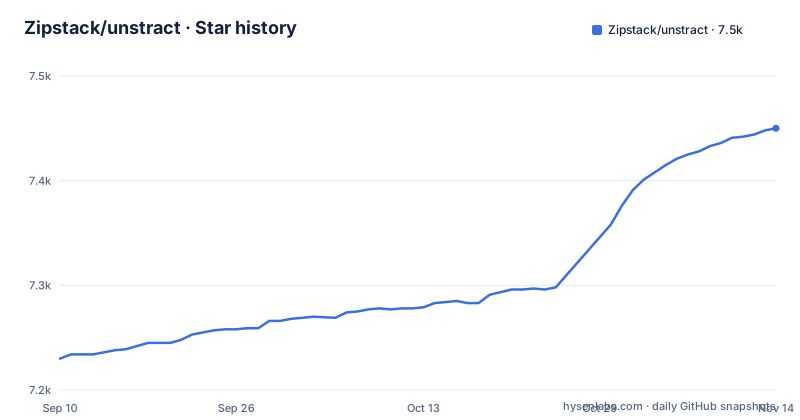
- Zipstack/unstract7,450 ★ · +220
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| Zipstack/unstract | 7.2k | 7.5k |
220 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Extraction schemas are natural language prompts, not templates
The central idea in Unstract is that a schema is something you describe in English rather than something you code. You write a prompt that names the fields you want pulled out of a document, and the platform returns JSON shaped by that description. The README frames this as a swap: without Unstract you write regex and build a template per vendor, with Unstract you write a prompt once and it handles variations. That line sits inside a comparison table, so read it as the project's own pitch rather than a measured result.
What is concrete is the surface the prompt runs on. Extraction definitions are edited in Prompt Studio, and the same definition is then published through an API deployment, an ETL pipeline, an MCP server or an n8n node. Because all four read from the same prompt, the prompt is the single place where output shape is decided. There is no separate mapping layer to catch a field that comes back renamed, so a sloppy instruction propagates to every consumer at once.
run-platform.sh is the entire install, and it only runs on Linux or macOS
The whole platform comes up through one shell script. The stated prerequisites are Linux or macOS on Intel or M-series hardware, Docker and Docker Compose, Git, and 8 GB of RAM as a minimum. Clone the repository and run it:
# Clone and start
git clone https://github.com/Zipstack/unstract.git
cd unstract
./run-platform.sh
When it finishes, the frontend sits at http://frontend.unstract.localhost and the README signs you in with the username `unstract` and the password `unstract`. Windows is absent from the supported list, so a Windows-only workstation needs a Mac, a Linux box or a virtual machine before anything starts.
The same script carries version control for the containers, which matters if you want to pin what you evaluated:
# Pull and run docker containers with a specific version tag.
./run-platform.sh -v v0.1.0

# Upgrade existing Unstract platform setup by pulling the latest available version.
./run-platform.sh -u

# Upgrade existing Unstract platform setup by pulling a specific version.
./run-platform.sh -u -v v0.2.0

# Build docker images locally as a specific version tag.
./run-platform.sh -b -v v0.1.0

# Build docker images locally from working branch as `current` version tag.
./run-platform.sh -b -v current
Note that `-u` upgrades an existing setup to the latest available version with no mention of a migration step or a way back, so treat the tag you are running as the thing you can reproduce later.
The ENCRYPTION_KEY in backend/.env is the lock on every stored adapter
Adapter credentials are encrypted, and the key that does it sits as a plain value in a dotenv file. The README marks this with a warning: copy `ENCRYPTION_KEY` from `backend/.env` or `platform-service/.env` to a secure location, because losing it makes existing adapters inaccessible.
That failure is narrower and nastier than losing a password. The default username and password can be changed by following the authentication steps in `backend/README.md`. A lost encryption key makes every existing adapter inaccessible. The ETL sources include AWS S3, MinIO, Google Cloud Storage, Azure Blob, Google Drive, Dropbox and SFTP, and the destinations run to Snowflake, Amazon Redshift, Google BigQuery, PostgreSQL, MySQL, MariaDB, SQL Server and Oracle. Restoring that list means re-keying a broad set of production systems.
So if Unstract is going to hold real warehouse and object store credentials, copy that value into your own secret store on day one, before you type anything sensitive into the UI. The README's backup instruction is to copy that value to a secure location.
One extraction core behind four doors: REST, ETL, MCP and n8n
The same extraction logic is published through four separate doors. API deployment takes a document over REST and returns JSON. The ETL pipeline pulls documents from a folder, processes them and loads them into a warehouse. The MCP server connects agents such as Claude over Model Context Protocol. The n8n node drops into existing automation workflows. Picking a surface is therefore mostly a question of who calls you, not of what gets extracted.
Underneath, the provider list is broad. LLM options cover OpenAI, Azure OpenAI, an OpenAI Compatible entry, Anthropic Claude, AWS Bedrock, Google Gemini, Mistral AI, Anyscale and Ollama running locally. Vector databases are Qdrant, Pinecone, Weaviate, PostgreSQL and Milvus. Text extraction can go through LLMWhisperer, Unstructured.io or LlamaIndex Parse.
That breadth is the project's main argument, and it is also its main source of surprises. The README lists each connector with a checkmark but never states which combinations are supported inside one pipeline, so a design that needs a specific source, a specific parser and a specific warehouse has to be checked piece by piece. Budget time for that verification instead of assuming the full matrix works.
Four services, one Redis and one RabbitMQ between your file and the JSON
A single extraction is not a single process here. The architecture diagram names four application services: a React frontend, a Django backend, a Celery worker and a FastAPI platform service, sitting on a Redis cache with a RabbitMQ message queue underneath. The repository layout mirrors that split, with `backend/`, `frontend/`, `platform-service/`, `workers/` and `runner/` directories, plus `tool-sidecar/` and `x2text-service/` for side work.
The consequences follow from that shape. One document crosses the API, the backend and a queue-backed worker, which is why the minimum is stated as 8 GB of RAM rather than something a thin laptop absorbs. Any state you care about lives in more than one place: the application database, the Redis cache and the RabbitMQ queues.
For evaluation this means the install is heavier than a library, and for operations it means backups and monitoring cover more components than the feature list suggests. If your team has nobody comfortable with container networking and queue brokers, that is the cost you are signing up for, not the prompt.
The format table lists extensions, not page quality
Unstract advertises turning documents into JSON, naming PDFs, images and scans, and the format table backs that with a wide list. Documents cover PDF, DOCX, DOC, ODT, TXT, CSV and JSON. Spreadsheets cover XLSX, XLS and ODS. Presentations cover PPTX, PPT and ODP. Images cover PNG, JPG, JPEG, TIFF, BMP, GIF and WEBP.
An extension list tells you what the platform will accept, not what it will read correctly. The README does not document page segmentation for multi column layouts, table reconstruction, handwriting handling, rotated scans, or how the system behaves when a page contains no extractable field. A three hundred page PDF of scanned invoices and a three hundred page PDF of born-digital invoices both satisfy the format requirement while failing in completely different ways.
The parser choice is also unresolved by the docs. LLMWhisperer, Unstructured.io and LlamaIndex Parse are all listed as text extractors with no stated difference in accuracy, speed or cost. The practical move is to run a handful of your ugliest real files through one prompt before you trust the list, since a parser that quietly returns half a page turns into missing JSON keys with no error anywhere in the stack.
No accuracy figure, no rollback path, no cost ceiling
The documentation is generous about components and silent about guarantees. There is no extraction accuracy number, no latency benchmark, no token cost estimate, and no statement about what happens when a document matches no field in the prompt.
The README names finance, insurance, healthcare and KYC and compliance as target industries, which raises the stakes on those missing numbers rather than lowering them. That is the failure mode to plan around: validate field presence and type on your side, in your own code, after every run.
The repository does ship a real test rig. The pyproject file defines a test-rig group with pytest, pytest-xdist, pytest-cov, pytest-timeout, pytest-django and testcontainers for Postgres, Redis, MinIO and RabbitMQ, installed through tox. That harness exercises Unstract's own code. It says nothing about whether your prompt returns the right values, and no result from it can stand in for that evidence.
Python 3.12 only, AGPL-3.0, and three releases in two days
The constraints worth knowing before you clone are narrow and explicit. The pyproject file sets `requires-python` to `>=3.12,<3.13`, ruff targets py312, and the line length is 90. Local path sources wire up unstract-core, unstract-connectors, unstract-workers, unstract-filesystem, unstract-workflow-execution, unstract-tool-sandbox, unstract-tool-registry and unstract-flags as editable installs, with uv.lock pinning the rest. Anything outside 3.12 is excluded by declaration.
Licensing is a straight read: the repository is AGPL-3.0. Read the LICENSE file yourself before embedding the platform in anything you distribute.
Release pace is fast enough to matter operationally. v0.201.0 shipped on 2026-11-03, v0.200.0 on 2026-11-01 and v0.199.1 on 2026-10-30, and the last push to the main branch was 2026-11-02. Frequent releases mean fixes arrive quickly and that pinning a version, as `./run-platform.sh -v` allows, is the only way to keep a working setup reproducible.
For contributors, two commands wire up the local checks:
# Install pre-commit hooks
./dev-env-cli.sh -p

# Run pre-commit checks
./dev-env-cli.sh -r
Editorial conclusion
Unstract suits teams that already run Docker and want a single extraction core shared by an API, a warehouse load and an agent. Verify three things before committing: that your Python is exactly 3.12 if you develop against the repository, that you can restore the ENCRYPTION_KEY from backend/.env, and that a sample of your own documents yields the fields you need. Do not put regulated volume on the strength of the feature list, since the repository publishes no accuracy or cost figures to check against, and read the AGPL-3.0 license before shipping it inside a product.
Frequently asked questions
What is Unstract?
Unstract uses LLMs to extract structured JSON from documents such as PDFs, images and scans. You define what you want extracted with natural language prompts, then deploy the result as an API or as an ETL pipeline.
How do I use Unstract for a first extraction?
Clone the repository, run ./run-platform.sh, open http://frontend.unstract.localhost and sign in with username unstract and password unstract. The prerequisites are Linux or macOS, Docker and Docker Compose, Git, and 8 GB of RAM.
Is Unstract open source?
The repository is published on GitHub under an AGPL-3.0 license and the full platform runs locally through ./run-platform.sh. A managed cloud option and an enterprise tier are offered alongside the self-hosted setup.
Is Unstract free to run?
The self-hosted platform runs from the public repository, and the README links to separate Enterprise and pricing pages for teams that want managed infrastructure. The repository itself states no license fee for the code.
How does Unstract compare with LLMWhisperer?
LLMWhisperer is one of three text extractor integrations listed inside Unstract, alongside Unstructured.io and LlamaIndex Parse. The README does not compare their output quality or performance, so the choice is not settled by the documentation.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zipstack-unstract)Star history chart for your README
[](https://hysenlabs.com/projects/zipstack-unstract)Was this useful?