HPX is on a 2.0 release candidate, and its build dashboard lives on a university host
The C++ Standard Library for Parallelism and Concurrency
At a glance
- What is it?
- HPX is a Boost licensed C++ standard library for concurrency and parallelism that tracks the standard from C++11 through C++23 and extends it to distributed work. The newest tag is a 2.0 release candidate, the build health dashboard is served from a university address rather than a code host, and the repository carries two CI systems alongside three build descriptions.
- Who is it for?
- HPX suits a team that wants the standard concurrency interfaces plus a task runtime it can steer with performance counters, and that has the compiler and platform appetite for a large C++ library rather than a small dependency. Three things to check first.
- Can I use it commercially?
- Yes. BSL-1.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
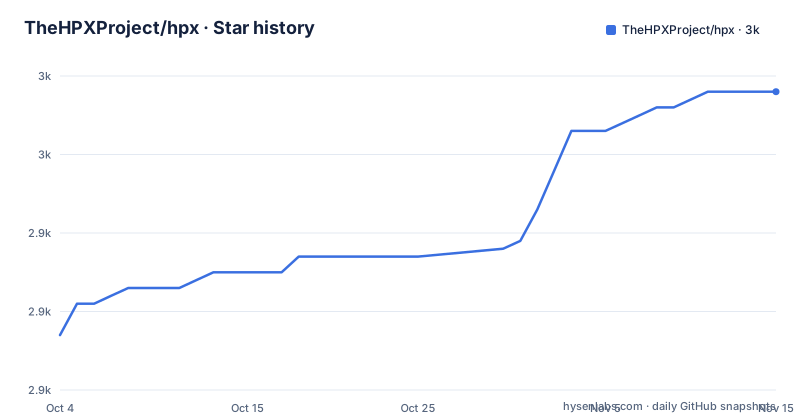
- TheHPXProject/hpx2,958 ★ · +31
| Repository | 2026-10-04 | 2026-11-15 |
|---|---|---|
| TheHPXProject/hpx | 2.9k | 3k |
31 Stars in the last 42 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two candidates, one stable, and fifteen months between them
The three most recent releases are a 2.0.0 release candidate from September 2026, a 1.11.0 stable from June 2025 and a 1.11.0 release candidate from June 2025.
Read as a sequence, the pattern is a short burst and then a long gap. The 1.11 candidate appeared on 2025-06-02 and its stable followed on 2025-06-29, twenty-seven days later. Then nothing until the 2.0 candidate on 2026-09-28, which is about fifteen months after the last stable.
The 2.0 candidate is also very recent relative to the branch itself: the most recent push is dated 2026-09-23, so the candidate was cut five days later. The project's own documentation tells you how to read that: it suggests starting with the latest released version for actual use, treats the master branch as the newest code, and says that while it tries to keep master stable and usable, sometimes new bugs trick their way into the code base.
So there are three states on offer at once: a stable line from mid 2025, a candidate line from late 2026, and a moving master branch, and the page's advice is to use the first and watch the other two.
The build health dashboard is not on a code host
The documentation section does something unusual. It strongly recommends following the current health status of the master branch by looking at the project's continuous integration results website, and the address of that site is on a subdomain of a university computing centre rather than on a code hosting service or a commercial CI vendor.
Alongside it, the page points at the GitHub continuous integration service, which additionally tracks the current build status for the master branch through a workflow named for building and testing. So there are two places to look, and the page's own emphasis is on the one outside the code host.
That ordering is a statement about what the project considers authoritative. A hosted service's badge reports whether one job passed on one machine; a results site that collects every configuration reports whether the matrix is green. For a library whose selling point is running on anything from a hand-held device to a very large scale system, the matrix is the interesting number.
Documentation follows the same split, with one URL for the latest release and another for the development documentation built from the master branch. A reader therefore has to know which of the two sets of pages matches the version they have installed, and the page does not label them with version numbers.
Two CI systems and three ways to describe the build
The repository root carries both a Jenkins directory and a GitHub directory, so the project runs continuous integration in two systems. It also carries three different descriptions of what to build.
The first is CMake: a top level CMakeLists file, a CMakePresets file, a testing configuration file used for submitting results to a dashboard, and a cmake directory. The second is Conan, with a recipe file, an ignore file and a separate test package directory, which is what lets the library be consumed as a package rather than as a subdirectory. The third is a wrap directory, which holds the mechanism CMake uses to fetch and build external projects.
Alongside those sit the files that describe how the source must look. There are separate format and lint configurations for clang, a format configuration for the CMake files themselves, a Codacy configuration for the automated code quality service the page mentions, and an editor configuration. There is also an attributes file for line endings and a committed git hooks directory, which means hook behaviour travels with the clone rather than with each developer's setup.
Two more files are about identity rather than code. A citation file at the root carries the metadata the page tells you to cite, and an SPDX file is committed, which is a software bill of materials for the project itself.
The examples directory is the feature list
There are twenty-four example directories, and their names are the most concrete description of what the library does.
Some are numerical patterns: a one dimensional stencil, an accumulator benchmark, two variants of a Jacobi solver, one for each of a single and multiple node setup, the n queens problem, and a random memory access benchmark. Some are about the runtime itself: asynchronous input and output, work balancing, a cancelable action, a future reduce, a pipeline, a heartbeat, startup and shutdown ordering, and a task benchmark. One is an emulated Google Test, which suggests the library can host a test framework's execution model on top of its own.
Then there are the ones named after outside systems: a tracing integration, a benchmarking harness integration, a toolkit example, a unikernel operating system example, and a spell checker written with the library. Four of the twenty-four are therefore about what HPX can be embedded in rather than what it computes.
Only one is called quickstart, which is consistent with the rest of the page: the getting-started material is a separate guide, and the examples are the reference.
Dataflow and futures are how concurrency is managed
The list of what makes the library distinctive is worth taking one item at a time.
It exposes a uniform, standards-oriented API for parallel and distributed applications, and it provides unified syntax and semantics for local and remote operations, which is the distributed half of the same promise. It lets programmers write fully asynchronous code using hundreds of millions of threads. And it makes concurrency manageable with dataflow and future based synchronization, which is the mechanism rather than the slogan.
Then there is a uniform, flexible and extendable performance counter framework, described as able to enable runtime adaptivity. That is the difference between a library that reports numbers and one that can change behaviour because of them.
The remaining claims are about range. It is designed to solve problems conventionally considered to be scaling-impaired, and it has been designed and developed for systems of any scale, from hand-held devices to very large scale systems. The stated purpose of all of it is to improve the scalability of today's applications and to expose new levels of parallelism needed to take advantage of the exascale systems of the future, which is the one claim on the page with a horizon in it rather than a benchmark.
The ParalleX claim appears once and carries the most weight
One bullet says HPX is the first fully functional implementation of the ParalleX execution model. It is the only place on the page where that model is named, and no further description of it follows.
Everything else the page says about the design is more concrete. HPX implements all of the concurrency and parallelism facilities as defined by the C++ standard, and additionally implements functionalities proposed as part of the ongoing C++ standardization process, which means the library runs slightly ahead of the compilers it targets. It also extends the standard APIs to the distributed case, so the same interface works across machines rather than only within one.
The stated goal underneath those claims is portability and longevity: a modular, well designed runtime architecture that would allow the implementation to be ported onto new computer system architectures, with real-world applications driving the development so that required functionalities are coined out and the API converges on something stable that gives developers a smooth migration path.
That is a project describing itself in terms of a research execution model plus a standards track plus a portability promise, with the model itself left as a single adjective-free line.
Standards on one side, Boost conventions on the other
The API is described as modelled after the interfaces defined by the C++11, 14, 17, 20 and 23 standards, and as also adhering to the programming guidelines used by the Boost collection of C++ libraries. Those are two different audiences and the page is explicit about both.
The documentation follows the same two-track shape. There is a Springer book titled Parallel C++, described as covering efficient and scalable high-performance parallel programming using HPX, with its code examples kept in a separate repository rather than in this one.
Citation has its own instructions, and they are specific: in publications, use the paper in the Journal of Open Source Software as the main citation for HPX, and for referring to the latest release use the archive entry the page badges. The root of the repository carries a citation metadata file, which is what tools read to generate the former.
Release signing is documented too, with the project's public key given at a key server address, described as the key used to sign HPX releases. So a user who wants to verify a tarball has a published fingerprint to check it against, and the page says where the key is.
Governance is meritocratic, and the copyright names two holders
The project describes itself as a meritocratic, consensus-based community project in which anyone with an interest can join, contribute to the project design and take part in deciding things. A separate governance document describes how that participation works and how to earn merit, so the route into influence is written down rather than informal.
It is also a member project of the High-Performance Software Foundation, which is the reason a neutral umbrella appears in the page at all.
The copyright lines are where the donation shows. The header of the page carries a copyright for Louisiana State University spanning 2007 to 2026, alongside the Boost Software Licence identifier, and the closing line carries a copyright for the HPX Project as a series of LF Projects, the wording used by the Linux Foundation's licensing entity. Two holders on one page is what a project that began inside a university and then moved under a foundation looks like from the repository.
The acknowledgements are specific in the same spirit. A free open-source licence of a commercial static analyser was used to check the codebase, and past and current funding and support for the project is listed on the project's own site. Support itself has a page in the repository's GitHub directory, alongside the code of conduct.
Editorial conclusion
HPX suits a team that wants the standard concurrency interfaces plus a task runtime it can steer with performance counters, and that has the compiler and platform appetite for a large C++ library rather than a small dependency. Three things to check first. Read the release channel, because the newest tag is a candidate rather than a stable release and the last stable predates it by about fifteen months. Watch the project's own build dashboard rather than assuming a green badge means the master branch is sound, since the page itself says new bugs get in. And budget for the build, since the repository ships CMake, Conan and wrap descriptions side by side, which is the shape of a project that supports several ways in.
Frequently asked questions
Who develops HPX?
It is described as a meritocratic, consensus-based community project that anyone with an interest can join, contribute to the design of, and participate in deciding, with a governance document describing how merit is earned. It is also a member project of the High-Performance Software Foundation, and the page's copyright lines name Louisiana State University and the HPX Project as a series of LF Projects.
What does HPX stand for?
The page does not expand the acronym. It describes HPX as a C++ standard library for concurrency and parallelism, and separately claims that HPX is the first fully functional implementation of the ParalleX execution model.
What licence is HPX released under?
The Boost Software License, version 1.0, identified in the page header by the SPDX identifier BSL-1.0 and described as a liberal open source licence. The license text file in the repository is named for that licence.
Which C++ standards does HPX track?
The API is modelled after the interfaces defined by the C++11, 14, 17, 20 and 23 standards, and additionally implements functionalities proposed as part of the ongoing standardization process. The page also says the API adheres to the programming guidelines used by the Boost collection of C++ libraries.
How do I check whether the HPX master branch is healthy?
The page strongly recommends following the project's own continuous integration results website, which is hosted on a university subdomain rather than on a code host, and notes that the GitHub Actions build workflow additionally tracks the master branch. It also says that while the project tries to keep master usable, new bugs sometimes get into the code base.
How do I build or consume HPX?
For building, the repository carries a CMake setup with presets and a testing configuration, a Conan recipe with its own ignore file and test package, and a directory of wrap files for external projects. For using it, the page suggests starting with the latest released version and points at a quick start guide for most Linux distributions and a manual page for other platforms.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/thehpxproject-hpx)Star history chart for your README
[](https://hysenlabs.com/projects/thehpxproject-hpx)Was this useful?