GO Feature Flag's WebAssembly build needed a 1 MB shadow stack, and CI now proves it
Project brief: GO Feature Flag is a simple, complete and lightweight self-hosted cloud native feature flag solution 100% Open Source, built on OpenFeature.
At a glance
- What is it?
- An open source, self-hostable feature flag service built on the OpenFeature standard, usable either as a hosted relay proxy or as an in-process Go module. The interesting files are the ones the build comments explain: a shadow stack raised from 64 KB, a verification target that fails CI on a silent TinyGo regression, and a dependency list longer than the feature list.
- Who is it for?
- GO Feature Flag fits a team that wants flags evaluated in one place across several languages, or a Go team that would rather evaluate in process than call a service. Five things to decide first.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
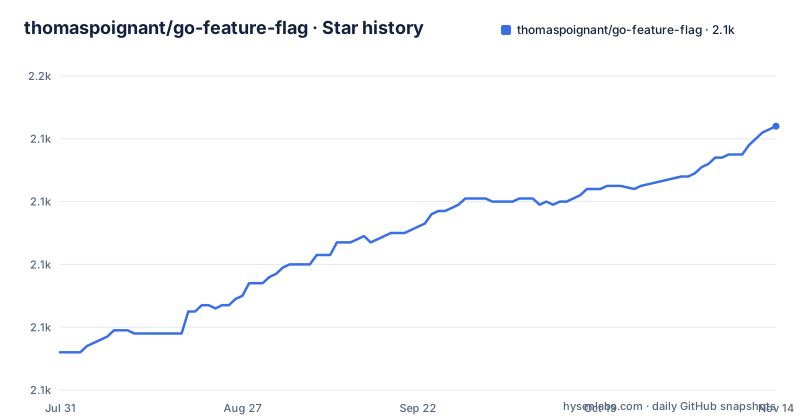
- thomaspoignant/go-feature-flag2,144 ★ · +72
| Repository | 2026-07-31 | 2026-11-14 |
|---|---|---|
| thomaspoignant/go-feature-flag | 2.1k | 2.1k |
72 Stars in the last 106 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two evaluation paths, and the project recommends the one with a server in it
The most important paragraph on the page is a decision you have to make before writing any code.
The important block says that before starting you should decide whether to use the OpenFeature SDKs or use GO Feature Flag as a Go module. The relay proxy is recommended: it gives central flag management and evaluation, it enables multi-language support, and it integrates with the OpenFeature SDKs. The page calls that the best way to get the full potential of the product. If your project is exclusively in Go, the Go module is the option, and it performs flag evaluation directly in your Go code.
The repository layout shows how the second path is packaged. config.go, config_exporter.go, feature_flag.go, variation.go, variation_all_flags.go and tracking.go sit at the repository root rather than in a subdirectory, so importing the module gives you the evaluator directly with no server in between.
The first path is what the rest of the project is built around. The relay proxy is an API server that can be hosted, and it is the thing that makes the project language agnostic: SDKs for other languages talk to it over HTTP instead of embedding an evaluator. The history explains the shift, since the tool was originally designed exclusively for Go and became multi-language after OpenFeature standardised the interface.
That standardisation is a stated design position rather than a convenience. The page argues for open standards and vendor neutrality, and lists the benefits as open-source standard SDKs, no vendor lock-in, and community-based SDK support. For a feature flag service, lock-in is a real risk, because flags outlive the code that reads them and migrating a flag store is work nobody budgets for.
The example directories back the claim. There is an OpenFeature example for Node, for React, for the web, for Kotlin on the server, and for Swift on iOS, alongside the Lambda and data export examples.
A 64 KB WebAssembly stack overflowed, and the fix has its own CI target
The Makefile contains the longest comment in the repository, and it is worth reading in full because it documents a real failure with a real consequence.
There is a WebAssembly build, cmd/wasm, among the three Go modules the Makefile iterates over, and a TinyGo tool variable alongside the standard Go one. The comment explains that the custom target files raise the wasm shadow stack from the 64 KB wasm-ld default to 1 MB with a stack size linker flag. The reason: the 64 KB stack could be overflowed by recursive JSON decoding or by targeting-query parsing on realistic flag configurations. The consequence is stated in the plainest terms available, the instance traps and is permanently poisoned, with an issue number attached.
Then the part that is genuinely careful. TinyGo's own stack size flag only affects goroutine stacks, not the system stack used with the scheduler disabled, which is why the linker flag is needed instead. Anyone who tried to fix this by raising the TinyGo setting would have seen no change and concluded the fix did not work.
And the guard: a target called verify-wasm-stack asserts that the produced binaries actually carry that stack size, so a TinyGo upgrade that stops honouring the target JSON linker flags fails CI instead of silently regressing. The comment explains why that target is kept out of the build targets, because it needs python3, and that it instead runs as a separate step in CI and in the release script.
That is a build system defending a specific property of an artifact against a dependency upgrade, and the reasoning chain is complete: the failure, the wrong fix that looks right, the right fix, and the test that keeps it. The rest of the Makefile is more conventional, with the workspace mode disabled in CI, five binaries built in the all target including the relay proxy with CGO disabled, a JSON schema generator, an editor API, a CLI and the modules.
The dependency list names more integrations than the feature list does
Read the module requirements against the feature list and the integrations come out ahead of the documentation.
The visible feature list says usage data can be exported to S3, Google Cloud Storage, a file or Kafka, and that notifications go to webhook and Slack. The requirements go considerably further.
There is a Microsoft Teams notification client in the build, a project with no Slack equivalent in the visible list at all. Kafka arrives twice over, once through the IBM Sarama library and once implied by the export example named for Kinesis, which is not in the visible export list either. On the AWS side there are two SDK generations' worth of packages: Lambda, the API proxy adapter from awslabs, S3 with its transfer manager, Kinesis and SQS. Azure is there through an identity package and a blob storage client, and Google Cloud brings BigQuery, Pub/Sub in both its first and second major versions, and Cloud Storage.
Two entries in that list are worth stopping on. Both major versions of the Pub/Sub client appear in a single build, v1 at 1.51.1 and v2 at 2.7.0, which usually means two different subsystems in the same codebase each pinned a different one. And a fake Google Cloud Storage server is a dependency, which is a test double rather than a runtime library and a sign that the storage integration is covered by tests against a local emulator.
Elsewhere the list explains parts of the architecture. A JSON schema library generates schemas from Go types, which is what the separate schema generator binary and the .schema directory at the root are for. An HTTP framework with an OpenTelemetry middleware is the relay proxy's server. A CLI flag parser is the command line. A WebSocket library, pinned to a dated commit rather than a release, is there for a reason the requirements do not say.
The examples cover retrievers and exporters the feature list omits
The examples directory is longer and more specific than the feature list, and the difference is where the surprises are.
The visible list says a flag configuration file can be stored in HTTP, S3 or Kubernetes. The example directories include a retriever for a ConfigMap, one for a local file, one for GitHub, one for MongoDB, one for S3, one for HTTP, and one for multiple configuration files read together. So the storage story includes a document database and a source code host, neither of which appears in the short list.
The export side is the same. Beyond S3, Google Cloud Storage, a file and Kafka, there are directories for Kinesis and for AWS Lambda deployed with SAM. An example that deploys with SAM is doing two things at once, showing the export and showing a hosting pattern.
The rollout examples match the three named strategies exactly: experimentation for A/B, progressive for a staged rollout, and scheduled for updates on a timetable. That is one place where the documentation and the repository agree completely, which is a good sign for the rest.
Then the OpenFeature examples, and they are the reason to look at the list carefully. There are directories for Node, React, plain web, Kotlin on the server, and Swift on iOS. Kotlin on a server is the interesting one, because a server-side SDK is the one you would expect the relay proxy to serve, and it is also the one with no repository of its own listed alongside the SDK list. The example is in this repository, which tells you where to look and not much about the SDK's maintenance.
One example is not a deployment at all: lint_flag_programmatically, which is a linting tool over flag definitions. It is the smallest directory name in the list and the most telling, because a feature flag service that cannot be linted is a service whose broken configuration is found in production.
Storing flags anywhere moves trust to wherever you store them
The retriever abstraction is the feature that makes this tool flexible and is also the one with a security consequence nobody mentions in a feature list.
A flag file can come from an HTTP endpoint, an object store, a Kubernetes ConfigMap, a GitHub repository, a MongoDB collection, a local file, or several of those combined. Configuration can be JSON, TOML or YAML. The combination means a flag value can live somewhere your application has no other reason to trust, and the application will read it on the next evaluation.
That is the trade the project is offering: no deploy needed to flip a flag, and a configuration change is as fast as a file write wherever that file happens to live. The same property means a compromised bucket, a public repository or an unauthenticated endpoint becomes a flag injection vector, and a flag is code as far as your application is concerned.
Two things in the repository address this. There is a JSON schema generator as its own build target and a .schema directory at the root, so flag files can be validated against a published schema rather than parsed hopefully. And there is a programmatic lint example, which is the same idea in code.
The rollout and targeting surface is where the complexity concentrates. Rules target users, evaluation context carries the attributes a rule matches on, custom bucketing decides which bucket a user lands in, variations are the possible values, and the three rollout strategies decide how many buckets get which value and when. A flag system with rules, context, bucketing and scheduled rollouts is a small expression language, and the examples are the only documentation for it in the repository.
Notifiers reach webhook, Slack and Microsoft Teams
When a flag changes, the project can tell you, and the notifier package is where that lives.
The visible feature list names two channels, webhook and Slack. The requirement list includes a Microsoft Teams notify client as well, so the implementation covers three channels against two documented ones. The same pattern runs through the export side, and it is a reasonable thing to expect from a project that grew integrations faster than it grew the summary at the top of its readme.
Notifying on a flag change is a different concern from exporting usage data, and the distinction matters for how you operate it. Export is telemetry: how often was each flag evaluated, to which variations, for which targeting keys. Notification is control plane: a human needs to know before the change takes effect rather than after, because the people who can approve a rollout are not the people watching a data pipeline.
The readme also names a demo application whose source is in the examples directory, and the table of contents has sections for the flag file format, the rule format with examples, evaluation context, custom bucketing, variations with an example, rollout with a note about complex strategies being available, notifiers, export data, and a command line section. The CLI is what you would use to check a configuration before you ship it, and its options are not in the part of the page visible here.
One last operational detail. The project asks users who are already running it to add themselves to an adopters list, and points sponsorships at a single maintainer. The releases show the scale: v1.55.3 in early September, v1.56.0 the day before the most recent commit, and a separate tag for the OpenFeature Python provider at v1.3.0 in between.
Two pull request bots and a FIPS module version file
The root directory describes how this project is governed and built more than the readme does.
There are two configuration files for automated pull request handling: a Kodiak configuration, which is a bot that merges pull requests when its conditions are met, and a Greptile configuration for automated code review. Two bots on the same repository is a deliberate throughput choice and a large amount of unreviewed change if either is misconfigured.
There is a FIPS version file at the root, and the Makefile reads it as the single source of truth for the FIPS module version, assigning it to a Go FIPS 140 variable. FIPS 140 validation is a cryptography compliance regime, and a feature flag service needing it is a specific kind of deployment, usually one feeding a system in a regulated environment. Pinning the module version in a file rather than in a script means the version is one value with one owner.
The rest is a well equipped Go repository. golangci-lint configuration, a pre-commit configuration, codecov for coverage, goreleaser for releases, sonar properties with a matching sonarlint directory, a gitmodules file for submodules, and a schema directory. There is also an AI agent setup: a Claude directory at the root, agent instructions in a file, a worktree include file, and a custom commands directory, which is the convention for letting an agent work on several branches at once.
And two files at the root that are not build related at all. The adoptors list the organisations using the project, and there is a code of conduct. Both are signs of a project that expects to be run by someone else's team, which is the same reason the schema, the linter and the notifiers exist.
Editorial conclusion
GO Feature Flag fits a team that wants flags evaluated in one place across several languages, or a Go team that would rather evaluate in process than call a service. Five things to decide first. Which of the two evaluation paths you take, because the relay proxy is a service you operate and the Go module is a dependency in your binary, and the project recommends the proxy even for Go projects. Where your flag file lives, since the retriever can read from HTTP, S3, a Kubernetes ConfigMap, GitHub, MongoDB, a local file or several at once, which turns a configuration file into a runtime dependency and a supply chain surface. What your failure mode is when the flag service is unreachable, which the documentation does not settle here. Which integrations you actually need, since the dependency list contains Microsoft Teams notifications, Kinesis, SQS, Lambda and BigQuery that the visible feature list does not mention. And whether a WebAssembly deployment matters to you, because if it does you are relying on a custom link flag that a CI check exists to protect.
Frequently asked questions
What is GO Feature Flag?
It is a lightweight, open source, self-hostable feature flag solution built on the OpenFeature standard. You can either run its relay proxy, an API server that serves SDKs for any language, or use it as a Go module that evaluates flags in process. The project recommends the relay proxy even for Go projects because it gives central management and multi-language support.
Where can GO Feature Flag store its flag configuration?
The retriever can read the flag file from HTTP, S3, a Kubernetes ConfigMap, GitHub, MongoDB, a local file, or several sources combined, and the format can be JSON, TOML or YAML. The visible feature list names only HTTP, S3 and Kubernetes, so the example directory is the fuller list. A separate build target generates JSON schemas, which is how a flag file can be validated before it is deployed.
What rollout strategies does GO Feature Flag support?
Three named strategies with matching example directories: experimentation for running A/B tests, progressive for gradually rolling a feature out, and scheduled for updating flags on a timetable. Targeting is done through rules evaluated against an evaluation context, with custom bucketing deciding which bucket a user falls into, and variations holding the possible values.
Can GO Feature Flag be deployed to WebAssembly?
There is a WebAssembly module among the three Go modules the build handles, built with TinyGo. Its build files raise the wasm shadow stack from the 64 KB linker default to 1 MB, because recursive JSON decoding and targeting query parsing on realistic flag configurations could overflow the smaller stack and permanently trap the instance. A separate verification target asserts the produced binaries carry that stack size so a TinyGo upgrade cannot regress it silently.
Which notifiers and export destinations does GO Feature Flag use?
The feature list names webhook and Slack for notifications, and S3, Google Cloud Storage, a file and Kafka for exporting usage data. The build dependencies and example directories show more: a Microsoft Teams notify client, an Amazon Kinesis export example, and an AWS Lambda deployment using SAM. The requirement list also pulls in both major versions of the Google Pub/Sub client.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/thomaspoignant-go-feature-flag)Star history chart for your README
[](https://hysenlabs.com/projects/thomaspoignant-go-feature-flag)Was this useful?