A project built around full openness, with no licence file in the repository
OpenResearcher: A Fully Open Pipeline for Long-Horizon Deep Research Trajectory Synthesis
At a glance
- What is it?
- OpenResearcher releases a 30B-A3B model, 96K research trajectories, an 11 billion token corpus, a distillation recipe and an evaluation framework, and describes the whole set as fully open source. The repository contains no licence file at all and its licence field reads as unknown, which is the first thing anyone planning to build on it needs to resolve.
- Who is it for?
- It fits a research group that already has the hardware, wants a retrieval-based deep research agent whose training data and recipe they can inspect, and is prepared to read a licence from the model card or ask the authors because the repository will not give it to them.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 158 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
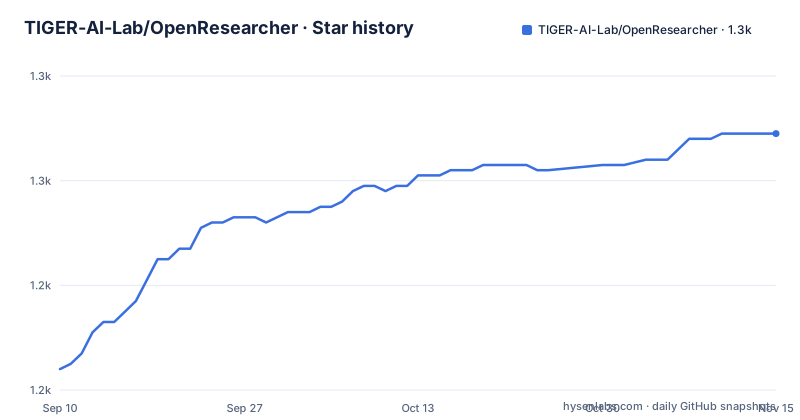
- TIGER-AI-Lab/OpenResearcher1,269 ★ · +45
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| TIGER-AI-Lab/OpenResearcher | 1.2k | 1.3k |
45 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The licence field reads unknown and there is no LICENSE file
The repository description leads with a claim about openness. It says the training and evaluation recipe is fully open sourced, naming the pieces as data, model, training methodology and evaluation framework, and the features paragraph restates it as a fully open-source recipe with a 96K trajectory dataset, a 30B-A3B model, a distillation recipe and a lightweight evaluation framework. The root listing is `.env.template`, `.gitignore`, `README.md`, `assets/`, four Python modules at the top level, `eval.py`, `pyproject.toml`, `run_agent.sh`, `scripts/`, `setup.sh` and `utils/`. No licence file is there, and the licence attached to the repository reads as unknown rather than as a named licence with an unrecognised identifier. The tension is straightforward: this is a project whose argument is that the field should be open, distributed under terms that permit reuse of a 30B model and a research dataset, and the one artefact that would let a reader confirm the terms is the one that is absent.
The manifest packages a directory that lives in another repository
The packaging configuration names two packages:
[tool.setuptools]
packages = ["utils", "tevatron"]
Only one of them is in this tree. `utils/` is a directory at the root; `tevatron/` is not, because the README installs it as a separate clone:
git clone https://github.com/texttron/tevatron.git
cd tevatron
uv pip install -e .
cd ..
So the manifest claims a package owned by a different project, and the working directory it expects is populated by a clone the user performs into a sibling position. Both repositories are then installed editable, this one with `uv pip install -e .`, so a broken tevatron checkout leaves the package metadata pointing at a directory that exists but is wrong, or at one that does not exist. This is the kind of thing that works for the author, whose directory layout already has tevatron beside the checkout, and produces a confusing failure for anyone who followed the README in a different order.
Eight 80GB accelerators, a JDK for a Python project, and root for apt
The reference environment is stated in three lines: eight A100 80G Nvidia GPUs on Linux. The alternative offered is that other hardware setups can work, with a reminder to modify the corresponding parameters, and no parameter is named. The installation sequence then asks for root, since it begins by updating the apt index and installing `openjdk-21-jdk`, which is an unusual line in a Python project until you notice `pyserini` in the dependency list, since that retrieval library runs on a JVM. The README does not make that connection, so the JDK looks like a stray instruction rather than a consequence of the search stack. The environment is then built by piping an installer into a shell, `curl -LsSf https://astral.sh/uv/install.sh | sh`, followed by `uv venv --python 3.12` and a source of the activate script. The manifest requires 3.12 or newer, so the interpreter is not negotiable either.
One dependency is pinned exactly and everything else has a floor
Look at the version specifiers and one component stands out. `vllm==0.13.0` is the only exact pin in the list; `transformers>=4.57.6`, `peft>=0.18.1`, `datasets>=4.5.0`, `fastapi>=0.128.0`, `pyserini>=1.5.0`, `httpx[http2]>=0.28.1`, `duckdb>=1.4.4`, `faiss-cpu>=1.13.2`, `gpt-oss[all]>=0.0.9` and the rest are all floors. That is the correct choice for the serving layer, where the model's tool-use interface has to match the runtime, and a loose choice for a research dependency set that will drift. Two further points. The retrieval stack is `faiss-cpu`, `pyserini` and `duckdb`, all CPU-side, so on the stated hardware the eight accelerators serve the model and the search index does not use them. And the teacher model is a runtime dependency: trajectories were generated with GPT-OSS-120B and `gpt-oss[all]` is installed alongside the student, so the pipeline that produces data and the pipeline that consumes it share a dependency.
Two search backends decide whether the no-API-cost claim holds
The scalability claim is specific: trajectories are generated at scale using a self-built retriever over a dedicated corpus of roughly 11 billion tokens, which removes the need for external search APIs and significantly reduces training cost. The configuration section shows what the alternative looks like, a `SERPER_API_KEY` used for web search when `browser_backend=serper`, and the table of contents separates the two into one example with a local search engine and another with the Serper API and no local search needed. So the choice is a switch, not a fixed architecture, and it decides three things at once: whether you reproduce the reported numbers, whether the pipeline runs without a paid API, and whether you need the FAISS, Pyserini and DuckDB stack at all. The browser tool path is worth noting separately, since the README points at the vLLM documentation for GPT-OSS tool use rather than at an external browser automation service, so tool calling runs through the model you are serving.
The same benchmark family is written two ways, and one checklist has a typo
The features paragraph names the benchmark set as BrowseComp-Plus, BrowseComp, GAIA and xbench-DeepSearch. The setup section names BrowseComp-Plus, BrowseComp, GAIA and xbench-DeepResearch, linking a different project. Both spellings are in the same file, and which one a reader follows determines which repository they end up preparing. The benchmark preparation step is also uneven in what it downloads: a setup script fetches BrowseComp-Plus from Hugging Face and lays out the directory structure, while the other three are said to be set up automatically the first time they are used. The script's own checklist spells the first item with a transposed word, writing Downlaod rather than Download, which is a small thing but it is in the file a user reads when something fails. The headline number also lives outside the repository, since the BrowseComp-Plus leaderboard is a Hugging Face Space run by a third party rather than a results table committed here.
Every artefact a paper needs is released, but the code has no version
The release list is unusually complete for a research project. There is a 96K trajectory dataset whose entries run to more than 100 turns each, a 30B-A3B model on the Hub, a distillation recipe described in a paper, the evaluation framework that is this repository, an approximately 11 billion token corpus behind the retriever, a Space running the model, and a directory of evaluation logs. Adoption by third parties is recorded with dates, among them a claim that the data was used in an NVIDIA Nemotron model and that it powers trajectory generation in another NVIDIA tool. What is missing is versioning on the code side. The manifest says version 0.1.0, the repository has no GitHub releases at all, and the branch was pushed on 2026-06-10, so the most recent news entry is five days before that and there is no tagged name to record which tree a result came from.
Editorial conclusion
It fits a research group that already has the hardware, wants a retrieval-based deep research agent whose training data and recipe they can inspect, and is prepared to read a licence from the model card or ask the authors because the repository will not give it to them. It does not fit anyone who needs a licensed artifact for a product, and it does not fit a single GPU, since the reference setup is eight 80GB devices and the alternative is described only as modifying parameters. Before using any of it, get the licensing question answered in writing, decide whether you are running the local retriever or a paid search API, and check which of the two benchmark name spellings the code expects.
Frequently asked questions
What is OpenResearcher?
A 30B-A3B agentic model for long-horizon deep research, released with a 96K trajectory dataset, a distillation recipe, an approximately 11 billion token corpus and an evaluation framework. The reported result is 54.8 percent on BrowseComp-Plus.
What licence does OpenResearcher use?
The repository contains no licence file and the licence attached to it reads as unknown, although the README describes the data, model, training methodology and evaluation framework as fully open sourced.
What hardware does OpenResearcher need?
The stated setup is eight A100 80G Nvidia GPUs on Linux. The README says other hardware can work and to modify the corresponding parameters, without naming them. Python 3.12 or newer is required and a JDK is installed during setup.
Does OpenResearcher need a paid search API?
Not on its own path. The pipeline uses a self-built retriever over an approximately 11 billion token corpus, but the configuration also accepts SERPER_API_KEY for a browser_backend set to serper, and the README gives one worked example of each.
Is tevatron part of the OpenResearcher repository?
No. The README clones tevatron from its own repository and installs it editable alongside this project, yet pyproject.toml lists tevatron as one of its two setuptools packages, so the manifest refers to a directory that only exists after the separate clone.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tiger-ai-lab-openresearcher)Star history chart for your README
[](https://hysenlabs.com/projects/tiger-ai-lab-openresearcher)Was this useful?