Dao Code optimises for cache hits, and its install step patches your dependencies
Open-source TypeScript terminal coding agent for DeepSeek-V4 — builds on DeepSeek's strong price-performance and ultra-cheap cache pricing, engineering byte-stable prefixes and cache-reusing forks so cross-session memory and a continuous self-correction layer add almost no token cost; 1M context, Skills/MCP/Hooks, Claude Code config compatible.
At a glance
- What is it?
- Dao Code is a terminal coding agent for DeepSeek V4 whose central engineering bet is a byte-stable system prefix, with memory and self-critique running as forks that reuse the main cache. The cost table is unusually well sourced. The packaging is where the sharp edges are: a manifest ahead of its newest tag, a postinstall that patches dependencies, and an ad-hoc signed bundled binary.
- Who is it for?
- Dao Code is worth a look if you want a terminal agent on a model you can reach and pay for without an Anthropic account, and if you are willing to read its evaluation logs rather than take the score on trust. The claims are checkable in a way most are not: every cost figure points at a log path, the cache mechanism has a live demo script, and the benchmark hides test files from the agent.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 18 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
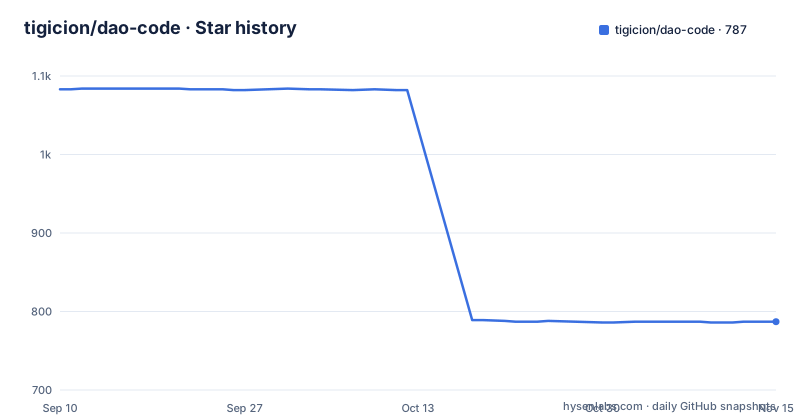
Star history
- tigicion/dao-code787 ★ · -296
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| tigicion/dao-code | 1.1k | 787 |
-296 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The manifest reads 0.5.9 and the newest tag is v0.4.7
Start with the version, because it is the first thing that does not line up. The release history shows v0.4.0 on 2026-06-29, v0.4.1 on 2026-07-08 and v0.4.7 on 2026-07-18. The manifest in this repository reads version 0.5.9. The last push was on 2026-09-22 and the repository is not archived. So the source tree is roughly two months and six patch versions ahead of the newest tag, which means the thing on npm and the thing in the checkout are not the same build unless you know which one you installed.
Other identity details worth having straight: the default branch is master rather than main, the npm package is dao-code and the command it installs is dao, and the project targets Node 20 or newer through the engines field. The package is ESM only, with type set to module and both main and the bin entry pointing at dist/index.js.
The scope of the project is narrower than the marketing framing suggests. The readme calls it a terminal-native coding assistant that reads code, writes code, runs commands and fixes bugs while streaming reasoning and tool calls behind an approval gate. It targets DeepSeek V4 with a 1M context, is Chinese-first with an English readme and a Chinese one alongside it, and describes itself as inspired by Claude Code while deliberately not depending on it. The stated reason for that road is availability and price rather than capability: an Anthropic account is described as a high bar in mainland China, another vendor's coding plan as quota-limited, and DeepSeek as register-and-go with pay-as-you-go pricing.
Installing the package runs patch-package across your dependencies
The install path does more than copy files. The postinstall script in the manifest is patch-package, and the repository root carries a patches/ directory to go with it. That combination means an install of this package into an existing node_modules tree applies patches to other people's dependencies as a side effect of installing the agent.
This is a normal thing for a project whose runtime depends on patched behaviour in a dependency, and it is also the kind of thing that surprises people who install agent CLIs globally without reading the manifest. The patches are in the repository, so they can be read before installing, which is more than most projects offer. The trade is that patch-package resolves and rewrites inside whatever node_modules it finds, and a global install puts it somewhere shared.
Two scripts sit alongside it that are worth knowing about because they explain how the cost claims were produced. One is npm run accept:cache, which runs a multi-turn conversation against the live API so the cache hit rate can be watched climbing from cold start to steady state; the readme is explicit that this is a mechanism demo and that the cost figures come from the evaluation suite instead. The other is a memory acceptance script with a matching verify script, plus debug scripts for the distillation step and for dumping the harness wire format.
The bundled binary is ad-hoc signed and installed into your PATH by a script
There is a second distribution channel next to npm, and it is the more unusual one. The bundle script first runs a version sync step and then compiles the TypeScript entry point into a single executable named dao using bun's compile mode. There is no separate build step for it and no framework bundler in between.
The install script for that binary does three things in one line: it runs the bundle, copies the result to $HOME/.local/bin/dao, and then signs it with an ad-hoc signature using codesign with the force flag and a dash for the identity. An ad-hoc signature is the weakest kind macOS accepts. It satisfies the local execution policy without any certificate, which means Gatekeeper has nothing to verify against and no notarization ticket is involved.
For a tool that reads your code, writes files and runs commands, that is the part of the install story to look at rather than the caching story. The npm route has its own postinstall behaviour, described separately, and this route trades that for a self-contained binary that needs no Node runtime present. Neither is better in the abstract; they are different risks, and the readme does not choose between them for you or warn about either.
The published package ships dist and five documents, and no source
The files array in the manifest is short: dist, README.md, README.zh-CN.md, CHANGELOG.md and LICENSE. That is the entire tarball. Source, tests, evaluation logs and scripts stay in the repository, so anyone reading the published package is reading compiled output rather than the TypeScript that produced it.
For a tool whose central argument is about a specific cache behaviour, that choice removes the part a reviewer would most want to check. There is no shipped src/ directory to confirm that the prefix really is byte-stable, or that the forks really do reuse the parent cache. Both claims are testable in principle, since the evaluation logs are referenced by path and the cache mechanism has a live demo, but neither is testable from the installed artifact.
The rest of the root is a full project rather than a wrapper. There is a .dao/ directory and a DAO.md, an install.sh, an evals/ directory, scripts/, docs/, src/, tests/ and patches/, alongside the usual CHANGELOG, CONTRIBUTING, CODE_OF_CONDUCT, SECURITY and LICENSE files, an .nvmrc for the Node version, and separate tsconfig files for the build and for an evaluation memory project that has its own typecheck script. The test runner is vitest, linting is eslint with a flat config, and the build is a plain tsc against tsconfig.build.json.
Auto-compaction is a four-step ladder that ends in a hard truncate
The context management is described as an escalation chain rather than a single strategy, and the order matters. Near the limit the agent attempts a reactive retry first. If that does not resolve it, it clears stale tool results in place. Then it produces an incremental summary. If the summarizer itself fails, the fallback is a hard truncate. Four steps, cheapest first, with a documented last resort rather than an error.
Output that is too large to hold is spilled to disk and leaves only a pointer behind in the context, which is a cheaper way to handle one enormous file read than summarising it. Two commands expose the machinery to the user: /cost reports the hit rate and the spend, and /audit cache is described as pinpointing what broke the cache using a four-dimension fingerprint. A cache audit that names the dimension that changed is far more useful than a warning that the hit rate dropped.
The same section states the central bet plainly. A byte-stable system prefix rides DeepSeek's prefix cache as far as it will go, and the system prefix, the tool table and the stored memory are all held byte-stable on purpose. That discipline is what the cost argument rests on, because DeepSeek's cache hit price is stated as roughly one hundred and twentieth of a miss. Break the prefix and the bill changes by orders of magnitude, which is why a tool built this way treats a stable prefix as a correctness property rather than an optimisation.
Memory is re-verified against the code at startup and pruned by a decay GC
The cross-session memory has an unusual shape. At the end of a session it distils preferences, project conventions and key facts. At the start of the next one it does not simply load them back: it verifies them deterministically against the current code, dropping the stale entries and flagging the ones that changed. The readme is blunt about why, contrasting this with tools that remember but misremember.
A decay garbage collector clears memories that have gone dead, and the model can read memory on demand through a memory_read tool rather than carrying everything in the prompt unconditionally. Verification at startup is the expensive part of that design, and it is another operation that has to be scheduled so it does not destroy the cache it depends on.
The reflection layer is built the same way, with three named critics. A challenger triggers on a failure streak or a recurring error and performs a sceptical independent review that questions the premise rather than the patch. A refocuser fires every N turns on a long task to restate the original goal and catch scope creep. A reply-challenger activates when the same problem is raised again. All three run as forks that reuse the main prefix cache, so the quality of a second opinion is decoupled from what it costs, which is the practical trick that makes this design affordable rather than merely clever.
Skills sit at the bottom of the priority order, below your own instruction
The precedence rules are stated as a constitution, and the ordering is the interesting part: safety and truth first, then your current instruction, then Dao Code's own core policy about model and cache discipline, then skills and memory. Your live instruction outranks the agent's defaults, and both outrank anything a third-party package installed.
The consequence is spelled out: a third-party skill you install can change how work is done, but never the safety and cache bottom line. That is a defensible answer to the problem that makes skill marketplaces risky, and it is enforced by position in a priority list rather than by inspecting what a skill contains. A skill cannot talk its way above your instruction or above the agent's own rules.
Long-running autonomy is handled by the same two mechanisms already described: auto-compaction carries context past the limit, and periodic refocusing curbs scope creep. The readme claims the agent stays on track even when it is left running for a long time unattended, which is a strong claim, and it is the claim most in need of the evaluation logs to substantiate rather than the cost figures, which come with per-task logs attached.
The cost table lists input tokens only, so the totals cannot be recomputed from it
The cost section is the most carefully sourced part of the file. Seven tasks on real repositories, valibot, date-fns, es-toolkit, sqlglot and hono, totalling 3,886,037 input tokens with a 95.8 percent aggregate cache hit rate and a per-task range of 85.4 to 97.7 percent. At DeepSeek V4 Pro pricing a full feature, described as read plus edit plus test plus self-review, runs between ¥0.07 and ¥0.21 with an average of ¥0.15, and all seven together come to ¥1.07. Every figure is said to trace back to evals/runs/<task>/run-1/agent.log, and /cost replays it.
The comparison against other vendors prices the same token trace under each vendor's official rates, and the readme notes that the high hit rate is credited to the other vendors too, in their favour. The footnote gives the rates it used, DeepSeek at separate hit, miss and output prices, and the two Claude models with cache reads at a tenth of the base rate, converted at ¥7.1 per dollar with multiples kept in dollars so the exchange rate does not matter. It even includes a cross-check, re-pricing one task at current rates and comparing against what the in-log report said.
What the table does not include is the column you would need to check the arithmetic yourself. It lists input tokens per task, while the footnote quotes a separate output rate, and the per-task cost figures cannot be derived from the visible columns without the missing half. That is a limit on verifiability rather than a sign of error, and the honest version of the claim is that the numbers are reproducible from logs that are in the repository while the summary table is not fully self-contained.
On capability, two evaluations are reported. A SWE-bench-style set drawn from recent open source bug fixes, judged on both fail-to-pass and pass-to-pass with the test files hidden from the agent specifically to prevent reward hacking, solved 13 of 14, described as reliable without a stated repetition count. Terminal-Bench 2.1, 89 third-party agentic tasks run through Harbor, passed 70 of 89, or 78.7 percent, with the V4 Pro model at the benchmark's own one-times timeout. The readme argues the more interesting point about that run was that reading real failure traces surfaced framework bugs rather than needing prompt tuning.
Editorial conclusion
Dao Code is worth a look if you want a terminal agent on a model you can reach and pay for without an Anthropic account, and if you are willing to read its evaluation logs rather than take the score on trust. The claims are checkable in a way most are not: every cost figure points at a log path, the cache mechanism has a live demo script, and the benchmark hides test files from the agent. Verify three practical things first. The manifest reads 0.5.9 while the newest GitHub release is v0.4.7, so work out which version you actually have before reading any documentation against it. The postinstall step runs patch-package across your dependencies, which is a real modification to node_modules and worth reading the patches/ directory before you install globally. And if you want the single-file binary rather than the npm package, note it is ad-hoc signed, not notarized.
Frequently asked questions
What model does Dao Code target, and how large a context does it use?
It targets DeepSeek V4 with a 1M context, is Chinese-first, and is described as inspired by Claude Code while deliberately not depending on it. The stated reason is availability and price: DeepSeek is register-and-go with pay-as-you-go pricing rather than requiring a vendor account with its own quota.
How does Dao Code keep its cache hit rate high?
It keeps the system prefix, tool table and stored memory byte-stable, and runs reflection and memory on forks that reuse the main prefix cache. DeepSeek's cache hit price is stated as roughly 1/120 of a miss, and /audit cache pinpoints what broke the cache with a four-dimension fingerprint.
What runs when I install the dao-code npm package?
The postinstall script runs patch-package, and the repository carries a patches/ directory, so the install modifies dependencies in node_modules. The patches are in the repository and can be read before installing.
What did the Dao Code evaluation runs report?
13 of 14 solved on a SWE-bench-style set with test files hidden from the agent and dual-track fail-to-pass plus pass-to-pass judging, and 70 of 89, or 78.7 percent, on Terminal-Bench 2.1 through Harbor with deepseek-v4-pro at the benchmark's official one-times timeout.
Can a third-party skill override Dao Code's own rules?
No. The stated precedence is safety and truth, then your current instruction, then Dao Code's own model and cache policy, then skills and memory. An installed skill can change how work is done but never the safety and cache bottom line.
Which version of dao-code is current?
The manifest in the repository reads 0.5.9 while the newest GitHub release is v0.4.7, published 2026-07-18. The last push was on 2026-09-22 and the repository is not archived, so the checkout runs ahead of the newest tag.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tigicion-dao-code)Star history chart for your README
[](https://hysenlabs.com/projects/tigicion-dao-code)Was this useful?