tsai: a fastai-style model zoo for time series, pinned tight
Time series Timeseries Deep Learning Machine Learning Python Pytorch fastai | State-of-the-art Deep Learning library for Time Series and Sequences in Pytorch / fastai
At a glance
- What is it?
- timeseriesAI/tsai puts two dozen neural architectures behind one PyTorch and fastai package for classification, regression, forecasting and imputation. The install is one line, and the two version ceilings below scikit-learn 1.8 and torch 3 decide who can share an environment with it.
- Who is it for?
- Adopt tsai if your time series work is classification, regression or forecasting with a neural architecture, and if you can give it a Python 3.10 environment where scikit-learn stays below 1.8 and torch stays under 3. Stay out if your stack already needs a newer scikit-learn, if your data is not among its 244 downloadable datasets.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 115 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
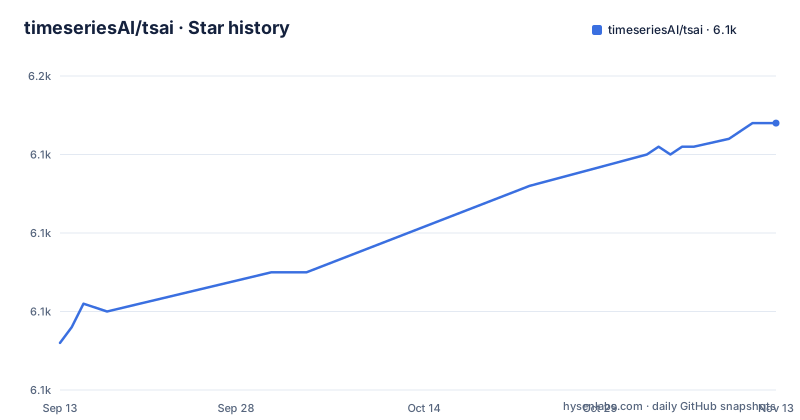
Star history
- timeseriesAI/tsai6,144 ★ · +28
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| timeseriesAI/tsai | 6.1k | 6.1k |
28 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Install from pip, or clone the tree and add the dev extra
tsai ships on PyPI and the shortest path is one line. That line installs the hard dependencies only, which is a deliberate choice rather than an oversight.
pip install tsaiFour packages, sktime, tsfresh, PyWavelets and nbformat, are needed only for selected tasks, and tsai prompts for them at the moment a task asks for one. If you would rather settle that before running anything, ask for the extras group:
pip install tsai[extras]For work inside the repository itself, the documented route is a clone plus the dev extra, which adds the notebook toolchain:
git clone https://github.com/timeseriesAI/tsai
pip install -e "tsai[dev]"
Your first real use is a notebook rather than a script. The one tutorial the README points at is tutorial_nbs/15_PatchTST_a_new_transformer_for_LTSF.ipynb, and the API documentation sits at https://timeseriesai.github.io/tsai/. A conda user should note that, as of tsai 1.0.0, the conda channel is no longer updated and tsai is distributed via PyPI only.
The version pins are narrow, and narrow pins decide who can share an environment
pyproject.toml states the floor and the ceiling in the same breath. Python 3.10 is the minimum, and the two pins that matter to an existing environment sit on scikit-learn and torch:
requires-python = ">=3.10"
dependencies = ['fastai>=2.8.7', 'fastcore>=1.13.2', 'pyts>=0.13.0', 'imbalanced-learn>=0.14', 'psutil>=6.1.0', 'scikit-learn>=1.7,<1.8', 'torch>=2.12,<3']
An upper bound on scikit-learn is the unusual part here. Anything else in the same stack that needs scikit-learn 1.8, or anything that needs torch 3, has to live somewhere else. pip resolves the conflict by refusing the install, which is the honest failure mode and also the one that costs you an afternoon.
The 1.0.0 release is where the floor moved. Python 3.9 support was dropped at that version, and the changelog is the file the README sends anyone arriving from 0.x to read. The tagged releases are 0.4.1 from 2025-07-29, v1.0.0 from 2026-05-26 and v1.0.1 from 2026-05-27, and the last push to the main branch was 2026-07-23. Two platform changes inside a year is an active line of work and a real upgrade cost to schedule around.
Four optional packages, and no table of which task needs which
Optional means optional. The README is explicit that only some tasks reach for sktime, tsfresh, PyWavelets or nbformat, and the two dependency groups in pyproject.toml name them with their floors:
dev = ['nbdev>=3', 'ipykernel>6']
extras = ['sktime>=0.38.4', 'tsfresh>=0.21.0', 'PyWavelets>=1.8.0', 'nbformat>=5.10.4']
The runtime behaviour is the part worth planning around: tsai prompts you to install a package at the moment a task needs it. Installing tsai[extras] ahead of time is the documented way to remove the question, at the price of four packages you may never import.
22 modules under tsai/models/, each one a paper and a file path
The model list is a directory listing with citations attached. Each entry names a module under tsai/models/, and several modules hold a family rather than a single architecture: RNN.py carries both LSTM and GRU, RNN_FCN.py carries LSTM-FCN, GRU-FCN and the multivariate MLSTM-FCN. The naming then wanders, with OmniScaleCNN.py, TSiTPlus.py, MINIROCKET.py and GatedTabTransformer.py sitting next to the plainer FCN.py, TCN.py, ResNet.py and TST.py.
So the catalogue hands you a file path rather than a class name, and leaves the call signature to the documentation. The recent additions named at the top of the README are PatchTST, accepted by ICLR 2023, three attention variants over recurrent networks (RNNAttention, LSTMAttention, GRUAttention) and TabFusionTransformer, alongside sklearn-type pipeline transforms, walk-forward cross validation and reduced RAM requirements.
What this list cannot give you is a decision. Every entry links a paper and a source file, and none of them carries an accuracy figure, a runtime, a memory figure, or a note about which dataset it suits. Choosing between TST, InceptionTime, ROCKET and MiniRocket means running them on your own data, and the walk-forward cross validation mentioned above is the only evaluation aid the release notes offer.
244 datasets, counted by task and never named
The dataset inventory is five numbers and nothing else: 128 univariate classification datasets, 30 multivariate classification datasets, 15 regression datasets, 62 forecasting datasets and 9 long term forecasting datasets. That is 244 datasets you can fetch, spread across the task families the package claims, except that imputation is named in the package description and never given a count.
The counts are the whole of the information. If your dataset carries a distribution licence, a class balance you cannot inspect before training, or a preprocessing convention that matters, none of that is visible until you have pulled it.
For a researcher whose data is already public and downloaded, that gap is harmless. For anyone with private, licensed or access-controlled series, the counts describe a library that will fetch for you, not one that will fit inside your compliance boundary. Check what you already hold before you lean on the download path.
The README is generated, so the file you would fix is not the file you read
The README opens by telling you not to edit it: the file is autogenerated. The generator is nbdev, and its configuration lives in pyproject.toml:
[project.entry-points.nbdev]
tsai = "tsai._modidx:d"
Two settings in the same file shape the workflow, with jupyter_hooks = true and custom_sidebar = true, and test selection driven by tst_flags = 'local slow extras onnx'. The repository layout matches the tool: nbs/ for the notebooks, tutorial_nbs/ for the tutorials, and the package version read from tsai.__version__ at build time, so nothing in the project metadata is maintained by hand.
The consequence for a reader who found a typo or a missing step is concrete. You cannot fix the README by opening it, because the next notebook export overwrites your edit. The same tooling builds the site, which is what the watcher service in docker-compose.yml exists for. It runs on every notebook change:
watchmedo shell-command --command nbdev_build_docs --pattern *.ipynb --recursive --dropGitHub reports the primary language of this repository as Jupyter Notebook rather than Python. That is an accurate description of where the work happens and a poor signal for anyone scanning language statistics to judge what a Python dependency drags into their environment.
docker-compose.yml publishes a root Jupyter server with an empty token
The compose file at the repository root is a contributor environment, and reading it before copying it saves a bad afternoon. The notebook service installs the tree and starts Jupyter on every interface, as root, with both authentication arguments blanked:
pip install -e . && jupyter notebook --allow-root --no-browser --ip=0.0.0.0 --port=8080 --NotebookApp.token='' --NotebookApp.password=''and publishes that port to the host:
notebook:
  <<: *fastai
  ports:
    - "8080:8080"
The shared base is the fastai/codespaces image, the working directory is /data with the repository mounted into it, log files are capped at 50m, and the restart policy is unless-stopped. A fourth service assembles the documentation site by copying docs_src to docs, installing the package, running nbdev_build_docs and serving Jekyll on port 4000, while the watcher runs with network_mode: host.
None of that is a deployment recipe. A published port 8080 with an empty token and an empty password is a root shell inside the container for anyone who can reach the host, and unless-stopped means it returns on its own after a restart. Use it for the notebook work it was written for, on a machine you control.
Editorial conclusion
Adopt tsai if your time series work is classification, regression or forecasting with a neural architecture, and if you can give it a Python 3.10 environment where scikit-learn stays below 1.8 and torch stays under 3. Stay out if your stack already needs a newer scikit-learn, if your data is not among its 244 downloadable datasets. Check the ceiling in pyproject.toml against your own environment first, because pip fails there rather than degrading. The last push on main was 2026-07-23, with v1.0.1 tagged on 2026-05-27.
Frequently asked questions
Can PyTorch be used for time series forecasting in tsai?
Yes. tsai is built on Pytorch and fastai, declares torch>=2.12,<3 as a hard dependency and notes Pytorch 2.0 support. Forecasting has 62 datasets plus 9 long term forecasting datasets behind it, and the PatchTST tutorial notebook covers long term forecasting.
What is the best model for time series forecasting with tsai?
The README does not rank them. It names at least 22 modules under tsai/models/, from TST and InceptionTime to ROCKET and MiniRocket, each with a paper link, and gives no accuracy or runtime figure, so the choice comes out of your own benchmark.
What is time series modeling and how does tsai approach it?
In tsai the work splits into classification, regression, forecasting and imputation. Models live as modules under tsai/models/, downloadable datasets are counted for classification, regression and forecasting, and recent additions include sklearn-type pipeline transforms and walk-forward cross validation.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/timeseriesai-tsai)Star history chart for your README
[](https://hysenlabs.com/projects/timeseriesai-tsai)Was this useful?