mergerfs: pooling directories with policies instead of disks
a featureful union filesystem
At a glance
- What is it?
- mergerfs merges filesystem paths into a single mount point and lets configurable policies decide every read, write, and delete. It is a pooling layer that sits on top of storage you already own, and it deliberately leaves parity, whiteout, and redundancy to other tools.
- Who is it for?
- mergerfs fits when you already own the disks and want one tree over them, and it stops being the right answer the moment you need parity, redundancy, whiteout, or a single file split across branches.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
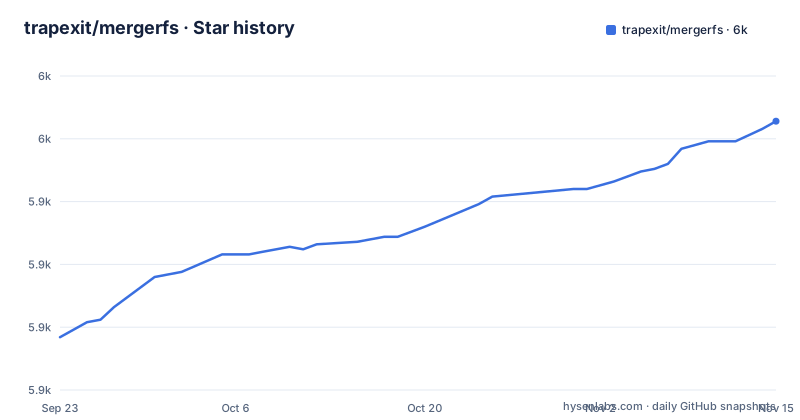
- trapexit/mergerfs5,957 ★ · +86
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| trapexit/mergerfs | 5.9k | 6k |
86 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Paths, not disks: what the union layer actually joins
mergerfs joins filesystem paths. Not block devices, not filesystem mounts, just paths, and it sits in front of them as a proxy instead of owning storage of its own. That single decision shapes the rest of the design. Where a pool built on a block layer would want a new abstraction over your disks, mergerfs leaves existing disks, partitions, and network shares exactly where they are and simply presents them as one directory tree.
The project calls the arrangement JBOFS, Just a Bunch of FileSystems, and the merge is purely logical:
A         +      B        =       C
/disk1           /disk2           /merged
|                |                |
+-- /dir1        +-- /dir1        +-- /dir1
|   |            |   |            |   |
|   +-- file1    |   |            |   +-- file1
|                |   +-- file2    |   +-- file2
|                |   +-- file3    |   +-- file3
|                |                |
+-- /dir2        |                +-- /dir2
|   |            |                |   |
|   +-- file4    |                |   +-- file4
|                |                |
|                +-- /dir3        +-- /dir3
|
Nothing is copied to produce that picture. In it, /disk1 and /disk2 keep their own layouts. /dir1 exists on both disks yet appears once under /merged. file1 lives only on the first disk, file2 and file3 only on the second, /dir3 only on the second, and file4 sits under /dir2 on the first. Asking for the contents of /merged/dir1 returns file1 from the first disk plus file2 and file3 from the second, because a directory name that shows up twice is one entry whose listings are combined.
Creation runs a policy first while reads just union the listings
The two everyday operations run through different logic, and mergerfs does not treat branches symmetrically in either. On read, it asks every branch for a directory listing, combines the lists, deduplicates entries, and returns the merged set. That is why a directory present on several disks appears once rather than several times.
On creation, a policy runs first to decide which branch receives the new file or directory, and that choice is configuration rather than code. The option set covers which existing file is selected when the same path lives in more than one branch, and where newly created files land. Read-only filesystems are ignored when a creation target is chosen, so a pool can hold a deliberately read-only branch without stopping writes.
Functions that change attributes or remove a file are the awkward case: the operation may be applied to all instances found instead of one branch. A chmod or an unlink reaching every copy is behavior to know about before pointing anything sensitive at a pool. The options and policies pages are where that behavior is actually specified.
Five things mergerfs refuses to do
The project states its own limits, and they matter more than the feature list.
It is not a read/write overlay on top of a read-only filesystem, the role OverlayFS-style container setups expect. There is no file whiteout, so deleting through the pool cannot paint a marker that hides a same-named file sitting in another branch. No RAID-style parity calculation happens inside mergerfs, which is why the README points readers at SnapRAID for that half of the job. There is no redundancy. And a single file is never split across branches: it stays whole inside one branch.
Those gaps are boundaries rather than missing patches. Need parity, pair it with an external tool. Need one enormous file to span twelve disks, this is the wrong layer entirely. The same honesty shows up in the positive claims: mergerfs works with filesystems of any size and of almost any type, and file IO passthrough reaches near native performance where supported. Those two qualifiers, almost any and where supported, are carrying real weight in sentences that otherwise read like absolutes.
Passthrough IO, hard links, and the copy-on-write switch
Passthrough is the performance story. Rather than copying data through an intermediate layer, mergerfs can hand file IO straight to the underlying filesystem and land near native performance, where supported. That qualifier is doing real work, because the result depends on what sits underneath each branch.
Metadata support is broad. Hard links work, and a separate copy-on-write mode governs what happens when a hard-linked file is modified. Extended attributes, file attributes through chattr, and POSIX ACLs are all supported, and each one has a config or documentation page behind it.
Two questions the README leaves open. It confirms hard links and links a page asking whether hard links work, without saying how links behave when the branches sit on different filesystems, which is the normal case in a pool. And the passthrough page plus the link_cow page hold the actual switches for those two options. Both change what happens on write, so they are worth reading before a large pool depends on them.
Branches come and go while the mount keeps serving
The reason to reach for a union layer instead of hand-built symlinks is churn. mergerfs can add or remove filesystems and paths without impacting the rest of the data, and it is runtime configurable, so the layout does not have to be frozen at mount time. When one branch fails, the failure stays contained: mergerfs is unaffected by individual filesystem failure, which is a narrower promise than surviving the loss of data on that branch. Other branches stay readable.
Size and type are deliberately not constraints. It works with filesystems of any size and of almost any type, and combining paths of the same or different filesystems is the normal case rather than a special mode. That is what allows spinning disks, an external drive, and a network location to sit in one mount point.
What is missing is a command. Installation lives on a separate QuickStart page, and a runtime interface page covers changing things while mounted. Read both before planning.
The build defaults to a Debian package and keeps xattrs compiled in
mergerfs is C++ and builds from source, with the packaging kept inside the repository rather than in a documented one-liner. The top level holds .github/, DEPENDENCIES, LICENSE, Makefile, README.md, buildtools/, debian/, man/, mergerfs.spec, mkdocs/, src/, tests/, tools/, and vendored/. That layout says what a build expects: a vendored dependency tree, an RPM spec, Debian packaging, a manual page, and a test suite.
Four Makefile defaults decide what you get:
DEFAULT_TARGET := debian:13.amd64
USE_XATTR ?= 1
BUILDDIR := build
GIT2DEBCL ?= buildtools/git2debcl
The default target is a Debian 13 amd64 package instead of a plain local install, xattr support is compiled in unless USE_XATTR is overridden, output lands in build/, and changelog generation calls a script under buildtools/. Even tool names are variables: fakeroot is emptied when the build runs as root, and rpmbuild is invoked by name for the RPM path. Compiler flags are grouped rather than scattered, with -fstack-protector-strong, -Wextra, and -Wno-unused-parameter in the common set, and -O0 and -g3 among the debug flags. Setting SANITIZE=1 expands to -fsanitize=address,undefined,leak. The first run of the finished tool is the mount itself, and the repository root does not show that invocation, so take the option names from the QuickStart page.
Two license answers, one maintainer, and a doc tree to lean on
Settle licensing before building on it. The project text says the software ships under the very liberal ISC license and is free for personal or commercial uses. The repository license field reads NOASSERTION, meaning the automated license guess did not resolve. ISC is short and permissive, but open LICENSE yourself before shipping it inside a product.
Activity is not in doubt. The repository is not archived, the last push landed on 29 October 2026, and three releases sit in recent history: 2.42.0 on 8 May 2026, 2.41.1 on 19 November 2025, and 2.41.0 on 12 November 2025. A single maintainer, Antonio SJ Musumeci, holds the copyright line in the Makefile. Commercial users are asked to sponsor the project so that maintenance continues, and custom feature work is routed to a direct contact address.
The real answers live in the documentation rather than in the feature list: a project comparisons page covering mhddfs, unionfs, aufs, and DrivePool, the options and policies pages, passthrough, link_cow, the runtime interface, a compatibility FAQ on which filesystems can serve as branches, and a technical behavior and limitations page.
Editorial conclusion
mergerfs fits when you already own the disks and want one tree over them, and it stops being the right answer the moment you need parity, redundancy, whiteout, or a single file split across branches. Before committing, confirm your branch filesystems pass the compatibility questions in the project documentation, read the policies you plan to rely on, and settle licensing by opening LICENSE yourself, since the repository license field reads NOASSERTION while the project text names ISC.
Frequently asked questions
What does Mergerfs do?
It logically combines many filesystem paths into a single mount point as a FUSE union filesystem, merging directory listings and deduplicating entries. A configurable policy decides which branch receives each new file or directory.
What are the key differences between MergerFS and UnionFS?
The project names unionfs among the tools it is similar to, alongside mhddfs, aufs, and DrivePool, and sends readers to a project comparisons page for the differences. The feature list does not spell them out itself.
Can I use mergerfs on Windows?
Nothing in the README answers that directly. mergerfs is a FUSE based union filesystem of paths, the repository ships a debian directory and an RPM spec, and a compatibility FAQ page covers which filesystems can be used as branches.
how to install mergerfs ubuntu
The README points to a QuickStart page instead of listing commands. Inside the repository, the Makefile defaults to a target of debian:13.amd64, the debian directory holds the packaging, and USE_XATTR defaults to 1 so xattr support is compiled in.
how to setup mergerfs and snapraid
mergerfs explicitly leaves RAID-like parity calculation out of itself and names SnapRAID as the tool for that job. The pairing is pooling paths with mergerfs and computing parity in a separate program.
is mergerfs good
That depends on the gap you are trying to close. It pools paths of any size and almost any type, adds and removes branches while mounted, and is unaffected by one filesystem failing. It computes no parity, offers no redundancy, and never splits a file across branches.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/trapexit-mergerfs)Star history chart for your README
[](https://hysenlabs.com/projects/trapexit-mergerfs)Was this useful?