simplify-codebase is an HTML project that refuses to draw a diagram unasked
Prove and remove accidental codebase complexity without breaking behavior.
At a glance
- What is it?
- This Codex skill exists to remove accidental complexity from an existing repository, and its most distinctive feature is the discipline it imposes on its own output: every candidate has to answer seven questions before anything is deleted, static analysis is explicitly not treated as proof, and the interactive Cleanup Map renderer built into the package is not produced unless a person asks for it and confirms what the picture would clarify.
- Who is it for?
- The design bet here is that deletion is an argument, not a diff, and the package mostly backs that up: it separates a read-only survey from an authorized change, asks where the consumers are before it asks what can go, and says outright that moving complexity elsewhere is not a simplification. Use it on a repository you already own, where you can answer the seventh question about migration cost yourself.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 71 days ago.
- What is it written in?
- Mainly HTML, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
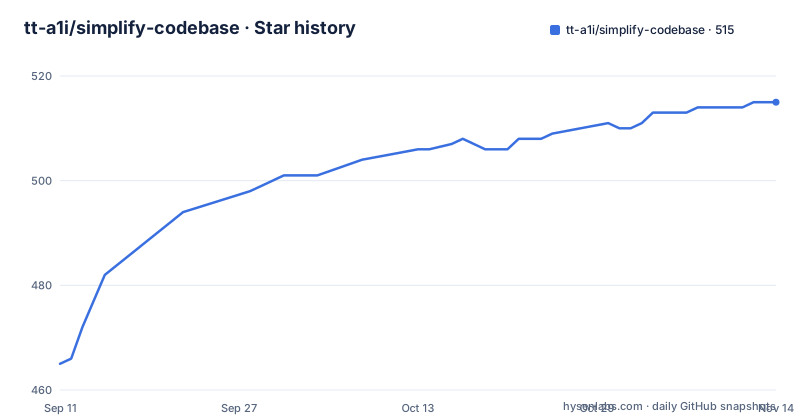
- tt-a1i/simplify-codebase515 ★ · +50
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| tt-a1i/simplify-codebase | 465 | 515 |
50 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The primary language is HTML and the default output is text
The repository's language field says HTML, which is unusual for a tool whose job is editing code, and it comes from the deliverable rather than the logic: the package ships an interactive cleanup map renderer and a desktop viewer, and the artifact that reaches a reader is an HTML page. That renderer is built in, so nothing else has to be installed, it needs Node.js 18 or newer, it pulls no extra npm packages, and the page it produces does not request external fonts. What makes that worth a section is the default. A full textual report is the standard delivery. The diagram is generated only when a reader explicitly asks for one, and even then the skill first explains what a picture would make clearer and waits for confirmation. No confirmation means no diagram, and the text audit still finishes. and the text audit still finishes. Only when a reader asks for the picture does it describe what the diagram would make clearer and wait for a yes, and the condition for keeping the text report instead is spelled out twice: when the topology has not been proven, or when the picture adds no explanatory value beyond the file locations. A fifth example prompt adds the honesty rule that the text proof record is the authoritative result, that only confirmed components and relationships should be drawn, and that reachability in a diagram must never be described as a runtime impact scope. Nothing about that is decoration, because a graph of a repository invites exactly that overclaim. So the most visual part of the project is gated behind a question, which is an unusual posture for a package whose declared language is markup. The slogan above it is the short version of the whole method, prove first and then delete, with the stated aim being fewer facts, fewer states and fewer contracts for the codebase to maintain. What it is aimed at is broader than dead code: duplicate state, abstractions with no owner left, interfaces that only tests consume, compatibility paths that stopped working long ago, and half finished features parked in shared files.
Four modes, and only one of them is allowed to write
The workflow is a two by two grid. The first axis is scope, either focused or broad. The second is permission: a read-only survey or an authorized change. A focused survey goes deep into one subsystem, one state machine or one suspected duplicate. A broad survey partitions the whole repository and returns candidates together with counter-evidence and blind spots, which is a different artifact from a shortlist. A focused change proves and completes one explicit simplification boundary. A broad change works through modifications in batches by ownership boundary, verifying each batch on its own rather than at the end. Three of the four cells produce analysis. The read-only cell is the one a reader can run first without giving anything up, and the file is explicit that the survey is where candidates are found and the change cell is where any deletion actually happens. The examples section shows how a person drives the four cells: one prompt asks for a whole repository audit with no file changes, one asks a single question about whether a set of readiness flags expresses different lifecycle guarantees or is really duplicate state, one asks for one already proven simplification with a verification step, an operation receipt and a rollback path, and one asks it to review and merge simplification suggestions from a pull request while keeping the evidence rather than the count of candidates.
Seven questions every candidate has to survive
Each candidate carries a proof record with seven fields, and the third one is the one that decides most cases: consumers, split into production, tests, dynamic and external. Alongside that sit the ownership boundary, the symbol and file, and line numbers where they can be verified; the maintenance burden the thing adds; where the full deletion boundary lies, including members that live inside shared files rather than files of their own; what observable behaviour or compatibility would be given up; which minimal verification would expose a wrong deletion; and finally whether the complexity removed outweighs whatever migration or replacement mechanism the removal introduces. That last field is the one most cleanup tools omit, and it is the difference between removing something and relocating it. The file also says plainly that static checks can offer clues but cannot on their own prove a deletion is safe, so the tool keeps tracing runtime consumers, dynamic registration, persisted formats, public interfaces, historical decisions and verification boundaries before it decides.
It has a list of things it will not simplify
Six categories are called out as requiring care rather than opportunity: public APIs together with dynamic loading and plugin registration; data formats, migrations, replay and backward compatibility; authorization, isolation, input validation and protection against data loss; concurrency, cancellation, cleanup and lifecycle ownership; generated files, shared resources and consumers that live outside the repository; and decisions records and architecture constraints that are still in force. Two failure modes are named explicitly. The first is finding a real consumer, which ends the simplification. The second is a boundary that has not been fully traced, which also ends it. The third is the subtler one: a simplification that only moves complexity somewhere else is treated as a failure too, and the recommendation becomes keeping the code. The stated reason is worth repeating because it is the whole thesis in one line, that deleting lines is only the result, and the real gain is deleting a fact, a state, a contract or a concept that somebody has to keep in sync from then on.
The install path is Codex, and the documented tree misses two directories
Installation is a prompt to Codex naming a repository URL, or a clone into the user level skill directory:
git clone https://github.com/tt-a1i/simplify-codebase.git \
  ~/.codex/skills/simplify-codebase
Afterwards the file asks you to start a new task so the skill directory reloads, which is a host behaviour rather than an installation step, and it notes that any other agent environment supporting the same skill file can host the repository in its own skill directory. The documented structure block then lists the main workflow file, a product positioning file, an agent metadata file, six reference documents and the visualization directory. The actual root listing holds two entries the block never mentions: a docs directory, which the text elsewhere depends on for its validation notes and a report format example, and an assets directory. So the file that teaches careful evidence gathering points at two directories it does not list in its own map. The rest of that map is worth reading for what it implies about the audience: an agent metadata file written for OpenAI sits inside a skill whose installation instructions are for Codex, and the reference set is split into six documents covering investigation, boundaries and lifecycle, execution and recovery, decision records, integrating other people's findings, and the honesty and delivery contract for the optional visual layer. A markdown lint configuration at the root is the only formatting tooling named anywhere. Above the map sits a centred header carrying four links with no link text at all, pointing at the workflow file, the licence, and the two readmes in Chinese and English, so a reader arriving at the page sees four empty targets rather than a navigation bar. The repository has 501 stars, 23 forks and 4 open issues, no tagged releases and no homepage field, and the default branch's last recorded push is 2026-09-04.
The renderer is vendored from another project, and only part of it
The interactive layer is not new work. It embeds a slimmed down architecture renderer, a signal flow visual system and a desktop viewer runtime taken from a project called Archify, and the installation section says explicitly that nothing extra needs to be installed because of it. What was added on top is the part that matters for this project: findings, the survey and change phases, deletion boundaries, and an evidence drawer that opens on demand. The default interface is told to state the problem in a sentence or two first and let source, path and decision evidence expand by phase, with the picture always holding the main visual space. The boundaries of the vendoring are stated too. Other general diagram types were not brought across, and neither were the repository command line, the publishing flow or the gallery flow, with the source, the modification boundaries and the MIT licence retained inside the visualization directory. A vendored core with an explicit exclusion list is a much better position than a fork nobody has audited. That does not make the layer the primary artifact, though, and the file says so where it describes the output: the picture is a companion to the proof record and does not replace consumer evidence, an operation receipt or a rollback path.
Four scenarios and one 973 file project carry the quality claim
The quality section is short and it is the part to weigh. The current version is described as exercised across change, broad, integration and decision record scenarios, and as having completed one whole repository audit on a project of 973 files mixing Python and TypeScript. The method and the known limits are pointed at a validation document, and a report format example sits beside it. One project is a thin foundation for a tool whose entire argument is that deletions need proof, and the file does not say how the audit was scored or what it found. What the file does say elsewhere is more reassuring about behaviour than about results: a passing small scope test will not be presented as a full runtime or user acceptance, and the survey and change outputs are organised differently, the first around locating a thing, its path, its deletion boundary and a judgement, the second around what existed before, what was removed, what exists after and how it was verified. Both are described as companions to the proof record rather than replacements for it. Two more boundaries close the file. The skill cannot substitute for a product decision, so removing a capability that is still reachable, an interface that is still supported, a persisted representation or a compatibility path still needs explicit authorisation from whoever owns the call. And the contribution guidance asks for failure cases, consumers that were missed, risks of wrong deletion and reproducible gaps in verification, in preference to more rules, which is the same argument the tool makes about deletions, applied to itself.
Editorial conclusion
The design bet here is that deletion is an argument, not a diff, and the package mostly backs that up: it separates a read-only survey from an authorized change, asks where the consumers are before it asks what can go, and says outright that moving complexity elsewhere is not a simplification. Use it on a repository you already own, where you can answer the seventh question about migration cost yourself. Before you trust its output, read the validation document, because the entire quality claim rests on four exercised scenarios and one whole-repository audit of a 973 file project, which is a thin base for a tool whose selling point is proof. Note that the docs and assets directories exist but are missing from the documented structure, that the interactive layer is a vendored renderer from another project rather than a new one, and that the skill itself says deletion of anything still reachable needs explicit human authorisation rather than its own judgement.
Frequently asked questions
What is tt-a1i/simplify-codebase?
It is a MIT licensed Agent Skill for existing codebases, whose job is to help a coding agent identify and safely remove accidental complexity while protecting behaviour that is still valid. Its stated goal is not deleting the most code but reducing the facts, states and contracts a team has to keep in sync.
How do I install the simplify-codebase skill?
Ask Codex to install it from the repository URL, or clone the repository into the Codex user level skill directory with a git clone whose target is the simplify-codebase folder under .codex/skills. After installing you need to start a new task so the skill directory reloads.
What does the simplify-codebase skill do in a read-only survey?
A focused survey goes deep into one subsystem, state machine or suspected duplicate, while a broad survey partitions the whole repository and returns candidates with counter-evidence and blind spots. The survey output covers what was examined, ranked proof records, important counter-examples, open questions and the next evidence needed.
What is in a simplify-codebase proof record?
Seven fields: the ownership boundary, symbol and file with line numbers where verifiable; the maintenance burden added; the consumers, split into production, test, dynamic and external; the complete deletion boundary including shared file members; what observable behaviour or compatibility is given up; the minimal verification that would expose a wrong deletion; and whether the removed complexity exceeds the migration or replacement it introduces.
Does simplify-codebase draw a diagram automatically?
No. The default delivery is a full text report, and the built in renderer is used only when a reader explicitly asks for a visualization. Even then the skill first explains what the picture would clarify and waits for confirmation, and it will keep the text report instead when the topology is unproven or the diagram adds no explanatory value.
How has the simplify-codebase skill been tested?
The file describes the current version as exercised across change, broad, integration and decision record scenarios, plus one whole repository audit on a 973 file Python and TypeScript project, with the method and known limits written up separately. The repository has no tagged releases.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tt-a1i-simplify-codebase)Star history chart for your README
[](https://hysenlabs.com/projects/tt-a1i-simplify-codebase)Was this useful?