Tura: one macro tool, two benchmark verdicts, and no ablation test
Across 348 long-horizon benchmark sessions, Tura used up to 83.1% fewer turns on the rewrite benchmark and improved the DeepSWE pass rate by up to 16.7 percentage points compared with Codex CLI.
At a glance
- What is it?
- Tura is a Rust agent runtime that replaces dozens of small tools with a single command_run macro so a five command workflow costs one model turn instead of five, and adds a backward reasoning pass that works from the state before the goal. Its published comparison against Codex CLI reports two opposite results depending on how the token saving is spent, and the README admits no ablation test isolates the macro tool as the cause.
- Who is it for?
- Use this if you are running coding agents on long workflows where five shell commands really do cost five round trips, and if you care that the authors published the gap in their own evidence. Skip it if you need a provider comparison or a cross-platform claim, because the numbers cover one baseline and the roadmap file lists the rest.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 39 days ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
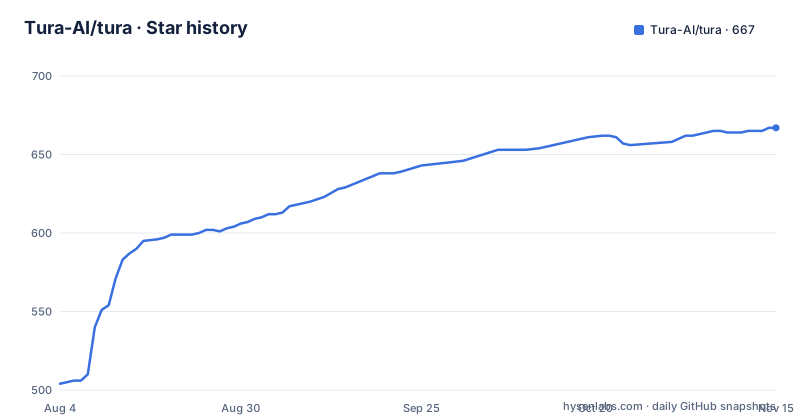
- Tura-AI/tura667 ★ · +163
| Repository | 2026-08-04 | 2026-11-15 |
|---|---|---|
| Tura-AI/tura | 504 | 667 |
163 Stars in the last 103 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Dozens of small tools collapse into one command_run macro
The opening argument is about conversational overhead rather than capability. In a ReAct session the model has to re-enter after every tool result, repeatedly carrying the system prompt and a growing context, so a five-command workflow costs five model round trips. Here is that workflow as a tool-calling agent runs it:
# Turn 1 :  inspect environment

rg -n "TODO|command_run|handler" crates/
rg --files crates/runtime/src crates/tools/src

# Turn 2 :  apply patch

*** Begin Patch
*** Update File: crates/tools/src/command_run/handler.rs
@@
-    // old command handler logic
+    // patched command handler logic
*** End Patch

# Turn 3 :  build

cargo build -p runtime

# Turn 4 :  run tests

cargo test -p runtime --lib

# Turn 5 :  run lint validation

cargo clippy -p runtime --all-targets
Tura takes a different route. Instead of exposing dozens of small tools to the model, it exposes one macro tool named command_run. The agent builds a multi-step execution tree and runs related actions in one LLM turn, so the same inspect, patch, build, test and lint sequence becomes one structured macro workflow instead of five turns separated by waits.
The consequence is stated plainly in the README: the saved work is conversational overhead, not engineering discipline. The commands are identical in both cases. What disappears is the round trip, and with it the repeated re-entry of the system prompt.
The macro payload is a JSON object with a name and a commands array, where each entry carries a step number and a command_type of shell_command or apply_patch, and the command itself as a string. The step numbers are what let two entries at the same step run together, which is how the two rg calls collapse into one turn.
Two configurations spend the same saving in opposite ways
The benchmark section is built around one idea: the token saving is a budget, and there are two ways to spend it. Across 20 DeepSWE v1.1 tasks, each run three times per agent, reducing repeated context and model round trips produces a token budget advantage that has to be allocated somewhere.
Direct turns most of it into cost. It uses 77.5% fewer aggregate tokens than Codex CLI with a comparable verifier success rate of 65.0% against 63.3%. On the full DeepSWE comparison Direct uses 69.1% fewer turns.
Balanced puts more of the saved budget back into reasoning, investigation and verification. It reached an 80.0% success rate, 16.7 percentage points higher than Codex CLI, while still using 31.1% fewer tokens and 35.8% fewer turns.
So the same runtime produces either a cost result or a quality result depending on the configuration, and the headline number you quote depends entirely on which one you mean. The repository description quotes a third figure, up to 83.1% fewer turns, and that one is attributed to the rewrite benchmark rather than to DeepSWE, which is a separate and much smaller task set.
No ablation test ties command_run to the lower turn count
The README makes a concession that most project pages would not. It states there is no ablation test proving that command_run alone causes Tura's lower turn and token usage.
What follows that concession is still substantial. The published artifacts compare the named Tura Balanced, Tura Direct and Codex CLI configurations on 20 DeepSWE tasks, 5 rewrite tasks and 2 separately reviewed design tasks, and the full report covers harness success and aggregate token usage across 25 high-difficulty tasks, 6 agent-and-model configurations and 270 sessions.
The repository description quotes 348 long-horizon benchmark sessions against that 270, and the README does not reconcile the two counts. Neither does it isolate how much of the improvement comes from the macro tool as opposed to the runtime, the routing layer or the prompt handling, so the savings are measured per configuration and the mechanism behind them is asserted rather than demonstrated.
The test set itself is versioned separately. The comparison points at a current test set record held in a separate Tura-AI benchmark repository, which means the task list can change without a code release and the numbers are tied to that document.
Backward reasoning estimates the state before the goal
The second mechanism is a change of direction. The stated premise is that an LLM is at its core a statistical induction model over text token probabilities, so an agent tends to generate the code and logic that are statistically more common, and common code and common logic are often mediocre and under-considered.
A normal agent reasons forward, with s1 as the current state and sn as the goal given by the user prompt. Tura guides the model to statistically estimate s(n-1) first and then reason backward from that state to s(n-2), so the plan is derived from the state you have to be in just before the goal rather than from the goal alone.
The worked example is rock, paper and scissors, because it is a case where the statistical argument is checkable. Asking a model to choose among three options does not produce a uniform random result, and the README is blunt that if a true one in three distribution matters the choice needs an external random number source rather than an uncited assumption about output probabilities. The prompt shown tells the model exactly that, to use a random number generator script for randint(1, 3) and then map rock, paper or scissors onto the number.
Applied to programming tasks, the framing is that an agent given a goal like fixing a frontend bug is guided through the full execution path, reconstructing the failure state rather than guessing at the patch.
The gaps are enumerated rather than left unsaid
The benchmark section carries an explicit limits paragraph, and it is unusually specific. The published results do not establish equivalent quality or performance for every configured provider, and the README names what is still missing: broader Anthropic/Claude, Google/Gemini, OpenAI-compatible and local-provider measurements, plus UI-latency, runtime and session parsing, and cross-OS measurements.
All of that is filed under two documents in the repository rather than a wish list in the README, a roadmap file and a known issues file under docs.
The shape of the evidence follows from the same paragraph. The comparison baseline is a single coding agent, Codex CLI, and the multi-provider claim is out of scope for the published numbers. That is a much narrower claim than the list of configured providers in the code would suggest, and the README does not try to close the gap.
What the artifacts do carry is depth rather than breadth, with archived prompts, per-round tool calls, token usage, patches and verifier results kept per run rather than reduced to an uncited aggregate.
Eighteen default members, and contract crates split from runtime crates
The core is a Rust cargo workspace whose root package is named tura_workspace, is marked publish = false, and uses resolver version 3 with edition 2024. The workspace package version is 0.1.0, the author is listed as Tura, and the licence is AGPL-3.0-or-later.
Eighteen paths appear in default-members and the same list plus apps/tauri/src-tauri appears in members. They break down into ten crates, three command packages and the person, agent and generate_media directories. The crate names are the interesting part, because five of them are named for a contract and five for the thing the contract describes: router and router_contract, runtime and runtime_contract, session_log and session_log_contract, alongside lifecycle, gateway, path, provider and tools.
The dependency choices suggest a server rather than a single local process. axum is pulled in at 0.8 with its websocket feature enabled, and redis at 0.25 with the tokio compatibility flag. Storage is rusqlite at 0.32 built bundled, HTTP is reqwest at 0.12 with json and stream, and PDF rendering comes from pdfium-render at 0.8 with the image feature. arboard at 3 pulls in the clipboard.
A rust-toolchain.toml at the repository root pins the toolchain, and Cargo.lock is committed.
Three version numbers and two lockfiles that do not line up
The npm package is named tura-ai and carries version 0.1.37, which matches the latest git tag, v0.1.37 from August 2026. The Cargo workspace package version, however, is 0.1.0, so the Rust side of the repository does not carry the release number the npm side publishes. Earlier tags run v0.1.36 on the same day and v0.1.35 in late July.
The install surface is small. The bin entry maps the tura command to npm/tura.mjs, engines require Node 20 or newer, and the os list is darwin, linux and win32, so the desktop shells and the CLI are published as one artefact. packageManager pins bun at 1.3.11 and the package is an ES module.
The licence is the one field where the three sources agree after a small correction. The repository record reads AGPL-3.0, and both package.json and Cargo.toml read AGPL-3.0-or-later, so the manifest files are the ones that spell out the full grant.
The published files list is where the packaging shows its seams. It ships apps/tui with a package-lock.json, and apps/gui and apps/tauri with bun.lock, in a package whose packageManager field names bun. It also ships Cargo.toml, Cargo.lock and the Rust source trees alongside the JavaScript ones, so the tarball carries both toolchains.
Root Python installs are unused on purpose
The requirements.txt at the repository root contains no packages. It is three comment lines explaining that root Python installs are intentionally unused, and that command owned Python dependencies are installed with uv in two specific places: the requirements file under commands/read_media and the one under commands/web_discover.
That makes the command directory the place where the language mix shows. Three commands sit there, generate_media, read_media and web_discover, and two of them carry their own Python environment rather than sharing one, so the isolation is per command rather than per repository.
Everything else about the tree is Rust or documentation. Alongside the crates there are agents/, personas/, apps/ with tui, gui and tauri subdirectories, an xtask/ directory, scripts/, tests/, docs/ and assets/, plus SKILL.md, architect.md, ARCHITECTURE.md, CHANGELOG.md, ROADMAP.md and a Simplified Chinese README.
The recorded state is a Rust project with 646 stars, 35 forks and 5 open issues, not archived, default branch main, homepage at turaai.net, and a last push on 2026-09-26. The npm description calls it a local AI coding system with Rust services, command packages, TUI and GUI workspaces, and the keywords name tauri alongside rust, tui and cli.
Editorial conclusion
Use this if you are running coding agents on long workflows where five shell commands really do cost five round trips, and if you care that the authors published the gap in their own evidence. Skip it if you need a provider comparison or a cross-platform claim, because the numbers cover one baseline and the roadmap file lists the rest. Before you benchmark it yourself, pin the test set record the README points at, since it lives in a separate repository and can change without a release, and check the version mismatch, because the npm package reads 0.1.37 while the Cargo workspace still reads 0.1.0.
Frequently asked questions
What is Tura written in and how do I install it?
The core is a Rust cargo workspace with eighteen default members, published to npm as tura-ai with a bin entry mapping the tura command to npm/tura.mjs. It requires Node 20 or newer, declares support for darwin, linux and win32, and pins [email protected] as its package manager. Both package.json and Cargo.toml state the licence as AGPL-3.0-or-later.
How does Tura compare with Codex CLI?
The published artifacts compare Tura Balanced, Tura Direct and Codex CLI on 20 DeepSWE tasks, 5 rewrite tasks and 2 separately reviewed design tasks, with each DeepSWE task run three times per agent. Direct used 77.5% fewer aggregate tokens at a 65.0% verifier success rate against 63.3%, while Balanced reached 80.0% using 31.1% fewer tokens and 35.8% fewer turns.
Does Tura replace the model tool calls with a single command?
Yes. Instead of exposing dozens of small tools it exposes one macro tool named command_run, and the agent builds a multi-step execution tree of shell_command and apply_patch entries that run in one LLM turn. The README states plainly that there is no ablation test proving command_run alone causes the lower turn and token usage.
Which model providers has Tura been benchmarked against?
The published numbers compare Tura against Codex CLI only. The README says those results do not establish equivalent quality or performance for every configured provider, and that broader Anthropic/Claude, Google/Gemini, OpenAI-compatible, local-provider, UI-latency, runtime and session parsing, and cross-OS measurements remain part of the roadmap and the documented evidence gaps.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tura-ai-tura)Star history chart for your README
[](https://hysenlabs.com/projects/tura-ai-tura)Was this useful?