tusd is a reference server, and its image runs as uid 1000 with one argument
Reference server implementation in Go of tus: the open protocol for resumable file uploads
At a glance
- What is it?
- tusd is the Go reference implementation of the tus protocol for resumable uploads, with storage backends for local disk, Google Cloud Storage and S3. The repository is unusually inspectable: a Dockerfile that stamps its own version with build flags, a dependency list that includes a network fault injector and a plugin framework, and examples shipping both an Apache and an nginx configuration.
- Who is it for?
- tusd suits an implementer who needs a protocol correct upload server rather than a bespoke one, and who has to support pause and resume across network failures. It does not suit someone who needs a client library or a hosted service, since this is a server and the repository says so.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 10 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
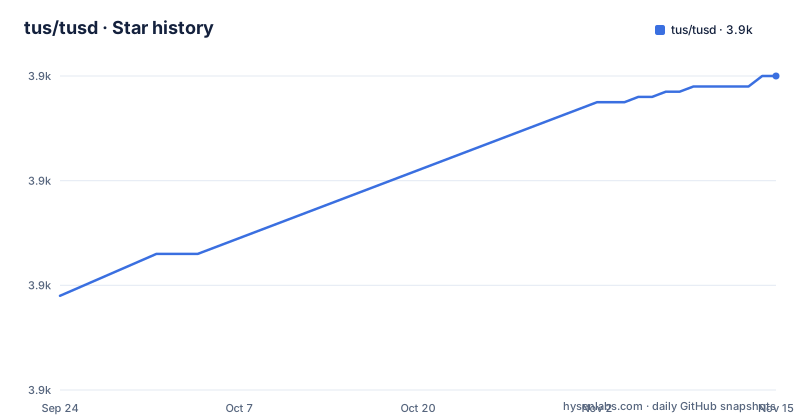
- tus/tusd3,920 ★ · +42
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| tus/tusd | 3.9k | 3.9k |
42 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The protocol is a pause button for an upload
The definition in the README is worth reading closely because it explains the whole design in three clauses. Tus is a protocol based on HTTP for resumable file uploads. Resumable means an upload can be interrupted at any moment and then resumed without re-uploading the data already sent. And the interruption may be either willing, because the user paused, or accidental, because the network failed or the server went away. That second case is the reason the protocol exists: without it, a flaky connection on a large file means starting again, and the client has to know how much the server already has. So the protocol is defined less by the transfer than by the bookkeeping that lets a transfer survive a break, and any client or server that ignores that is not implementing it.
Storage is a boundary, and three cloud SDKs are direct dependencies
The server supports arbitrarily large uploads and storage on local disk, Google Cloud Storage, Azure Blob Storage, or AWS S3 and compatible services. The reason the list can be short is stated in the next sentence, which is about design rather than features: because the project is modularised and extensible, support for nearly any other cloud provider could be added. That claim is checkable in the manifest rather than purely rhetorical, because the module file lists the Google Cloud storage client, the AWS SDK for Go including its configuration and S3 service packages, and the Azure SDK for storage as direct requirements. A fourth cloud is one interface away, and the third is already there for a compatibility path the README does not detail.
Protocol version 1.0.0, server major version 2
Two version numbers sit next to each other and mean different things, which is the first thing to get right. The protocol version is fixed at 1.0.0, so the wire contract is settled. The server has its own major version, and the branch in front of you is version 2, with a pointer to the previous major release at a specific tag for anyone who has not migrated. That tag is named in the file because the second major version introduced breaking changes, so the boundary is drawn in the repository rather than in release notes. The Go module path carries the same boundary as a version suffix, which is the mechanism the language uses to let two incompatible majors coexist in one dependency graph, and the module also declares a recent Go language version rather than an old one.
The image runs as a non-root user and passes one default argument
The runtime stage of the container file is short and every line is a decision. The base is a pinned Alpine release, the working directory is a data directory under the server's own path, and two shell scripts are copied in from the docker directory: an entrypoint and a loader for environment variables. The package install is deliberate, taking certificates, a JSON processor and a shell, which together are what the environment loader needs. Then a group and a user are created with the same numeric identifier, and the data directory is given to them while a separate hooks directory is created. The final four lines are the contract: the port, the user, the entrypoint, and one default argument pointing at that hooks directory. So a hook placed in the mounted directory is picked up without a flag, which is the extension point the README does not mention at all.
Version and commit are stamped with build flags
The build stage is where the version number comes from, and the comment about caching is the part that tells you how the image is maintained. A compiler and its development headers are installed first so that layer is cached, then only the module files are copied and downloaded, and only then the three source directories are copied, each in its own layer, with a comment explaining that directories are special in a container build and so they are copied separately. The binary is cross compiled for the target operating system and architecture, and three values are stamped into it through linker flags: a version name, a git commit, and a build date formatted as UTC. Those three correspond to the version output you would see at runtime, which is why a self-built image reports where it came from rather than only what it is.
The dependency list is a testing and extension toolkit
The direct requirements read like a test plan rather than a runtime list, and grouping them explains the project. Fault injection is there, in the form of a proxy that can sever connections on purpose, which is how a server like this is tested against the failure its protocol is designed for. HTTP mocking and a recording transport are there for the same reason, alongside a property testing library and the usual assertion and mocking libraries. Profiling and metrics clients are there, so a running server can be measured. A structured logger with hooks is there for output. And two requirements are about the server being extensible rather than tested: a plugin framework from a well known provider, and a lock file library published by the same organisation as the protocol, which is the obvious choice for coordinating writes to a shared upload directory.
Examples ship two web servers and a compose file
The examples directory is the fastest way to see what deploying this looks like, and it is broader than a single sample. There is a readme, a compose file, and two separate web server configurations, one for Apache and one for nginx, which tells you the project expects you to terminate TLS or handle routing in front of the server rather than expecting the server to do it. A hooks directory sits alongside them, matching the default argument baked into the container image, and a server directory suggests a runnable configuration. Documentation lives off the repository entirely, on a site that covers installing, using and configuring, and the README is explicit that this is where the content is. The release history is steady rather than rapid, with three releases across the first nine months of 2026 and a push at the start of October.
Editorial conclusion
tusd suits an implementer who needs a protocol correct upload server rather than a bespoke one, and who has to support pause and resume across network failures. It does not suit someone who needs a client library or a hosted service, since this is a server and the repository says so. Before deploying, read the documentation site rather than the README, which is ten lines long, and check the hooks directory default in the container, since the image passes it as its only argument and a missing hook path changes what the server does at the end of an upload.
Frequently asked questions
What is the tus protocol?
An HTTP based protocol for resumable file uploads, where an upload can be interrupted at any moment and then continued without re-uploading the data already transferred. The interruption can be deliberate, such as a user pausing, or accidental, such as a network failure or a server outage.
What storage backends does tusd support?
Local disk, Google Cloud Storage, and AWS S3 or any S3 compatible system. The project describes itself as modularised and extensible, saying support for nearly any other cloud provider could easily be added, and the module file requires the Google, AWS and Azure storage clients directly.
What is the difference between protocol version 1.0.0 and tusd version 2?
The protocol version is fixed at 1.0.0 and describes the wire contract, while the second major version of the server introduced breaking changes. Anyone still on the earlier release is pointed at the previous major version tag, and the Go module path carries a version suffix so both majors can coexist.
How does the tusd container image start?
It runs as a non-root user created with a numeric identifier of 1000, exposes port 8080, and uses an entrypoint script copied into the image. Its single default argument is a hooks directory path, so hooks placed in the mounted directory are picked up without an extra flag.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tus-tusd)Star history chart for your README
[](https://hysenlabs.com/projects/tus-tusd)Was this useful?