jvm-profiler's jar contents depend on the build, so two 1.0.0 jars are not the same jar
JVM Profiler Sending Metrics to Kafka, Console Output or Custom Reporter
At a glance
- What is it?
- uber-common/jvm-profiler is a Java agent for collecting memory, CPU, IO and thread metrics plus stacktraces across the many JVMs of a Spark or Hadoop job. The mechanics are in the details: reporters are compiled in or left out depending on a maven profile, stacktrace sampling is off unless sampleInterval is set, argument profiling puts real argument values into whatever reporter you name, and the config file may be an HTTP URL.
- Who is it for?
- Reach for jvm-profiler when you need one metrics view across the dozens or hundreds of JVMs in a distributed job, and you are willing to rebuild the jar when a reporter is missing. Skip it if you need stacktraces by default, since sampling is off until sampleInterval is set, or if you cannot accept that argument profiling writes real argument values to your reporter.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 179 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
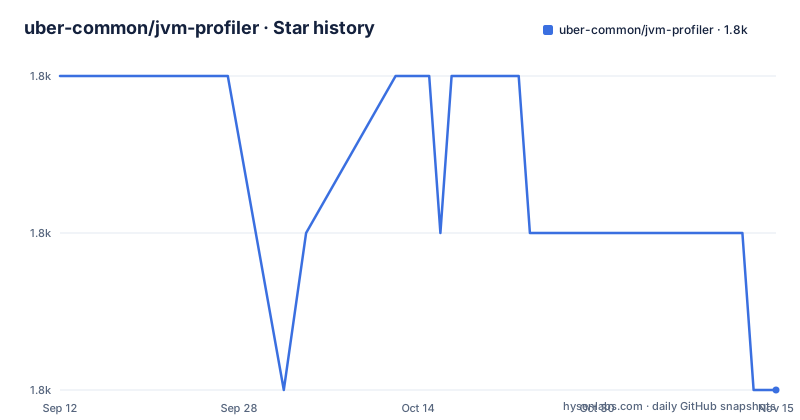
- uber-common/jvm-profiler1,800 ★ · -2
| Repository | 2026-09-12 | 2026-11-15 |
|---|---|---|
| uber-common/jvm-profiler | 1.8k | 1.8k |
-2 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The jar is different depending on which profile you build with
The build is a single maven command, and the first requirement is JDK 8 or newer plus maven:
mvn clean packageThat produces `jvm-profiler.jar` with the default reporters inside it, which the README names as ConsoleOutputReporter, FileOutputReporter and KafkaOutputReporter. The reporters that talk to external stores, RedisOutputReporter and InfluxDBOutputReporter, are not in that jar. To get one you pass a maven profile id:
mvn -P redis clean packageand the README points you at `pom.xml` for the list of available reporters and their profile ids, which means the set of valid profile ids is documented nowhere except in the build file.
The consequence is worth stating plainly. Two people who both call it version 1.0.0 can hold jars with different classes inside, and a command line naming `com.uber.profiling.reporters.RedisOutputReporter` fails on one machine and works on another for reasons that have nothing to do with the code. When you distribute the agent, the build profile is part of what you are distributing.
Every example names version 1.0.0 and there are no releases
All five run examples in the README name the same artifact, `jvm-profiler-1.0.0.jar`, in a path under `target/` or `/opt/jvm-profiler/target/`. The path shape tells you the jar is a build output rather than a downloaded release.
The repository has no GitHub releases at all, so there is no tag to compare that filename against, and the last commit on the default branch, `master`, is dated 2026-05-21. So the version in the documentation is the best available marker and nothing confirms it matches a built jar.
Continuous integration is a single `.travis.yml` at the root, and the README's only badge points at `travis-ci.org/uber-common/jvm-profiler/`. There is no other CI configuration in the tree. Combined with the absence of releases, that means the state of this project is read from its commit history rather than from published artifacts, and there is no mechanism in the repository that would tell a user which build they have.
The Spark example attaches to executors, and the driver is not in it
The reason the project exists is stated in the README's own terms: a single Spark application usually has dozens or hundreds of processes and machines, and the point of the agent is to let you correlate metrics across them. It was created to profile Spark applications, and it is described as a generic Java agent usable for any JVM process afterwards.
Running it means putting the jar where the executors can reach it, then passing two Spark settings:
--conf spark.jars=hdfs://hdfs_url/lib/jvm-profiler-1.0.0.jar
--conf spark.executor.extraJavaOptions=-javaagent:jvm-profiler-1.0.0.jar
The jar goes to HDFS, and the second line attaches the agent through the executor JVM options. What the example does not set is the driver equivalent. `spark.executor.extraJavaOptions` covers the executors only, so the driver process in this configuration runs without the agent, which for a job whose whole premise is a correlated picture across all its processes is the gap to check first.
Everything the agent needs travels in that one `key=value,key=value` string after the jar name, which is the same grammar in every launch method the README shows.
Argument profiling puts real values into the reporter
The feature that is most worth reading twice is argument profiling. `argumentProfiling` takes a method and an argument index, and the README explains that `.1` means the value of the first argument is read and sent out in the reporter. The example combines it with a method named `publicSleepMethod`:
java -javaagent:target/jvm-profiler-1.0.0.jar=reporter=com.uber.profiling.reporters.ConsoleOutputReporter,tag=mytag,metricInterval=5000,durationProfiling=com.uber.profiling.examples.HelloWorldApplication.publicSleepMethod,argumentProfiling=com.uber.profiling.examples.HelloWorldApplication.publicSleepMethod.1,sampleInterval=100 -cp target/jvm-profiler-1.0.0.jar com.uber.profiling.examples.HelloWorldApplicationThe README's own motivation for the feature is tracing the HDFS file paths each application reads or writes, to find hot files. Those paths are user data, and where they end up is decided entirely by the `reporter` you name on the same command line.
The Kafka example shows one destination:
java -javaagent:target/jvm-profiler-1.0.0.jar=reporter=com.uber.profiling.reporters.KafkaOutputReporter,metricInterval=5000,brokerList=localhost:9092,topicPrefix=profiler_ -cp target/jvm-profiler-1.0.0.jar com.uber.profiling.examples.HelloWorldApplicationWith `topicPrefix=profiler_` the metrics go to the topic `profiler_CpuAndMemory`. Anything argument profiling captured on the same run goes there too.
There is a second network path in the parameters. `configFile` is a path used by the YAML config provider and the README says it can be a local file path or an HTTP URL, so the agent will read its configuration over the network at startup.
sampleInterval is the switch that turns stacktraces on
Stacktrace profiling, and therefore flamegraphs, is off by default. The parameter list says `sampleInterval` is the frequency in milliseconds for stacktrace sampling, and that if the value is not set or is zero the profiler will not do stacktrace sampling at all. The examples disagree with each other about the value, and both are valid: the HelloWorld example uses `sampleInterval=100`, while the executable jar, Tomcat and Spring Boot examples all use `sampleInterval=5000`.
That five second default in the copy and paste examples is a one in five hundred sampling rate, which is a different diagnostic from a one in one hundred one.
The flamegraph step is manual rather than built in. The feature list says the profiler does stacktrack profiling and generates a flamegraph to visualise CPU time, and the root of the repository holds `stackcollapse.py` for folding sampled stacks, alongside `metricDetails.md` for the metric format. The blog post at eng.uber.com/jvm-profiler is the pointer for the rest of the details.
The other measured families are memory, with heap, non-heap, native values such as VmRSS and VmHWM, memory pools and the direct and mapped buffer pools; CPU and garbage collection time; IO, with disk read and write bytes and machine CPU iowait; and threads, with total, peak, live or active, and newly created counts.
Four launch paths deliver the same agent string
Everything the README shows is the same `-javaagent` string placed in a different place. For a plain application it goes on the command line. For Tomcat it goes into the environment before startup:
export CATALINA_OPTS="$CATALINA_OPTS -javaagent:/opt/jvm-profiler/target/jvm-profiler-1.0.0.jar=reporter=com.uber.profiling.reporters.ConsoleOutputReporter,metricInterval=5000,durationProfiling=foo.bar.FooController.barMethod,sampleInterval=5000"and the metrics land in `logs/catalina.out`. For a Spring Boot 2.x project it is passed as a maven property, `-Dspring-boot.run.jvmArguments`, with the note that Spring Boot 1.x needs `-Drun.arguments` instead, so the same agent has two different property names depending on the major version. For an executable jar it is prepended to the `java` invocation alongside `-jar`.
Two small details in those examples are worth knowing before you copy them. The Spring Boot and Tomcat examples profile `foo.bar.FooController.barMethod`, a class that only exists in the sample application, and the executable jar example misspells the same idea as `foo.bar.FooAppication.barMethod`, with the second `l` missing. Wildcards are supported by the parameter itself, so `com.uber.profiling.examples.HelloWorldApplication.*` instruments every method in a class, which is the convenient form and also the most expensive one.
Three licence files at the root and no recorded licence
The top-level entries include `LICENSE`, `NOTICE` and `epl-v10.txt`, while no licence at all is recorded in the repository metadata. The third file is the Eclipse Public License version 1.0 text sitting next to the other two, and the README does not say which of them governs the code or whether they cover different parts of it.
That is a real question for anyone who wants to use the agent in a product rather than to profile a Spark job, and it cannot be settled from the file list alone. The safe move is to read all three and, if the relationship is not stated, ask.
The project is otherwise self-contained in a way that helps. Alongside the licence files there is `metricDetails.md` for the metric format, `stackcollapse.py` for the flamegraph step, and a `src/` directory, with no build wrapper or vendored dependency tree at the root. Metrics are structured rather than log lines, which is what makes the correlation across dozens of JVMs possible in the first place.
Editorial conclusion
Reach for jvm-profiler when you need one metrics view across the dozens or hundreds of JVMs in a distributed job, and you are willing to rebuild the jar when a reporter is missing. Skip it if you need stacktraces by default, since sampling is off until sampleInterval is set, or if you cannot accept that argument profiling writes real argument values to your reporter. Before you deploy it, read the three licence files at the root, since the repository records no licence, and check whether the reporter you name receives the argument values you enabled, because the Kafka path puts them on a topic.
Frequently asked questions
What does uber-common/jvm-profiler collect?
Memory metrics including heap, non-heap, native values such as VmRSS and VmHWM, memory pools and buffer pools; CPU usage and garbage collection time; IO metrics with disk read and write bytes and machine iowait; thread counts for total, peak, live and new; plus duration profiling, argument profiling and stacktrace sampling for flamegraphs.
How do I build the jvm-profiler jar?
With JDK 8 or newer and maven installed, run `mvn clean package`. That bundles the console, file and Kafka reporters. Reporters such as RedisOutputReporter and InfluxDBOutputReporter need a maven profile id, for example `mvn -P redis clean package`, and the README says to check pom.xml for the available ids.
How do I attach jvm-profiler to a Spark application?
Upload the jar to HDFS so the executors can read it, then set spark.jars to the hdfs path and spark.executor.extraJavaOptions to the -javaagent string. Note that the example profiles executors only, since it does not set the driver equivalent.
Why is there no flamegraph from jvm-profiler by default?
Because stacktrace sampling is off until sampleInterval is set, and the README says sampling does not happen when the value is unset or zero. The examples use 100 in one case and 5000 in the others, and the flamegraph step itself is manual using the stackcollapse.py script in the repository root.
What does argumentProfiling do in jvm-profiler?
It captures the value of a method argument and sends it to the reporter, with .1 meaning the first argument. The README motivates it with tracing HDFS file paths per application, so the values captured are user data and they land wherever the configured reporter sends them, including a Kafka topic such as profiler_CpuAndMemory.
Which licence applies to jvm-profiler?
The repository records no licence in its metadata, while the root holds LICENSE, NOTICE and epl-v10.txt, the last of which is the Eclipse Public License 1.0 text. The README does not say how the three relate, so the terms have to be read from the files.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/uber-common-jvm-profiler)Star history chart for your README
[](https://hysenlabs.com/projects/uber-common-jvm-profiler)Was this useful?