UditAkhourii/adhd: a divergent-ideation skill that fans out isolated reasoning frames and prunes the traps
ADHD — a skill for coding agents. Tree-of-thought with pruning, built on the Claude & Codex Agent SDK. Fans out parallel divergent thoughts under different cognitive frames, scores, prunes traps, deepens the survivors. The no-brainer skill for creative and interdisciplinary work.
At a glance
- What is it?
- adhd-agent is a TypeScript skill and library for coding agents that runs several isolated reasoning processes under distorted cognitive frames, then scores, clusters and prunes the results. The name is a pun on divergent thinking, and the evidence for its quality is mostly the author's own.
- Who is it for?
- Install it if you regularly ask an agent for design options, names or strategy and want several independent framings with traps flagged. Skip it for questions with one correct answer, and treat the published eval numbers as one author-run problem until you have run npm run evals on your own prompts.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 21 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
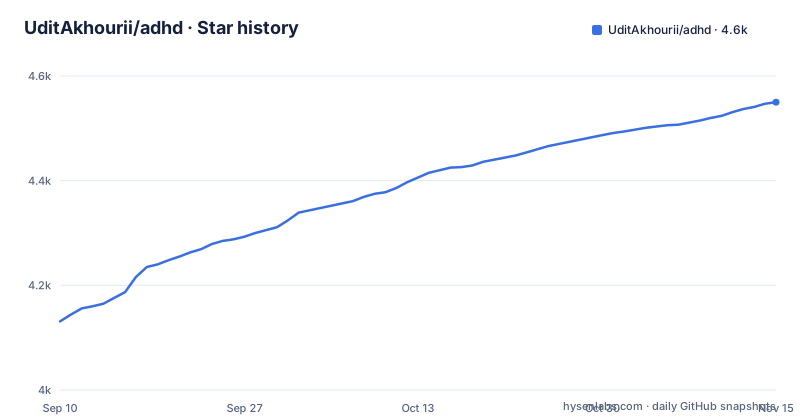
- UditAkhourii/adhd4,550 ★ · +419
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| UditAkhourii/adhd | 4.1k | 4.6k |
419 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Isolated frames are the fix for anchoring that shared context cannot provide
The project starts from a diagnosis. Linear chain-of-thought anchors on whatever it says first. Tree-of-thought widens the search but still walks a single shared context, so the anchoring persists across branches. ADHD treats this as an architectural problem, not a prompting one.
Its answer is to spawn N isolated reasoning processes under deliberately distorted cognitive frames, with zero shared context during divergence. Because no frame sees what another wrote, one early idea cannot pull the rest toward it. The cost of that design is that you get N separate runs of reasoning instead of one, so a single question turns into several model sessions. The skill is built on the Claude Agent SDK, and the repository description also names Codex.
A separate critic pass scores, clusters, prunes traps and deepens the survivors
Divergence is only the first stage. After the isolated frames finish, a separate critic pass scores the ideas, clusters them, prunes the traps and deepens the survivors. The programmatic result exposes each stage as a field, which shows the shape of the output:
// result.shortlist · result.nonObviousPick · result.traps · result.deepened · result.clustersThe split between generation and judgement is the point. A frame that invents an idea is not the one grading it. In the README's worked example the critic produced clusters named economic-incentive, async-control-surface, gamification, perceptual-distortion, collective-intelligence and redundancy-race. Trap flags come with one-line reasons, so a rejected idea tells you why it was rejected, and you can overrule the critic if you disagree with a stated reason.
The side-by-side comes from a single problem about a CLI that hangs for 90 seconds
The README shows one eval problem: a CLI that calls an LLM and sometimes hangs for 90 seconds, with the task of designing the retry, timeout and UX strategy. Baseline, a single shot, gives four textbook patterns and lands on a hybrid with a 15s first-token timeout, a 30s between-token timeout, 90s absolute and one auto-retry. ADHD spawned 6 isolated frames, surfaced 30+ ideas and flagged 20 traps. Its non-obvious pick was an instant abort that branches to a cheaper, faster model, on the idea that the slow model might be the wrong model for this prompt.
An independent LLM judge scored breadth 9 vs 6, novelty 8 vs 3 and trap detection about 8 vs about 2. Those are the author's published numbers on one problem. They show one case where the method found a framing the baseline missed. They do not tell you how often that happens, and the methodology is in documentation/evals.md. Full transcripts are in bench/results.json.
One npx command detects your agent, while the npm installs add a CLI or a library
The primary install is a single command that auto-detects the agent you use, with Claude Code, Cursor, Antigravity, Codex, Cline, Gemini CLI and Windsurf named, plus about 50 more:
npx skills add UditAkhourii/adhdAfterwards you invoke it explicitly with /adhd "your problem", or let it auto-trigger on ideation intents. Auto-triggering means a prompt phrased as brainstorming can start a multi-frame run without you typing the command. The package is also published as adhd-agent, in two forms:
npm install -g adhd-agent     # CLI
npm install adhd-agent        # library
The package.json sets engines node to >=18, exposes an adhd binary at dist/cli.js, and ships dist, skills, SOURCE-SPEC.md, README.md and LICENSE. The Codex quick path, manual curl for other agents and per-platform paths are in documentation/install.md.
The CLI exposes frame, idea and top counts, and the library mirrors them as options
Running the tool directly takes a problem string and three tuning flags:
adhd "design a rate limiter that survives a leader election"
adhd "name this function" --frames 3 --ideas 8 --top 2
The second line shrinks the run: 3 frames, 8 ideas and a top 2 shortlist. Fewer frames means fewer isolated processes and less spend, but also fewer chances for a distorted framing to hit something useful. The library takes the same knobs under different names, framesPerRun and topK:
import { run, renderText } from "adhd-agent";

const result = await run({ problem: "How should we shard this queue under bursty load?", framesPerRun: 5, topK: 3 });
console.log(renderText(result));
renderText turns the result into readable text. The README points to documentation for the full API reference, which this article does not reproduce.
The method is aimed at open-ended prompts and does not help with questions that have one answer
The README tells you where to reach for it: design decisions, fuzzy debugging, naming, API surface design, strategy, and any prompt of the shape "give me a few ways to…". Every item there is a question with many acceptable answers and a cost for picking the wrong direction early.
That is also the boundary. A prompt with one correct answer, such as a factual lookup, gains nothing from six distorted frames and a trap-pruning pass, and you would still pay for the extra sessions. The skill also does not claim to decide for you. Its output is a shortlist, a non-obvious pick, flagged traps and deepened survivors, so you still read and choose. Because the frames are deliberately distorted, some ideas will be impractical by design, which is why the trap list exists.
Version 0.1.4, SDK range ^0.1.0 and self-reported adopters mark an early project
The latest release is v0.1.4, tagged on 2026-05-30 and titled around community opening, Codex compatibility and a first open source adopter. The repository is not archived and the last push was on 2026-10-25. It is MIT licensed, written in TypeScript, and declares @anthropic-ai/claude-agent-sdk at ^0.1.0 with p-limit and zod as its other runtime dependencies. A 0.1 range on the SDK and a 0.1 version on the package mean you should pin and test upgrades.
The README claims 17+ projects ship or integrate ADHD and lists repowire, mstack, zk-flow-oss, han, wtfismyrepo and awesome-prompts, with the full table in ADOPTERS.md. Adopters add themselves through a pull request or issue, so the count is self-reported. The scripts include npm test, npm run typecheck, npm run evals and npm run evals:quick, which lets you re-run the benchmark yourself.
Editorial conclusion
Install it if you regularly ask an agent for design options, names or strategy and want several independent framings with traps flagged. Skip it for questions with one correct answer, and treat the published eval numbers as one author-run problem until you have run npm run evals on your own prompts.
Frequently asked questions
What is UditAkhourii/adhd?
It is a skill for coding agents, published as the npm package adhd-agent, that fans out parallel divergent thoughts under different cognitive frames, scores them, prunes traps and deepens the survivors.
How do I install the ADHD skill for my agent?
Run npx skills add UditAkhourii/adhd, which auto-detects your agent. Then call /adhd "your problem" or let it auto-trigger on ideation intents.
When should I use the ADHD skill for coding agents?
Use it for design decisions, fuzzy debugging, naming, API surface design, strategy, and prompts shaped like "give me a few ways to…", where several independent framings are worth the extra runs.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/uditakhourii-adhd)Star history chart for your README
[](https://hysenlabs.com/projects/uditakhourii-adhd)Was this useful?