NeuroArxiv: one isolated read per paper, then one committed recommendation
A skill to kill from-scratch coding — Claude checks real arXiv prior art before it designs a new architecture.
At a glance
- What is it?
- NeuroArxiv is a TypeScript skill that makes a coding agent check arXiv before it designs anything. Each paper is read in a separate isolated pass, and the run ends in a single recommendation with citations rather than a list for you to choose from.
- Who is it for?
- Adopt NeuroArxiv when you are about to write a non-trivial component and there is prior art worth finding, because the isolation discipline is the part that produces its own results and a list of papers would not. Leave it alone when your problem has no academic literature, since the fetcher is arXiv-only and the project's own evaluation says it loses on citation breadth against general web search.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 59 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
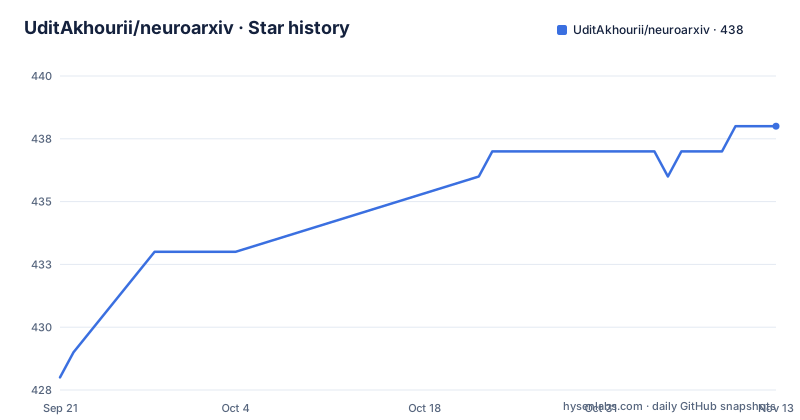
- UditAkhourii/neuroarxiv438 ★ · +10
| Repository | 2026-09-21 | 2026-11-13 |
|---|---|---|
| UditAkhourii/neuroarxiv | 428 | 438 |
10 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Isolate-then-converge is the entire design
The pitch is one line: before Claude designs something new, it checks arXiv first. The mechanics are worth more than the pitch.
Step zero maps your problem onto three to five arXiv categories plus search terms. Step one fetches real metadata over HTTP against `export.arxiv.org`, category by category, with no model in the loop at all, which the README calls deterministic and courtesy-rate-limited. Step two is the unusual one: one isolated read per paper, in parallel, where each read sees one abstract and never the others.
That isolation is the mechanism. A model reading five abstracts at once tends to anchor on the first plausible one, and the papers reinforce each other into a consensus that no single paper supports. Separate reads remove the anchor.
Step three scores each paper on relevance, practicality and rigor, then clusters them by underlying architectural angle. Step four converges: one cluster becomes the recommended path, with the runner-ups explicitly explained and a note on what to watch for in the paths not taken.
Fetch has no model in it, on purpose
Splitting the pipeline into an LLM half and a non-LLM half is what makes the results checkable. Retrieval is a plain HTTP client walking category listings, rate-limited out of politeness to arXiv, with no generation anywhere in that step.
That means the paper list cannot be hallucinated at the retrieval stage. The IDs and links come from the export API or they are not there, and the README states that every claim traces to a fetched abstract, with papers, ids and links being real arXiv metadata rather than invented ones.
The model is fenced further downstream. The read prompt is explicitly forbidden from quoting more than a few words verbatim, and the skill's own anti-patterns section names hallucinated citations as the failure mode to watch for. A tool that asks a model about papers has an obvious way to go wrong, and this one writes the constraint down rather than hoping.
The runtime dependencies follow the same split: `p-limit` for the parallel reads, `zod` for schemas, and the Claude agent SDK for the model calls.
The evaluation measures source skepticism, not a ratio
The project's comparison is deliberately built to be hard to win. Same model, same five cross-domain problems spanning physics, applied math, quantitative biology, machine learning and statistics, three conditions run independently, and a sample of the web-search condition's citations was checked against the real arXiv API before anything was scored.
The metric is not a quality ratio. Every transcript was re-read for one pattern: does the answer name a source it just cited and flag a real limitation in that source's own claim, rather than a generic risk. On that pattern the cold condition and the plain web-plus-arXiv condition scored zero out of five, and NeuroArxiv scored five out of five, with seven flags in total across the five problems.
Two examples are named. It caught a withdrawn proof it had itself cited and declined to rely on it, and it caught a benchmark result validated at only one context length and flagged it before recommending the approach.
The project also reports where it loses. On raw answer quality the margin over web search was a modest 1.1x to 1.3x, and citation breadth was worse in two of the five problems, because arXiv-only search has a narrower net than general web search.
Install is one npx line, and both agents read the same file
npx github:UditAkhourii/neuroarxiv installNo clone and no build step of your own. Claude Code and Codex CLI both discover skills at `<agent home>/skills/<name>/SKILL.md` and read the same frontmatter, so one bundled skill serves both, and `install` picks whichever agents it finds on the machine.
You can override the detection with `--claude`, `--codex` or `--all`, which installs into `~/.claude/skills/neuroarxiv`, `~/.codex/skills/neuroarxiv`, or both regardless of whether they were detected. `CLAUDE_CONFIG_DIR` and `CODEX_HOME` are honoured if you keep those directories somewhere non-default, which is the detail that matters for anyone with a portable agent setup.
Restart the agent afterwards. In Claude Code you invoke it as `/neuroarxiv "<problem>"`, and in Codex you ask for it by name.
If you want the engine locally, to edit it or run the CLI directly, the full checkout path is a clone, `npm install`, `npm run build` and `node dist/cli.js install`.
Inside Claude Code you can skip the install entirely
The skill file at `skills/neuroarxiv/SKILL.md` runs the same loop using `WebFetch` against arXiv's export API directly. No install is required to try it once, which is the cheapest way to find out whether the discipline suits you before you commit to a package.
From a shell, the CLI takes a problem string and a paper count:
neuroarxiv "cache LLM completions across requests without serving stale answers"
neuroarxiv "leader election for a queue with flaky nodes" --papers 6
The package itself is small. `package.json` names it `neuroarxiv-agent` at version 0.1.0, exposes a single binary at `dist/cli.js`, requires Node 18 or newer, and ships three runtime dependencies. Tests run through `node --import tsx --test tests/*.test.ts`, typechecking is a separate `tsc --noEmit` target, and the build is plain `tsc`, so there is no bundler in the path.
Every claim is supposed to trace to a fetched abstract
This is the constraint that makes the rest credible, and it is enforced in three places rather than one.
Retrieval returns real metadata. The read prompt cannot quote more than a few words verbatim, which keeps long passages from appearing in a summary as if the model had read them closely. And the skill's anti-patterns section calls out hallucinated citations by name, so a failure shows up as a known failure mode rather than as a surprise.
Convergence is the second constraint. Instead of returning four papers and a shrug, the run commits to one path, says why the others lost, and names the failure modes to avoid in the paths it rejected. That is a much harder thing to produce, and it is the reason the tool is framed around decisions rather than around literature review.
The evaluation transcripts are committed too, under `bench/`, alongside `EVALS.md` for the methodology. A tool whose headline claim is a behavioural pattern should let you read the transcripts where the pattern did not hold.
Version 0.1.0, MIT, and a master branch with no releases
The project is MIT licensed and the default branch is `master`, which is worth knowing before you script anything against it. There are no GitHub releases, and `package.json` carries version 0.1.0, so the npm-style tag and the commit history are the only version signals available.
The last push was on 2026-09-17. The tree is small enough to read in one sitting: `src/`, `skills/`, `tests/`, `bench/`, `Assets/`, `EVALS.md`, a `.claude-plugin/` directory, and the usual config.
There is also a community layer around it, a Discord for live discussion of arXiv coverage, eval design and prior-art hunting, a short form for contributing or adopting the skill, and a longer write-up on the author's blog. The category taxonomy is described as community-contributed, which means coverage of any given arXiv category is partly a function of who showed up.
For a 0.1.0 tool whose value depends on retrieval quality, that is the piece to weigh: the pipeline is fixed, the taxonomy behind it is not.
Editorial conclusion
Adopt NeuroArxiv when you are about to write a non-trivial component and there is prior art worth finding, because the isolation discipline is the part that produces its own results and a list of papers would not. Leave it alone when your problem has no academic literature, since the fetcher is arXiv-only and the project's own evaluation says it loses on citation breadth against general web search. Three things to check before you rely on a run. Look at `bench/deep-tech-eval-transcripts.md` rather than the summary table, since the headline number is a source-skepticism pattern and the project is candid about the two problems where it cited less than the baseline. Confirm your agent reads the skill at `<agent home>/skills/<name>/SKILL.md`, because an install into the wrong home is the usual reason nothing happens. And note the package is version 0.1.0 with no GitHub releases, the default branch is `master`, and the last push was 2026-09-17, so treat the engine as young and read `src/` before you depend on its scoring.
Frequently asked questions
What does NeuroArxiv do before Claude writes code?
It maps the problem onto three to five arXiv categories, fetches real metadata over HTTP from export.arxiv.org with no model in that step, reads each paper in an isolated pass where the model sees one abstract and never the others, scores and clusters them, then commits to one recommended path with citations and a first step.
How do I install NeuroArxiv?
Run `npx github:UditAkhourii/neuroarxiv install`. Claude Code and Codex CLI both read skills from `<agent home>/skills/<name>/SKILL.md`, so one bundled skill covers both, and `--claude`, `--codex` or `--all` pins a target regardless of detection. CLAUDE_CONFIG_DIR and CODEX_HOME are honoured.
Can I try NeuroArxiv without installing it?
Inside Claude Code, yes. The bundled skills/neuroarxiv/SKILL.md runs the same loop using WebFetch against arXiv's export API directly. From a shell, a full checkout needs npm install, npm run build and node dist/cli.js install, and the package requires Node 18 or newer.
Does NeuroArxiv return several options to choose from?
No. It picks one cluster as the recommended path, states why the runner-ups lost, and names what to watch for in the paths it did not take. Papers are grouped by underlying architectural angle before that choice is made.
What did the NeuroArxiv evaluation find?
Across five cross-domain problems in three independently run conditions, the source-skepticism flag appeared in 5 of 5 NeuroArxiv runs and 0 of 5 for both a cold condition and plain web plus arXiv, with seven flags in total. It also reports losing on citation breadth in two of five problems, and the full scorecard is in EVALS.md.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/uditakhourii-neuroarxiv)Star history chart for your README
[](https://hysenlabs.com/projects/uditakhourii-neuroarxiv)Was this useful?