unstructured: open-source parsing, with chunking and embedding pitched to an enterprise Platform
Convert documents to structured data effortlessly. Unstructured is open-source ETL solution for transforming complex documents into clean, structured formats for language models. Visit our website to learn more about our enterprise grade Platform product for production grade workflows, partitioning, enrichments, chunking and embedding.
At a glance
- What is it?
- The unstructured library is an Apache-2.0 set of open-source components for ingesting and pre-processing documents such as PDFs, HTML and Word files into structured elements for language model pipelines. The front page is candid about where that ends. The repository description points to an enterprise-grade Platform product for production workflows, partitioning, enrichments, chunking and embedding, and the README pitches a separate Transform v2 API for higher-quality output.
- Who is it for?
- Unstructured is a defensible choice for the parsing stage of a document pipeline, particularly in a container where you want one image covering many formats rather than assembling LibreOffice, Tesseract and poppler yourself. Three things to weigh.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly HTML, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
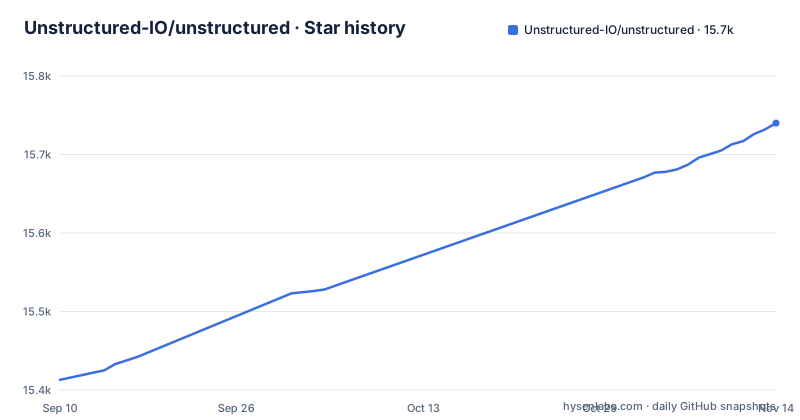
- Unstructured-IO/unstructured15,740 ★ · +327
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| Unstructured-IO/unstructured | 15.4k | 15.7k |
327 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The library parses, and the front page sells the rest
Read the two halves of this front page together.
The open-source half provides components for ingesting and pre-processing images and text documents, PDFs, HTML, Word docs and more, so that data processing workflows for language models are streamlined. That is the partitioning stage.
Then the repository description points readers to an enterprise-grade Platform product for production-grade workflows, partitioning, enrichments, chunking and embedding, and the README offers the Transform v2 API for higher-quality output, citing 0.878 text accuracy against 0.715 for the open-source library.
So chunking and embedding, which most people picture when they say document pipeline, are what the description pitches for the commercial Platform.
Plan your architecture around that line rather than assuming the whole pipeline is free.
The documented pull command uses the latest tag
The quick start is a pull, a run, and an exec:
docker pull downloads.unstructured.io/unstructured-io/unstructured:latestwith a container created from the same latest tag and then a shell inside it.
Images are built for every push to main and carry three tags: the short commit hash, the application version, and latest on the most recent image. Multi-platform images cover x86_64 and Apple silicon, with --platform available if you need to override it.
So the reproducible tag exists and is not the one you are told to use. Two installs a month apart pull different code under the same name, with no warning.
Pull by commit hash for anything you intend to keep running.
The base image is unpinned and the README admits builds can break
The container is built from a wolfi-base image on its latest tag, and the README says plainly that if you are building the image locally it is possible the docker-build target could fail due to upstream changes in that base.
That is an unusual thing to document and a useful one. A build that fails because the base image moved is not your bug, and without that note you would spend time bisecting your own changes.
It also means the build is not hermetic. The same commit produces a different result over time, and there is no digest pinned anywhere in the instruction.
The Dockerfile leans on system packages to do the real work: LibreOffice for office formats, Tesseract with its tessdata and tessconfigs cloned at build time, poppler for PDF, openjpeg, libmagic and cmake. A change in any of those upstream repositories can move your parser behaviour without a version bump on your side.
Accept that, or build your own base and pin it.
Customising an image means editing the Dockerfile
The library installs in layers, and the layering is by document type.
A plain pip install covers plain text files, HTML, XML, JSON and emails that need no extra dependencies. Other formats need extras: the all-docs extra for everything, or a narrower combination such as docx and pptx. On Windows there is a separate conda route documented elsewhere.
The image route mirrors that. The README notes that if you only plan on parsing one type of data you can speed up building the image by commenting out the packages and requirements needed for other data types, and to look at the Dockerfile to see which lines are necessary for your case.
That advice is practical and it has a lasting consequence. A customised image is no longer built from a tracked file, it is built from your edited copy of one, and the project keeps changing the original. Every upgrade then becomes a merge rather than a pull.
Only customise if the build time actually hurts you, and track your Dockerfile.
Python support stops below 3.14
The manifest sets the supported range as Python 3.11 up to but not including 3.14, and the classifiers list 3.11, 3.12 and 3.13.
So the range and the classifiers agree with each other, and together they exclude the next interpreter. That upper bound is the kind of decision a project makes when it has not yet validated a release, and it has to be revisited by shipping a new version rather than by configuration.
The container does not help you here either, because it pins an interpreter explicitly, with a build argument defaulting to Python 3.12, which is inside the supported range. Running the library outside the image on 3.14 is what the bound rules out.
If you are standardising on a newer Python, wait for the cap to move rather than forcing the install, and check the bound again at each upgrade.
Beta status on a 0.27 line with releases days apart
The manifest classifies this project as Development Status 4, Beta, and the release numbers are still in the zero series. The three most recent releases are 0.27.36, 0.27.35 and 0.27.34, published within an eight day window.
Pre-1.0 with that cadence means minor bumps are where breakage lives, because there is no compatibility promise attached to the minor version yet. A rapid release train also means the branch is not a stable base to track.
The commit activity is not the concern here. The repository is not archived and main was pushed on 2026-11-02, so work is continuous.
Pin an exact version rather than a range, and read the changelog before taking a patch bump, because the gap between releases is measured in days.
A hosted MCP server sits alongside the local library
The README also promotes a hosted alternative to the library: the Transform v2 API. It claims 2x table content accuracy, 58% less invented content and 0.878 text accuracy against 0.715 for the open-source library.
Notice where those numbers come from. The open-source figures cite the project's benchmarks page (1,000+ pages), while the Transform figures come from SCOREBench on 224 pages in Sept 2026, so the two are not measured on the same set.
So there are three tiers here rather than one: the local library for partitioning, the container for a bundled runtime, and a hosted API. Pick the tier deliberately, because the third sends your documents somewhere.
Editorial conclusion
Unstructured is a defensible choice for the parsing stage of a document pipeline, particularly in a container where you want one image covering many formats rather than assembling LibreOffice, Tesseract and poppler yourself. Three things to weigh. Decide early whether you need chunking and embedding, because those are the features the project pitches for its commercial Platform. Pin your image by commit hash rather than using the latest tag the front page suggests. And note the package still declares itself beta on a 0.27 line, so pin the Python version too.
Frequently asked questions
Is unstructured free to use?
The library is open source under the Apache-2.0 licence and can be installed with pip, including per-format extras or an all-docs extra. The README says the open-source library is, and will stay, completely free, while the repository description points to an enterprise-grade Platform product for chunking and embedding, so the free part covers ingestion and pre-processing.
how to install unstructured
Use pip install "unstructured[all-docs]" for full document type support, or a plain pip install unstructured for text, HTML, XML, JSON and emails that need no extra dependencies, or a narrower extra set such as "unstructured[docx,pptx]". There is also a Docker route and separate conda instructions for Windows.
how to use unstructured
Import a partition function for the format you need and pass it a filename, so partition_pdf for a PDF or partition_text for a plain text file, each returning a list of elements. The README demonstrates this from a Python console inside the container, which is the easiest way to try it before installing anything.
how to use unstructured library in python
The partition functions are namespaced by format, imported from paths such as unstructured.partition.pdf and unstructured.partition.text, and called with a filename to return parsed elements. The project supports Python 3.11 through 3.13, with an upper bound below 3.14 declared in its manifest.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/unstructured-io-unstructured)Star history chart for your README
[](https://hysenlabs.com/projects/unstructured-io-unstructured)Was this useful?