nvidia_gpu_exporter runs as uid 65534 because a named user would break Kubernetes
Nvidia GPU exporter for prometheus using nvidia-smi binary OR using NVML
At a glance
- What is it?
- This Prometheus exporter reads GPU metrics by parsing nvidia-smi, with an optional native backend that calls the driver library directly. The engineering notes are unusually candid: the image deliberately avoids a distroless no-SSL base, the user is numeric on purpose, and the maintainer opens the page by saying it is a spare time project.
- Who is it for?
- This is the exporter to reach for when nvidia-smi is your only uniform source, which is exactly the consumer card, virtualized guest and homelab case it names. Its dependency surface is deliberately small, since the default backend shells out rather than linking the driver, which is why it runs on Windows and macOS from the same codebase.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 19, 2026, and from our analysis. They are not legal advice.
Star history
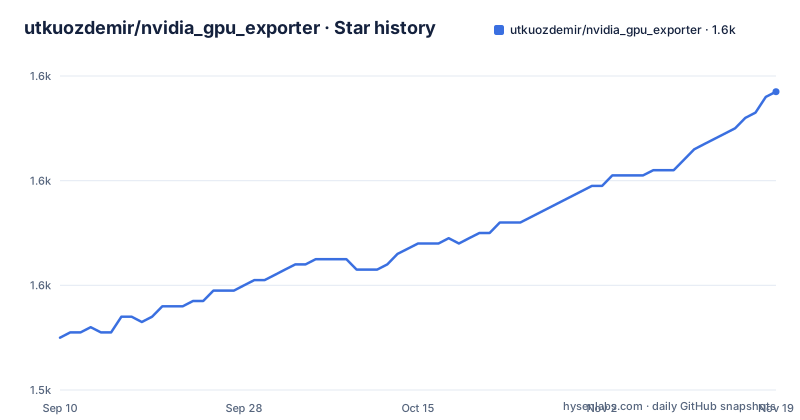
- utkuozdemir/nvidia_gpu_exporter1,597 ★ · +47
| Repository | 2026-09-10 | 2026-11-19 |
|---|---|---|
| utkuozdemir/nvidia_gpu_exporter | 1.6k | 1.6k |
47 Stars in the last 70 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The default backend shells out instead of linking the driver
The core design decision is that the exporter parses the output of a command-line tool rather than calling the vendor library. That single choice is what makes the project portable: the same binary works on Linux, Windows and macOS, on bare metal, in a container or on Kubernetes, and the page says explicitly that no C bindings are required.
The trade is fidelity. Where the datacenter tooling exposes deep counters, this approach sees what a command line utility prints, which for consumer cards is often the only uniform source of utilization, memory, power and temperature. The project is candid that on datacenter cards with the GPU Operator already installed, the vendor's own exporter is the better fit, and positions itself for the cases where it is not.
Two optional behaviours sit on top. Per-process metrics show which process is using how much GPU memory, and background collection runs the command on a timer instead of on every scrape. The second one matters for a slow or heavily shared machine, where a per-scrape invocation is a latency problem rather than a convenience.
The exporter can also be pointed at a remote machine to run the command there, so the monitoring process need not live on the box holding the GPU.
The native backend promises identical metrics and adds four families
An optional backend reads the driver library directly, skipping the command line entirely. Its compatibility promise is precise: every metric the default backend serves stays identical in name, labels and value, so existing dashboards and alerts keep working.
What it adds is the part the command line cannot reach. Per-instance metrics for partitioned GPUs, error counters, a total energy counter, and throughput over the interconnect. The project's own dashboards carry panels for all of these, and the pages state that those panels sit empty on the default backend and fill up on the native one.
The packaging follows that split. A separate release flavour already defaults to the native backend, published as archives with a suffix, and a container image tag with the same suffix does the same for Docker users. So choosing the backend is a tag choice rather than a configuration flag, which is simple but also means the two builds drift apart as separate artifacts.
The label attached to it is experimental, and the stated reason is test coverage rather than design: it needs more testing across driver versions and GPU generations. The page asks testers to open an issue either way, which is an honest way to ask for the evidence that would remove the label.
Demo mode serves synthetic metrics including the experimental families
There is a backend that needs no GPU, no driver, and not even Linux. It serves realistic synthetic metrics, and unusually it includes the families that only the native backend can produce in reality.
By default it simulates two datacenter-class GPUs with fluctuating values, a partitioned topology, and an error history. The simulated setup is configurable through the configuration document, so you can build a scenario rather than a default.
This is a testing and development feature with a real use: the per-instance panels, the error counters and the energy panel can all be exercised, and dashboards can be built, before anyone has the hardware to populate them. For anyone writing alerts, being able to see what a populated panel looks like without a GPU in the room is more useful than it sounds.
It also makes the project demoable, which is how a lot of its adoption happens, since the quick start tells you to try this first if you do not have a GPU to hand.
The container runs as a numeric user on purpose
The image comments are the most instructive part of the build file, because each one explains a choice that looks arbitrary.
The base is a distroless Debian image without the SSL bundle, chosen because the container runtime injects the command line binary from the host, and that binary needs a C library and its loader inside the container. A scratch or fully static base therefore cannot work. The base is pinned by digest rather than by tag.
The second comment is about the user. The exporter runs as a numeric user and group rather than a named one, and the reason is specific: the kubelet cannot verify a non-root requirement against a named image user and refuses to start the container. Using a named user here would break every pod that asks to run as non-root.
That is a real operational lesson encoded as a comment, and it explains a choice that would otherwise look like a style preference. The port is exposed and the binary is the entry point, and nothing else is copied in. The quick start shows the shape of a container deployment:
docker run -d --name nvidia_gpu_exporter --restart unless-stopped \
  --gpus all -e NVIDIA_DRIVER_CAPABILITIES=utility -p 9835:9835 \
  utkuozdemir/nvidia_gpu_exporter:latest
curl http://localhost:9835/metrics
Note the capability restricted to utility rather than all capabilities, which is what the container needs in order to see the injected binary, and the host port published for a scrape endpoint.
Releases are signed and the manifest is newer than the toolchain floor
Release artifacts carry a checksum file, and the verification section points at keyless signing, so a download can be checked against the project's own release pipeline rather than against a checksum someone published next to it. The distinction matters in supply chain terms, and it is documented rather than assumed.
The build configuration shows a multi-architecture release process with separate Dockerfiles for the default and native backends, and the dependency list pins the vendor's own language bindings alongside the Prometheus client libraries, a command line parser, a systemd integration library, and a shell quoting helper used for the command invocation path.
Two things stand out. The Go version floor in the module file is a recent patch release, which is aggressive for a tool meant to be widely deployed on heterogeneous machines. And the require block lists the Prometheus client libraries as direct dependencies even though the exporter also embeds a server toolkit, which is normal for exporters and worth noting because it means the binary links a web server.
Version numbering is plain and there are three releases in the recent past, with the two most recent published within an hour of each other.
The maintainer says up front that issues may go unanswered
The first warning on the page is not about the software. It says this is a side project maintained in spare time, that issues and pull requests might take a long time to be looked at or might not be looked at at all, and apologises in advance.
That is worth reading before you install rather than after an unanswered report, because for a monitoring component the failure mode is silent. If an exporter stops reporting, the symptom appears in a dashboard rather than in your face, and the usual first response is to check whether the metrics are still there. A project with an explicit single maintainer and a stated slow response is not a red flag so much as a fact to plan around.
The rest of the project's posture matches the warning. The dashboards are published as first class artifacts with numeric identifiers, install routes cover every major platform including package managers on Windows, and the Helm chart is registered on a public chart index, so adopting it does not require tracking the repository for the documentation.
The page also links an external best practices score and a security scorecard view, which suggests the project is comfortable being measured by outside tooling.
Metrics are discovered rather than hard coded
One line in the highlights list does more work than it appears to. The exporter auto-discovers the metric fields the command line utility is able to expose, and the parenthetical is that this makes it future compatible.
That is a design choice with consequences in both directions. On the positive side, a new card generation or driver release that adds a field to the utility's output can show up without a code change. On the negative side, the set of metrics on a given machine depends on what that utility happens to print, so two hosts of different generations will not necessarily expose the same families, and a dashboard written against one may show gaps on the other.
This is also why the native backend is described in terms of preserving metric identity rather than adding to a fixed set. If discovery drives what exists, then adding families has to be done without renaming or reshaping the existing ones, and the claim that names, labels and values are identical is doing exactly that work.
A reader deploying this should expect to compare the exposed families across their fleet before writing alerts, rather than assuming a uniform surface.
Editorial conclusion
This is the exporter to reach for when nvidia-smi is your only uniform source, which is exactly the consumer card, virtualized guest and homelab case it names. Its dependency surface is deliberately small, since the default backend shells out rather than linking the driver, which is why it runs on Windows and macOS from the same codebase. Two things to weigh. The native backend is labelled experimental for want of testing across driver versions and GPU generations, so treat its extra metric families as unproven even though the existing ones are unchanged. And the maintainer says outright that issues may go unanswered, which for a monitoring component is a real operational factor rather than a disclaimer.
Frequently asked questions
What is nvidia_gpu_exporter and how does it collect metrics?
It is a Prometheus exporter for NVIDIA GPUs that collects, parses and exports metrics from the nvidia-smi command line utility. An optional native backend skips that utility and reads the driver library directly, and a third backend serves synthetic metrics with no GPU present.
Does nvidia_gpu_exporter need Docker or Linux?
No. Because the default backend only needs the nvidia-smi binary, the page says it also works on Windows with no Docker or Linux required. Install routes cover Linux packages, Docker, Kubernetes via a Helm chart, Windows package managers and services, and macOS.
Should I use nvidia_gpu_exporter or the vendor's own exporter?
The page points you to the vendor exporter if you run datacenter cards on Kubernetes with the GPU Operator already installed, and positions this project for consumer cards, small clusters, virtualized guests and mixed fleets where the command line utility is the only uniform source.
What does the native NVML backend add?
Per-instance metrics for partitioned GPUs, XID error counters, a total energy counter and PCIe throughput, which the command line utility cannot provide. Metrics the default backend serves keep identical names, labels and values, and it ships as a separate release flavour and image tag.
How can I test nvidia_gpu_exporter without an NVIDIA GPU?
Run it with the demo backend, which serves realistic synthetic metrics including the families the native backend provides. It simulates two datacenter-class GPUs with a partitioned topology and an error history by default, and the simulated setup is configurable.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/utkuozdemir-nvidia-gpu-exporter)Star history chart for your README
[](https://hysenlabs.com/projects/utkuozdemir-nvidia-gpu-exporter)Was this useful?