llm-server-docs: the guide describes a server the repository does not contain
End-to-end documentation to set up your own local & fully private LLM server on Debian. Equipped with chat, web search, RAG, model management, MCP servers, image generation, and TTS.
At a glance
- What is it?
- llm-server-docs is a single document for building a self-hosted LLM stack on Debian across ten or eleven named components, from an inference engine through SearXNG, Open WebUI, Tailscale and Caddy. The repository holds a README, a docs folder, a media folder and a licence. The startup script, containers and network it tells you to create are not in it.
- Who is it for?
- llm-server-docs suits a beginner on Debian with a spare GPU box who wants an ordered shopping list and a set of decisions already made, and who is prepared to create every artifact themselves. It does not suit anyone expecting a runnable deployment, because the startup script, the Docker network and the container hardening described in its own table of contents are not in the repository.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 138 days ago.
- What is it written in?
- GitHub does not report a main language for this repository.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
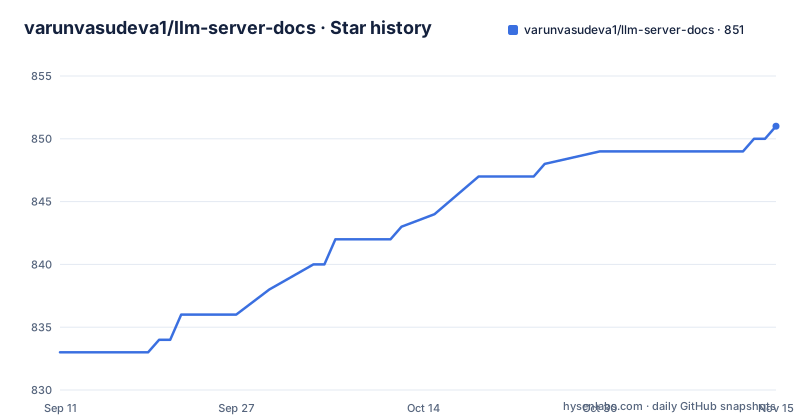
- varunvasudeva1/llm-server-docs851 ★ · +18
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| varunvasudeva1/llm-server-docs | 833 | 851 |
18 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The repository is a document, not the server it describes
The root of this repository holds four things: a licence, a README, a docs directory and a media directory. The primary language is recorded as unknown, which is consistent with that. There is no Dockerfile, no compose file, no script directory, no environment template and no configuration sample anywhere in the top-level listing. That matters because the document's own table of contents promises instructions to allow sudo permissions, to schedule a startup script, to create a network, to harden Docker containers, to install the Nvidia container toolkit, and to configure auto-login. Every one of those steps asks the reader to produce something. The result is a specification you execute rather than a project you run, which is a legitimate thing to publish and is a different thing from a deployment bundle.
The same integration section appears four times over
The table of contents runs to more than sixty entries and repeats itself in a structural way. There are four separate sections called Open WebUI Integration, one after the model server, one after the MCP proxy, one after the text-to-speech server and one after the image generation server, and the anchor names disambiguate them with a numeric suffix. General appears twice, SearXNG twice, Docker twice, Ollama three times, vLLM three times, and the ssh and Nvidia Drivers entries each twice. The repetition follows a rule rather than being an oversight: every component gets its own integration chapter. The cost is a document in which a reader looking for how the chat platform talks to the search engine has to know which of four similarly named sections to open.
Auto-login and a boot script, for a machine that runs all day
The opening description of the process names four things before any software is installed: installing the requisite drivers, setting the GPU power limit, setting up auto-login, and scheduling a script called `init.bash` to run at boot. The rationale is stated plainly, that these settings are based on the author's ideal setup for a language model server that runs most of the day. So the intended deployment is a headless Debian box that boots itself, logs a user in without a prompt, and starts the stack from a scheduled script. The startup script itself is a file the reader has to write, since it is not among the repository's four root entries. The same pattern holds for the SSH configuration, the firewall rules and the remote access section that come later.
Aesthetics is listed as a priority next to security and stability
The section defining what the guide optimises for is unusual in including a non-technical criterion. It names seven: simplicity, stability, security, maintainability, aesthetics, modularity and open source. Each has a sentence. Security is about limiting a component's capability to damage the system in case of a known vulnerability. Open source is about a community being able to verify the code, on the grounds that chat platforms and language models carry large amounts of personal data in natural language. Aesthetics gets its own justification: the result should be as close to a cloud provider's chat platform as possible, because a homelab solution does not necessarily need to feel cobbled together. That is a design constraint, not decoration, and it explains some of the component choices.
Private describes the data path, not an offline or unreachable box
The summary calls the result a local and fully private LLM server, and the open-source priority explains what private is meant to cover: the point is knowing that chat data is not going outside your machine. The stack itself is not private in the sense of being sealed. It includes SearXNG as a search engine, so the assistant can reach the web on request, and it includes Tailscale for a VPN, Caddy as a reverse proxy and Cloudflare as a DNS provider, so the box is designed to be reached from outside the local network. A reader who takes fully private to mean the machine never talks to the internet, or that the service is not reachable from a phone, will misread the architecture. What the guide optimises is where the conversation data lives and who can verify the code handling it.
Two RTX 3090s, and 24GB that could be either figure
The prerequisites give a reference system so a reader can gauge scale. It is an Intel Core i5-12600KF, 96GB of 3200MHz DDR4, a 1TB M.2 NVMe drive, and two Nvidia RTX 3090s annotated 24GB. The ambiguity is in that last figure. Written as 2x Nvidia RTX 3090 (24GB), it reads equally as 24GB per card, which is the card's own configuration, or 24GB in total, which would be impossible across two of them. Anyone using the line to estimate how much model will fit has to resolve it themselves. The rest of the specification is unambiguous, and the 96GB of system memory is the figure that actually constrains a large model split across CPU and GPU.
The AMD note skips power limiting and ends mid-sentence
GPU support is handled in two passes. The prerequisites say that AMD compatibility used to be a problem, that the recent Ollama releases have worked through it, and that AMD GPUs are now supported natively. A separate note then carves out a step: power limiting is skipped for AMD GPUs, with the justification beginning that AMD has recently made it difficult to set pow. That sentence is where the visible text ends, so the reason is given as a fragment and the reader is left to infer whether the limitation is technical, or a matter of a recently restricted interface. The consequence is clear enough: the GPU power-limit step in the main sequence applies to Nvidia cards, and a reader on AMD follows the same guide minus that step.
The author says no part of it was written using AI
The About section carries a callout about how the document was produced, and the claim is specific. No part of the guide was written using AI, the note says, and the phrasing adds that any hallucinations are the good old human kind. AI is credited with formatting Markdown elements and with vetting for technical inaccuracies. The callout then turns into a verification instruction: check everything you execute in a terminal. That is a reasonable position for a document that asks readers to run privileged commands, add their user to the Docker group, install a container toolkit and enable automatic login. It also means the document is asking to be audited rather than trusted, which is the correct expectation for a beginner-oriented homelab guide of this size.
Editorial conclusion
llm-server-docs suits a beginner on Debian with a spare GPU box who wants an ordered shopping list and a set of decisions already made, and who is prepared to create every artifact themselves. It does not suit anyone expecting a runnable deployment, because the startup script, the Docker network and the container hardening described in its own table of contents are not in the repository. Check three things before following it. Check which inference engine you are installing, since three are offered and they are not interchangeable. Check that your GPU is covered by the power-limit step, because the document skips that step for AMD and says the reason only in a note. And check what you are trusting, because the guide tells you to verify every command rather than to rely on it.
Frequently asked questions
Does llm-server-docs include the server code or a deployment?
No. The repository root holds a licence, the README, a docs directory and a media directory, with no Dockerfile, compose file, script directory or configuration sample. The steps ask the reader to create the startup script, the Docker network and the container hardening themselves.
Which components does the llm-server-docs stack use?
An inference engine from Ollama, llama.cpp or vLLM; SearXNG for search; llama-swap and a systemd service for the model server; Open WebUI as the chat platform; mcp-proxy or MCPJungle for MCP; Kokoro FastAPI for text to speech; ComfyUI for images; Tailscale, Caddy and Cloudflare for remote access.
Does the llm-server-docs guide work with AMD GPUs?
The prerequisites say AMD GPUs are now supported natively by recent Ollama releases, and a separate note says power limiting is skipped for AMD cards. The visible text gives that skip as a fragment and does not complete the reason.
What hardware is the llm-server-docs guide written against?
An Intel Core i5-12600KF, 96GB of 3200MHz DDR4, a 1TB M.2 NVMe drive, and two Nvidia RTX 3090s annotated 24GB. Whether that 24GB figure is per card or in total is not stated.
What operating system does llm-server-docs target?
Debian specifically, with the About section saying most other Linux distributions should follow a very similar process. The guide is written for a server that runs most of the day, using auto-login and a boot-scheduled script called init.bash.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/varunvasudeva1-llm-server-docs)Star history chart for your README
[](https://hysenlabs.com/projects/varunvasudeva1-llm-server-docs)Was this useful?