vcaesar/riot is an embeddable Go text index forked from Bluge, with vector search and a separate gse layer for CJK
Go Open Source, Distributed, Simple and efficient Search Engine
At a glance
- What is it?
- Riot is an Apache-2.0 Go library for full-text and vector indexing, forked from Bluge. It runs inside your process, and the distributed engine its description mentions lives in a different repository.
- Who is it for?
- Riot fits Go developers who want an embedded index with BM25 scoring, aggregations and HNSW vector search inside their own binary. It is the wrong pick if you expect a network search server out of the box, since the distributed engine is the separate zed project.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
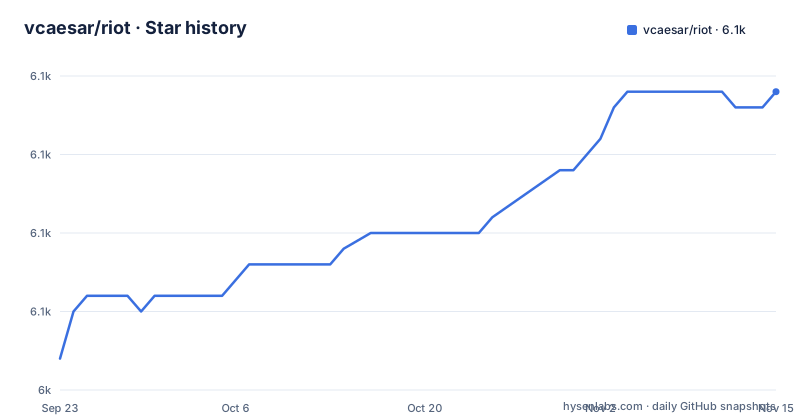
Star history
- vcaesar/riot6,064 ★ · +17
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| vcaesar/riot | 6k | 6.1k |
17 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Riot is a library you import, and the distributed engine is zed
The repository description calls riot a distributed, simple and efficient search engine, but the README opens differently: it is a fast, modern text indexing library in Go, forked from Bluge. For a distributed search engine and a lightweight alternative to full Elasticsearch built on riot, the README sends you to a separate project named zed.
That changes what you get from the install. You add the module to a Go program:
go get -u github.com/vcaesar/riotYou then open a writer and a reader against a directory such as ./riot_index, and your program owns the index. Nothing here starts a server or a cluster. If you need an HTTP endpoint or sharding, you either write that layer yourself or look at zed. The module path is github.com/vcaesar/riot, and the package is imported with the alias riot.
Reading an index you are still writing needs writer.Reader()
The indexing example builds a config with riot.DefaultConfig, opens it with riot.OpenWriter, creates a document with riot.NewDocument and a text field, and stores it with writer.Update. The query example opens the same directory with riot.OpenReader, builds a riot.NewMatchQuery on the name field, wraps it in riot.NewTopNSearch with a limit of 10 and standard aggregations, and iterates the matches. The expected output for the demo is a single line, match: example.
The trap is process layout. Those two programs are run separately, with go run ./write and then go run ./read. If you index and search in the same process, the README says to use writer.Reader() instead of riot.OpenReader. For an index that never touches disk, riot.InMemoryOnlyConfig gives an in-memory index. Opening a second reader on a directory your own process is still writing is the mistake this guidance exists to prevent.
Chinese and Japanese go through the gse package, not the core tokenizer
The gse package wraps riot with the gse tokenizer for CJK text, and it adds query-string search and highlighting. Its options are small. Index names the index, here test.riot. Dicts selects dictionaries, with embed, ja for Japanese or embed, zh for Chinese. Opt is set to search-hmm in the example. Setting Lang to en skips gse entirely and uses a riot analysis analyzer instead, with other values such as cjk and de, and gse.Langs() lists them.
The example output shows highlighting at token level. The Japanese query for fate's victim matched two documents in 14.5 microseconds, with each token wrapped in its own mark tags. The timings are labelled as varying, so do not read them as a benchmark. A struct-indexing demo shows an Article type with Title and Text fields indexed under an ID, and the empty-index comment says it uses memory only. The consequence: CJK search needs the extra import and a dictionary choice, and picking the wrong Dicts value for your text changes the tokens you match.
Vector search offers exact KNN and approximate ANN, with a disk or heap choice
Vector is one of the supported field types, and the query list includes ANN and KNN. The approximate search is HNSW with int8 quantization. Graphs persist with segments, so a reopened index searches them without a rebuild, and they are memory-mapped from disk. The runnable demo is examples/knn, started with go run ./examples/knn, and it indexes three two-dimensional vectors named east, northeast and north. Both KNN and ANN return east at 1.000 and northeast at 0.707.
WithVectorStorage decides where vectors live. riot.VectorStorageDisk is the default and memory-maps each graph together with its vectors, so they sit in the OS page cache and not on the Go heap. riot.VectorStorageMemory stores links only and loads vectors onto the heap when a graph opens, which gives smaller files and costs more memory. The choice is a direct trade between file size and heap pressure, and a service with many large graphs feels it first.
Aggregations include estimates, not exact counts
Beyond term, phrase, match, prefix, regexp, wildcard and fuzzy queries, riot supports conjunction, disjunction and boolean combinations, plus numeric, date, term and IP ranges and geo bounding box, distance and polygon queries. Scoring is BM25 with pluggable interfaces, and results can carry match highlighting. Other field types are text, numeric, date, boolean, IP and geo point.
Aggregations are extensible. Bucketing covers terms, numeric range and date range. Metrics cover min, max, count and sum, average and weighted average, cardinality estimation with HyperLogLog++ and quantile approximation with T-Digest. The last two are approximations by name. If a dashboard needs an exact distinct count or an exact percentile, those metrics will not give it to you, and you should compute the figure another way. Both algorithms come from third-party modules, github.com/axiomhq/hyperloglog and github.com/caio/go-tdigest, which appear in go.mod.
The module requires Go 1.26.0 and swaps in a forked vellum
The go.mod file declares go 1.26.0, so older toolchains cannot build the module. Direct requirements include roaring bitmaps, hyperloglog, bitset, vellum, go-tdigest, gse v1.3.1, cobra, bluge_segment_api, ice and several zedsearch packages for the Porter stemmer, mmap, segment handling and Snowball stemming. A replace directive points github.com/blevesearch/vellum at github.com/zedsearch/vellum, pinned to a pseudo-version dated 2026-11-03.
The consequence is a dependency tree tied to the same author's forks, so a vulnerability or fix in vellum reaches you only when those forks are updated. If your organization audits upstream modules, expect to review the zedsearch and vcaesar packages as first-class dependencies. The repository also contains a cmd directory and a cobra dependency, which suggests command-line tooling, but the library API is what the README documents.
Three releases landed in three days at the end of October
The repository is not archived. The last push was on 2026-11-01. Recent tags are v1.61.2 on 2026-10-30, v1.61.3 on 2026-10-31 and v1.62.0 on 2026-11-01. That is a rapid sequence of patch and minor releases.
For a user, the version number moves fast, so pin the module version in go.mod and read the diff between tags before upgrading, especially since vector storage and persistence behavior are among the newer features listed. The license is Apache-2.0. Translations of the README exist in Simplified and Traditional Chinese, Japanese, Korean, French, German, Spanish, Russian and Portuguese. Build and lint status badges point to GitHub Actions workflows on the main branch, and a Discord invite is linked for questions.
Editorial conclusion
Riot fits Go developers who want an embedded index with BM25 scoring, aggregations and HNSW vector search inside their own binary. It is the wrong pick if you expect a network search server out of the box, since the distributed engine is the separate zed project. Check that your toolchain meets the go 1.26.0 line in go.mod before adding it.
Frequently asked questions
Is vcaesar/riot a search server or a library?
It is a Go text indexing library forked from Bluge. A distributed search engine built on riot is the separate zed project.
How do I install riot in a Go project?
Run go get -u github.com/vcaesar/riot. The go.mod file declares go 1.26.0, so your toolchain must meet that.
Does riot support vector search?
Yes. It has a Vector field type with exact KNN and approximate ANN queries. ANN uses HNSW with int8 quantization, and graphs persist with segments on disk.
How does riot handle Chinese and Japanese text?
Through the gse package, which wraps riot with the gse tokenizer. Dicts values such as embed, ja or embed, zh select the dictionaries.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/vcaesar-riot)Star history chart for your README
[](https://hysenlabs.com/projects/vcaesar-riot)Was this useful?