Zipkin: a 155k core jar, a JRE 17 server, and a dependency graph built by a separate job
Zipkin is a distributed tracing system
At a glance
- What is it?
- Zipkin collects and serves distributed trace data over HTTP, Kafka and other transports, and stores it in memory, Cassandra or Elasticsearch. The server wants JRE 17 while the core library still targets Java 8, and both real backends need an external job before the dependency diagram in the UI has anything to draw.
- Who is it for?
- Zipkin fits a fleet whose services already emit spans over HTTP or Kafka and where you want to search them by service, operation, tags or duration. It does not fit a team expecting the server to work out the service graph on its own, because Cassandra and Elasticsearch both need the zipkin-dependencies job to run first.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 100 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
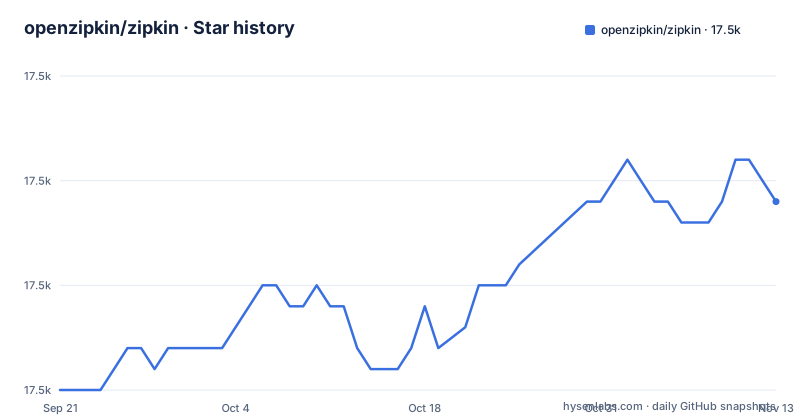
- openzipkin/zipkin17,474 ★ · +9
| Repository | 2026-09-21 | 2026-11-13 |
|---|---|---|
| openzipkin/zipkin | 17.5k | 17.5k |
9 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A trace ID in a log line gets you into the UI in one jump
The fastest path through Zipkin is not a search. If you have a trace ID sitting in a log file, you can jump straight to that trace. Everything else is a query built from attributes, and the set of attributes is the query surface: service, operation name, tags and duration. The UI also does the arithmetic for you, summarizing how much of the time was spent inside a service and whether operations failed, so a service that looks busy in a latency complaint can be split into its failing and its slow parts without exporting anything. The practical consequence is about coverage. The design assumes your instrumentation library is putting the right values in those four places, and the library is a separate project from this one.
The dependency diagram counts traced requests, and only traced ones
Beyond the trace list, the UI draws a dependency diagram showing how many traced requests went through each application. The stated purpose is aggregate behavior: error paths, and calls into services that have been deprecated but are still being invoked by something. That second use is the one worth knowing, because a deprecated service rarely appears in a code search of the service that calls it, while it shows up plainly as a node with traffic on it. The catch is in the counting. The diagram is built from the spans that arrived, so an application nobody instrumented is not a blank box, it is absent. A diagram that looks clean may mean the graph is incomplete rather than that the architecture is clean, and the only way to tell those apart is to know your instrumentation coverage before you trust the picture. Storage has to hold the link data for this to work at all, which is where the aggregation jobs come in later.
Instrumentation is yours; the server only receives what you send
Applications need to be instrumented to report trace data to Zipkin, and the README puts this plainly: what that usually means is configuring a tracer or an instrumentation library, and if your applications are not sending traces yet, that configuration is the missing step. The popular reporting paths are http and Kafka, with Apache ActiveMQ, gRPC, RabbitMQ and Apache Pulsar named as further options. Transport is therefore your first design decision rather than a server setting, and it decides which build you can run: the slim build, described later, drops the messaging transports. The README also notes that the example in the core library section is just an example, and that most people will use an existing tracing library such as Brave instead of assembling spans by hand. Zipkin is the collector, the storage and the query UI; it is not the instrumentation, and it cannot report on a service that never speaks to it.
The 155k core jar repackages gson so it cannot collide with yours
The core library under zipkin/src/main/java/zipkin2 is the piece both the server and third-party instrumentation depend on, and it carries built-in codecs for Zipkin's v1 and v2 json formats. Instead of taking a direct dependency on gson, it minifies and repackages the classes it uses, which produces a 155k jar that will not conflict with whatever json library you already ship. Building a span looks like this:
// All data are recorded against the same endpoint, associated with your service graph
localEndpoint = Endpoint.newBuilder().serviceName("tweetie").ip("192.168.0.1").build()
span = Span.newBuilder()
    .traceId("d3d200866a77cc59")
    .id("d3d200866a77cc59")
    .name("targz")
    .localEndpoint(localEndpoint)
    .timestamp(epochMicros())
    .duration(durationInMicros)
    .putTag("compression.level", "9");
The java version rules here are deliberately lower than the server's. The core library's minimum language level is Java 8, which exists to support people writing agent instrumentation, and version 2.x was the last to support Java 6. zipkin-reporter-brave does not use this library at all, so Brave itself still supports Java 6. So a legacy JVM can still ship spans, while anything touching storage needs Java 17 or newer.
Zipkin Slim drops Kafka and RabbitMQ, so the build choice is a transport choice
Two distributions ship, and the difference between them is not size. The slim build is smaller and starts faster, and it supports in-memory and Elasticsearch storage but no messaging transports like Kafka or RabbitMQ. Getting it through the quickstart script means naming the slim artifact explicitly:
curl -sSL https://zipkin.io/quickstart.sh | bash -s io.zipkin:zipkin-server:LATEST:slim zipkin.jarand through Docker the image name changes too:
# Note: this is mirrored as ghcr.io/openzipkin/zipkin-slim
docker run -d -p 9411:9411 openzipkin/zipkin-slim
There is a third route, a Homebrew formula, with brew install zipkin to put the binary in place, zipkin to run it in the foreground and brew services start zipkin to run it in the background. Pick the build after you have picked the transport. A team reporting over Kafka who reaches for the slim image because it starts faster gets a server that will not be listening on the queue, and the symptom is a healthy process with no spans in it.
In-memory storage is a laptop setting that holds spans in the heap
InMemoryStorage ships inside Zipkin's core library, and the README is unusually clear about its status: it is neither persistent nor viable for realistic work loads, and its purpose is testing, for example starting a server on your laptop without any database needed. That is the default experience for anyone who runs java -jar zipkin.jar or the Docker image and stops there, so it is worth knowing what the default is. Traces live in the process heap, which means a restart loses them, a second instance sees a different set, and memory pressure is handled by whatever the JVM does with the heap. It also means the fastest way to try Zipkin is the way that quietly discards everything you collected. For a real deployment the choice is Cassandra or Elasticsearch, and both of those bring their own requirement, described next. Nothing in the core library pushes you toward a persistent store, and the storage components keep their dependencies minimal because the same code is used by the server and by those making collectors or span reporters.
Both real backends need a separate job before the graph has data
The dependency diagram depends on dependency links, and neither storage backend computes them during ingestion. The Cassandra component uses Cassandra 3.11.3+ features and is tested against the latest patch of Cassandra 4.1; it is the second generation of the schema, stores spans in UDTs so they read like Zipkin v2 json in cqlsh, and combines SASI with manually implemented indexes for query performance. It also requires a job to aggregate dependency links. The Elasticsearch component uses Elasticsearch 5+ features, is tested against Elasticsearch 7-8.x and OpenSearch 2.x, stores spans as Zipkin v2 json so other tools can read them, and again uses custom and manually implemented indexing. It requires a spark job to aggregate dependency links. Both point at the same zipkin-dependencies project. The consequence is operational: install Zipkin, ship spans, and the trace list works, while the diagram stays empty until you also deploy the aggregation job.
The search endpoints can be turned off, and the trace list goes with them
Zipkin exposes a set of search endpoints, they are enabled by default, and search is what makes the trace list screen of the UI operate. Two of the listed endpoints are GET /services, which returns the distinct Span.localServiceName values, and GET /remoteServices?serviceName=X, which returns the distinct Span.remoteServiceName values for a given local service. That distinction is the useful part: the first tells you what is reporting at all, the second tells you what a given service is calling. Turning them off has a direct cost, since the list screen depends on them. Configuration detail lives in the zipkin-server documentation rather than the top-level file, with docker/examples covering the compose setup.
Editorial conclusion
Zipkin fits a fleet whose services already emit spans over HTTP or Kafka and where you want to search them by service, operation, tags or duration. It does not fit a team expecting the server to work out the service graph on its own, because Cassandra and Elasticsearch both need the zipkin-dependencies job to run first. Check three things before you deploy: the transport, since Zipkin Slim carries no Kafka or RabbitMQ and will not collect spans sent over those transports; the storage backend, since in-memory keeps nothing across a restart; and the Java version on the reporting side, where the server wants JRE 17 while the 155k core jar still loads on Java 8.
Frequently asked questions
What is Zipkin used for?
Zipkin gathers the timing data needed to troubleshoot latency problems in service architectures, and both collects that data and lets you look it up. You can jump to a trace by ID or query by service, operation name, tags and duration.
Is Zipkin still used?
The repository has tagged releases, with 3.6.1 published on 2026-04-08 and 3.6.0 on 2026-03-23, and the last recorded push was on 2026-08-06. The repository is not archived.
What are the key differences between Zipkin and Jaeger?
Zipkin stores spans as Zipkin v2 json and keeps dependency links separately, and on both Cassandra and Elasticsearch those links are filled in by an aggregation job rather than during ingestion.
how to install zipkin
Fetch the latest released server as a self-contained executable jar, which needs a minimum of JRE 17, or run the openzipkin/zipkin Docker image. Once it is up, the UI is at http://localhost:9411/zipkin.
how to install zipkin in windows
The documented routes are the quickstart shell script with java -jar zipkin.jar, which needs JRE 17 or newer, the openzipkin/zipkin Docker image and a Homebrew formula.
what is zipkin server
zipkin-server is the module that collects spans and serves the UI, and its documentation is where configuration details live. It needs JRE 17 or newer, stores data in memory, Cassandra or Elasticsearch, and exposes the UI at http://localhost:9411/zipkin.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openzipkin-zipkin)Star history chart for your README
[](https://hysenlabs.com/projects/openzipkin-zipkin)Was this useful?