whisper_android: two sample apps over an upstream Whisper TFLite port
Offline Speech Recognition with OpenAI Whisper and TensorFlow Lite for Android
At a glance
- What is it?
- whisper_android packages a TFLite port of Whisper into two Android apps, one on the Java API and one on the native API, with pre-generated models, a conversion script and pre-built APKs. The integration surface is four Java snippets and one audio format constraint.
- Who is it for?
- whisper_android fits a developer who wants offline transcription in an Android app this week and is comfortable reading four snippets and wiring permissions, paths and error handling by hand. It does not fit a team that wants a maintained library with versioned releases, because there are no tags, the last push is dated 2026-03-18, and the model conversion step is a script you run yourself.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 8 months ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
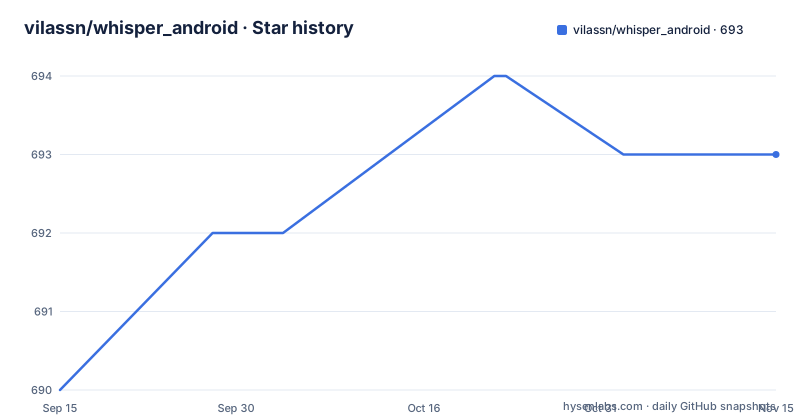
- vilassn/whisper_android693 ★ · +3
| Repository | 2026-09-15 | 2026-11-15 |
|---|---|---|
| vilassn/whisper_android | 690 | 693 |
3 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two apps, one upstream port doing the real work
The repository is an Android packaging of somebody else's work, and the acknowledgement section says so plainly. It uses Niranjan Yadla's 2022 project, Whisper TFLite: OpenAI Whisper Model Port for Edge Devices, with a link to the `nyadla-sys/whisper.tflite` repository and a BibTeX entry describing it as the original TFLite implementation of OpenAI Whisper for on-device recognition.
What this repository adds is the Android side. `whisper_java` is an app built on the TensorFlow Lite Java API, aimed at Java developers who want easy integration. `whisper_native` uses the TensorFlow Lite native API and is aimed at people who want the performance. `models_and_scripts` holds a Python script, `generate_model.py`, that converts Whisper models into TensorFlow Lite format, plus a `generated_model` directory of already optimised models. `demo_and_apk` holds pre-built APKs for direct installation.
So the model work is upstream, the model conversion is here, and the Android wiring is the actual contribution.
The two apps differ in the binding, not the API
The stated difference between the two apps is the inference layer: the Java API for easy Java integration, the native API for enhanced performance and optimised execution. Everything the README teaches is identical on both sides, because the classes the guide uses, `Whisper` and `Recorder`, do not change shape.
That is the useful thing to notice. Choosing between the two apps is a performance decision, not an API decision, so a port between them does not mean rewriting your integration code.
To run either one, you open the folder in Android Studio and build to a device or emulator. There is no Gradle coordinate to add, no version to pin, and no release channel, so the sample apps are a starting point you copy rather than a dependency you require.
Audio has to arrive as 16 kHz mono 16-bit
The one hard constraint in the guide appears in both snippets as a comment. Transcription needs audio in 16K, mono, 16 bits, and the recorder records in the same format. Both classes take the path rather than the bytes:
String waveFilePath = "path/to/your_audio_file.wav"; // Provide audio file path
mWhisper.setFilePath(waveFilePath); // Set audio file path

// Start transcription
mWhisper.setAction(Whisper.ACTION_TRANSCRIBE); // Set action to transcription
mWhisper.start(); // Start transcription
The shape is a small state machine of its own: set a file, set an action, start, stop. Nothing is streamed from the microphone into the model in this path, which is why the live case needs the extra step below.
If your audio arrives from an encoder, a call or a file the user picked, resampling and downmixing happen before this point or not at all. The snippets do not do it for you, and the closing note asks you to handle file path management and exceptions yourself.
Loading a model takes two files and a boolean
Initialisation is where the integration surface is widest. The Whisper class is constructed with an Activity, then given a model file, a vocabulary file and a flag:
String modelPath = "path/to/whisper-tiny.tflite"; // Provide model file path
String vocabPath = "path/to/filters_vocab_multilingual.bin"; // Provide vocabulary file path
mWhisper.loadModel(modelPath, vocabPath, true); // Load model and set multilingual mode
Two consequences follow from that signature. The vocabulary is a separate binary, so a model file on its own is not a working setup. And the third argument is multilingual mode, which means the same call can be made monolingual, and the README does not say which model variant pairs with which flag.
Status arrives through a listener, an `IWhisperListener` with an `onUpdateReceived(String)` callback, so transcription progress is reported rather than returned. That is the pattern to design your UI around: a start, a progress channel, and a stop.
Live recognition is a commented-out line
The Recorder class is where the interesting case lives. It records to a file in the same 16 kHz mono 16-bit format, and its listener has two callbacks: `onUpdateReceived(String)` for status and `onDataReceived(float[] samples)` for the audio itself.
The README then shows what you can do with those samples and leaves it commented out:
public void onDataReceived(float[] samples) {
    // Handle audio data received during recording
    // You can forward this data to Whisper for live recognition using writeBuffer()
    // mWhisper.writeBuffer(samples);
}
`writeBuffer()` is the difference between transcribing a finished file and transcribing as someone speaks. The sample keeps it disabled, and the two videos linked from the README, one demo and one labelled live transcription, are the evidence that the enabled path works.
Permission handling is the other prerequisite in that snippet: `checkRecordPermission()` is called before recording starts, and the README asks you to make sure the necessary permissions are in place.
Pre-built APKs and a privacy policy sit next to the models
Three things in the repository tree explain how this is meant to be consumed. `demo_and_apk/` holds APKs you can install directly, which is the fastest way to see whether offline recognition on device is worth integrating. `models_and_scripts/` holds the converter and the outputs of running it, so you can inspect what a converted model looks like before generating your own. And `privacy_policy.md` sits at the root, next to those APKs, which is a store requirement rather than a library convention.
The licensing is the permissive kind, MIT in `LICENSE.txt`, and the model work it depends on is credited rather than vendored, which keeps the licence question simple.
The support section is a personal one: a PayPal link for contributions and a direct email address for questions, which reads like a single maintainer rather than a team.
The integration is four snippets and a set of caveats
The guide closes with instructions rather than a reference. Adapt the snippets to your use case, provide the correct file paths, handle exceptions appropriately, and make sure permissions, error handling and file path management are in place. A separate note adds that handling audio data and transcriptions may need careful synchronisation and error handling for a smooth experience.
That is the honest shape of the project. There is no API documentation, no changelog, no test suite and no release series, just four annotated Java snippets covering initialisation, transcription, recording and the live buffer path, plus two videos.
The last push is dated 2026-03-18 and there are no GitHub releases, so the repository is a maintained sample rather than a versioned dependency. For anything long-lived, the practical route is to copy the integration, pin the upstream TFLite port you trust, and own the maintenance.
Editorial conclusion
whisper_android fits a developer who wants offline transcription in an Android app this week and is comfortable reading four snippets and wiring permissions, paths and error handling by hand. It does not fit a team that wants a maintained library with versioned releases, because there are no tags, the last push is dated 2026-03-18, and the model conversion step is a script you run yourself. Before you adopt it, find out which upstream port the code tracks, check that the pre-generated model matches your language pair, and plan for the 16 kHz mono 16-bit requirement to reach every caller in your app.
Frequently asked questions
What does whisper_android contain?
Two Android apps, whisper_java on the TensorFlow Lite Java API and whisper_native on the native API, plus models_and_scripts with the generate_model.py conversion script and pre-generated TFLite models, and demo_and_apk with pre-built APKs.
What audio format does whisper_android expect?
16 kHz, mono, 16-bit. Both the Whisper and the Recorder snippets state it, and each takes the path through setFilePath before transcription or recording starts.
Which Whisper implementation does whisper_android build on?
It acknowledges Niranjan Yadla's 2022 work, Whisper TFLite: OpenAI Whisper Model Port for Edge Devices, as the open-source implementation it uses, with the nyadla-sys/whisper.tflite repository linked and cited.
How do I load a model in whisper_android?
Construct the Whisper class with an Activity and call loadModel with a whisper-tiny.tflite path, a filters_vocab_multilingual.bin path and true for multilingual mode. Then set a listener, give it a 16 kHz mono 16-bit file path, set the action to ACTION_TRANSCRIBE and call start and stop.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/vilassn-whisper-android)Star history chart for your README
[](https://hysenlabs.com/projects/vilassn-whisper-android)Was this useful?