GuideLLM resolves torch from the CPU index and its own comparison table omits its vLLM backend
Evaluate and Enhance Your LLM Deployments for Real-World Inference Needs
At a glance
- What is it?
- GuideLLM is an Apache-2.0 benchmarking platform from the vLLM project that generates workload patterns against OpenAI-compatible servers and reports full latency distributions. Its packaging metadata, its resolver configuration and its own comparison table do not quite agree with each other.
- Who is it for?
- GuideLLM suits a team that already runs a server and wants repeatable load patterns plus distributional latency data rather than a single average, and it suits it less well if the plan depends on GPU kernels out of the box or on the feature matrix in its comparison table. Before adopting it, check four things.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
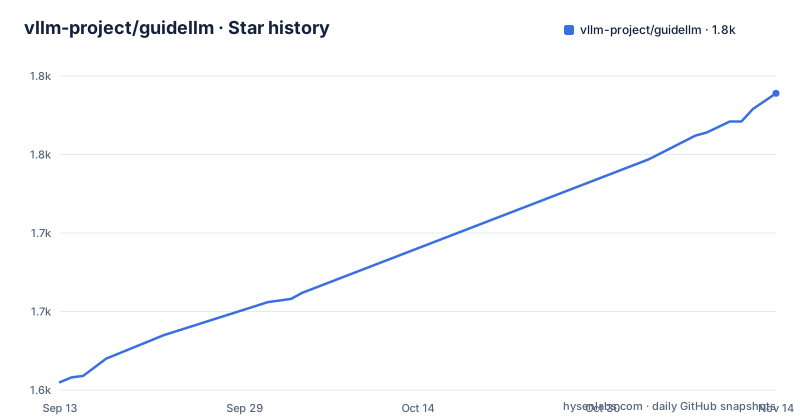
- vllm-project/guidellm1,789 ★ · +184
| Repository | 2026-09-13 | 2026-11-14 |
|---|---|---|
| vllm-project/guidellm | 1.6k | 1.8k |
184 Stars in the last 62 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three different one line descriptions ship in the same repository
The repository description, the page heading and the packaging metadata each describe something different. The repository description reads as a mandate to evaluate and enhance deployments for real world inference needs. The heading above the logo calls it an SLO-aware benchmarking and evaluation platform for optimizing real world LLM inference. The project metadata says something else entirely:
description = "Guidance platform for deploying and managing large language models."That line is what package index pages, wheels and metadata readers show. The keyword list attached to it carries guidance alongside benchmarking, model-evaluation and inference. An author field names Red Hat as the sole author of the distribution.
None of the three mentions the other. A reader arriving from a package index sees a guidance platform, a reader arriving from the repository sees an evaluation platform, and the repository description promises enhancement rather than measurement. The name itself compounds this: GuideLLM can be read as a guide to an LLM, and the packaging description is the only one of the three that supports that reading.
torch and torchcodec are bound to a CPU wheel index
The resolver configuration names one extra index and marks it explicit:
[[tool.uv.index]]
name = "pytorch-cpu"
url = "https://download.pytorch.org/whl/cpu"
explicit = true
A separate sources block points torch and torchcodec at that index. The effect is that a default resolution produces CPU builds of both. On a machine with accelerators, that is not a rounding error: the benchmarking load generator and anything that touches tensors will run on the CPU path unless the index is overridden. The choice is deliberate, in the sense that it makes installs reproducible and small, but it is easy to miss because nothing in the runtime documentation repeats it.
The same block constrains where installs are expected to work at all:
[tool.uv]
required-environments = [
    "sys_platform == 'darwin' and platform_machine == 'arm64'",
    "sys_platform == 'linux' and platform_machine == 'x86_64'",
    "sys_platform == 'linux' and platform_machine == 'aarch64'",
]
Three environments are guaranteed. Windows is absent, and so is darwin on x86_64, so an Intel Mac is not a target environment even though the project requires only Python 3.10 or newer.
The comparison table drops the vLLM backend that the same page lists as new
The page compares itself against five other tools: inference-perf, genai-bench, llm-perf, ollama-benchmark and the benchmarks directory inside vLLM. The GuideLLM row is the only one marked as having both a CLI and an API, and the only one marked as having full metrics, and its output types are the widest set at console, json, csv and html.
The same row is where the page stops being accurate about itself. Its backends column reads OpenAI-compatible, and nothing else. A few sections later, the recent additions name an in-process vLLM Python API backend and a websocket audio transcription backend. Meanwhile the row for the vLLM benchmarks tool lists its backends as OpenAI-compatible and the vLLM API. So the table credits the vLLM API to a competitor while omitting it from the row describing the project that just added it.
Two more gaps in the same row: the data modalities column reads Text, Image, Audio, Video, with no entry for embeddings or re-ranking, both of which the genai-bench row lists; and the backends column has no hosted cloud entry, which the genai-bench and llm-perf rows do have. No column records a version or a date for any tool, so a reader cannot tell how old the other rows are.
Trace replay accepts Mooncake, WEKA and OTEL files as load sources
The load side is not limited to generated traffic. Replay of Mooncake, WEKA and OTEL trace files is listed as a recent addition for realistic load testing, which means a captured trace from one of those systems can stand in for a request pattern instead of a synthetic sweep. Two storage oriented names and one telemetry format in one feature line is an unusual combination, and it suggests the tool is aimed at teams who already have those traces lying around.
The rest of the additions move in the same direction, from a load generator towards an agent harness. Multi-turn conversation capabilities exist for benchmarking chat agents and dialogue systems. Full tool calling support is claimed on both sides, client and server, across the chat completions and responses APIs. Synthetic video and image datasets were added for controlled experiments, and support for benchmarking geospatial models is listed alongside them.
Two documentation gaps sit next to that list. The active development section shows one item with no text after it, and the page gives no version attached to any of the additions, so a reader cannot tell which are in the newest release and which are still being built.
Version numbers come from tags, with a hardcoded 0.8.0 fallback
The build keeps the version out of the project table and derives it from git tags through a setuptools plugin. Two constants govern the scheme:
LAST_RELEASE_VERSION = Version("0.8.0")
TAG_VERSION_PATTERN = re.compile(r"^v(\d+\.\d+\.\d+)$")
The pattern is anchored at both ends and admits nothing but three numeric components, so any tag carrying a suffix, a prefix or a fourth component is invisible to the scheme. When no tag matches, the hardcoded fallback becomes the version, which means the number a build reports can be a literal rather than a reading of the repository. A second function counts commits since the last tag, so a build can also report how far it sits from a release.
The build type decides the shape of the result. A release build takes the last version and adds a post segment when a build iteration is present, so the artifact version and the tag can differ. A candidate build increments to the next minor and appends an rc suffix. In the function's own description, the nightly and alpha cases are worded identically, both incrementing to the next minor and appending an a, so the documentation for those two cannot tell them apart. The page badges a nightly workflow, so at least one of those paths is in use.
The release names on the tags are inconsistent as well. The 0.7.3 and 0.7.4 releases carry names prefixed with the project name, while the 0.8.0 release is named with the bare tag. Since the versioning code only reads the tag itself, that naming drift is cosmetic, but it does mean a changelog assembled from release names will not be uniform.
Two container files, a .containerignore, and two test runners
The root holds Containerfile and Containerfile.vllm, which is the pair a benchmarking tool needs when the server under test is the one it shares a name with. The ignore file is named .containerignore rather than .dockerignore, following the more general convention that works for both build tools.
Testing is configured twice. A tox file sits beside a uv lock file, so a contributor has both an environment matrix runner and a pinned resolution available, and neither is presented as the preferred one in the visible documentation. A markdown formatting configuration and a pre-commit configuration sit at the root as well, along with a manifest for including non-Python files in a source distribution.
The repository also carries the full set of governance and agent files a hosted project accumulates: a code owners file, a code of conduct, a contributing guide, a developing guide, an AGENTS.md, a CLAUDE.md and dot directories for agent and assistant tooling. Documentation is built with mkdocs from a docs directory, which is what backs the published site. The pattern is consistent with a project run under a corporate umbrella rather than a single maintainer.
It measures a server endpoint, not model weights, and says so
The framing paragraph concedes the most important limitation in a plain sentence: many tools benchmark endpoints rather than models. The response to that is that GuideLLM focuses on LLM specific workloads, measuring time to first token, inter token latency, output distributions and dataset driven variation.
Everything in the architecture follows from that choice. The backends are OpenAI-compatible servers, the endpoints named are /completions, /chat/completions, /audio/translation and /audio/transcription, and the data sources are HuggingFace datasets, local files, synthetic sets or custom ones. So a run measures a deployment: the server, its scheduler, its batching and its queueing. Two servers running identical weights can produce different numbers, and that is the point rather than an artefact.
The metric vocabulary is distributional. The page promises full distributions rather than averages for time to first token, for inter token latency and for end to end behaviour, and calls the result suitable for SLO driven evaluation. Results are written as console output, json, csv or html, and the packaging configuration ships the scenario schemas and the html report templates as package data so that a report renders without a separate asset bundle.
Real workload and synthetic traffic are both first class inputs
The word realistic does real work in this project, and the inputs behind it come from two different places. Synthetic generation uses a data generator library alongside a text repair library for cleaning generated strings, so a synthetic run can produce text, image, audio and video inputs and a matching request pattern without a dataset. Real inputs come from HuggingFace datasets or from files the operator supplies.
The six named workload profiles are where those inputs meet a schedule: synchronous, concurrent, throughput, constant, poisson and sweep. Four of them describe how many requests are in flight or how they are spaced, and sweep is the one aimed at finding a boundary, described as reproducible sweeps to identify safe operating ranges. That combination is why the page claims reproducible runs rather than single measurements.
The remaining direct dependencies explain the transport and output side. The CLI is built on a pinned click release, the HTTP client is httpx with the HTTP/2 extra, and msgpack and protobuf sit alongside it for wire formats, with loguru for logging. The Python floor is 3.10, and a type expression backport package is listed, which is what allows newer typing syntax on that floor.
Editorial conclusion
GuideLLM suits a team that already runs a server and wants repeatable load patterns plus distributional latency data rather than a single average, and it suits it less well if the plan depends on GPU kernels out of the box or on the feature matrix in its comparison table. Before adopting it, check four things. Read the dependency resolution configuration, because torch and torchcodec are bound to a CPU wheel index, so a GPU host needs an explicit override. Read the comparison table as a claim rather than a specification, since its GuideLLM row omits the vLLM backend and websocket audio backend that the same page lists as recent additions. Confirm your platform appears in the three required environments, which are darwin on arm64, linux on x86_64 and linux on aarch64. And decide whether an html report is worth the package weight, since the report templates ship as package data alongside the scenario schemas.
Frequently asked questions
what is guidellm
GuideLLM is a platform for evaluating how language models behave under real workloads and configurations. It simulates end to end interactions with OpenAI-compatible and vLLM-native servers, generates configurable traffic patterns, and produces reports including full distributions for time to first token, inter token latency and end to end behaviour.
What are the alternatives to GuideLLM for benchmarking an LLM server?
The page's comparison table names inference-perf, genai-bench, llm-perf, ollama-benchmark and the benchmarks directory shipped inside vLLM. Across those rows GuideLLM is the only entry marked as having both a CLI and an API, and the only one marked as carrying full metrics.
Which LLM should be used, according to GuideLLM?
GuideLLM does not rank or recommend models. It generates load against a server you point it at, across six profiles from synchronous to sweep, and reports latency distributions so you can compare deployments yourself.
What metrics does GuideLLM report?
Full distributions rather than averages for time to first token, inter token latency and end to end behaviour, plus output distributions and dataset driven variation. Results can be written as console output, json, csv or html, and the report templates ship as package data.
Which servers and platforms does GuideLLM support?
The backends column names OpenAI-compatible servers with the endpoints /completions, /chat/completions, /audio/translation and /audio/transcription, and recent additions add an in-process vLLM Python API backend and websocket audio transcription. The resolver guarantees only three environments: darwin on arm64, linux on x86_64 and linux on aarch64.
What does LLM mean in the GuideLLM documentation?
The acronym is used throughout the packaging metadata and the documentation without ever being expanded there. The metadata line that describes the project expands it once, as a platform for deploying and managing large language models, while the page presents the tool as a benchmarking and evaluation platform.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/vllm-project-guidellm)Star history chart for your README
[](https://hysenlabs.com/projects/vllm-project-guidellm)Was this useful?