SearchCLI is published as viking-cli, calls its skills Viking, and hands you a curl to paste
Open CLI for integrating AI search, recommendation, and conversational retrieval into agent systems and business systems
At a glance
- What is it?
- The open command line for Volcengine's AI Search, covering dataset onboarding, application setup, runtime verification, tuning and conversational retrieval, with eleven command groups and six installable skills for external agents. The onboarding flow is server-driven and has you paste a curl command into your own shell.
- Who is it for?
- SearchCLI fits a team integrating Volcengine AI Search into a business system who wants the data onboarding and validation steps to be reviewable commands rather than a console, since every stage has a dry run or a verification counterpart and the output is machine readable. It is a poor fit if you need a one-command onboarding, because the schema inference stage hands you a URL and a task identifier to paste into your own terminal.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
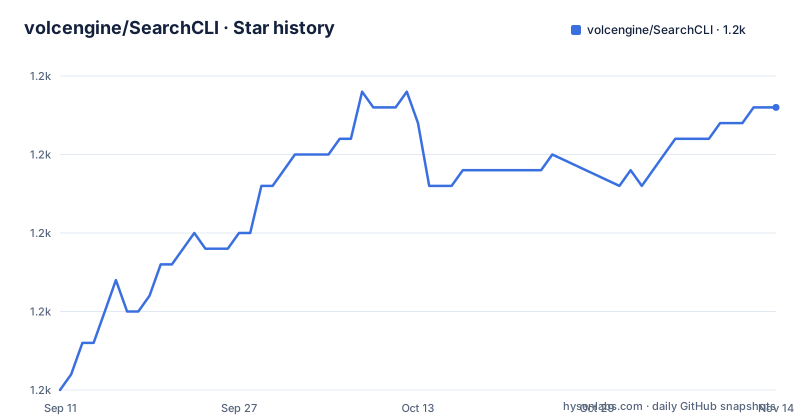
Star history
- volcengine/SearchCLI1,193 ★ · +18
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| volcengine/SearchCLI | 1.2k | 1.2k |
18 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One product, three names, and the package is not called SearchCLI
The names do not line up, and that matters for anyone searching an index or reading a lockfile. The repository, the product and the command are SearchCLI, the underlying service is called AI Search, the installable skill bundle is called Viking skills, and the published npm package is named viking-cli with a version of 0.2.0 and a single binary called vs. So a stack trace, a lockfile and a documentation search will each use a different word for the same tool. The project is also unusually well translated for a command line tool: the root holds twelve README files in addition to the English one, covering Simplified Chinese, Japanese, German, Korean, French, Russian, Italian, Spanish, Brazilian Portuguese, Turkish, Thai and Indonesian. The package manifest ships all twelve alongside the English one, so the translations travel with the install rather than living only in the repository.
The onboarding flow asks you to run its own output
The first data flow is a documented sequence of eight steps and one of them is not a CLI command at all. It starts by asking the tool for an upload URL for a file, then hands you a bare curl invocation with the URL placeholder still in it:
vs dataset import-url --file-name items.jsonl
curl -X PUT --data-binary "@./items.jsonl" "<FileUrl from previous step>"
Only after that upload does schema inference run, taking a storage key, a type, a theme, a language and a dataset name, and then a second call fetches the inference result by task identifier and renders a schema. Only at that point do the JSON files exist that the remaining commands consume. The claim of server-driven schema inference is a real design, and the cost of it is that the happy path cannot be scripted end to end without reading the tool's output and splicing it into a shell command.
The key goes to a credential store and the model name goes to config
The authentication section is the best-engineered part of the page and it makes one distinction consistently. If your shell already holds the access key and secret key pair, an import command moves them into place, and two JSON-emitting commands report what happened and check the environment. Otherwise an interactive login runs in a real terminal. The second credential is an OpenAI-compatible model API, needed if you want tuning query generation or model-based relevance judging, and here the page is explicit that the key must not sit in plain configuration. There is a login command, a status command, and a live check inside the tuning group itself. If the shell already has the base URL, the key and the model name, an import command reads them from the environment, and then the split is stated: the key is stored in the local secure credential store, while the base URL and the model name are stored as ordinary non-secret configuration.
Eleven command groups, and one of them never appears in the capabilities
The public command list has eleven entries: auth, llm, doctor, skill, item, app, dataset, data, search, chat and recommend. The capability list above it names three groups for management, dataset, app and data, three for runtime verification, search run, recommend run and chat run, one tuning group, and the installable skills. The item group is the one that appears in neither sentence. It is plausibly the predecessor of the dataset and data groups, or a separate item-oriented path, but the page gives no description of it, so anyone who types the group name to see what it offers gets no help from the documentation. The verification trio is the part worth internalising: each capability has a run command whose purpose is to check that the configuration works before you trust it in production.
Six skills are published and the CLI can create a seventh
The agent route installs the tool the same way a person does, then adds the skills with a package installer invocation pointed at the repository itself, with a flag that accepts the prompt and a flag that installs globally. The default bundle has six skills and they map onto the command groups one for one: a shared base, an item onboarding skill, and then search, search tuning, chat and recommend. Verification after installation is five commands, of which four take a JSON flag and one does not. For people maintaining the repository rather than using it, there is a separate local loop: list the skills, initialise a new one from a template name, validate, then install all of them. The repository checks are four npm scripts, and the acceptance suite has a built and a live variant for each of two delivery shapes.
A pull request needs a contributor agreement first
The contribution section is two sentences and the second one is a gate. Rather than describing review conventions, it states that external contributors must complete a Contributor License Agreement before a pull request can be accepted. That is a meaningful difference from a project that simply asks for a pull request: the agreement is a precondition rather than a formality attached to the merge, and it has to be done before the work lands. The surrounding documents are named on the page and are present at the root, a contributing guide, a code of conduct and a security policy with the vulnerability reporting route and supported versions in it. The licence is Apache 2.0 with the text in a root file, and the page points at it directly rather than through a badge.
The binary acceptance test covers one platform and one architecture
The build and test scripts are the place where the project's real shape shows. The build regenerates an embedded project template, cleans the distribution directory and runs the TypeScript compiler over the project configuration, and the same build runs automatically before packing. There is a development entry that runs the TypeScript source directly through a runner, and a standalone entry that does the same for a separate source file, which suggests two execution modes shipped from one tree. The acceptance suite exists in four variants rather than two: the built distribution and the packaged binary, each with an offline variant and a live variant. And the binary variant is where the gap is. Packaging a binary is scripted for one target only, an arm64 macOS build on Node 20, so the acceptance path that exercises a real packaged executable runs on one platform and one architecture, while the three platforms the requirements section cares about are never covered by that test.
Editorial conclusion
SearchCLI fits a team integrating Volcengine AI Search into a business system who wants the data onboarding and validation steps to be reviewable commands rather than a console, since every stage has a dry run or a verification counterpart and the output is machine readable. It is a poor fit if you need a one-command onboarding, because the schema inference stage hands you a URL and a task identifier to paste into your own terminal. Before building against it, read the agent quick start and the security policy, complete the contributor agreement if you intend to contribute, and note that only one platform and architecture is exercised by the binary acceptance test.
Frequently asked questions
What does SearchCLI do?
It is the open command line integration surface for AI Search on Volcengine, covering dataset and application management, runtime verification of search, recommendation and chat, text-similarity tuning, and conversational retrieval grounded in application data.
What does SearchCLI require before it runs?
Node.js 20 or newer, git, and a Volcengine access key and secret key with access to AI Search. An OpenAI-compatible model API is additionally needed for tuning query generation and model-based relevance judging.
How does SearchCLI store credentials?
The access key pair is imported from environment variables or entered through an interactive login. For the model API, the key is kept in the local secure credential store while the base URL and model name are stored as non-secret configuration, so the key never sits in plain config.
Which Viking skills does SearchCLI install by default?
Six: vs-shared, vs-item-onboarding, vs-search, vs-search-tuning, vs-chat and vs-recommend. They are installed from the repository itself with a package installer invocation, and the CLI also has commands to list, initialise, validate and install skills for repository maintainers.
Can I contribute to SearchCLI?
Pull requests are welcome, but external contributors must complete a Contributor License Agreement before a pull request can be accepted. The contributing guide, code of conduct and security policy are all at the repository root.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/volcengine-searchcli)Star history chart for your README
[](https://hysenlabs.com/projects/volcengine-searchcli)Was this useful?