TTS Voice Wizard: your speech, mirrored onto a VRChat avatar over OSC
Speech to Text to Speech. Song now playing. Sends text as OSC messages to VRChat to display on avatar. (STTTS) (Speech to TTS) (VRC STT System) (VTuber TTS)
At a glance
- What is it?
- A Windows desktop tool that runs speech to text to speech and can push what you say to an avatar as OSC messages for display. Free and MIT licensed, with cloud voices, extra languages and better recognition behind a subscription, and a README download button that still points at an older release.
- Who is it for?
- TTS Voice Wizard fits a VRChat user who wants captions on an avatar without giving up speech input, and it works outside VRChat too if all you want is dictation to speech. Do not expect the free build to cover the cloud voice providers, since those sit behind the subscription along with the larger language list and the DeepGram recognition model.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 34 days ago.
- What is it written in?
- Mainly C#, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
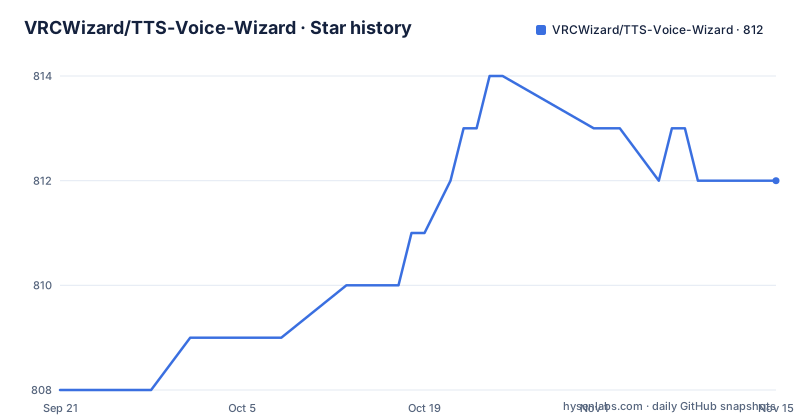
- VRCWizard/TTS-Voice-Wizard812 ★ · +4
| Repository | 2026-09-21 | 2026-11-15 |
|---|---|---|
| VRCWizard/TTS-Voice-Wizard | 808 | 812 |
4 Stars in the last 55 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Speech in, text on the avatar, speech back out
The core loop is narrower than the acronym suggests. You speak, the app recognises the speech as text, and it can speak that text back through a text-to-speech voice. The interesting half is what happens to the text in between.
The app sends what you say to VRChat as OSC messages so it can be displayed on your avatar. Three display targets are named: KillFrenzyAvatarText, Frosty's Billboard, and VRChat's own chatbox. That means the same text can ride on an avatar animation, on a world-space sign, or in the standard chat box, and the choice is a configuration decision rather than a different application.
The stated scope is accessibility, and the documentation makes the point that it works outside VRChat as well. Used as a plain dictation tool it is speech recognition in, speech synthesis out, with a hundred or more voices to choose from and various recognition and synthesis methods behind those choices.
On top of that sits translation, from one language to more than fifty others. The pipeline is therefore configurable at three points: what recognises your speech, what language it is assumed to be in, and what language the voice speaks back in.
A Windows-only C# solution with a shared props file
The repository is a .NET solution rather than a single project. The root holds the solution file, an `OSCVRCWiz/` project directory, a `MoonbaseVoices/` directory that presumably carries voice data, and `common.props` for shared build properties, plus the usual GitHub and licence files.
That shape tells you it is compiled from source if you want to, and shipped as a build artefact if you do not, which is the normal arrangement for a Windows desktop application of this kind. The MIT licence covers the code either way.
The platform requirement is narrow and stated without hedging: Windows 10 or 11, with compatibility explicitly not guaranteed on older Windows versions. There is no macOS or Linux build mentioned anywhere in the project, which for an OSC tool aimed at a VR platform is a reasonable constraint rather than an oversight, since the target hardware runs Windows.
The documentation lives on its own site rather than in the repository, which is worth knowing before you start reading: the wiki table of contents in the README is a list of links into that site, organised into a quick start guide and a set of additional guides. The repository itself holds almost no prose beyond the README.
The download button in the README points at an older build
The getting-started section tells you to download the application from the releases page, and the link it embeds is a direct URL to a specific archive: the Windows x64 zip for version 1.7.7.8. That is not the current release.
The release history moves faster than that link. v1.8.0 was published 2026-05-08, v1.8.0.1 on 2026-05-28, and v1.8.0.2 on 2026-08-19, which is also the date of the last push to the default branch. So the branch has not moved since the most recent patch release, and the version the README button hands you is several patch generations behind it.
The practical consequence is small but annoying: a newcomer following the README gets a two-major-minor-old build, and if a later guide assumes a feature added in 1.8, the documentation and the binary disagree. Take the release asset from the releases list rather than the embedded link.
The versioning convention is worth noting too. A patch bump to the fourth component, from 1.8.0 to 1.8.0.1 to 1.8.0.2, is how fixes are shipped here, so a feature release is the event to look for rather than a minor bump.
Scoop is the alternative install, and it needs an extras bucket
There are two documented ways to install, and the second is contributed rather than first-party. Because of work by a contributor, the application can be installed through Scoop:
`scoop bucket add extras`
`scoop install extras/tts-voice-wizard`
Scoop does not host the application itself, so the first command registers the community extras bucket that contains it and the second installs from there. That is why there are two commands rather than one, and why a plain `scoop install` without the bucket would not find the package.
For anyone already using Scoop this is the route to prefer, because upgrades then follow the same path as everything else on the machine. For anyone who does not use it, the release zip is simpler and avoids installing a package manager first.
Either way the operating system floor is the same, Windows 10 or 11, and the setup documentation points at a quickstart guide and a tutorial video for the initial configuration, including the step that routes audio back through your microphone so that software sees a virtual device.
The free build speaks 50 languages, the subscription speaks 70
The free application is not a trial. It ships with more than a hundred voices and various customization options, and it translates your speech into more than fifty supported languages.
The subscription changes those numbers and adds capabilities rather than unlocking the app. Instant access to premium voices from four cloud providers is the headline: Microsoft Azure, Amazon Polly, Google Cloud and IBM Watson. Translation goes from the free tier's fifty-odd languages to more than seventy. And speech recognition goes through DeepGram's Nova-2 model instead of whatever the default recognizer is.
The stated reason for charging is arithmetic rather than rhetoric. The subscription covers server upkeep and the character costs of the premium APIs, which is the honest version of the pitch and explains why the cloud voices are the part that costs money to deliver.
Subscriptions run through Ko-Fi or Patreon, and the project asks for a GitHub star separately as free support, with a Trello board for planned features and a Discord server for questions.
Beyond speech: song titles, battery levels, heart rate and touch counters
Once the OSC plumbing is in place, the same channel carries more than speech, and this is where the tool becomes an avatar dashboard rather than a dictation app.
Media integration displays the song currently playing, read from Spotify or from your browser. Battery level for trackers and controllers can be displayed in conjunction with XSOverlay. Heart rate can be shown in the VRChat chatbox using Pulsoid or an OSC bridge for heart rate data. There are customizable interactive counters that track how many times a contact receiver has been touched, which is the kind of thing avatars animate on. And voice commands can drive avatar parameters directly, so saying a phrase changes the avatar rather than printing a caption.
For streamers there is a separate guide for putting text into OBS for recording, and for controllers there is a guide to binding hotkeys to speech-to-text on the VR controllers or the mouse.
The common thread is that all of these are outputs over OSC to something that renders in VR. Which is also why the app is not VRChat-only in practice, since anything that listens on the same OSC addresses can display the same data.
Documentation on a site, roadmap on Trello, demo video out of date
Three small facts tell you what to trust about this project.
First, the documentation is a site, not the repository. The quickstart covers playing audio through your microphone with a virtual cable, speech-to-text, text-to-speech, and getting a VoiceWizardPro key, followed by how to get text into VRChat and how to set hotkeys. Additional guides cover translation, voice commands, VRChat counters, word replacements, heart rate with Pulsoid, and tracker battery life. That is a real manual, and it is maintained separately from the code.
Second, the roadmap is a Trello board rather than a milestone list in the repository. Planned features are tracked there, which is a reasonable choice for a single-maintainer desktop application but means you cannot see the plan from the code host.
Third, the project says itself that the demonstration video is a bit out of date. Take that as a signal to prefer the written guides.
On the numbers: 809 stars, 82 forks and 9 open issues, with the last push on 2026-08-19. Given that the audience is a single platform with a large but bounded user base, a high fork count with a modest issue queue reads as a tool people have adopted and stopped reporting problems about.
Editorial conclusion
TTS Voice Wizard fits a VRChat user who wants captions on an avatar without giving up speech input, and it works outside VRChat too if all you want is dictation to speech. Do not expect the free build to cover the cloud voice providers, since those sit behind the subscription along with the larger language list and the DeepGram recognition model. Before you download, ignore the version in the README's button and take the newest release, because that link still points at an older build than the current one.
Frequently asked questions
What is TTS Voice Wizard?
A Windows application that turns speech into text and back into speech, and can send what you say to VRChat as OSC messages for display on your avatar using a billboard tool or the chatbox. It works outside VRChat too.
How do I install TTS Voice Wizard on Windows?
Download the Windows x64 zip from the releases page, or install it with Scoop by running `scoop bucket add extras` and then `scoop install extras/tts-voice-wizard`. Windows 10 or 11 is required, and older versions are not guaranteed to work.
Is TTS Voice Wizard free to use?
Yes, the application is free and MIT licensed, with more than 100 voices and translation to over 50 languages. A VoiceWizardPro subscription through Ko-Fi or Patreon adds cloud voices from Azure, Polly, Google Cloud and IBM Watson, 70+ languages, and DeepGram Nova-2 recognition.
Where can I get more TTS voices for it?
The free application already includes more than 100 voices with customization options. Additional voices from Microsoft Azure, Amazon Polly, Google Cloud and IBM Watson are part of the VoiceWizardPro subscription.
How do I show my speech on my VRChat avatar with it?
Run the application and let it send your speech as OSC messages to VRChat. The text can be displayed through KillFrenzyAvatarText, Frosty's Billboard, or the standard VRChat chatbox, and the wiki covers the setup for each.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/vrcwizard-tts-voice-wizard)Star history chart for your README
[](https://hysenlabs.com/projects/vrcwizard-tts-voice-wizard)Was this useful?