Wan2.1 fits a consumer GPU, but the install pulls a compiled kernel
Wan: Open and Advanced Large-Scale Video Generative Models
At a glance
- What is it?
- Wan2.1 is an open suite of video foundation models covering text-to-video, image-to-video, video editing, text-to-image and video-to-audio, with a 1.3B checkpoint that needs 8.19 GB of VRAM and produces five seconds of 480P video on an RTX 4090 in about four minutes without quantisation. The install requires a compiled attention package and caps numpy below version 2.
- Who is it for?
- Wan2.1 fits someone who wants open video generation running on hardware they own, and who will reach for the 1.3B checkpoint on a consumer card. It does not fit a pipeline that needs throughput, because five seconds of 480P takes about four minutes on a 4090 with no quantisation, and the acceleration work lives in other repositories.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 8 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
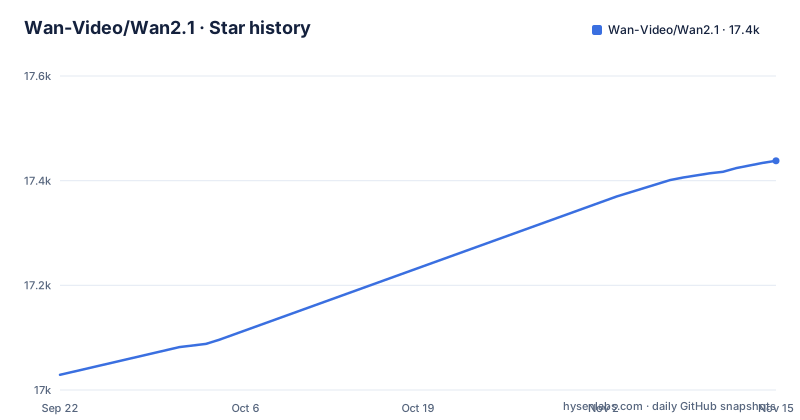
- Wan-Video/Wan2.117,438 ★ · +409
| Repository | 2026-09-22 | 2026-11-15 |
|---|---|---|
| Wan-Video/Wan2.1 | 17k | 17.4k |
409 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The 1.3B checkpoint is the one that fits, and the four minutes is unquantised
The hardware claim in this file is specific enough to plan around, and it comes with a qualifier worth keeping. The text-to-video model at 1.3B parameters requires 8.19 GB of video memory, which the file says makes it compatible with almost all consumer-grade GPUs, and it generates a five-second 480P video on an RTX 4090 in about four minutes. The qualifier is in brackets: without optimisation techniques such as quantisation. So the number to plan around is four minutes of compute for five seconds of output, on a card that costs more than most laptops. That is a throughput figure rather than a latency one, and it is the right way to read the rest of the file, which claims performance comparable to some closed-source models and better benchmark results than existing open models. Both claims are about quality per unit of compute, not about how quickly you get a clip.
The dependency list is where the install difficulty actually is
There is no pure-Python install here. The runtime list is short and ordinary until two entries, one of which is a compiled attention package and one of which is a version ceiling:
torch>=2.4.0
torchvision>=0.19.0
opencv-python>=4.9.0.80
diffusers>=0.31.0
transformers>=4.49.0
tokenizers>=0.20.3
accelerate>=1.1.1
tqdm
imageio
easydict
ftfy
dashscope
imageio-ffmpeg
flash_attn
gradio>=5.0.0
The attention package has to be built against your stack, which means a compiler and a matching toolkit, and the final line of the same list caps numpy below version 2, so a shared environment that already has numpy 2 will conflict. The list also appears a second time in a requirements file, and the two are identical today, which means nothing keeps them identical tomorrow. The package itself is a plain setuptools build with a version of 2.1.0, requiring Python 3.10 or newer and below 4.
The documentation link points back at the repository, so INSTALL.md is the reference
The packaging metadata lists a set of links, and one of them is worth pausing on. There is a homepage, a documentation entry, the repository itself, the model host on one registry, the model host on another, and a chat invite. The documentation entry resolves to this same repository. So the install instructions you need are a file at the top of the tree, and the model documentation lives on the model hosts, where the weights and the cards are, rather than here. That is a reasonable division for a research release, and it does mean that anyone evaluating the project has three places to read: this file for the claims, the install file for the steps, and the model host for what is actually available to download.
The ComfyUI and Diffusers integrations landed before most of the features
The news list is a timeline and it changes how you should approach the repository. The inference code and weights were released on 25 February 2025. The ComfyUI integration arrived two days later, on 27 February. The Diffusers integration for text-to-video and image-to-video came on 3 March. The technical report followed on 21 March, first-last-frame-to-video on 17 April, and the all-in-one creation and editing model on 14 May. So the two integrations predate most of the capabilities, which means the practical route for a lot of people is a node or a pipeline in one of those two tools, with this repository as the reference implementation underneath. That has a consequence for anyone writing their own inference code: you are likely rebuilding something a maintained pipeline already does, and the community list is where the interesting reuse is.
The community list tells you which checkpoint to start from
This is the most useful section in the file and it is the one most summaries skip. The projects built on top are listed with the checkpoint each one uses, and the mapping is consistent. The 1.3B text-to-video checkpoint is the base for editing work, including a training-free editing collection built on image-based methods, and a multi-shot portrait model that keeps the same character across clips. The 14B image-to-video checkpoint is the base for control work: an autonomous driving world model conditioned on a scene frame and a trajectory, a point-level motion control framework, an animation model driven by 3D avatars, a video virtual try-on, a semantic control model with a mixture-of-transformers design, and more. So the checkpoint is not interchangeable, and the file's list is a better guide to which one you want than the feature bullets above it.
The impressive throughput numbers belong to other repositories
Read the community entries for speed and the base model stops looking like the fast option. One project reports minute-scale video synthesis at 19.5 frames per second on a single H100, and about 10 frames per second on a single Ascend NPU, and it claims to do that without conventional long video anti-drifting strategies or standard video acceleration techniques. Another integrates both this version and the next one and supports a set of engineering acceleration techniques, running on an RTX 5090 and on an RTX 4060 with 8 GB. Neither of those numbers is about the model in this repository on its own. The honest summary is that the base model is a research checkpoint that runs on a consumer card at four minutes per clip, and that the speed people quote from this ecosystem comes from work done on top of it.
black and isort are configured, and the make target runs yapf
A small inconsistency tells you about the working habits here. The packaging metadata configures two formatters and a type checker: a line length of 88 for one, an import profile matching the other, and a type checker in strict mode. The repository also carries a style file for a third formatter, and the entire build file has one target, a format target, which runs the import sorter and then that third formatter over the entry script, the demo directory and the package. So make format does not produce what the configured formatter would, and the two toolchains disagree about the same files. It is harmless if you do not use the target and mildly confusing if you do, and it is the kind of detail that tells you the scripts were written and then the project configuration moved on without them.
Editorial conclusion
Wan2.1 fits someone who wants open video generation running on hardware they own, and who will reach for the 1.3B checkpoint on a consumer card. It does not fit a pipeline that needs throughput, because five seconds of 480P takes about four minutes on a 4090 with no quantisation, and the acceleration work lives in other repositories. Before you install, read the dependency list twice: a compiled attention package is a hard requirement rather than an extra, numpy is capped below version 2, and the same list is written down twice. Then choose your route, because the ComfyUI and Diffusers integrations predate most of what is in this repository, so a pipeline you write yourself is likely to reimplement something a library already does. And pin a commit rather than a tag: the repository publishes no releases, and the last recorded push is 2026-03-05.
Frequently asked questions
how to install wan2 1
The install instructions are in an install file at the top of the repository. The runtime dependencies are listed twice, in the packaging metadata and in a requirements file, and they include a compiled attention package and a ceiling on numpy below version 2, so the environment needs a compiler and a matching setup. The package is a plain setuptools build requiring Python 3.10 or newer.
how to use wan2.1
Pick a task and a checkpoint. The suite covers text-to-video, image-to-video, video editing, text-to-image and video-to-audio, and the 1.3B text-to-video model is the one that fits a consumer GPU at 8.19 GB of video memory. The repository also ships a demo directory built on a web interface toolkit, and the file points at ComfyUI and Diffusers integrations for running the models from an existing tool.
what is wan2 1
It is an open suite of video foundation models. Beyond the generation tasks it includes a video autoencoder that encodes and decodes 1080P video of any length while preserving temporal information, and it is described as the first video model able to generate both Chinese and English text inside the picture.
is wan2 1 open source
The repository is licensed under the Apache License 2.0, with the licence text in a file at the top level, and the project released its inference code and weights, published a technical report, and integrated its text-to-video and image-to-video pipelines into a widely used diffusion library.
How to make Wan2 1 faster?
The README states that the 1.3B model produces a five-second 480P clip on an RTX 4090 in about four minutes without optimisation techniques such as quantisation, and it lists third-party projects that add acceleration, including one that runs on a 5090 and on an 8 GB 4060 and another that reports 19.5 frames per second on a single H100.
how to install wan2 1 comfyui
There is nothing to install into ComfyUI from this repository, because the integration already exists. The project announces that Wan2.1 was integrated into ComfyUI in February 2025 and links to a page of ComfyUI examples for it, alongside a separate integration into a diffusion library from March 2025.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/wan-video-wan2-1)Star history chart for your README
[](https://hysenlabs.com/projects/wan-video-wan2-1)Was this useful?