UZI-Skill: one ticker in, a self-contained HTML report and 66 judge votes out
UZI Skill: hot-money trading skills for A-share, Hong Kong and US stocks, modeled on 66 veteran investors, combining 22 dimensions of data, 180 quantitative rules and 17 institutional analysis methods to help you watch the market.
At a glance
- What is it?
- UZI-Skill is a Python agent skill that turns one ticker into a stock deep-analysis report, wrapping free data sources and 66 named reviewer personas. Its install paths differ per agent, its command set is prefix-sensitive, and its free-data design is also its main limit.
- Who is it for?
- UZI-Skill suits a developer who wants a research-shaped draft report per ticker from free sources, works inside an agent such as Claude Code, Cursor or Gemini CLI, and accepts that the numbers come from scraped and public endpoints rather than a paid feed. It is a poor fit for anyone needing a defensible data lineage, a chat group, or a reproducible version pin, since package.json and the README say 3.9.4 while the newest tag is v3.9.1.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 4 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
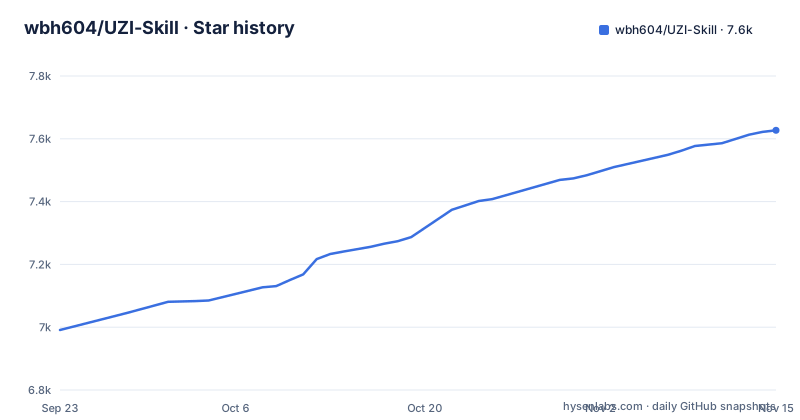
- wbh604/UZI-Skill7,627 ★ · +636
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| wbh604/UZI-Skill | 7k | 7.6k |
636 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Six agents, six install lines, and one namespace prefix you cannot skip
Installation is a table of one-liners, one per agent, and each one is a command rather than a document to read. Claude Code takes a marketplace add followed by a plugin install:
/plugin marketplace add wbh604/UZI-Skill
/plugin install stock-deep-analyzer@uzi-skill
Cursor takes /add-plugin stock-deep-analyzer. Gemini CLI takes gemini extensions install with the repository URL. Codex is told to follow an INSTALL.md from a raw GitHub URL, and OpenClaw is simply told to install the repository. One agent is already broken upstream: hermes skills install is described as being misjudged by a Skills Guard in another project, so the README routes Hermes users to a shell script instead.
The rule that matters after install is the prefix. Once the plugin is installed, every command begins with stock-deep-analyzer:, and short names such as /analyze-stock are not resolved in some environments. The four commands the project expects you to use most are:
/stock-deep-analyzer:analyze-stock 贵州茅台    ← 完整 22 维 × 66 评委分析(5-8min)
/stock-deep-analyzer:quick-scan 002217         ← 30 秒速判
/stock-deep-analyzer:scan-trap 002217          ← 杀猪盘排查
/stock-deep-analyzer:dcf 600519                ← DCF 估值专项
There are 14 commands in total, and the same full-name requirement is repeated for Cursor, Gemini CLI and Codex.
The plain clone path is the only one that shows you the dependencies
One install route bypasses the agent entirely and exposes what the skill actually needs:
git clone https://github.com/wbh604/UZI-Skill.git && cd UZI-Skill && pip install -r requirements.txt && python run.py 贵州茅台The dependency file splits by job. akshare>=1.14.0 and yfinance>=0.2.40 cover A-share, HK and US data. baostock>=0.9.1 is the K-line fallback, and that lower bound is not cosmetic: the file records that from 2026-04-22 the BaoStock service side requires 0.9.1 or newer, and older versions fail outright at login().
Then come pandas>=2.0.0 and requests>=2.31.0 for handling, exchange-calendars>=3.0.2,<5.0 for validating trading days and holidays across the three markets, ddgs>=9.0.0 for web search, which the file marks as the default in lib/web_search and as mandatory for the fallback path on qualitative dimensions, mplfinance>=0.12.10b0 marked optional for PNG output, playwright>=1.42.0 for screenshots, and rich>=13.0.0 for terminal formatting.
One step lives outside requirements.txt. The header of that file tells you to run playwright install chromium afterwards, because the share card and war report images are rendered with a real browser rather than drawn in Python.
The optional API key changes name resolution, not access
The project's stated position is free data sources with zero API keys, and the environment file keeps every value optional. Copying .env.example to .env is the entire setup step.
MX_APIKEY is the one that does real work. When it is set, the skill prefers an official NLP API for two specific tasks: correcting Chinese company names, so a typo like 北部港湾 resolves to 北部湾港, and fetching quote snapshots, which the file says is far more stable than scraping push2.eastmoney.com. Leave it empty and both jobs fall back to the scraped path, which is where wrong-name lookups and missing quotes surface.
Four more switches are documented as commented lines. STOCK_NO_CACHE=1 disables all API caching and forces a refetch, UZI_NO_AUTO_OPEN=1 stops the finished report from opening a browser, UZI_DISABLE_GLOBAL_PEERS=1 keeps peers inside the local market instead of going global, and UZI_GLOBAL_PEER_LIMIT=8 caps how many global peers get completed, with a supported range of 3 to 12.
Read together, the file is a switchboard for cost and noise rather than a place where you enable the tool. Nothing in it is required to produce a report.
The rule counts disagree between the description and the README
The headline numbers are large, and they are not consistent across the project's own files. The repository description advertises 22 dimensions, 180 quantitative rules and 17 institutional methods. The README says 22 dimensions, 66 reviewers across 9 schools, 242 quantitative rules and 22 institutional methods. Both are in the same repository, on the same day, describing the same engine.
Versioning has a similar gap. package.json declares version 3.9.4 for a package named stock-deep-analyzer, and the README calls v3.9.4 the manifest version, noting recent maintenance has not bumped the version number. The newest tagged release on the repository is v3.9.1, dated 2026-06-22, whose note describes a collapsible report navigation bar tied to issue #79. Before that, v3.9.0 on 2026-06-11 added the 股海贼王 judge and v3.8.1 on 2026-06-10 was a broad cleanup.
So pinning is ambiguous by construction. An agent install takes what package.json says, while a git tag gives you 3.9.1. The last push to the default branch main is dated 2026-10-18, so the branch is ahead of every tag.
Each of the 14 commands is its own analysis, not a flag
The command set is wide, and each entry produces a different document rather than a variation of one report. The specialised commands include DCF valuation with a WACC plus a 5x5 sensitivity table, peer comparison with PE and PB percentile analysis, a 30 second quick scan, a trap scan, ic-memo and investor-panel.
Three flags change the shape of a run instead. --versus puts two to four stocks against each other, --portfolio reads a CSV for portfolio health, and --school A-I locks the analysis to one school and prints a SCHOOL LOCK banner so you know the other reviewers were not consulted.
A full analyze-stock run produces a self-contained HTML report you can open in a browser and read offline, a 1080x1920 vertical image, a 1920x1080 war report image, and a one-paragraph summary meant for pasting into a chat. The full analysis takes 5 to 8 minutes; the quick scan takes 30 seconds.
Remote mode publishes the report and can install a binary for you
There is a mode for reading a report away from the desk, and it works by putting the report on the public internet. Passing --remote starts a Cloudflare Tunnel and returns an https://xxx.trycloudflare.com link. If cloudflared is not present on the machine, the default is to print installation instructions and stop, and automatic installation only happens when you add --install-cloudflared.
Both halves of that design deserve a second look. The tunnel URL is public for as long as the process runs, and a report contains the verdicts of all 66 reviewers on one stock, so a forwarded link is a forwarded view of your position analysis. The other half is that --install-cloudflared lets the tool install cloudflared itself.
Ticker formats are broader than the market list suggests. The usage examples show a Chinese company name such as 贵州茅台, an A-share code such as 002273, an HK code with a suffix such as 00700.HK, a US symbol such as AAPL, and exchange-suffixed codes such as 7203.T and 005930.KS.
No community, no paid feed, and a verdict engine you must read sceptically
The project's most-advertised property is also its ceiling: every price, fundamental and history input is pulled from free web sources plus web search, and the stated goal is zero API keys with A-share coverage working out of the box. That is a real advantage for a draft, and it is also why there is no data vendor behind a verdict.
Scoring is opinionated on purpose. The Serenity reviewer carries 8 penalty factors and a 3-level evidence ladder, scoring roughly 90 for a company with confirmed mass production against roughly 60 for one that is only a theme, plus an 8-layer supply chain breakdown. The A-share and HK daily watchlist filters out ST names, names without a valid quote and names with turnover under 200 million, then caps the list at 10 stocks rather than padding it.
There is also no chat group to fall back on. The README states plainly that there is no group and that none will be created. Usage guidance lives in per-agent instruction files instead: AGENTS.md, CLAUDE.md, CODEX.md, GEMINI.md, and separate INSTALL.md files under .codex/ and .opencode/. Code lives in skills/ with commands/ and agents/ alongside, plus run.py, screen.py and setup.sh at the top level.
Editorial conclusion
UZI-Skill suits a developer who wants a research-shaped draft report per ticker from free sources, works inside an agent such as Claude Code, Cursor or Gemini CLI, and accepts that the numbers come from scraped and public endpoints rather than a paid feed. It is a poor fit for anyone needing a defensible data lineage, a chat group, or a reproducible version pin, since package.json and the README say 3.9.4 while the newest tag is v3.9.1. Before running it, read the requirements for the hard lower bounds, decide whether the optional API key is worth it, and check whether publishing a report through --remote is acceptable for the stock you are about to analyse.
Frequently asked questions
How do you describe uzi in UZI-Skill?
UZI stands for 游资 and names the skill set: the README frames it as 66 investment personalities, among them 巴菲特 and 赵老哥, scoring the same stock across A-share, HK and US markets. The newest of them, 股海贼王, arrived with v3.9.0 and is described as the first judge distilled from real trade statements.
What does UZI-Skill need before its first run?
On the plain CLI path, a clone plus pip install -r requirements.txt, followed by playwright install chromium, since the report images are rendered with a real browser. The data libraries are akshare, yfinance and baostock, with baostock needing 0.9.1 or newer because the service side has required that since 2026-04-22.
How long does one UZI-Skill analysis take?
The full analyze-stock run takes 5 to 8 minutes, while quick-scan is documented as a 30 second judgement. Either way the output set is a self-contained offline HTML report, a 1080x1920 image, a 1920x1080 war report and a one paragraph summary.
Does UZI-Skill need a paid API key?
No, the design goal is free data sources with zero API keys. The optional MX_APIKEY points at an official NLP endpoint used to correct Chinese company names and to fetch quote snapshots more reliably than scraping, and four other switches in .env.example disable caching, browser auto-open, global peers or cap how many global peers are completed.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/wbh604-uzi-skill)Star history chart for your README
[](https://hysenlabs.com/projects/wbh604-uzi-skill)Was this useful?