Midscene.js: screenshot-driven E2E tests in natural language, inside Playwright or as YAML
AI-powered, vision-driven UI automation for every platform. Two ways to test, add Midscene to your Playwright / Vitest suite, or let an AI agent test autonomously via Skills.
At a glance
- What is it?
- Midscene.js locates and checks UI elements from screenshots with a vision model, so tests are written as plain-language steps rather than selectors. It runs inside Playwright, Puppeteer and Vitest or through its own YAML framework, across web, Android, iOS, HarmonyOS and desktop, and every step depends on the model you configure.
- Who is it for?
- Midscene.js fits teams whose UIs defeat selectors, such as canvas apps, icon-only controls, cross-origin iframes or native mobile and desktop apps, and who accept paying for model calls on every run. Teams that need byte-for-byte deterministic tests with no external model dependency should keep their selector-based Playwright suites and add Midscene only where selectors fail.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
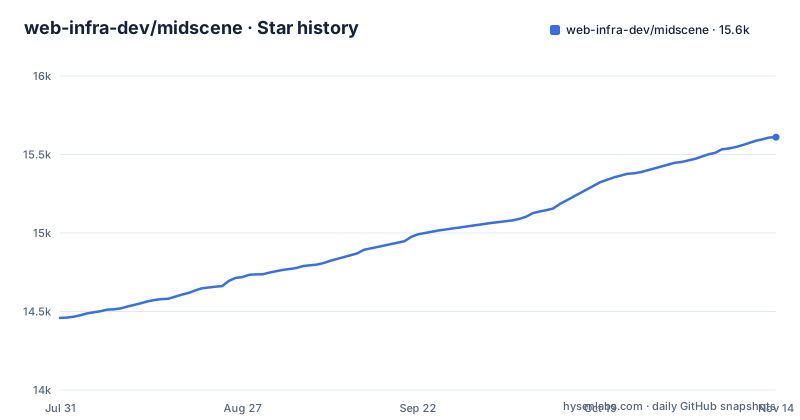
- web-infra-dev/midscene15,610 ★ · +1,151
| Repository | 2026-07-31 | 2026-11-14 |
|---|---|---|
| web-infra-dev/midscene | 14.5k | 15.6k |
1,151 Stars in the last 106 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Elements are found by how they look, not by selectors
Midscene's core mechanism is visual localization. It takes a screenshot, locates the element you described by its appearance and position, then clicks, types or scrolls. Because nothing depends on the DOM, you can target icon-only buttons, custom controls, content drawn on a canvas element, and elements inside cross-origin iframes without maintaining selectors or adding test IDs or semantic annotations.
The same property is what makes the approach portable. Visual localization does not care which rendering stack produced the pixels, so one set of Agent APIs covers browsers, phones and desktop applications. The project also argues that screenshots keep model input smaller than sending a large DOM tree.
The cost is that a step is no longer a deterministic lookup. Each instruction is interpreted by a vision model, so the outcome depends on the model's reading of the screen and on how precisely you phrased the step. A selector either matches or it does not; a description like "the blue button" can be ambiguous when two blue buttons are visible. Teams moving from selector-based suites should expect to spend time on wording, and to keep exact checks in code where precision matters.
PlaywrightAgent wraps an existing Playwright page
Midscene does not replace Playwright for web testing; it sits on top of it. You configure a model, open your app in a Playwright page as usual, and hand that page to an agent:
import { PlaywrightAgent } from '@midscene/web/playwright';

const agent = new PlaywrightAgent(page);

await agent.aiAct('Search for headphones and filter the results to prices under $100');
await agent.aiWaitFor('The filtered search results are visible');
await agent.aiAssert('There are products in the search results, and each costs less than $100');
Three verbs carry most tests. aiAct performs an action described in plain language, aiWaitFor blocks until a described state is visible, and aiAssert checks a described condition. Navigation, fixtures and test runners stay in Playwright, so you can mix ordinary locator-based steps with AI steps in the same file.
For web, Puppeteer is also supported, and a bridge mode drives a desktop Chrome. For mobile and desktop apps the integration is the platform Agent used with Vitest. After a run, an HTML report shows screenshots, the element locations the model chose, the AI decision process, and action and assertion results, which is where you go to understand why a step failed.
Midscene Test splits flows into YAML and reusable TypeScript Nodes
The second way to use the project is Midscene Test, published as @midscene/test, a natural-language E2E framework of its own. After creating a Midscene Test project and configuring a model and the Web runtime, a case looks like this:
beforeEach:
  - gotoUrl: https://your-shop.example

cases:
  - name: Find headphones under $100
    steps:
      - aiAct: Search for headphones and filter the results to prices under $100
      - aiWaitFor: The filtered search results are visible
      - aiAssert: There are products in the search results, and each costs less than $100
Logic that needs precise control lives in TypeScript Nodes: data preparation, API calls and cleanup that several cases share. A refund test can create an order through an API, request the refund through the UI, and verify the result in one workflow. Registered Nodes and their inputs can be exported as a Markdown Node Spec, so developers and AI agents can write cases without reading the TypeScript.
The framework has the controls a suite needs at scale: setup, fileSetup, beforeAll and beforeEach hooks with matching cleanup hooks that still run after timeouts or Ctrl+C; case retries, step timeouts, continue-on-error and bail; and maxConcurrentFiles for concurrency, with fileSetup giving each file its own page, Agent or device. Step-level reports include screenshots, inputs, outputs and Agent replay.
Nothing runs until you choose and pay for a model
Every AI step calls a model, so model choice is a setup decision, not an afterthought. Supported families include GPT, Qwen, Doubao Seed, DeepSeek, Gemini and Kimi, including open-source options you can self-host. The project's Model Selection Guide and Model Configuration pages cover choosing and wiring one up.
The published numbers show how much the model matters. In the reported AppControlBench run, Midscene with Doubao Seed 2.1 Turbo passed 58 of 60 tasks, a 96.7% Pass@1, for $0.59 in total model cost. AndroidWorld reports 93.1% with Gemini-3.5-Flash, and MobileWorld 78.6% with Gemini-3.6-Flash. Each figure belongs to one model in one configuration, and the AndroidWorld report notes its own environment and validator adjustments.
The consequence for a reader is that none of these numbers transfers automatically to your app or your model. A different model, a self-hosted one, or a UI unlike the benchmark tasks can change both pass rate and cost. Running the suite also means every CI run sends screenshots to the model endpoint you configure, which is a data handling question for apps that display customer information on screen. Self-hosting an open model keeps that traffic in-house.
Mobile and desktop support rides on ADB, WebDriverAgent, HDC and RDP
The one-API claim holds at the Agent level, but each platform still needs its own device plumbing. Android devices and emulators connect through ADB. iOS devices and simulators go through WebDriverAgent. HarmonyOS NEXT uses HDC. Desktop covers macOS, Windows and Linux, with remote RDP support. For anything else, you can provide screenshots and action capabilities yourself and plug in a custom interface.
This means Midscene removes selector maintenance but not device setup. An iOS test still needs a working WebDriverAgent connection, and an Android suite in CI still needs devices or emulators reachable over ADB. If that plumbing is flaky, the AI layer above it cannot compensate. The showcases on the project site range from web form validation to mobile workflows and community-built in-vehicle testing, which shows the custom interface route is used beyond the listed platforms.
Visual assertions check what users see, including canvas and native views
aiAssert is where the visual approach pays off most clearly. You describe the expected appearance and Midscene checks it against the screenshot:
await agent.aiAssert('The selected plan has a blue border and a checkmark');
await agent.aiAssert('The error message is visible below the email field');
Colors, selection highlights, layout and visual feedback become assertable, including content drawn on a canvas or shown in a native app, which selector-based checks cannot see at all.
The limit is precision. An assertion like "has a blue border" is judged by the model, not by reading a CSS value, so it confirms what a person would perceive rather than an exact color code or pixel offset. For checks where exact values matter, such as a computed price or a specific attribute, keep a conventional assertion in code next to the visual one. The YAML framework's TypeScript Nodes exist for exactly that split.
An Nx monorepo that ships patch releases days apart
The repository is a pnpm and Nx monorepo under the MIT license, with packages in packages/, applications in apps/, and examples in examples/catalog/. The root package.json is at version 1.17.5. Its scripts separate ordinary tests from model-dependent ones: test runs the unit suites, while test:ai runs AI tests for @midscene/core, @midscene/web and @midscene/cli, and test:ai:all chains the web e2e, cache, report and visualizer suites. Contributors running the AI suites need model access configured.
Releases are frequent. v1.17.2 shipped on 2026-10-28, v1.17.3 on 2026-10-29 and v1.17.5 on 2026-11-02, the same day as the last push to main. That cadence is good for fixes reaching users quickly, but it also means behavior can shift between minor patch versions of an AI-driven tool. Pin the @midscene packages to an exact version in your test project so a model-facing change does not alter suite results between two CI runs. A Simplified Chinese README is maintained alongside the English one.
Editorial conclusion
Midscene.js fits teams whose UIs defeat selectors, such as canvas apps, icon-only controls, cross-origin iframes or native mobile and desktop apps, and who accept paying for model calls on every run. Teams that need byte-for-byte deterministic tests with no external model dependency should keep their selector-based Playwright suites and add Midscene only where selectors fail. Before adopting it, pick a model from the selection guide and run your own critical flows, because the published pass rates were each measured with one specific model.
Frequently asked questions
What is Midscene.js?
Midscene.js is an MIT-licensed, vision-driven UI automation and E2E testing tool. You describe steps and expected results in natural language, and an AI agent locates elements from screenshots to act and verify on web, mobile and desktop apps.
How does Midscene compare with Playwright?
Midscene works on top of Playwright rather than replacing it: PlaywrightAgent from @midscene/web/playwright wraps a Playwright page and adds aiAct, aiWaitFor and aiAssert steps. It also supports Puppeteer, desktop Chrome, and mobile and desktop platforms through Vitest.
Which AI models can Midscene use?
Midscene supports GPT, Qwen, Doubao Seed, DeepSeek, Gemini, Kimi and more, including open-source models you can self-host. In the reported AppControlBench run, Doubao Seed 2.1 Turbo passed 58 of 60 tasks for $0.59 in total model cost.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/web-infra-dev-midscene)Star history chart for your README
[](https://hysenlabs.com/projects/web-infra-dev-midscene)Was this useful?