VideoCaptioner: free ASR engines, a key-gated LLM middle stage, and a version that comes from git tags
VideoCaptioner (Kaka Subtitle Assistant) is an LLM-powered subtitle assistant covering the full workflow: subtitle generation, sentence segmentation, correction and translation - a powerful tool for easy and efficient video subtitling.
At a glance
- What is it?
- WEIFENG2333/VideoCaptioner is a Python tool that transcribes, refines, translates and burns in subtitles through a CLI and a PyQt desktop app. Recognition and translation run free, the LLM stages need a key, and the version number is derived from git tags rather than written in pyproject.toml.
- Who is it for?
- VideoCaptioner suits someone subtitling their own footage who is happy with recognition plus machine translation and does not want to write a pipeline. Read scripts/run.sh before piping it to bash on macOS, because that path fetches whatever is on master at that moment with no checksum.
- Can I use it commercially?
- Yes, with conditions. GPL-3.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Yes. The repository last received commits 63 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
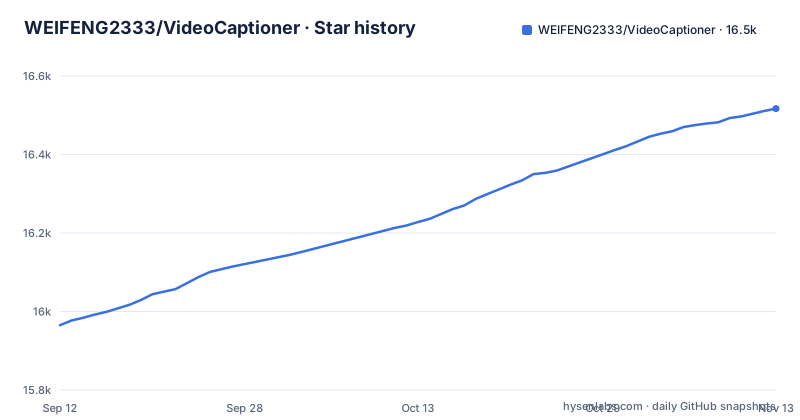
- WEIFENG2333/VideoCaptioner16,517 ★ · +552
| Repository | 2026-09-12 | 2026-11-13 |
|---|---|---|
| WEIFENG2333/VideoCaptioner | 16k | 16.5k |
552 Stars in the last 62 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The version comes from git tags, and the newest tag is not a version
The package manifest does not contain a version number. The project table sets dynamic = ["version"], and the build requirements list hatchling together with hatch-vcs, so the version is derived from the repository's tags at build time. That makes the tag list load-bearing in a way it usually is not. The releases here are v1.4.2 dated 2026-05-24 and v1.4.1 dated 2026-03-28, but a third tag, ffmpeg-bin, is dated 2026-06-17 and carries a note describing itself as the FFmpeg runtime dependency binary that should not be deleted. So the most recent tag by date is not a version tag. Any tooling that infers the current release by taking the newest tag, including scripts and mirrors that assume semver ordering, can pick up a payload tag instead of a release, and you cannot read the answer out of pyproject.toml because the field is declared dynamic.
The gui extra is empty while PyQt5 sits in the required dependencies
The optional dependency groups hold a single entry, and that entry is empty: the gui extra declares nothing. Everything the desktop application needs is instead in the mandatory dependency list, where PyQt5 is pinned to exactly 5.15.11 and PyQt-Fluent-Widgets to exactly 1.8.4. Every other dependency in that list uses a >= lower bound, so these two are the odd ones out for a reason that is not stated anywhere. The consequence for a user is direct. A CLI-only installation, where you never open the desktop app, still pulls in the Qt bindings, and because the pins are exact rather than ranges, a different PyQt5 already present on the machine, or one required by an unrelated package in the same environment, has no room to coexist. The extra named for the GUI buys you nothing to skip.
The dependency list names no Whisper engine and no ffmpeg
The command reference offers five transcription engines: faster-whisper, whisper-api, bijian marked free, jianying marked free, and whisper-cpp. The declared dependencies include none of the local Whisper names. There is an openai client, which covers the hosted whisper-api path and the LLM calls, but no local Whisper runtime is declared as a dependency. The same gap exists for media tooling. Fusing an audio track, or burning subtitles into a picture, needs ffmpeg, and ffmpeg is not among the dependencies either. So a plain pip install gives you the CLI, the language detection, the caching layer, the retry library and the TTS client, while the two local Whisper engines (faster-whisper and whisper-cpp) and ffmpeg are not among the declared dependencies.
The macOS install path pipes a remote script straight into bash
Three installation routes are offered and they carry very different risk. The first is pip, which resolves a declared, pinned dependency list from a package index. The second is a Windows installer taken from the releases page, a binary you download and then run yourself. The third is a single line that fetches a script from the master branch and pipes it into a shell. That last one executes whatever happens to be on master at the moment you run it, with no tag, no commit and no checksum, and it gives you no chance to read the script before it runs. The scripts directory in the repository does contain run.sh, so the content is inspectable in advance if you choose to fetch it and read it first. Installing on macOS this way means trusting a branch tip, which is a weaker guarantee than the Windows route offers.
pip install videocaptioner
curl -fsSL https://raw.githubusercontent.com/WEIFENG2333/VideoCaptioner/master/scripts/run.sh | bash
Configuration resolves through four layers and only one of them shows you the result
Settings are resolved by a documented priority: command line arguments first, then environment variables prefixed VIDEOCAPTIONER_, then the configuration file, then built-in defaults. The subcommand table lists config with show, set, get, path and init. That gives the LLM credentials three independent homes. A key written into the config file is silently overridden by an exported VIDEOCAPTIONER_ variable with the same name, and neither one warns the other. The only way to see which layer actually won is to run config show and read the merged result, and config path is what tells you where the file lives so you can inspect what is in it. For a tool that sends subtitles to a third-party endpoint, that difference matters, because the endpoint and the model name are the settings an exported variable can silently replace, and a leftover VIDEOCAPTIONER_ value from an earlier run is indistinguishable from a deliberate one.
Free coverage stops at recognition and translation, before the refinement stage
The README separates the tool into what costs nothing and what does not. Speech recognition through the bijian engine and translation through bing or google are free and need no configuration, stated plainly as working immediately after install. The LLM is reserved for subtitle optimization and large-model translation. Providers are anything speaking the OpenAI protocol, with three listed: the project's own relay at api.videocaptioner.cn, SiliconCloud and DeepSeek. The working principles section credits LLM semantic segmentation, context-aware translation with a reflection optimization step, and batch concurrency. So on the free path the recognition and translation stages have backends, while the middle of the pipeline, the line breaking and refinement, is the part that wants a key. The documentation does not say what the full process command does when no key is configured, which is the detail to check before assuming an unattended run will complete end to end. The README's CLI examples include these four commands:
videocaptioner transcribe video.mp4 --asr bijian
videocaptioner subtitle input.srt --translator bing --target-language en
videocaptioner process video.mp4 --target-language ja
videocaptioner synthesize video.mp4 -s subtitle.srt
Setting the LLM side is three more, and each key travels through the same config command. Replace `YOUR_API_KEY` with your key:
videocaptioner config set llm.api_key 'YOUR_API_KEY'
videocaptioner config set llm.api_base https://api.openai.com/v1
videocaptioner config set llm.model gpt-4o-mini
The Claude Code Skill is a markdown file copied into your home directory
Agent integration is handled by installing one file. You create a directory under your home folder for skills named videocaptioner, then copy the repository's skills/SKILL.md into it. After that, typing the slash command with a transcribe invocation inside Claude Code routes the request to the CLI. Nothing is registered with a package manager, no version is recorded and no dependency is resolved, so what lands in your home directory is a snapshot of the instruction file at the moment you copied it. If the CLI's commands or flags change in a later release, the copied file does not follow, and your agent keeps working from the older description. The tree does carry the skills directory and the README treats this as a supported install path rather than an experiment, but the update step is manual and easy to forget.
OS Independent is declared while the packaged routes cover Windows and macOS
The classifier list claims Operating System :: OS Independent, alongside Environment :: Console, Intended Audience :: End Users/Desktop and Development Status :: 4 - Beta. The documented installation routes do not match that claim evenly. One is the pip install, which is platform neutral but gives no platform instructions beyond that. One is a Windows installer from the releases. One is a bash script for macOS. There is a VideoCaptioner.spec at the top level, which is the PyInstaller configuration used to package the desktop app, and a scripts directory holding the shell entry point, so packaging work has clearly been done for two operating systems and not a third. A Linux user has the pip route and nothing else written down. The Python constraint is firmer still: requires-python is >=3.10,<3.13, and the classifiers stop at 3.12, so 3.13 is out of range.
Editorial conclusion
VideoCaptioner suits someone subtitling their own footage who is happy with recognition plus machine translation and does not want to write a pipeline. Read scripts/run.sh before piping it to bash on macOS, because that path fetches whatever is on master at that moment with no checksum. Note that ffmpeg is not a declared dependency. Expect no CLI-only install: the gui extra is empty and the PyQt stack is pinned exactly, so the desktop libraries arrive whether you want them or not. The last push on master was 2026-09-12.
Frequently asked questions
Do I need an API key to use VideoCaptioner?
Not for the free path. The bijian speech recognition engine and bing or google translation are described as needing no configuration and working after install. A key is required only for the LLM stages, subtitle optimization and large-model translation, set with videocaptioner config set llm.api_key <your-key>.
Which speech recognition engines does VideoCaptioner support?
The transcribe command lists faster-whisper, whisper-api, bijian, jianying and whisper-cpp, with bijian and jianying marked free. The declared dependency list contains no faster-whisper or whisper-cpp entry, so the local engines are not installed by the package itself.
Does VideoCaptioner burn subtitles into the video?
Yes. The synthesize command burns a subtitle file into a video as either soft or hard subtitles, for example videocaptioner synthesize video.mp4 -s subtitle.srt. A separate dub command generates a dubbing audio track or a dubbed video from subtitles.
How do I check which VideoCaptioner configuration is in effect?
Run videocaptioner config show to see the merged result. Precedence runs from command line arguments, to VIDEOCAPTIONER_ environment variables, to the configuration file, to defaults, and the config subcommand set also includes path, which reports where the configuration file lives.
What Python versions and operating systems does VideoCaptioner target?
The manifest sets requires-python to >=3.10,<3.13 and the classifiers list 3.10, 3.11 and 3.12, so 3.13 is excluded. The classifiers claim OS Independent, but the documented packaged routes cover a Windows installer from the releases page and a shell script for macOS.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/weifeng2333-videocaptioner)Star history chart for your README
[](https://hysenlabs.com/projects/weifeng2333-videocaptioner)Was this useful?