Track an object you have no model of, and read the caveat about scoring it
[IROS 2021] BundleTrack: 6D Pose Tracking for Novel Objects without Instance or Category-Level 3D Models
At a glance
- What is it?
- BundleTrack is the 2021 robotics conference work for six-degree-of-freedom pose tracking of novel objects without any instance or category-level model, where the practical shape of the repository is two vendored upstream networks, two per-benchmark configuration files, a two-terminal run in which the feature network is started as a local server, and a documented warning that evaluating over a whole benchmark perturbs the initial pose and therefore flatters the numbers.
- Who is it for?
- It fits a robotics researcher who needs pose tracking for an object with no mesh, or who wants a baseline for comparing against it, since the published pose outputs let you plot against the same results without rerunning anything. Three things to know first.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 7 months ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
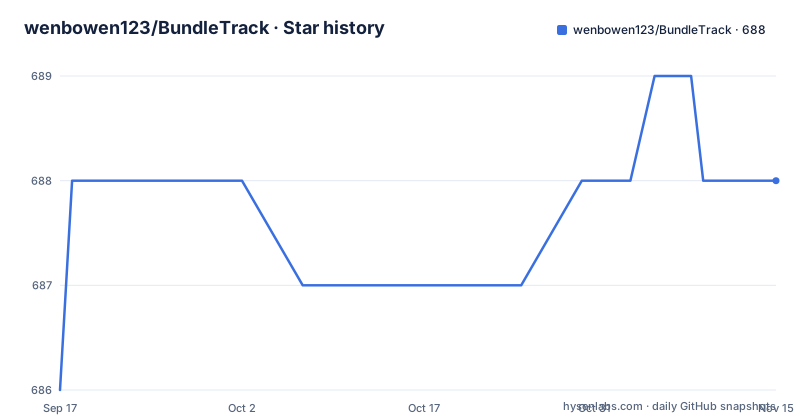
- wenbowen123/BundleTrack688 ★ · +2
| Repository | 2026-09-17 | 2026-11-15 |
|---|---|---|
| wenbowen123/BundleTrack | 686 | 688 |
2 Stars in the last 59 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The premise is that you do not have a model of the object
Nearly every prior method in this area assumes something you often do not have.
The stated assumption is the target object's computer-aided design model, at least at the category level, available either for offline training or during online template matching. If you are tracking an object nobody has modelled, those methods do not apply to you.
BundleTrack removes that requirement entirely. It is a general framework for pose tracking of novel objects with no dependency on a three-dimensional model, at either instance or category level.
What replaces the model is a combination of three things. Recent deep learning advances for segmentation and for feature extraction that holds up under viewpoint change, which supply the observations, and a memory-augmented pose graph optimisation that supplies spatiotemporal consistency across frames. The memory augmentation is what makes low drift over long sequences possible: the optimisation carries information forward rather than treating each frame independently.
The scenarios the paper targets are the ones that break frame-at-a-time methods: significant occlusions, and object motion.
And the performance claim is measured at ten hertz for the entire framework in a CUDA implementation, which is the number that matters if you want to use it rather than cite it.
Two networks are vendored at the repository root
The top-level directory explains the architecture: a source tree, a scripts directory, a docker directory, and two upstream projects sitting alongside them.
One of them is a feature-detection release, and the other is a video-segmentation repository. Both are needed, and both are configured by unpacking a downloaded archive into a specific path inside them.
The feature-detection weights go under the vendored feature directory so that the path resolves to a specific named subdirectory inside it. The segmentation weights go into the vendored video-segmentation directory at its root. And a third download, a set of precomputed masks, is unpacked into the repository itself.
That is three archives to fetch and place correctly before anything runs, and none of it is fetched automatically. The exact destination paths are given for each, which is the difference between a painful setup and an impossible one.
Two consequences follow from vendoring rather than depending on released packages. You get the exact network the paper used, which matters when you are reproducing a number. And you inherit two upstream projects you did not choose, at whatever state the copies are pinned to, with the build and dependency conflicts that implies.
The documentation is upfront about the cost of all this: it strongly recommends the container images and says setting the environment up from scratch is very complicated and not supported in the repository.
Two images, three paths to edit, then a clean build
The setup procedure is short enough to follow in one sitting, and it is deliberately dumb.
Install a container runtime, then pull two images: one for the project and one for the environment of the vendored feature-detection release.
docker pull wenbowen123/bundletrack:latest
docker pull wenbowen123/lf-net-release-env:latest
The documentation's framing is that you do not need to know how containers work, only run a few basic commands.
Then one file to edit. The run script in the docker directory takes three paths: where the project lives, where the first benchmark dataset lives, and where the second one lives. Those three substitutions are the entire configuration step.
Then run that script, which puts you inside the environment.
The last step is the build, and it is a from-scratch compile rather than an install:
rm -rf build && mkdir build && cd build && cmake .. && makeThat pattern looks dated and is a good sign, because it means the build does not depend on stale cache state, which is the most common reason a research repository fails to reproduce on a second machine.
The build system is a plain CMake file at the root. There is no packaging manifest, no lockfile, and no published release, so the build is the only supported path and the container is the only supported environment.
The feature network runs as a server in a second terminal
The run procedure requires two terminals, and the reason is the architecture rather than a quirk.
In the first terminal you start the container for the feature-detection release, change into that project, and launch its server script. It listens on a port.
In the second terminal, the one already running the main project container, you run a prediction script for the dataset, and you pass that same port as an argument:
python scripts/run_nocs.py --nocs_dir [PATH_TO_NOCS] --scene_id 1 --port 5555 --model_name can_arizona_tea_normSo the tracker connects to a feature-extraction server over the local network rather than loading the network in-process.
That has consequences worth understanding. The port argument on both sides is the contract, and if you launch two runs against the same port the second will connect to the first one's server. And because the server is separate, its logs are separate, which is why the documentation says to open a separate terminal rather than chaining the commands.
Output goes to a debug directory named in the configuration file, and the default location is under the system temporary directory. For more detail you raise a log level in the dataset's configuration file rather than adding a command line flag, which is an older style but keeps the run commands identical between datasets.
Two configuration files exist, one per benchmark, and each names its own debug directory, network weights and log level. That is the only structural difference between running on one dataset and the other.
One benchmark needs you to name the object and point at its mesh
The two benchmarks are run with the same scripts and the same two-terminal pattern, but one of them requires per-object configuration that the other does not.
The category-level dataset runs straight from a directory of scenes: you pass the dataset path, a scene identifier, the port, and a model name taken from that scene.
The other benchmark is organised per object, so before running you edit its configuration file to give the object's identifier and the path to its mesh file. The documentation gives a concrete example, which is what makes it usable: for a folder named for one bleach bottle, the identifier is the category name for a bleach cleanser, and the mesh is a specific simplified textured file inside that category's directory in the object model collection.
So the object dataset takes one edit per object and the other takes none. That asymmetry exists because the second benchmark is object-centric by construction, and it is also why the object model collection is a separate download.
The prediction script then takes the data directory, the same port, and the object identifier, so the object name appears twice, once in configuration and once on the command line.
Duplicating an identifier in two places is a small design smell in a research tool. In practice it means a typo in one produces a confusing failure rather than a clear message, so checking both is worth the minute.
Whole-benchmark evaluation perturbs the ground truth, and says so
One note in the documentation is the most valuable paragraph in the repository, and it is about a number you would otherwise trust.
When you evaluate over the entire dataset rather than on the single-scene path shown earlier, the process adds noise in order to perturb the initial ground-truth pose used for evaluation. The paper explains why. And the documentation then tells you that if you want to see how the tracker actually performs, you should run the per-scene section instead.
So the headline benchmark numbers are not produced by the same procedure as the demo. The full-dataset run deliberately disturbs the initialisation, which makes the run tolerant of a bad starting pose, and the consequence is that it measures something slightly different from what a user would experience when the initial pose is accurate.
That is not an admission of a bug. It is a methodological choice, disclosed, with a pointer to which procedure to use for which question. And the per-scene demo is exactly the procedure that matches deployment, where you would initialise from a real detection rather than from a perturbed ground truth.
For a reader comparing this work to others, the distinction is the difference between a number you can quote and a number you can only quote with the caveat. Both versions are in the paper; only one is in the README.
The pose outputs are published for both benchmarks, which is the other thing that makes the comparison possible without rerunning anything.
Ten hertz is a claim about the whole framework, not a stage
The performance sentence is easy to skim and load-bearing when you skim it.
An efficient implementation in CUDA provides real-time performance of ten hertz for the entire framework. The emphasised word is entire. A tracker that runs segmentation at ten hertz and the optimisation loop on another schedule is not a ten-hertz system, and papers frequently report the fast stage.
So the claim covers feature extraction, segmentation, the memory-augmented pose graph optimisation and the output stage, all inside one loop at ten frames per second. That is the number to check against your own hardware before planning around the method.
The comparison claims are stated as two separate things, which is unusual precision. The method significantly outperforms state-of-the-art category-level tracking and dynamic simultaneous localisation methods. And against methods that do use an instance model for a specific object, performance is comparable despite the reduced information requirements.
The second claim is the interesting one. It is the same kind of statement this repository's sibling makes: if you do have a CAD model for your object, use the other implementation. Both papers are by the same author, they cover the two halves of the problem, and the documentation cross-links them rather than competing with them.
The evaluation runs on two public benchmarks, one category-level with real-world scenes and one per-object set with depth, masks and calibration files per object, and results for both are downloadable for plotting.
Editorial conclusion
It fits a robotics researcher who needs pose tracking for an object with no mesh, or who wants a baseline for comparing against it, since the published pose outputs let you plot against the same results without rerunning anything. Three things to know first. Reproducing it means two container images and two vendored upstream networks, and the project says plainly that building the environment from scratch is complicated and unsupported. Evaluation has a documented bias: running over a whole benchmark perturbs the initial ground-truth pose, so the per-scene path is the one that reflects real performance. And if you do have a CAD model for your object, the same author points at a different repository, which is the honest answer rather than a limitation.
Frequently asked questions
What is BundleTrack?
It is the official implementation of a paper accepted at the 2021 International Conference on Intelligent Robots and Systems, licensed Apache-2.0 and written in C++. It performs six-degree-of-freedom pose tracking of novel objects without depending on any three-dimensional model, at either instance or category level, using deep learning for segmentation and for feature extraction that survives viewpoint change, together with memory-augmented pose graph optimisation, and runs at ten hertz for the whole framework in a CUDA implementation.
How do I set up BundleTrack?
With containers. Install a container runtime, pull the project image and the environment image for its vendored feature-detection release, then edit the run script in the docker directory to set three paths for the project and the two benchmark datasets, and run that script. Inside the environment you remove any existing build directory, recreate it, run the CMake generator and compile. Setting the environment up from scratch is described as complicated and unsupported.
Why does running BundleTrack need two terminals?
Because the feature-detection network runs as a separate local server process, and the prediction script connects to it by passing the same port number on both sides. So you start the server script in one terminal and run the prediction script in the terminal already inside the main project container. Reusing the same port for two runs means the second connects to the first server.
What caveat does the BundleTrack documentation give about evaluation?
Evaluating over the entire dataset rather than the single-scene path adds noise in order to perturb the initial ground-truth pose used for evaluation, which the paper explains, and the documentation says that to see how the tracker actually performs you should run the per-scene section. So the full-dataset procedure and the demo procedure are not measuring the same thing.
What networks do I need to download for BundleTrack?
Three archives: the weights of the feature detection network, unpacked into the vendored feature-detection release directory so it resolves to a named subdirectory there; the weights of the video segmentation network, unpacked into the vendored video-segmentation directory at its root; and a set of precomputed masks, unpacked into the repository root. Neither vendored upstream project is fetched automatically, and the exact destination path for each is given.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/wenbowen123-bundletrack)Star history chart for your README
[](https://hysenlabs.com/projects/wenbowen123-bundletrack)Was this useful?