Cactus: A Hybrid Edge-Cloud Inference Engine with Rotation-Based Quantization
Quantization, kernels, runtime and inference engine for mobiles, wearables, smart home and robots.
At a glance
- What is it?
- Cactus is a C++ inference engine for mobile and edge devices that combines a zero-copy computation graph, custom quantization, and automatic cloud handoff. Its accuracy tables and benchmark claims are impressive, but the NOASSERTION license and experimental model conversion warrant careful review.
- Who is it for?
- Adopt Cactus if you need on-device LLM, VLM, and speech inference on Apple or ARM hardware and want a single C API with automatic cloud fallback. Avoid it if you require a standard open-source license, because NOASSERTION means GitHub does not recognise its LICENSE file as a standard licence, so read that file first.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
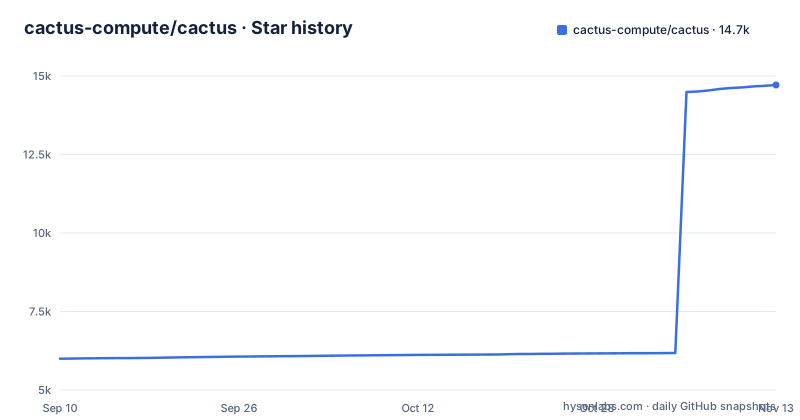
- cactus-compute/cactus14,712 ★ · +8,714
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| cactus-compute/cactus | 6k | 14.7k |
8,714 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Cactus Solves and Who It Targets
Cactus is a hybrid edge-cloud AI engine aimed at mobile devices, wearables, smart home hardware, and robots. The README positions it as a full stack: OpenAI-compatible APIs for text, speech, and vision, a zero-copy computation graph, CPU/GPU kernels tuned for Apple, Samsung, and Pixel chips, and a custom quantization technique called rotation-based quantization. The intended user is a developer building on-device AI features who wants to avoid gluing together separate libraries for model loading, inference, and quantization. The inclusion of a Python package and bindings for Swift, Kotlin, Flutter, React Native, and Rust suggests the project targets cross-platform product teams rather than researchers. A specific use case is tool calling on-device, demonstrated by the Needle model, a 26m parameter model that runs with a simple `cactus run` command and accepts OpenAI function-calling format.
Architecture: Graph, Kernels, and Quants
The repository layout shows three core layers beneath the engine. Cactus Graph is a C++ computation graph that supports tensor operations like matmul, transpose, and input/output handling with precision specifiers. The code example shows a graph where you define inputs with shapes and precision (FP16, INT8), set data, execute, and retrieve outputs. The claim is zero-copy, which would avoid memory duplication between operations. Cactus Kernels provides ARM NEON SIMD kernels for matmul, attention, convolution, quantization, DSP, and image processing. Cactus Quants implements rotation-and-codebook quantization from 4-bit to 1-bit for all weight tensors. The engine layer sits on top, exposing a C API for chat completion, streaming, tool calling, transcription, embeddings, RAG, vision, and cloud handoff. The API returns a JSON response with fields like `cloud_handoff`, `confidence`, `time_to_first_token_ms`, and `decode_tps`, which indicates that the engine tracks performance and confidence internally.
Running Cactus: Commands and Configuration
The README gives concrete commands. On macOS, installation is `brew install cactus-compute/cactus/cactus`, then `cactus run` launches a demo. For model management, `cactus convert [HF-Name]` converts any HuggingFace model, though the README warns this is experimental. Pre-converted models are available on HuggingFace under Cactus-Compute, and `cactus download [HF-Name]` fetches them. `cactus run [HF-Name]` automatically downloads or converts if the model is not found. For tool calling, `cactus run Cactus-Compute/needle --tools my_tools.json` uses an OpenAI-compatible tools file. Benchmarks run with `cactus benchmark` optionally with `--ios` or `--android`. The C API example shows initialization with a weight folder path and a text directory for auto-RAG, then a chat completion call that accepts JSON messages and options like `max_tokens` and `stop_sequences`.
Quantization Accuracy: Where the Trade-offs Bite
The output quality table is the most substantive evidence in the README. It compares Gemma-4-E2B-it across precision levels: F16, CQ4, CQ3.26, CQ2.54, and CQ2. CQ4 holds up well against F16 on tasks like ARC-E (73.73 vs 73.80) and HumanEval even improves (57.11 vs 54.88). CQ3.26 stays close on several benchmarks but drops noticeably on GSM8K (66.20 vs 73.67). CQ2.54 is a cliff: GSM8K falls to 22.00, HumanEval to 15.24, and BFCL Parallel to 30.00. CQ2 is nearly useless for reasoning tasks, with GSM8K at 0.40 and HumanEval at 1.02. This pattern tells you that the lower-bit formats are not drop-in replacements. The README notes that CQ3.26 and CQ2.54 are mixed-precision, meaning different tensors get different bit widths, while CQ2, CQ3, and CQ4 are uniform. If your application involves multi-step reasoning or code generation, stay at CQ4 or higher. The table also shows that accuracy varies by task: WinoGrande stays above 60 even at CQ2.54, but GSM8K collapses. You need to test against your own workloads.
Performance Claims and Their Limits
The README includes a benchmark table for LLM, VLM, and transcription on Apple devices. Numbers like 2964 tokens per second prefill on a Mac M5 Max and 154 tokens per second decode are striking. The table notes these are with 1k-context prefill and decode for 100 tokens, and that no speculative decoding or MTP was used. The VLM column shows image encode times and decode rates, and the transcription column covers 20-second audio. RAM usage peaks between 633MB and 1348MB for the LLM benchmark. These figures come from the maintainers, not from independent testing, so treat them as vendor claims. The benchmark command is available, so you can reproduce them on your own hardware if you have a Mac or iOS/Android device. One limitation is that the table covers only Apple silicon; there are no numbers for Samsung, Pixel, or other ARM chips even though the kernel layer claims support. The absence of Linux or Windows benchmarks means server-side comparison is not possible from the README's table.
Cloud Handoff: A Hybrid Approach with a Confidence Threshold
A distinctive feature is automatic cloud handoff. The response JSON includes `cloud_handoff`, a boolean, and `confidence` with a `confidence_threshold`. The README says the engine routes hard queries to the cloud based on local model confidence. The documentation reference for Cactus Hybrid describes it as a C/Python API that routes based on confidence. This is a pragmatic answer to the accuracy limits of small on-device models. The example response shows a confidence of 0.8193 and a threshold of 0.7, so the query stayed local. If confidence falls below the threshold, the engine presumably sends the request to a cloud model. The trade-off is latency and privacy: you lose the on-device guarantee when handoff occurs. The threshold is model-dependent, which means you must calibrate it per model. If you need to control data egress, confirm which cloud provider and protocol the handoff uses before relying on it.
Model Support and Conversion Risks
The README says any HuggingFace model can be converted with `cactus convert`, but it labels the path experimental. Tested families include Liquid, Gemma, Whisper, Parakeet, and Qwen. Pre-uploaded models are available for download, which suggests the conversion pipeline produces artifacts that the engine expects. The risk is that a model outside the tested families may convert but produce poor results, or fail silently. The Needle model, a 26m parameter tool-calling model, is a specific example of a custom model that works. For speech, Parakeet-TDT-0.6B is listed in the transcription benchmark. The VLM benchmark shows vision is supported, and the Cactus Engine reference lists vision among its features. If your use case is multimodal beyond text and speech, you need to check the docs for vision specifics.
Licensing and Maintenance Considerations
The license field is NOASSERTION, which is a red flag for adoption. It means GitHub could not match the repository's `LICENSE` file to a standard open-source license, so read that file before assuming rights to use, modify, or distribute the code. The project is actively maintained, with the last push on September 26, 2026, and releases v2.2.0, v2.2.1, and v2.2.2 in September 2026. That cadence suggests ongoing development. The README references documentation files like `cactus_engine.md` and `cactus_quants.md`. You would need to clone the repository to inspect them. The bindings for multiple languages indicate a commitment to broad platform support, but each binding adds maintenance burden, and the README does not state which bindings are stable.
Editorial conclusion
Adopt Cactus if you need on-device LLM, VLM, and speech inference on Apple or ARM hardware and want a single C API with automatic cloud fallback. Avoid it if you require a standard open-source license, because NOASSERTION means GitHub does not recognise its LICENSE file as a standard licence, so read that file first. Verify the quantization accuracy on your own tasks, especially below CQ4, and confirm that the experimental `cactus convert` path works for your target HuggingFace model before committing.
Frequently asked questions
How do I install the Cactus engine on a Mac?
Homebrew installs it with brew install cactus-compute/cactus/cactus and the demo starts with cactus run. The quick demo is headed for the Mac, while the Linux route builds from the repository instead.
What does cloud_handoff mean in a Cactus response?
It is set to true when a cloud model was used. The sample also carries a confidence value and a confidence_threshold of 0.7, described as the resolved handoff threshold and model-dependent.
How does Cactus choose a bit width?
Precision is declared per input tensor in Cactus Graph, FP16 for one tensor and INT8 for the next in the sample. The quants cover 4-bit down to 1-bit, with CQ3.26 and CQ2.54 described as mixed-precision.
Which models does Cactus support best?
The README says any HuggingFace model can be converted with cactus convert, though it calls that experimental, and names the Liquid, Gemma, whisper, parakeet, and Qwen families as the most tested.
How does Cactus perform on an iPhone?
The published table lists 729tps prefill and 37tps decode on an iPhone 17 Pro with 644MB peak RAM at 1k context, against 2964tps and 154tps with 1348MB on a Mac M5 Max.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/cactus-compute-cactus)
[](https://hysenlabs.com/projects/cactus-compute-cactus)Star history chart for your README
[](https://hysenlabs.com/projects/cactus-compute-cactus)Was this useful?