Aila wraps twenty-five consumer chatbots in web views, and its last release is from 2024
Aila (AI Super Domain): the premier AI integration tool for Windows, macOS, and Android. Ask once, get answers from 10+ AIs like ChatGPT, Gemini, Claude 3, Copilot, Poe, Perplexity and more. Features customizable AI and prompts.
At a glance
- What is it?
- A .NET MAUI desktop shell that types your question into twenty-five consumer AI websites at once and lines up the answers, where the documented way to add a service is a DOM script that another chatbot generated from one site's HTML, the newest release predates the last commit by two years, and the Windows build needs a certificate installed into the machine.
- Who is it for?
- Aila is worth understanding as an interface over other people's websites rather than as an AI client, because that is exactly what it is: a native shell holding one web view per service, a configuration file naming which services to load, and a prompt you send to all of them at once. The appeal is real for anyone who wants to compare how models answer the same question without twenty-five browser tabs.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 8 days ago.
- What is it written in?
- Mainly C#, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
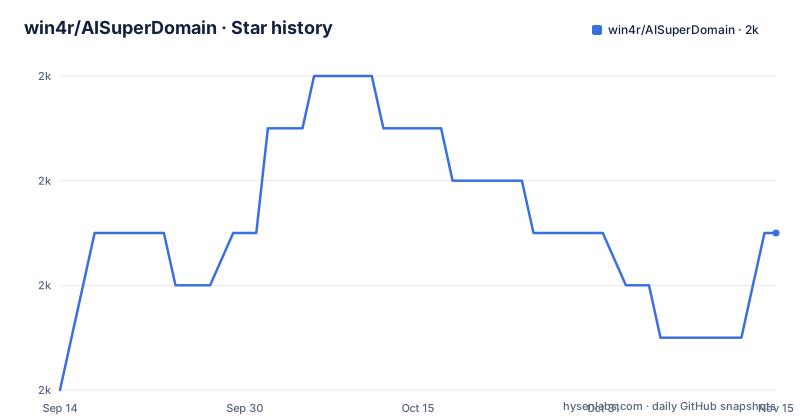
- win4r/AISuperDomain1,997 ★ · +3
| Repository | 2026-09-14 | 2026-11-15 |
|---|---|---|
| win4r/AISuperDomain | 2k | 2k |
3 Stars in the last 62 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The mechanism is typing into a web page, and that decides which services can work
Everything this application does follows from one architectural choice. It does not call an API. It hosts a web view per service and drives the site's own interface, so a question is typed into the page's input element and the reply is read back out of the rendered page.
That is why the supported list is a list of websites rather than a list of models, and it is the single most important fact for anyone evaluating the project. Twenty-five entries are given, including ChatGPT, Gemini, Claude, Copilot, Mistral, Poe, Coze, Perplexity, HuggingChat, YouAI, Grok, ChatGLM, Tongyi Qianwen, DouBao, Wenxin Yiyan and Kimi Chat. Every one of them is a consumer chat interface that a person logs into.
The list also quietly contains things the mechanism cannot reach. An image generator is one row, a music generator is another, and both are described as being driven by a text description or by user input. Neither has the prompt box this technique automates. A third row describes a personal-intelligence assistant that helps you manage personal data securely, which is a product description rather than a chat surface. So the count of twenty-five overstates the coverage by at least three, and the readme does not distinguish between services that can be driven this way and services that cannot.
There is a fourth category in the table that is not a chatbot at all: one row describes a service for experimenting with different models, which is a developer tool rather than a conversation endpoint. Driving it with a script and reading a reply is a different problem from the other twenty-four.
The practical consequence is that the list is aspirational rather than verified. Nothing on the page states which of the twenty-five have working automation today.
The documented way to add a service is a script a chatbot wrote from one site's HTML
There is a section on customising and adding a service, and it is the most revealing thing in the documentation.
The procedure is four steps. Locate the input box for the AI in question. Use the browser's developer tools to inspect the HTML of that input box element. Send the HTML to ChatGPT. Ask ChatGPT to write a generic script.
So the extension mechanism is a script generated by a language model from a page fragment, and the readme is candid about how that was validated: the step is based on the input box of one specific service, which is what allowed ChatGPT to produce a correct and usable script, and a shared conversation is linked as the worked example. The reference implementation is therefore not in this repository. It is a link to a chat transcript.
That single-site origin is the weakness, and the readme states it in the middle of the instruction rather than at the end. A script derived from one site's DOM is applied to twenty-four others by assumption. Every site has a different element structure, a different rich-text editor, a different suggestion overlay, a different way of signalling that a response has finished, and a different rate limit. The part that is genuinely hard, telling that an answer is complete rather than still streaming, is not mentioned anywhere on the page.
The rest of the extension story is a JSON configuration file, reachable from a menu, where you can add models, modify prompts and change the display count. There is no versioning of scripts, no test for them, and no place in the visible tree where a working automation for any service is checked in.
The newest release is from March 2024 and the branch carries four unreleased version plans
The release history is three tags in sixteen days and then nothing. A 0.1 on 2024-03-08, a 1.0 on 2024-03-10, and a 1.1 on 2024-03-24. The last push to the branch is dated 2026-08-09.
That gap is the fact to plan around. The repository is not archived and it has been pushed to within the last two months, so the source tree is current while the downloadable binaries are not. Anyone who follows the documented getting-started instruction, which is to download the latest version from the releases page, gets a build from March 2024 regardless of how active the repository looks.
The tree explains where the time went. At the root there are four files named for versions that do not exist in the release history: `v2.0.txt`, `v2.1.txt`, `v2.2.txt` and `v2.3.txt`. A 2.0 plan sitting in a repository whose newest tag is 1.1 is either a long-running plan or a stalled one, and the readme does not say which. There is also an `update.txt` alongside them.
So the honest reading of the project's state is: the shell, the configuration model and the list of services have all continued to move since 2024, and the packaged artefact has not. Whether that is a packaging backlog, an abandoned release process or a deliberate choice to stop shipping binaries cannot be determined from what is in the repository, and the contributing section, which invites issues and pull requests warmly, does not mention releases at all.
Windows needs .NET 8 and a certificate installed; macOS needs neither
The installation section covers two platforms and the two sets of prerequisites are not comparable.
macOS is described in one sentence: double-click the downloaded file and follow the on-screen instructions. That is the whole procedure.
Windows takes three steps, and the first two are prerequisites rather than installation. The system must already have .NET 8 installed before installation proceeds, so the application is not self-contained. And the provided certificate must be installed before proceeding.
The second prerequisite deserves a sentence of its own, because the readme does not explain what the certificate is for. It is described only as provided, with no statement of what it signs, who issued it, or whether it should end up in the machine's trusted root store. Installing a certificate is an instruction to add a trust anchor to an operating system, and a reader who does that without knowing what they are trusting is doing something the documentation gives them no basis to evaluate. The sensible move is to inspect it first.
The .NET 8 requirement has the opposite property. It is the kind of prerequisite that is tedious but entirely benign, and stating it plainly is better than shipping a build that fails at launch.
Together the two platforms tell you the shape of the release: a Windows build that is framework-dependent and signed with something, and a macOS build that is neither. Neither is unusual, but they are very different trust stories and only one of them is explained.
The description says Android, the installation section covers two platforms
The repository description opens by naming three: a Windows, macOS and Android integration tool. The opening paragraph of the readme narrows it to two, saying the application is designed to run on both Windows and macOS systems. The installation section then covers those two and no others.
That inconsistency is plausible rather than damning, because the project is built on a cross-platform mobile and desktop framework, and the tree does contain a per-platform directory that is where those targets are configured. So an Android build is plausible. What is missing is any statement about it: no download, no store listing, no prerequisites, and no line in the readme beyond the two platforms that are actually covered.
The same pattern shows up in the demonstration link. The demo video is referenced through a URL shortener belonging to a Chinese video platform, under a heading written in Chinese, in an otherwise English document. The link resolves to something rather than to a named, stable page, which means the primary demonstration of the product is one redirect away from disappearing.
The project does localise carefully, which is worth crediting. The English readme is the default and there are five translations alongside it, covering Simplified Chinese, Traditional Chinese, Japanese, Korean and French. Five maintained translations of a readme this size is more localisation effort than most projects of any age spend, and it is the one part of the documentation effort that is unambiguously in good shape.
The declared homepage is a video channel rather than a site, so the project's front door is where its videos live.
You can display one, two, three, four or six answers, and five is missing
The display is configurable, and the set of choices is a fixed list rather than a number. The options are 1, 2, 3, 4 or 6 responses shown simultaneously.
Five is absent from the sequence. With a maximum of six on screen against a list of twenty-five services, the layout cannot be a free choice, and the omissions are the kind that tell you the options were added one at a time as layouts were designed rather than derived from anything.
The consequence for use is the cycling behaviour. There is a button whose stated purpose is easy cycling through the displayed models, which is how a user moves past the first batch to the next. So the workflow for a full comparison is submit, read six, switch, read six more, and so on, which is a different experience from the description's claim of getting answers from more than ten at once.
The rest of the interaction model is small and worth writing down because two characters are reserved. A query beginning with a slash opens a list of prompt suggestions instead of being sent. A query beginning with a hash activates a persistent prompt that stays available. Submission is on a keyboard shortcut or a button. And clicking a model's name in the top right corner opens that single response full screen, with a home button to come back.
There is no cancel, no per-model error state, no retry and no partial result described anywhere. For an application that fans one question out to twenty-five independent services on someone else's website, the failure paths are conspicuously absent from the documentation, and they are where the interesting behaviour would be.
The source lives at the repository root, next to a .DS_Store and three test files
There is no source directory. The project file, the solution file, every page, every code-behind file and the application entry point sit at the top level of the repository, alongside the readme, the licence and the documentation.
Named files at the root include the application shell and its code-behind, a main page, a configuration page and a settings page each with their code-behind, the configuration manager, a web view manager, a type for the current AI, a type for the view count, a prompts file, a configuration file, an application configuration class and a message type for configuration changes. That last group tells you how the settings model works: configuration lives in JSON, a change publishes a message, and the views reconfigure in response.
Mixed in with the source are files that should not be in version control. A macOS Finder metadata file is committed at the root, which is the kind of artefact that appears when the ignore rules miss on one machine. There is a file named simply `note` with no extension. There are three files that look like scratch output: a JSON file, a text file, and a second JSON file named after that text file. And there is a bug log as an HTML file.
None of this is dangerous. It is the shape of a project developed on one machine and pushed without a cleanup pass, and for a repository with no source directory it means every build artefact, note and scratch file shares a namespace with the source. There is also no test project in the root listing, so whatever verification exists is not visible as a directory.
The service descriptions are vendor copy, including one comparative performance claim
The table of supported services has two columns, and the second column is where the care lapses.
Most entries are one-line restatements of how each vendor markets itself. One describes a personal-intelligence assistant that helps you manage personal data securely. Another describes a service for financial analysis and predictions in the fintech sector. Another describes a large language model as an application that facilitates collaboration and teamwork through shared tasks and project management tools, which is a description of a project management product rather than of a language model.
Two entries are different in kind. One claims a language model is comparable to a specific competitor's model in terms of performance, with no benchmark, no version, no date and no source. That is the only comparative performance claim in the whole document, and it is the kind of statement that ends up quoted. The other describes a chat platform as an advanced aggregator for seamless conversations, which is at least accurate about what the aggregator does.
The table also records the age of the list. One row names a model version from 2024 while another names the same product without a version, so the same service occupies two rows. The repository description, separately, names a specific third-party model generation by name and number.
None of this changes what the application does. It does mean the list was assembled from vendor blurbs at one moment and has been extended since without revisiting the descriptions, which is exactly what you would expect of a table whose real function is to be a set of checkboxes in a configuration file rather than a piece of documentation.
Editorial conclusion
Aila is worth understanding as an interface over other people's websites rather than as an AI client, because that is exactly what it is: a native shell holding one web view per service, a configuration file naming which services to load, and a prompt you send to all of them at once. The appeal is real for anyone who wants to compare how models answer the same question without twenty-five browser tabs. Three things to settle first. Check the terms of each service you intend to query, because the application types into consumer web interfaces programmatically rather than using an API, and nothing in the documentation addresses whether that is permitted; that question is yours to answer per service, not per application. Then check the version you are installing, since the newest published release is from March 2024 while the source tree has been pushed as recently as August 2026 and carries four version plans that were never released. And check whether the service you want is one of the ones that can work at all, because the mechanism is a text input box and at least three of the listed services are image or music generators that do not have one. Teams that need a defensible, reproducible way to compare models should look for a client built on documented APIs, since this one automates the front end and offers no audit trail of what was sent where.
Frequently asked questions
How does the Aila desktop app query other AI services?
By driving each service's website. The application hosts a web view per service and types your question into that page's input element, then reads the reply from the rendered page. It does not call an API, so you must be logged in to each service yourself.
How do I add a new AI service to Aila?
The documented procedure is to inspect the target site's input box with browser developer tools, send that HTML to ChatGPT, and ask ChatGPT to write a generic script. The readme says the method was developed against one service's input box and a shared chat transcript is linked as the worked example.
What are the system requirements for Aila?
macOS users double-click the downloaded file and follow the instructions. Windows users must already have .NET 8 installed, and must install the certificate provided with the release before running the installer.
What is the latest version of the Aila desktop app?
The newest published release is 1.1, dated 2024-03-24, following 1.0 and 0.1 earlier that month. The repository has been pushed to more recently, in 2026, and the tree contains planning files for versions 2.0 through 2.3 that have not been released.
How many AI responses can Aila show at once?
One, two, three, four or six simultaneously, chosen in settings. With around twenty-five services configured and a maximum of six on screen, the Switch button is used to cycle through the rest.
Is Aila available for Android?
The repository description names Windows, macOS and Android, while the readme's own introduction says it is designed for Windows and macOS and the installation section covers only those two. No Android download or store listing appears in the documentation.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/win4r-aisuperdomain)Star history chart for your README
[](https://hysenlabs.com/projects/win4r-aisuperdomain)Was this useful?