PDF Patcher: a Windows PDF toolbox that leans on Office 2003 for its OCR
PDF Patcher - a PDF toolbox for editing bookmarks, cropping and rotating pages, removing restrictions, extracting or merging documents, inspecting document structure, extracting images, converting to images, and more.
At a glance
- What is it?
- PDF Patcher edits bookmarks, merges and splits files, replaces fonts and inspects document structure, built on iText and MuPDF in C#. Its text recognition is not its own: it calls Microsoft's MODI component from Office 2003 or 2007.
- Who is it for?
- Adopt PDF Patcher if you work on Windows, need to repair or restructure PDFs with an external tool rather than a browser, and are willing to accept a Windows-only, .NET Framework application with an AGPL licence carrying an added condition.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 9 days ago.
- What is it written in?
- Mainly C#, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
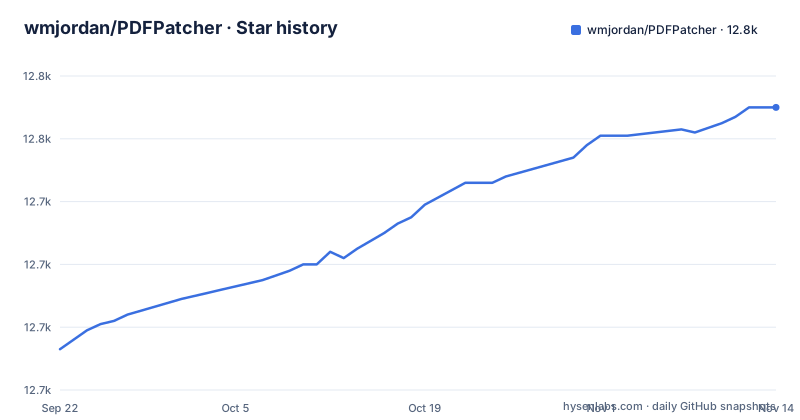
- wmjordan/PDFPatcher12,770 ★ · +77
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| wmjordan/PDFPatcher | 12.7k | 12.8k |
77 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two C libraries do the PDF work, and the choice between them is the architecture
Writing a PDF processor from scratch is described as difficult and unrealistic for most people, so this project leans on two existing libraries and that choice explains most of its behaviour. iText is the .NET component used for parsing, generating and modifying documents and for embedding TTF font subsets, and it is the better of the two at those jobs. MuPDF is written in C and compiled, and its distinguishing advantage is rendering a PDF to a bitmap.
So image conversion goes through MuPDF and everything else goes through iText. The bridge is P/Invoke, the .NET mechanism for calling into native code, and the classes that do it live in a Mupdf subdirectory inside the Processor folder. The native library itself comes from a separate open source project, SharpMuPDF, rather than being built into this repository.
The dependency set around them is worth naming because it tells you what problems are already solved: FreeImage decodes raster images in many formats, Cyotek's ImageBox displays rendered pages, ObjectListView is the list control, HTMLRenderer renders the HTML interface, and TabControlExtra builds the tabbed document UI. Reading the App directory listing, the source splits into Common for utilities, Functions for forms and controls, Lib for third-party components, Model for the higher-level document model, Options for settings, and Processor for the algorithms. The base data model underneath the Model layer is implemented by the iText and MuPDF classes themselves.
Removing copy and print restrictions is a feature with a name, not an accident
One line in the feature list deserves to be read directly rather than skimmed. Among the operations on a document, alongside changing page numbering, unifying page size, deleting actions that auto-open a web page on open, setting the reader's initial view mode, cleaning hidden junk data, recompressing black and white images and rotating pages, there is 去除复制及打印限制: removing copy and print restrictions.
That is permission-flag removal, and it is a mainstream feature of desktop PDF tools rather than an exploit. A PDF carries flags marking whether its content may be copied or printed, and clearing them is the same class of operation as the page rotation next to it in the list. The distinguishing factor between this and a DRM circumvention tool is intent and context: this is one function in a toolbox whose other functions merge files and fix bookmarks.
If you are deploying this somewhere, though, note what that function implies for whoever owns the documents. A tool that clears content restrictions will be applied to documents whose owner set those restrictions, and nobody is going to ask whether the flag was intentional.
The font features sit in the same category of legitimate repair work. Embedding a font into a document removes garbled characters when the text is copied, and it is what makes a document readable on a device such as a Kindle that does not have the original font installed.
Text recognition is not this project's capability, it is a P/Invoke to Microsoft Office
The single hardest external dependency is the text recognition feature, and its cost is easy to miss. Analysing text in the images inside a PDF is done by calling Microsoft's Office image recognition engine, and it requires the Document Imaging component, known as MODI, from Microsoft Office 2003 or Office 2007.
Two consequences follow. The first is deployment: any machine that needs this feature must have that Office component present, which ties a modern machine to an Office version from the previous decade. The second is scope: what this project recognises is bounded by a component Microsoft shipped with those editions and no longer develops, so the recognition behaviour is not something the project controls or can extend.
The feature also covers converting a scanned document's table of contents pages into real PDF bookmarks, and it can write the recognised text back into the PDF. Those are genuinely useful for scanned material, and they are exactly the tasks where a PDF whose pages are images would otherwise be unusable. Which means the value of the feature tracks closely with how common scanned documents are in your work, and the installation cost is fixed regardless.
Nothing else in the toolbox needs Office. That is worth knowing when deciding what to install where: a machine doing only bookmark editing, merging and font embedding has no Office dependency at all.
Bookmark editing has a reading interface, and vertical documents are a first-class case
The bookmark editor is the part of this toolbox with the most unusual design. It is built around a reading interface rather than a property grid, and it includes a right-to-left reading mode for vertical typesetting, which is not a decorative option when the documents being fixed were produced by Chinese publishing pipelines.
Bookmarks can be modified in bulk, covering colour, style, target page and zoom ratio, and each one can be positioned precisely to the middle of a page rather than snapped to the top. There is find-and-replace inside the bookmarks themselves, supporting both regular expressions and XPath matching, with a way to select a chapter or section quickly rather than one entry at a time. Automatic bookmark generation is documented separately.
For documents that arrive without usable bookmarks, generation from the table of contents or from the document structure is often the whole job, and it is the reason OCR can write its results back into the file as bookmarks. The XPath support in the replace function also suggests the bookmark tree is treated as a document structure to query, not merely as a flat list to edit.
Merging carries the same attention. Merged output keeps the original documents' bookmarks, can have new ones added or generated from filenames, and the new entries' text and styling are configurable. Merged documents can also be given a uniform page size so the result prints and reads coherently, which is a practical detail that separates a usable merge from a technically completed one.
The structure tree view is a debugging tool, and it exports to XML
Document analysis is presented as a tree view of the PDF's structure, with nodes that can be edited and modified, and with the whole thing exportable as XML for people who want to analyse or debug the document themselves.
Read the export clause carefully, because it changes what this feature is for. XML output is not a convenience format, it is the interchange point for anyone who wants to work on a PDF's internals outside this application. The stated audience is PDF enthusiasts analysing and debugging documents, which is a different reader from the person editing a bookmark.
Editing nodes directly in the tree view is the stronger claim and the riskier one. A PDF's internal structure is a graph of objects with cross-references, and a change made in a viewer that does not validate the whole object graph can produce a file that opens but is subtly wrong. Since the same feature exports XML for outside analysis, the reasonable workflow is to change in the tool, export, and confirm, rather than to treat the tree view as an oracle.
Image work sits alongside this: lossless export of a PDF's images, conversion of pages to images, and freeimage doing the raster decoding. Naming a file after its own metadata is also in the list, which matters when handling batches where the filename carries no information.
AGPL plus a conscience clause, and the extra conditions are the ones to read
The licence is the most surprising thing about this project and the thing most likely to block an adoption decision. It is AGPL, adopted because the project uses AGPL-licensed third-party components, and then it adds conditions. The project calls this 良心授权, a conscience licence: if the software helps you, you should do one good deed after each use.
The good-deed clause is described as resting on the user's conscience and unenforced, and for most end users that is the honest reading. The part that is not unenforced is condition ④ under the Restrictions definition: if you write other software using this source and earn revenue from it, at least one part in a thousand of that revenue should be donated to disadvantaged groups. That is a real financial obligation attached to commercial use of the code, and it sits on top of the AGPL obligations rather than replacing them.
Three more conditions matter for anyone redistributing. You must supply the complete unmodified version of the software. You must not change the licence. And attaching the software to a commercial product or in promotional material requires the copyright holder's written permission, which is a clause AGPL does not contain.
The repository lists 授权协议.txt at the root alongside 使用手册.docx and 更新历史.txt, and the project's own instruction is to read the licence text before using the software or the source. Note also that the licence metadata for this repository is unresolved, so automated tooling will not tell you what terms apply here.
Windows 7, .NET Framework 4.x, and a Visual Studio build that needs two workloads
The runtime requirements are narrow in a way that rules the project out of a lot of deployments. It runs on Windows 7 and above, on .NET Framework 4.0 through 4.8. There is no .NET Core or modern .NET target mentioned anywhere, which means it is not cross-platform and is tied to the framework that shipped with Windows itself.
Building from source is a second-narrow requirement. Visual Studio 2022 or newer is recommended, with two workloads installed: .NET desktop development for the application, and C++ desktop development for the JBIG2 encoding component. The project warns that you will probably hit a message saying the project targets an unsupported .NET Framework and asking you to retarget it, with .NET Framework 4.8 given as the simple fix and a linked article covering the alternative if you would rather not change the target.
That warning is informative about the current state. The default branch is named v1.2 while the newest release tag is v1.1 from 2025-02-01, preceded by v1.0.4 in September 2024 and v1.0.2 in June 2024. The repository is not archived and the last push was on 2026-10-23, so work is continuing, but the tags show a slow release cadence against a codebase that still expects developers to retarget a legacy framework.
The distribution channels are the GitHub repository and a Gitee mirror. Bug reports go through issues on the open source site, the author states that QQ and WeChat consultation is not offered, and attachments are asked to stay under 10M, with a note to extract representative pages rather than sending the whole file.
Editorial conclusion
Adopt PDF Patcher if you work on Windows, need to repair or restructure PDFs with an external tool rather than a browser, and are willing to accept a Windows-only, .NET Framework application with an AGPL licence carrying an added condition. Skip it if you need a maintained cross-platform workflow, if you are on macOS or Linux, or if Office 2003 or 2007 is not available anywhere in your environment, because the text recognition feature is delegated to a Microsoft component that shipped with those Office versions. Before depending on it, confirm the .NET Framework version on the machine you must run it on, and read 授权协议.txt rather than the summary, because the redistribution conditions are not the ones AGPL alone would impose.
Frequently asked questions
What is PDF Patcher used for?
PDF Patcher is a Windows PDF processing tool for editing bookmarks, merging and splitting files, replacing and embedding fonts, rotating and resizing pages, converting pages to images, and inspecting or editing document structure. It is written in C# on the iText and MuPDF libraries.
Does PDF Patcher need Microsoft Office installed?
Only for its text recognition feature. Analysing text inside PDF images is delegated to Microsoft's Document Imaging component, known as MODI, from Microsoft Office 2003 or Office 2007. Every other feature, including bookmark editing, merging and font embedding, carries no Office dependency.
Can PDF Patcher be used commercially?
The software is free for end users and the source is available under AGPL with added conditions. Using the source to write other software is allowed, but condition ④ under the licence's Restrictions definition requires donating at least one part in a thousand of any resulting sales revenue to disadvantaged groups, and attaching the software to a commercial product or in promotional material requires the copyright holder's written permission.
Which platforms does PDF Patcher run on?
Windows 7 and above, on .NET Framework 4.0 through 4.8. No cross-platform or modern .NET target is described. Building the source additionally needs Visual Studio 2022 or newer with both the .NET desktop development and C++ desktop development workloads, the latter for the JBIG2 encoding component.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/wmjordan-pdfpatcher)Star history chart for your README
[](https://hysenlabs.com/projects/wmjordan-pdfpatcher)Was this useful?