AutoBE builds a backend from ASTs, not from prompts alone
AI Vibe Coding Agent of TS backend server, enhanced by compiler skills, generating 100% working code
At a glance
- What is it?
- A waterfall pipeline of forty-plus agents that turns a natural-language requirement into a TypeScript and Prisma backend, with the unusual constraint that each stage validates a language-neutral syntax tree before any code is written. The claims are strong and the tooling around them is scrappy: a shallow clone in the install guide, three overlapping linters, and a README that a release script rewrites.
- Who is it for?
- AutoBE suits someone who wants a scaffolded backend in an afternoon and plans to hand it to an assistant afterwards, since the README is explicit that the generated application is meant to be extended with tools like Claude Code. Two things to weigh.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 144 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on October 6, 2026, and from our analysis. They are not legal advice.
Star history
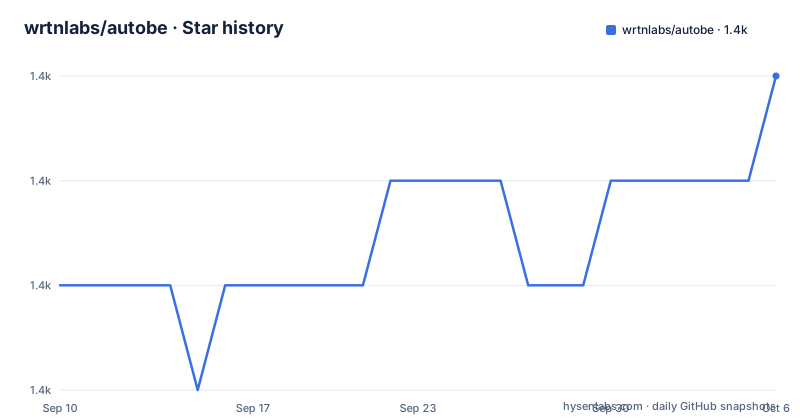
- wrtnlabs/autobe1,362 ★ · +2
| Repository | 2026-09-10 | 2026-10-06 |
|---|---|---|
| wrtnlabs/autobe | 1.4k | 1.4k |
2 Stars in the last 26 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
ASTs first, and a compiler that checks them
The differentiating idea is stated in one paragraph of the README and it is worth reading closely. AutoBE follows a waterfall methodology with more than forty specialised agents, one set per phase. Each waterfall stage includes AI-friendly compilers intended to guarantee type safety in the generated code.
The mechanism is that the agents do not write code directly. They first construct language-neutral Abstract Syntax Trees using predefined schemas, and every AST node is validated against type rules before any code generation happens. Structural errors are therefore caught at the conceptual level rather than surfacing during compilation.
That distinction matters more than it first appears. Most code-generating agents produce text and then hope it parses, which means a structural mistake is discovered by a compiler after the fact and costs a round trip. Validating an AST against a schema first turns a whole class of failures into something the pipeline catches while it is still cheap to fix.
The five named functional agents follow the stages you would expect: requirements analysis, database design from an entity relationship diagram, API design, test code generation, and the main program. A facade controller sits above them and dispatches. The generated stack is TypeScript with Prisma as the ORM inside NestJS, which is why the manifest installs a patched TypeScript compiler.
Buildable is not the same as working
The repository description says the tool generates 100% working code. The README makes a narrower claim, and the difference is the thing to hold on to.
The README says the generated application is designed to be 100% buildable by AI-friendly compilers, and that stability comes from end-to-end test functions. Later it says the approach is designed to ensure the final generated TypeScript and Prisma code is 100% buildable, and that based on testing with multiple example projects including e-commerce platforms, discussion boards and task management systems, this compilation guarantee is maintained across application types.
So the promise is that the project compiles. Stability is a separate property attributed to the generated tests. Those are different claims, and the description's version is the broader of the two.
The evidence base is also worth naming precisely: a handful of example applications, which the README then lists. Four exist in a separate repository, a to-do list, a Reddit community clone, an e-commerce store and an ERP system. All four sit under a path segment naming one specific model, so every published example was generated by the same model rather than by the best available one. The ERP example is documented in the most detail, with links to its analysis report, its entity relationship diagram and Prisma schema, its controllers and DTO structures, its end-to-end test functions, and its implementations.
The generated layout is worth a glance too. Tests land in a features directory and implementations in a providers directory, which is not the controllers-and-services shape most NestJS code uses.
The install guide starts with a shallow clone
Getting started is three commands, and the first one contains a decision worth understanding:
git clone https://github.com/wrtnlabs/autobe --depth=1
cd autobe
pnpm install
pnpm run playground
The depth flag makes it a shallow clone, which fetches one commit's worth of history instead of the whole repository. That is the right trade for a quick evaluation: the clone is much smaller and much faster, and most people running the playground do not need the history.
It is the wrong trade if you plan to contribute, and it produces confusing behaviour if you do. A shallow clone has no parent commits, so blame points at the boundary commit, bisect cannot walk history, and fetching later needs an explicit unshallow step that the command does not mention. Since this is a monorepo with a development community and a contribution guide, that mismatch shows up.
The third command runs the playground, which is a local application rather than a hosted service. You chat with the agents at localhost port 5173, you can manage multiple sessions, and you supply the model access yourself, with local models named as an option. Nothing is submitted to a hosted endpoint unless you point it at one.
A release script rewrites the README
The root package manifest contains a release script, and it is worth reading what the release does before it bumps a version: it synchronises the README, synchronises dependencies, and then bumps versions recursively across the workspace.
The README synchronisation is run by a script under the deploy directory. That is the explanation for a class of drift visible in the current file. The licence badge near the top points at a blob path on the master branch while the default branch is main, so the badge resolves to nothing, while a link inside the architecture diagram points at the main branch correctly. A generated section and a hand-written section are sitting in the same document with different assumptions about what the default branch is called.
Dependency synchronisation running as part of release is the same idea applied to versions: a central catalog holds the shared versions and a script propagates them, which is why the manifest uses the catalog protocol for TypeScript and Prisma rather than pinning numbers in every package.
So treat the README as partly machine-written. It is not wrong so much as assembled, and the parts to trust are the ones describing behaviour rather than the parts describing navigation.
Three linters, one of them pinned exactly
The tooling configuration is a good example of a project that grew rather than was designed. There are three separate lint and format configurations at the root: a Biome configuration, an ESLint configuration, and a Prettier configuration. The lint script runs both Biome and ESLint, while format and the format check run Prettier over TypeScript files.
Running two linters over the same code means every rule exists twice or the two are configured to cover different ground, and with no documentation of which is which, a contributor adding a rule has to guess. Biome is pinned to an exact version while almost everything else in the manifest uses a caret range, which suggests Biome is treated as the load-bearing one and ESLint as the incumbent.
Two other entries are worth noting. The prepare script installs a patched TypeScript compiler, which is the standard way to get transformer support for decorators that NestJS relies on. And there is a separate script named estimate that shells out to a benchmark runner inside a package of the same name, which is how cost or token estimation is kept out of the main build.
The version management is thorough: a recursive version bumper, a separate next-channel publish path driven by a shell script, and a publish command that tags the latest channel explicitly.
A Korean job description sits in the repository root
The top-level listing has a few entries that do not belong in an open-source project, and one of them is a file called JOB-DESCRIPTION-KR.md sitting next to PLAN.md, the licence and the readme. It is a Korean-language job description, committed to the repository root.
Its presence tells you something about how the work is organised. The author field in the manifest is a company rather than a person, and the project is developed under that company, so a job posting landing in the root is consistent with a corporate repository where the working directory doubles as the company's own scratch space.
It is also a small sign that the repository is not curated the way a community-facing repository usually is. The root also carries a directory named .ai alongside .claude and .vscode, a plan document, a script named next.bash, a deploy directory, an internals directory and a website directory. Several of those are entirely reasonable. The job description is the one that stands out, because it is a document with an audience outside the codebase.
None of this affects whether the tool works. It affects how much of the tree is documentation you can act on, and the practical advice is to read the official site rather than treating the repository as the reference.
Five turns, forty agents, and a replay viewer
The example conversation the README gives is a useful picture of how the thing is driven, because it is five short requests. You ask for a requirements analysis report for an economic and political discussion board, explicitly saying you are not familiar with programming and asking the agent to write it as it sees fit. Then you ask for the database schema, then the API interface specification, then the end-to-end test functions, then the implementation.
Five turns, each mapping to one waterfall stage. The middle steps are the ones that matter, because the design puts the schema and the API contract before any implementation, which is what makes the AST validation stage possible at all.
There is one feature in the README that is more useful for judging the tool than any of the claims: a replay viewer. It is reachable inside the playground and it shows chat sessions from the development team's own testing and benchmarks. That means you can read transcripts of real runs, including the prompts and the agent responses, before committing your own requirement to it.
It also means the benchmark sessions are public, which puts a constraint on the roadmap. The release phases listed are alpha, beta and gamma, all marked done, with delta active, and the published package version sits at 0.31.x. A pre-1.0 tool with public transcripts is worth evaluating on those transcripts rather than on the description.
Editorial conclusion
AutoBE suits someone who wants a scaffolded backend in an afternoon and plans to hand it to an assistant afterwards, since the README is explicit that the generated application is meant to be extended with tools like Claude Code. Two things to weigh. The guarantee is that generated code builds, which is not the same as that it works, and the evidence offered for it is a handful of example projects. And the install path is a local playground that needs your own model access, not a hosted product, so you are running the pipeline yourself rather than submitting your requirements to a service.
Frequently asked questions
How does AutoBE differ from Claude Code for building a backend?
AutoBE is positioned as the step that builds a backend application quickly, after which you maintain and extend it with AI code assistants like Claude Code. The README frames the two as sequential rather than competing: scaffold first, then iterate with an assistant.
What does AutoBE actually guarantee about generated code?
The README says the generated TypeScript and Prisma code is 100% buildable, with stability attributed separately to generated end-to-end test functions. The evidence given is testing across multiple example projects including e-commerce platforms, discussion boards and task management systems.
How do I run AutoBE locally?
Clone the repository, install with pnpm, and run the playground script. The chat interface is then available on port 5173, where you can manage multiple sessions and bring your own model provider, including local models.
Why does the AutoBE install guide use a shallow clone?
The clone command passes a depth flag, which fetches a single commit instead of full history to make the download fast. That suits evaluation but leaves no parent commits, so blame, bisect and later fetching need extra steps if you intend to contribute.
Can I see real AutoBE runs before trying it?
Yes. The playground includes a replay page where you can view chat sessions from the AutoBE development team's testing and benchmarks, which shows real prompts and agent responses rather than a demo.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/wrtnlabs-autobe)Star history chart for your README
[](https://hysenlabs.com/projects/wrtnlabs-autobe)Was this useful?