bm25s: BM25 with the scores computed up front
Fast BM25 search in Python, powered by Numpy and Numba
At a glance
- What is it?
- xhluca/bm25s is a pure Python BM25 implementation that precomputes token scores into sparse matrices so query time is a lookup. The speedup claim points at a separate benchmark repository, the numba backend that adds roughly twice the speed is optional, and retrieval is position based, which makes corpus order part of the contract.
- Who is it for?
- bm25s fits batch retrieval where you want BM25 without Elasticsearch, without PyTorch and without a Java process, and where the corpus is fixed enough that paying for index construction once is worth it. It does not fit a case where document scores must change per request, since eager scoring is the design.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
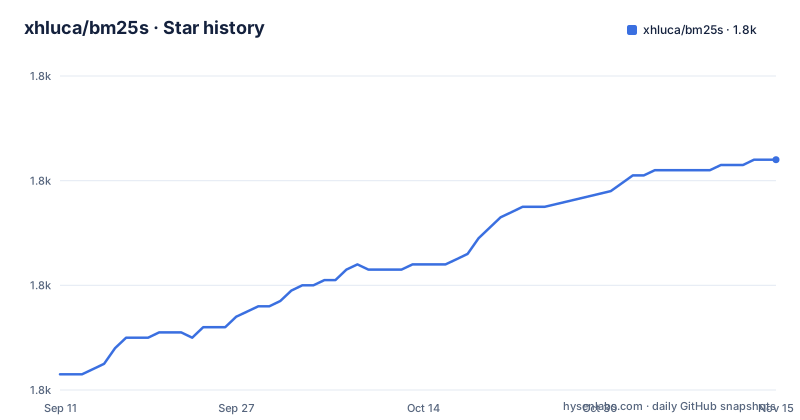
- xhluca/bm25s1,824 ★ · +41
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| xhluca/bm25s | 1.8k | 1.8k |
41 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Eager scoring turns the query into a lookup
The library is BM25S, also written BM25-Sparse, and the design choice is in the name. Rather than walking documents and accumulating scores when a query arrives, bm25s computes the score contributions for all document tokens ahead of time and stores them in sparse matrices, so scoring a query means reading precomputed values. The stated payoff is scoring at query time without per-document Python work, which the README claims beats popular libraries by orders of magnitude. It makes no dependency on Java or on PyTorch: NumPy is what it needs, with optional extras for stemming and for JIT compilation. The comparison it offers is a speedup over rank-bm25, described as the most popular Python implementation of BM25, measured as queries per second on a few BEIR datasets in a single threaded setting, with Elasticsearch mentioned as the other point of reference. The tables themselves are not in this README; they live in a separate bm25-benchmarks repository, and the technical write-up is an arXiv paper on eager sparse scoring.
The numba backend is where the extra speed lives, and it is optional
Version 0.2.0 is called out in the README as the release that started rolling out a numba backend, with a claimed speedup of around two times for larger datasets. Two things follow from that note. First, the headline speed is not the default: the baseline implementation is pure Python on NumPy, and numba compilation is something you opt into. Second, the packages are split accordingly. A plain install is one command:
pip install bm25sThe extras exist as three named variants, and the README is direct about which one to take. `bm25s[core]` is marked highly recommended and covers JSON loading, the progress bar, stemming and JIT compilation, so an install without it will miss pieces the library itself expects. A stemmer on its own can be added separately with `pip install PyStemmer`, and `bm25s[full]` pulls every extra. The examples directory carries a script for tokenising with multiprocessing and another for using an NLTK stemmer instead, so the optional surface is documented by example rather than by a table of extras.
Retrieval is position based, so corpus order is part of the contract
The corpus format section is the part of this documentation worth reading twice, because the API separates what you index from what you get back. You pass strings to `bm25s.tokenize()` and the resulting tokens to `retriever.index()`. The optional `corpus` argument on `BM25(...)`, `retrieve(...)` and `save(...)` is simply the list of values returned for matching document IDs, and it may hold plain strings or dictionaries with any shape, since dictionaries have no required keys. Because retrieval is position based, `corpus[i]` comes back for document ID `i`. That is the whole mechanism, and it is also the trap: the corpus you pass has to be the same order and the same length as what you indexed, and a reordered list will return confident, well formed metadata attached to the wrong document. Saving follows the same rule, since entries must be strings, dictionaries, lists or tuples that serialise to JSON, with string entries written to `corpus.jsonl` as `{"id": i, "text": doc}` while other shapes are stored as provided.
The version number comes from a tag, an environment variable, or nothing at all
There is a setup.py at the root and no pyproject.toml, and the visible part of that file is not packaging metadata but version plumbing. It reads, in order, an environment variable named BM25S_VERSION, then RELEASE_TAG, then, when the ref type is a tag, the ref name, then a GITHUB_REF that starts with refs/tags/. Failing all of those it parses a Version: line out of a PKG-INFO file in the package directory, and failing that it shells out to `git describe --tags` with two match patterns, one for tags beginning with a digit and one for tags beginning with v. A helper strips a refs/tags/ prefix and a leading v before comparing. The practical consequence is that there is no literal version string in the file: a source checkout without tags and without the relevant environment variables has no version to report, which is normal for CI driven publishing but means local installs can carry a version you did not choose.
The quickstart stops on a half typed line, and a second example finishes the job
The first code block shows a four document corpus, an optional English stemmer, tokenisation with stopwords and the stemmer, then a retriever. Its last line is `retriev`, a partial word, so the call that indexes and searches is not completed inside that block. The corpus format section immediately after it does show the shape in full, with a retriever constructed against a metadata corpus and then indexed. The higher level module is the tidier entry point for one-off work, and it handles the file plumbing itself:
import bm25s.high_level as bm25

# Load a file (csv, json, jsonl, txt)
# For csv/jsonl, you can specify the column/key to use as document text
corpus = bm25.load("tests/data/dummy.csv", document_column="text")
# Index the corpus
retriever = bm25.index(corpus)

# Search
results = retriever.search(["your query here"], k=5)
for result in results[0]:
    print(result)
The terminal path mirrors it, with `bm25 index documents.csv -o my_index` using the first column by default, `-c text` naming a column instead, and a text file treated as one document per line.
The README points beginners at a different package on PyPI
One note in the documentation is easy to skim past and important if you are new to this. The project now recommends the BM25 package published on PyPI for a simpler, beginner friendly experience, stating that it includes all the necessary dependencies, stemming and a CLI among them, and that it provides the same high level API. So there are two distributions: bm25s, which is the lean one you assemble yourself from extras, and BM25, which bundles the conveniences. The same tension runs through the install section, where the base package is one command but the recommended variant is a second command with a quoted extra. Neither choice is hidden, and the API is the same, but it does mean the name you pip install is not obviously the name of the project whose repository you are reading.
Sixteen examples, including a multiprocess tokenizer and an MCP server
The examples directory does more work than the prose documentation does, and its shape hints at what people actually use this for. There is an evaluation script for the BEIR benchmarks, a Natural Questions script that indexes two million documents, several numba variants marked advanced, one that reaches Hugging Face datasets and one that loads from it, a script for indexing with metadata, a save and reload end to end script, a plain simple load example, a tokenizer class example, an NLTK stemmer alternative, a multiprocess tokeniser, and a directory named mcp containing a server example. Scale is treated as a first class concern rather than a footnote, with batching and multiprocessing each getting their own file. The repository also carries a CITATION.cff and points at the arXiv paper, BM25S: Orders of magnitude faster lexical search via eager sparse scoring, authored by Xing Han Lù, and the project is MIT licensed with its last recorded push on 2026-10-01.
Editorial conclusion
bm25s fits batch retrieval where you want BM25 without Elasticsearch, without PyTorch and without a Java process, and where the corpus is fixed enough that paying for index construction once is worth it. It does not fit a case where document scores must change per request, since eager scoring is the design. Before you adopt it, check four things. That you install the extras you actually need, because the base package omits JSON loading, the progress bar, stemming and JIT compilation. That your corpus order survives the round trip, since retrieval is positional and nothing in the API stops you from passing a reordered list. Where the performance numbers come from, because the README states orders of magnitude without printing a table and points at a separate repository. And which distribution you install, since the project itself recommends a differently named package on PyPI for anyone who wants the dependencies included by default.
Frequently asked questions
What is bm25s and how does it differ from plain BM25?
It is a pure Python implementation of the BM25 ranking function that stores eagerly computed scores for all document tokens in sparse matrices, so scoring at query time reads precomputed values instead of walking every document. It depends on NumPy, with no Java or PyTorch dependency, and takes optional extras for stemming and numba compilation.
How do I install bm25s with stemming and speedups?
With `pip install "bm25s[core]"` for the recommended set covering JSON loading, the progress bar, stemming and JIT compilation, `pip install PyStemmer` if you only want a stemmer, or `pip install "bm25s[full]"` for every extra. The numba backend that gives roughly twice the speed on larger datasets arrived in version 0.2.0.
Can I attach my own metadata to documents in bm25s?
Yes. The optional `corpus` argument on BM25, retrieve and save takes the values returned for matching document IDs, and dictionaries are valid entries with no required keys. Retrieval is position based, so `corpus[i]` comes back for document ID `i`, which means the corpus must be kept in the same order and length as what you indexed.
Does bm25s need Elasticsearch or a service to run?
No. It is a library, and its own comparison names Elasticsearch as a reference point while stating the project has no dependency on Java or on PyTorch. It also ships a terminal interface, with `bm25 index documents.csv -o my_index` using the first column by default and `-c text` to name a column.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/xhluca-bm25s)Star history chart for your README
[](https://hysenlabs.com/projects/xhluca-bm25s)Was this useful?