MTranServer runs offline translation on port 8989, and the first request is where it surprises you
Offline translation model server with low resource consumption, fast speed, and private deployment capability.
At a glance
- What is it?
- A local translation server built around small models, packaged as a desktop app, an npm command and a container, with compatibility routes for existing translation clients. It trades output quality for latency on your own hardware, and its default posture is an unauthenticated listener on every interface.
- Who is it for?
- Adopt MTranServer when you need repeated translation on your own machine, or on an internal network, and can accept output quality below what a large model gives you. Before you expose it anywhere, set MT_API_TOKEN and narrow the listen host, and preload language pairs with the download flag instead of letting the first request pull a model.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
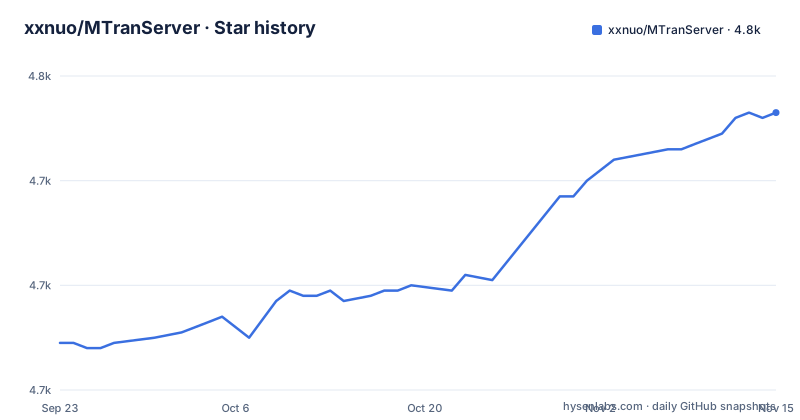
Star history
- xxnuo/MTranServer4,753 ★ · +44
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| xxnuo/MTranServer | 4.7k | 4.8k |
44 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One process, one port, no graphics card
MTranServer is a local translation server whose stated design goals are offline translation, response speed, cross-platform deployment and running on your own machine, with no graphics card required. The README attaches numbers to the speed goal: in its v5 ONNX benchmark on CPU with caching off, English to Chinese short sentences averaged 11.5 ms with one concurrent request. For developers who do not want a permanent install, the shortest path is a single command:
npx mtranserver@latestThat pulls the package from the npm registry and runs it in place. The same note says npx can be replaced with whichever package runner you prefer, such as bunx or pnpx, so nothing here is tied to npm. Read the quality admission near the top of the README, because it is the tradeoff the whole design rests on: the service is meant for everyday reading and getting the gist, results may contain errors, and important content should be checked against the original.
Four ways to start it, each with a different maintenance burden
There are four documented launch paths, and they differ in what you keep on your own machine. The desktop build is the one-click option, with packages for Windows, Mac and Linux; once launched it creates a tray menu for managing the service, and the application carries its own simple UI address along with online debugging documentation. For a permanent command line install:
npm i -g mtranserver@latestAfter that you start it by running `mtranserver`, and npm can equally be swapped for bun or pnpm. The container path assumes an empty directory holding a compose.yml:
services:
  mtranserver:
    image: xxnuo/mtranserver:latest
    container_name: mtranserver
    restart: unless-stopped
    ports:
      - "8989:8989"
    environment:
      - MT_HOST=0.0.0.0
      - MT_PORT=8989
      - MT_OFFLINE=false
      # - MT_API_TOKEN=your_secret_token_here
    volumes:
- ./models:/app/modelsdocker pull xxnuo/mtranserver:latest
docker compose up -dThe compose file kept in the repository root carries more than the snippet above: it also sets MT_ENABLE_UI=true and adds a healthcheck that uses node to fetch http://localhost:8989/health every 30 seconds with a 3 second timeout, 3 retries and a 5 second start period. Both routes listen on 8989 by default, so the port is the one number to change first if something else already owns it.
Models are not in the package, they arrive on first translation
The behavior that catches out first time users is that the translation models are not shipped with the code. On the first translation of a language pair the server downloads the matching model automatically, and how long that takes depends on your network speed and the size of the model. Unless offline mode is on, that download can land in the middle of somebody's first request. The fix is to do it deliberately before anything depends on the server, because the millisecond level speed claim only applies to a request whose model is already downloaded and loaded. Two flags cover the preload:
--download en_zh zh_en              下载并准备指定翻译方向
--languages [filter]                列出可下载的翻译方向
The documentation also suggests running one translation before real use so the server downloads and loads models ahead of time. Offline mode is the deliberate opposite choice: it disables automatic model downloads, which is what you want on a machine with no outbound network, and it means every language pair must already exist in the model directory.
Every flag has an environment twin, and the defaults bind wide open
Each command line flag has a matching environment variable, which is how the container and desktop paths work without rewriting arguments. The defaults deserve attention before the port is reachable. The listen address defaults to 0.0.0.0 and the port to 8989, and the compose file turns the web UI on and offline mode off. The worker idle timeout, after which the translation engine is released, defaults to 60 seconds, and the cache keeps the most recent 1000 results by default. In the compose setup the model directory is /app/models and the configuration directory is /root/.config/mtran/server.
The consequence is visible in the compose file, where authentication is a commented out line reading MT_API_TOKEN=your_secret_token_here. Leave that line commented and the host at 0.0.0.0 and you have a translation server answering on every interface with no token check, reachable by anything that can open port 8989 on that machine. On a laptop that is a local network exposure rather than a public one, but on a shared box or a tunnel it is open service. Set the token and narrow the host before this runs anywhere other than your own desktop.
Client routes are named after the clients, and each one authenticates differently
Pointing an existing translation client at the server is the point of the compatibility routes, and they are named after the clients rather than after any internal API. POST /imme maps to the immersive translation plugin, POST /kiss to the simple translation plugin, POST /deepl to a DeepL API v2 compatible shape, POST /deeplx to the DeepLX shape, and POST /hcfy to the selection translation plugin. The same table carries two further routes that mirror the request shapes used by web translation clients, one POST and one GET.
Authentication is not uniform across them, which is where a misconfigured client usually shows up. Several routes read the token from the query string, for example http://localhost:8989/imme?token=your_token, where the token tail is replaced with your own MT_API_TOKEN value. The DeepL compatible route accepts either a DeepL-Auth-Key header or Bearer authentication, and the DeepLX and selection translation routes accept a token parameter or Bearer. For request rate and concurrency, the README advises keeping each plugin's defaults at first and lowering them if translations time out or the computer is overloaded.
The npm package is a command and a library at once
The repository layout shows which pieces belong to the server and which belong to the desktop build. package.json marks the package as an ES module with dist/index.js as its main entry, dist/index.d.ts as its types, and a bin entry pointing at dist/main.js, so a single install gives you both an executable and an importable module. The keyword list includes wasm and onnx alongside translation and translation-server, and the documented way to call translation from another program is through those TypeScript type definitions. An example/ directory holds usage.ts with its own README, API.md documents the HTTP side, and tsoa.json drives generated API documentation.
Three more root entries matter outside npm. install.sh and uninstall.sh sit beside mtranserver.service for a system level install, and a deprecated/ directory stays in the tree for retired code paths. The container build is a two stage Dockerfile: it installs with bun install --frozen-lockfile inside an oven/bun:1 builder, runs bun run build:node, then copies the built dist into node:22-bookworm-slim with EXPOSE 8989 and CMD ["node", "main.js"]. Development scripts build with bun and then run node, for example bun run build:node && node dist/main.js --log-level debug --port 8990 --model-dir ~/.config/mtran/models.
Ecosystem status and the two limits stated outright
The surrounding projects show how much of the plan is real. MTranCode is an IDE plugin that translates code comments, published for the VS Code family of editors including VS Code, Cursor and Augment, and installable from the plugin store by searching for its name. It calls the server at http://localhost:8989 by default and that endpoint can be changed in settings, and it is a fork of an existing comment translation extension, which tells you its feature set started somewhere else. MTranBrowser is listed with a TODO and a note that work on it is under way, so treat that browser extension as not there yet.
Two limits are stated outright. The README says the service suits everyday reading and getting the gist, with results that may contain errors and should be checked against the original for important content, and that v5 does not yet offer a single-file server executable. On timing, the last push landed on 2026-10-19, after v5.1.0 and v5.0.1 both shipped on 2026-10-16 and v4.0.33 on 2026-03-08, and v5 is described as using a new translation engine with much better performance. One honest detail from the scripts: the lint entry is literally echo 'No linter configured'.
Editorial conclusion
Adopt MTranServer when you need repeated translation on your own machine, or on an internal network, and can accept output quality below what a large model gives you. Before you expose it anywhere, set MT_API_TOKEN and narrow the listen host, and preload language pairs with the download flag instead of letting the first request pull a model. Pick an online large model API instead when translation fidelity matters more than latency or privacy.
Frequently asked questions
How do I start MTranServer without a permanent install?
Run npx mtranserver@latest. The README notes npx can be swapped for another package runner such as bunx or pnpx, and that npm i -g mtranserver@latest followed by running mtranserver is the permanent alternative.
Does MTranServer need a graphics card to translate?
No graphics card is required. The container image builds on an oven/bun:1 stage and ships a node:22-bookworm-slim runtime that exposes port 8989, and the design goals include offline translation and low resource use on your own machine.
How do I preload translation models instead of waiting on the first request?
Use the download flag with pairs such as --download en_zh zh_en, and use --languages to list every pair available for download. If you do nothing, the first translation of a pair triggers the download unless offline mode is enabled.
How do I protect the MTranServer API from other machines on the network?
Set MT_API_TOKEN, which appears as a commented out line in the compose file, and clients pass it as a token query parameter or Bearer credential. The listen host defaults to 0.0.0.0, so narrow it with MT_HOST if the server should not answer on every interface.
Which translation clients can talk to MTranServer?
The compatibility routes cover the immersive translation plugin at /imme, the simple translation plugin at /kiss, a DeepL API v2 compatible shape at /deepl, the DeepLX shape at /deeplx and the selection translation plugin at /hcfy, plus two routes mirroring web translation client requests.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/xxnuo-mtranserver)Star history chart for your README
[](https://hysenlabs.com/projects/xxnuo-mtranserver)Was this useful?