GLM-TTS needs a WavLM checkpoint the page never links, and pins torch 2.3.1 beside transformers 4.57.3
GLM-TTS: Controllable & Emotion-Expressive Zero-shot TTS with Multi-Reward Reinforcement Learning
At a glance
- What is it?
- zai-org/GLM-TTS is a zero-shot text-to-speech system in two stages, an LLM on the Llama architecture producing speech tokens and a Flow Matching model turning them into mel-spectrogram before a vocoder. The install path clones two third-party repositories, asks for a WavLM checkpoint with no address, and offers an NPU route that points at PyTorch's CPU wheel index.
- Who is it for?
- This is a research release with an inference path you can follow and a training path you cannot finish from the page alone. For inference, the shape is straightforward: Python between 3.10 and 3.12, a single pinned requirements file, weights pulled from one of two model hubs into a ckpt directory, and three ways to run it, a Python script, a shell script and a Gradio module.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 7 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
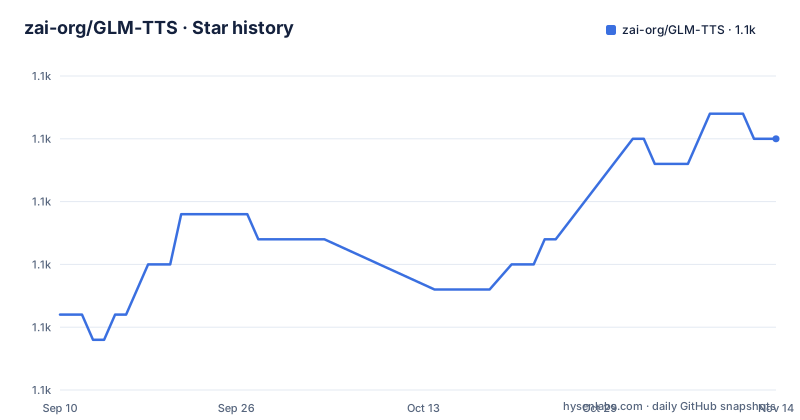
- zai-org/GLM-TTS1,070 ★ · +7
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| zai-org/GLM-TTS | 1.1k | 1.1k |
7 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The reinforcement learning checkpoint is named without an address
The GPU install path ends with four lines marked optional, and three of them fetch things from outside the repository:
cd grpo/modules
git clone https://github.com/s3prl/s3prl
git clone https://github.com/omine-me/LaughterSegmentation
# Download wavlm_large_finetune.pth and place it in grpo/ckpt directory
Two GitHub repositories are cloned into grpo/modules by URL, so those are unambiguous. The third line is not. The instruction names wavlm_large_finetune.pth and a destination directory, grpo/ckpt, but gives no source for the file, and no other part of the quick start supplies one. The same three lines reappear in the NPU path, so the gap exists twice rather than once. Treat it as the one manual step the documentation does not finish, and expect to look outside the project for where that checkpoint comes from.
The NPU install points extra index at PyTorch's CPU wheels
The NPU route starts from a CANN image on Ascend hardware:
export IMAGE=quay.io/ascend/cann:8.5.1-910b-ubuntu22.04-py3.11
docker run --rm \
    --name vllm-ascend-env \
    --shm-size=1g \
    --device $DEVICE \
    --device /dev/davinci_manager \
    --device /dev/devmm_svm \
    --device /dev/hisi_hdc \
The device list is specific: a numbered davinci device chosen through an exported DEVICE variable, plus the manager, shared memory and HDC device nodes, with the host driver directories bind mounted so the container can reach the driver. The install step that follows is where it gets strange. It runs pip config set global.extra-index-url against the PyTorch CPU wheel directory, then installs requirements_npu.txt with --no-build-isolation. A path for non-NVIDIA hardware that adds the CPU wheel index is worth checking against your own build before you trust it, and the second requirements file is a separate list you never see on the GPU side.
The demo command ends with a commented flag inside the continuation
Inference has three entry points. The documented command line is:
python glmtts_inference.py \
    --data=example_zh \
    --exp_name=_test \
    --use_cache \
    # --phoneme # Add this flag to enable phoneme capabilities.
The last line is a comment sitting inside a backslash-continued command, immediately after the continuation itself, so the shell ends the command there and the phoneme switch is a note rather than a flag you can uncomment in place and be sure of. The same capabilities are also reachable through bash glmtts_inference.sh and through python -m tools.gradio_app for an interactive page. The default data argument points at the Chinese example set, and a use_cache switch implies results are written somewhere and reused between runs, which is worth knowing before you run the same input twice expecting identical work.
Two coming soon items and a news list whose newest entry is from December
The news list has two dated entries and two that are not. Dated 2025.12.11, the project was open sourced with inference scripts and a series of model weights. Dated 2025.12.17, the technical report went up on arXiv as 2512.14291. Then there is a 2D Vocos vocoder update marked as in progress, and model weights optimised through reinforcement learning marked as coming soon, that last line also the only entry in the list without closing punctuation.
Neither pending item has a date, and neither has an artifact behind it. The repository publishes no GitHub releases, so there is no release list to check them against, and the last commit landed on 2026-04-10, some four months after the newest news entry. The complete weights the download section describes, covering tokenizer, LLM, flow, vocoder and frontend, are the pre-reinforcement-learning set; the RL-optimised version of that same idea is what the pending line refers to, and it is not among them.
One requirements file, 43 pinned lines, and two package names that are ordinary words
requirements.txt is 43 lines and every one is pinned with a double equals. The set is internally split by era. torch 2.3.1, torchaudio 2.3.1 and torchvision 0.18.1 form a matched trio, and numpy is held at 1.26.4, while transformers sits at 4.57.3, far ahead of the release those three belong to. The page asks for Python 3.10 through 3.12 without tying that range to any of the pins.
Two names in that list deserve a second look before you install anything: train pinned at 0.0.5, and evaluation pinned at 0.0.2. Both are ordinary English words rather than names scoped to a project, which is exactly the shape of a dependency you should confirm resolves to the code you expect. The rest of the file reads as three working groups: audio handling with soundfile, librosa and pydub, Chinese text processing with zhconv, zhon, pypinyin and WeTextProcessing, and serving and evaluation with gradio, fastapi, funasr, jiwer and openai_whisper.
Voice cloning runs on three to ten seconds of prompt audio
The headline capability is zero-shot voice cloning from three to ten seconds of prompt audio, and the architecture section explains how it avoids per-speaker tuning: speaker features are extracted from the prompt audio without fine-tuning for that speaker. The two stages are a large language model based on the Llama architecture that converts input text into speech token sequences, then a Flow Matching model that converts those tokens into mel-spectrogram, and finally a vocoder that produces the waveform.
The examples directory is built for exactly that flow. It holds two Chinese JSONL files and two English ones, example_zh.jsonl and example_zh1.jsonl, example_en.jsonl and example_en1.jsonl, alongside a prompt/ directory that holds the reference audio for those lines. The default in the demo command is the first Chinese file, so the shortest path from a fresh clone to audible output is the weights in ckpt plus one of those four files plus a clip in the prompt directory.
Polyphones are handled by a table lookup between G2P and generation
Phoneme-level control exists for the cases where automatic pronunciation goes wrong: polyphones such as a character read as either of two different ways, and rare characters. The mechanism is called Phoneme-in and it accepts hybrid phoneme plus text input, which is how you override one word without rewriting the sentence.
Training and inference solve the problem differently. During training, random G2P conversion is applied to parts of the text, which forces the model to accept mixed sequences and so keeps its ability to read pure text while improving on phoneme input. At inference the workflow is three steps: convert the whole text with G2P, then use a dynamic controllable dictionary to find polyphones and rare characters and replace them with chosen phonemes, then feed the replaced phonemes together with the original text as hybrid input. The target cases named are educational assessment and audiobook work, where a misread character is a defect rather than a stylistic choice.
The reward list is four named functions, and the paragraph ends inside an abbreviation
Reinforcement learning is the stated answer to flat emotional expression in traditional TTS. The framework evaluates generated speech through several reward functions, and four are named on the page: a similarity reward, a CER reward, an emotion reward and a laughter reward. The algorithm is named as GRPO, and the sentence introducing it stops there, inside the parentheses of the expansion, so the variant in use is not written down.
The repository layout maps onto those claims. llm/, frontend/, flow/ and tools/ follow the two-stage pipeline, grpo/ holds the training side, and configs/ and assets/ sit alongside them. One directory has no counterpart in that scheme: cosyvoice/ sits at the root next to llm/ and flow/, with nothing in the quick start or the architecture text saying what it contains or where it came from. Given that the optional clone step pulls in two external repositories for the reward computation, the training path clearly depends on code the project does not own, and this third directory is the visible remnant of that.
Editorial conclusion
This is a research release with an inference path you can follow and a training path you cannot finish from the page alone. For inference, the shape is straightforward: Python between 3.10 and 3.12, a single pinned requirements file, weights pulled from one of two model hubs into a ckpt directory, and three ways to run it, a Python script, a shell script and a Gradio module. Two things to check first are the version pairing, since the file pins torch 2.3.1 alongside transformers 4.57.3 and includes two packages named after ordinary English words, and the fact that the promised reinforcement-learning-optimised weights are still marked as pending rather than downloadable. For training, budget for the missing pieces yourself: two cloned repositories and a WavLM checkpoint that the page names without linking. The emotion work is the interesting part of the design, and it is also the part with the fewest released artifacts behind it.
Frequently asked questions
What is zai-org/GLM-TTS?
A zero-shot text-to-speech system with a two-stage architecture. A large language model based on the Llama architecture turns text into speech token sequences, a Flow Matching model turns those tokens into mel-spectrogram, and a vocoder produces the waveform. It is Python, Apache-2.0 licensed, and its complete weights cover tokenizer, LLM, flow, vocoder and frontend.
How much audio does GLM-TTS need to clone a voice?
Three to ten seconds of prompt audio. Zero-shot cloning extracts speaker features from that prompt without fine-tuning for the specific speaker. The repository ships four example JSONL inputs, two Chinese and two English, plus a prompt directory holding the reference audio.
Which languages does GLM-TTS support?
Primarily Chinese, with English mixed text also supported. Chinese polyphones and rare characters are the motivation for the Phoneme-in mechanism, which takes hybrid phoneme plus text input and resolves pronunciation through a dynamic controllable dictionary.
What does the reinforcement learning in GLM-TTS optimise?
A multi-reward framework that scores generated speech with several reward functions, named as similarity, CER, emotion and laughter rewards, using GRPO. Those dependencies are optional for inference: the quick start marks the grpo module clones and the WavLM checkpoint as an extra step.
Does GLM-TTS run without an NVIDIA GPU?
An NPU path is documented, using a CANN image on Ascend hardware with a separate requirements_npu.txt installed after pointing the extra index at PyTorch's CPU wheel directory. No CPU-only path is described, and the last commit on the repository is dated 2026-04-10.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zai-org-glm-tts)Star history chart for your README
[](https://hysenlabs.com/projects/zai-org-glm-tts)Was this useful?