Agent Interview Hub grades its own question evidence
An interview prep library for AI Agent engineers, with interview experiences, job requirements and frequently asked questions from major Chinese tech companies
At a glance
- What is it?
- Agent Interview Hub is a Chinese-language study repository for AI agent engineer roles, carrying 300 or more questions that all ship with reference answers, fifteen categories of company and job material, six timed hands-on exercises and a sixteen-week plan from basics to offer, and its most distinctive document is not a question at all but an evidence model that records company, interview round, source count, recency and whether a report is first-hand or aggregated.
- Who is it for?
- Agent Interview Hub fits an engineer preparing for an agent role at a large Chinese technology company who wants one ordered path rather than scattered notes, and who will read the answer rather than memorise the question. It does not fit someone who needs evidence that a given question is asked often, because the repository's own signal board and evidence model are built from publicly shared reports rather than from interview data.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 23 days ago.
- What is it written in?
- Mainly HTML, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
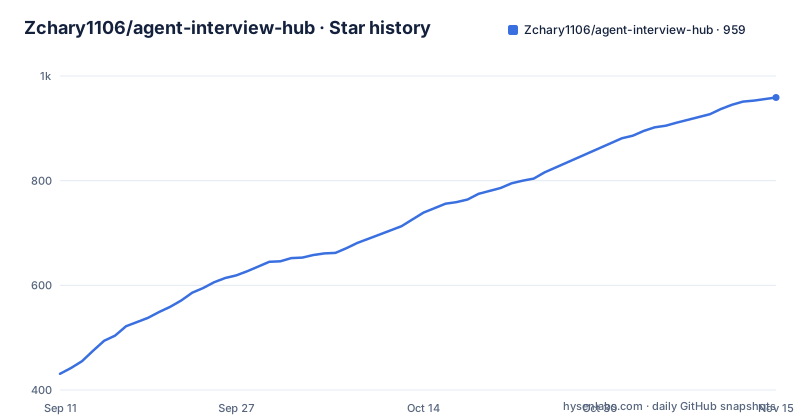
- Zchary1106/agent-interview-hub959 ★ · +528
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| Zchary1106/agent-interview-hub | 431 | 959 |
528 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The numbers the project leads with
The repository describes itself as the most complete interview knowledge base for AI agent engineers in China, aimed at engineers preparing to move into agent roles at large domestic technology companies.
The headline figures are specific. There are more than 300 interview questions with reference answers, fifteen categories of company and job material including overseas companies, six timed hands-on exam questions, and a complete sixteen-week learning roadmap from nothing to an offer. The general knowledge section holds 35 documents, and one of them is a traditional theory question set of 69 questions with detailed answers.
Three selling points are stated plainly. Every question comes with an answer, which removes the most common failure mode of a question dump. The interview reports are drawn from real sharing on a Chinese job forum rather than invented. And the whole thing reads in a browser, because it is published through GitHub Pages.
Interview reports can also be submitted by readers through the issue tracker, so the collection is expected to grow from outside.
The repository is MIT licensed, its primary language is HTML, and the last push was on September 14, 2026.
Four layers, drawn as a dependency graph
The knowledge system is drawn as a tree in the README, and the shape is the argument.
The foundation layer holds transformer architecture and attention, the principles behind language models with tokenisation and embeddings, and prompt engineering basics. Everything above it assumes those.
The core layer is the one most candidates are examined on. It covers agent design patterns, naming ReAct, plan-and-execute and multi-agent; the full retrieval pipeline from chunking to retrieval to reranking to generation; function calling and tool use; the Model Context Protocol; mainstream frameworks such as LangChain, LangGraph and AutoGen; and context engineering.
The advanced layer adds agentic retrieval and graph-based retrieval, agentic coding and AI programming tools, fine-tuning with inference optimisation and quantised deployment, and agent safety, evaluation and alignment.
The practice layer is the least technical and probably the least available elsewhere: system design and project experience, how to read a job requirement at one of these companies, and interview technique with real reports.
Several documents are marked as newly added, and the marks cluster in tool use, the protocol, agentic coding and harness evaluation, which is a reasonable signal of where the role has moved.
Six exercises with clock limits, borrowed from another project
The hands-on section is six programming tasks with difficulty stars and time limits, and the README is explicit that they come from a separate preparation project rather than being written here.
They are an intelligent document question-answering agent and a multi-agent team collaboration system, both at two stars with four to six hours. A ReAct pattern agent is slightly shorter at three to five hours. A timed full-stack development task takes two to three hours.
The two three-star tasks are the short, hard ones: an AI debugging challenge with a one to two hour limit, and an AI code review agent with four to six hours.
The design is deliberate. Most candidates can describe a ReAct loop; far fewer can build one in three hours while being watched. And a one-hour debugging task inverts the usual preparation, where debugging is the thing you practise last because it is hard to fake.
There is also a canvas file for users of a note-taking application that arranges the material as four parallel review lines: the long-term route, core knowledge, project practice, and company interview reports.
Two company tables, and two columns nobody has filled in
The company material is presented as two tables with the same three columns: job requirements, interview questions, and real interview reports.
The domestic table covers nine companies, and the pattern of marks is informative. Most have all three columns filled. Two of them, Baidu and Tencent, have job requirements and interview questions but no real reports marked at all.
The overseas table has five entries, and the gap is larger. Two of them, OpenAI and Anthropic, have all three. The remaining three, a Google entry for its DeepMind division, Microsoft, and a general startups entry, have requirements and questions but no reports.
So a candidate targeting Baidu or Tencent, or any of the three unfilled overseas entries, gets the requirements and a question list but not the part that is actually hard to get: what was asked, in what round, and how it was answered.
That gap is also why the repository asks for submissions through the issue tracker. The tables are honest about being incomplete rather than presenting a uniform set.
The evidence model is the cleverest document here
One document describes how the question bank knows what it knows, and it is the reason to take the rest of the repository seriously.
The model records, for each question, the company it came from, the interview round, how many sources reported it, how recent it is, whether the account is first-hand or aggregated, and a confidence level. Those six fields are the difference between a question bank and a rumour mill.
Two supporting documents close the loop. One is an index of recent interview reports drawn from public sources including a Chinese job forum, a social platform, a question-and-answer site, a developer blog network and a code host. The other is a document on cross-company role capability matrices, comparing application, algorithm, runtime, coding-agent and platform roles, which tells you which questions apply to the job you are actually applying for.
There is also material for the pressure phase rather than the study phase: nine chains of consecutive follow-up questions with answer evidence and scoring criteria, and a document on presenting a project in one or three minutes, covering technical difficulty, failure cases and how to write metrics.
That combination, an evidence model plus follow-up chains plus a scoring rubric, is closer to a practice instrument than to a list.
The new documents are about production, not prompts
Reading the recently added documents as a set, they cluster on the unglamorous half of the job.
There is a document on agent harnesses and coding-agent evaluation, covering deep reviews of several coding agents with source entry points. Another covers harness evaluation and release gating, with a three-part specification for tasks, environments and outcomes, a three-layer grading approach, and shadow and canary deployment patterns.
A document titled as new exam points for agent engineering in 2026 lists runtime behaviour, resumable execution, path oscillation, tool routing, tracing, and production-grade evaluation. Path oscillation in particular is a failure mode you cannot prepare for from a tutorial, because it only appears when an agent loops between two states.
Then there is enterprise platform work: control planes, runtimes, multi-tenancy, registries, model gateways and platform governance. And a document on self-evolving agents and the skill lifecycle, covering trace review, a curator role, skill versioning, canary rollout, rollback and preventing contamination.
The older documents in the list, by contrast, are the standard curriculum: framework comparisons, retrieval pipelines, inference optimisation and quantisation.
Two site versions, two build dependencies, and a scraper
Reading is supported three ways, and the two hosted versions are not the same site.
The classic version keeps the original content and the default address, with a notice at the top offering the switch. The new version uses a different layout built around a preparation path. A third page is a signal board for high-frequency questions, and all three are served from GitHub Pages and described as usable on a phone.
To read locally you clone the repository and open the files in any Markdown editor. To build the site locally, there are two dependencies, a Markdown library and its extension pack, then a build script and a local HTTP server:
python3 -m pip install -r requirements.txt
python3 scripts/build_site.py
python3 -m http.server 8000 -d dist
The output lands in a build directory, and pushing to the main branch triggers the same build through a GitHub Pages workflow, so the hosted site and the local site are the same pipeline.
The last piece is the interview collector. The repository ships an agent that searches public sources for interview reports, turns them into structured candidates, and syncs them into the index and the company documents. It installs with one command taking a list of target tools, and a table lists where it writes on each platform.
Editorial conclusion
Agent Interview Hub fits an engineer preparing for an agent role at a large Chinese technology company who wants one ordered path rather than scattered notes, and who will read the answer rather than memorise the question. It does not fit someone who needs evidence that a given question is asked often, because the repository's own signal board and evidence model are built from publicly shared reports rather than from interview data. Before you plan around it, check which company folders actually contain real reports rather than only job requirements and questions, and read the harness and release-gating documents, since those cover production practice that most interview preparation skips.
Frequently asked questions
What is the Agent Interview Hub used for?
It is a Chinese-language study repository for AI agent engineer roles at large domestic technology companies. It holds more than 300 questions that all carry reference answers, fifteen categories of company and job material, six timed hands-on exercises, 35 general knowledge documents and a sixteen-week plan from basics to an offer.
How does agent-interview-hub decide which questions are common?
Through a documented evidence model that records the company, the interview round, the number of sources, how recent the report is, whether the account is first-hand or aggregated, and a confidence level. A separate index collects recent public reports, and readers can submit new ones through the issue tracker.
What topics does the agent-interview-hub knowledge system cover?
Four layers. Foundations cover transformers and attention, language model principles with tokenisation and embeddings, and prompt engineering. The core layer covers agent design patterns, the retrieval pipeline, function calling and tool use, the Model Context Protocol, mainstream frameworks and context engineering. Advanced material adds agentic retrieval, agentic coding, fine-tuning and inference optimisation, plus safety and evaluation, with a practice layer on system design and interview technique.
What are the six practical exercises in agent-interview-hub?
A document question-answering agent, multi-agent team collaboration, a ReAct pattern agent, timed full-stack development with AI, an AI debugging challenge and an AI code review agent. Difficulty is marked out of three stars and time limits range from one hour for the debugging challenge to six hours for the three heaviest tasks.
How do I build the agent-interview-hub site locally?
Install the two documentation dependencies, run the site build script, then serve the output directory with a local HTTP server. The result lands in a build directory, and pushing to the main branch runs the same build automatically through a GitHub Pages workflow.
Which companies does agent-interview-hub have material for?
Nine domestic companies including Alibaba, ByteDance, Xiaohongshu, Baidu, Tencent, Meituan, Ant Group, Huawei and Kuaishou, plus five overseas entries covering OpenAI, Anthropic, Google DeepMind, Microsoft and startups. Baidu and Tencent have job requirements and questions but no real reports yet, and the same gap applies to Google, Microsoft and the startups entry.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zchary1106-agent-interview-hub)Star history chart for your README
[](https://hysenlabs.com/projects/zchary1106-agent-interview-hub)Was this useful?