No Cost AI: eighty free services listed in one README
80+ free AI services for chat, image, video, voice & APIs (may sometimes include access to lead gen ai models for free)
At a glance
- What is it?
- This repository is three files: a README, a licence and a workflows directory. The README is an index of free AI services, split into a no-signup half and a signup half, with a limits column for each entry. Its value is the bookkeeping rather than the links, including a row that was removed and left in place with its former details intact, and its blind spot is that several entries are third-party front-ends to commercial models whose free access cannot be relied on.
- Who is it for?
- Read this index as a starting point rather than a directory to depend on, because a free tier can change without notice and the index itself records one entry as already gone. Prefer the entries that are first-party services run by the model provider, where the quota is a published policy, and treat any third-party front-end offering premium model names as a thing that can disappear between one visit and the next.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 55 days ago.
- What is it written in?
- GitHub does not report a main language for this repository.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
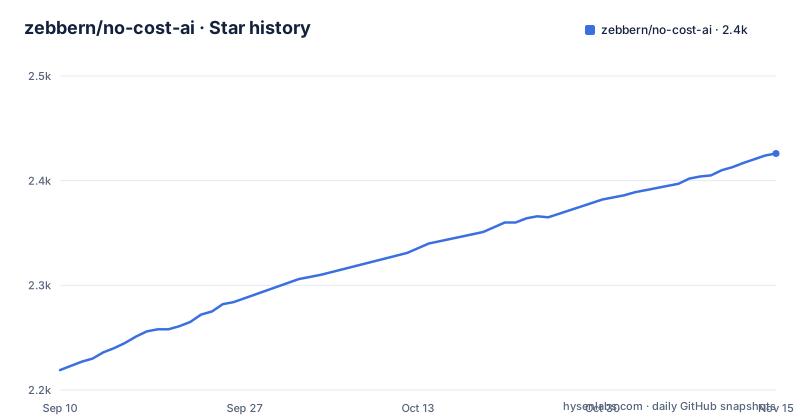
- zebbern/no-cost-ai2,426 ★ · +207
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| zebbern/no-cost-ai | 2.2k | 2.4k |
207 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three files, an unknown language, and an author who names the caveat
The repository contains a workflows directory, a licence and a README. That is the whole project, and the metadata agrees: the primary language field reads as unknown, because there is no code.
The licence is MIT, with a licence file at the root. There are no releases and the last push to main was 2026-09-21, so the artefact is a document that changes when a service changes its terms, not a versioned package.
The description is where the author sets the frame, and it is unusually candid for a list of this kind: eighty or more free services for chat, image, video, voice and APIs, followed by a parenthetical saying that these may sometimes include access to leading models for free. The README header calls it a living index for developers, researchers and curious builders, and asks for contributions.
The site it points to is deployed on Vercel, which is worth noting for one reason: a personal documentation repository whose front page is a hosted single-page app means the index and the site can disagree, and only the README is versioned.
So the honest description of this project is that it is a link index with an audit trail, not a directory with a guarantee.
Two count tables at the top and neither says which half it is
Two tables sit at the top of the README inside kbd elements, and each is a topic breakdown with link counts.
The first covers chat at 21, media at 5, voice at 3 and developer APIs at 4, which is 33. The second covers chat at 13, media at 12, voice at 4, IDEs at 2 and APIs at 17, which is 48. Together that is 81, consistent with the eighty or more claim in the description.
The structure of the body makes the split obvious once you scroll: the first set of tables is under a heading for services requiring no signup and the second is under a heading for those that require one. The count tables themselves do not carry those words, and they sit above the headings that would explain them. A reader arriving at the top of a long README sees two near-identical tables with no indication of which is which.
There is a smaller inconsistency in the same area. The second count table has a row for IDEs, and the body does have an AI IDEs section, but that section is an empty table: a heading and three column headers followed by no rows.
So the counts are checkable and one of them is not backed by content.
The limits column mixes quotas with reliability notes
Each row has three cells: a link, the free models, and the limits. The third cell is where the interesting information is, and it does not hold one kind of information.
Some entries are quotas: the ChatGPT row says five to ten messages, Mistral says ten messages resetting every twenty-four hours, Grok says three messages every two hours, Gemini says thirty-two thousand tokens and five to ten prompts per day with no image, file or audio generation, Copilot says unlimited with one image per day, and Perplexity gives three Pro searches per day with unlimited basic searches.
Other entries are field reports. One site offering premium model names is described as unlimited but possibly hard to get a response from because many other people use it, with the note that it really does work. Another says the model is unknown and the limit is unlimited, should be. A third says unknown for both the models and the limits.
One row is simply a subscription product with a small free slice: Poe's entry says three thousand tokens resetting every twenty-four hours.
Mixing a hard quota with an impression of reliability in the same column means you cannot sort or filter the list by what kind of constraint you are up against. A reader who needs a documented allowance can find one. A reader who needs to know whether a service will answer at all has to read prose in a table cell.
One entry is marked removed and kept in place
The best piece of bookkeeping in the index is a row for a service that is no longer there:
`freegpt.es` *(removed: unreachable)* | Formerly listed with `gpt-4o`, `DeepSeek`, `Grok`, `Gemini` etc.. | Previously `50 requests` per day or more
Nothing was deleted. The row keeps the domain, marks it as removed and unreachable in the link cell, preserves the models it used to offer, and preserves the quota it used to have. That is more useful than deleting the row, because a reader who has a project depending on that service can see at a glance that it is gone rather than wondering whether they mistyped a URL.
The same habit shows up elsewhere. A site that hosts several chat endpoints is listed with a backup domain next to it, so there is a fallback path if the primary disappears.
It also makes the risk visible. Several entries in both tables are third-party front-ends advertising commercial model names, and one of them advertises the most expensive tiers of a subscription model as unlimited. The index cannot vouch for any of them, and the fact that one is already gone is the evidence for how quickly that can happen.
A front-end offering premium models for free is either a promotional arrangement, an abuse of someone's credentials, or both, and in either case it is the entry most likely to disappear without notice.
The media table says unlimited and then names a proprietary model
The media section has five rows and the same three-column shape.
A commercial video and image platform is listed with its fourth-generation creative assistant and marked unlimited. A generative image service with no signup is listed with a long model list and unlimited. An image editor is marked unlimited for editing with the model described as unknown. And a page hosted on a free hosting site is listed as unlimited, image generation only, no watermark, with the mechanism given as using another service's API.
Two of those deserve a note.
The first is that the model behind one entry is described in the free models column as proprietary. A free service built on a model nobody else can run is free because someone is paying for it, which means the terms are that provider's to change.
The second is the entry that says it uses another service's API. It is honest about the mechanism, and it is also an unversioned dependency: the page keeps working or stops working based on a third party's behaviour, and nothing in the index would tell you it had changed.
The API section gives up precision twice
The developer API section is the most useful part of the index for automation, and the least precise.
One row offers an OpenAI-compatible API described as unlimited, with a named text model, a coding model and a speech model. Two rows say the same thing in the free models column: too many to list. One of those is a wrapper around local models, with the limit given as unknown. The other is the local model runtime itself, listed as unlimited and runnable in the cloud or on your own machine.
The last row is the honest one: it lists several backends the wrapper can use, including hardware vendor endpoints and a specific open model, and it requires an API key. An entry in a no-signup list that requires an account is not wrong, but it is not what the heading promises.
Two rows saying too many to list is the real cost here. In the chat tables, an imprecise row still tells you which service to visit. In the API tables, imprecise means you cannot write the integration without opening the vendor's own documentation, which is the work the index was supposed to save you.
The OpenAI-compatible row is also the one with the shortest half-life. An endpoint that offers unlimited access to commercial models through a third party is the kind of thing that gets withdrawn.
The leaderboard table is a different kind of artefact
Eight of the links in this repository are not services at all. They are benchmarks, listed in a table of their own with a scope column: a provider ranking page, an instruction-following evaluation against a reference model, an open leaderboard covering more than forty thousand open models, a crowd-sourced ranking of chat models, an embedding benchmark across a hundred languages and a thousand tasks, an independent evaluation site, and two more crowd-sourced ranking pages.
That is a different promise from the rest of the file. A free web service can be checked by visiting it. A benchmark can only be trusted if you accept what it measures, and several of these have a known constituency, since crowd-sourced rankings depend on who votes.
The signup-required section also mixes models with a reward scheme. One entry gives unlimited access as long as credits are maintained, and the credits are earned by giving feedback on model usage, with the earnings described as a randomized variable. That is a payment for your time rather than a free tier, and the phrasing in the index is accurate about it.
What the two halves of the repository share is curation by one person with no automated checking. Both the service lists and the leaderboard list are snapshots, and only the service list shows any sign of being revisited.
Editorial conclusion
Read this index as a starting point rather than a directory to depend on, because a free tier can change without notice and the index itself records one entry as already gone. Prefer the entries that are first-party services run by the model provider, where the quota is a published policy, and treat any third-party front-end offering premium model names as a thing that can disappear between one visit and the next. Before you build on it, note that it is a single README with no releases, no machine-readable data file and no per-entry last-checked date, so nothing here is verifiable without opening every link yourself.
Frequently asked questions
What is the No Cost AI repository?
A single README indexing free AI services, split into chat, media, voice, IDE and developer API categories, with a no-signup section and a signup-required section. Each row gives a link, the models said to be free, and the stated limits. There is no code in the repository.
How often is the No Cost AI list updated?
The repository has no releases and the last push to main was 2026-09-21. Entries carry no last-checked date, so freshness has to be judged per entry. One entry is explicitly marked removed and unreachable, with its former models and quota kept in the table.
Does No Cost AI offer an OpenAI-compatible API?
One developer API entry is listed as an OpenAI-compatible API described as unlimited, with a text model, a coding model and a speech model. Other rows in that section say the model list is too many to list, and one entry requires an API key despite appearing in the no-signup section.
Can No Cost AI give free access to premium models?
Its own description says the listed services may sometimes include access to leading models for free, and the chat tables include third-party entries advertising commercial model names, including the highest tiers of one subscription model, marked as unlimited. No entry is guaranteed to keep working, and one entry listed with such names is already marked removed.
What is the licence on the No Cost AI list?
MIT, with a licence file at the repository root. The repository metadata also reports MIT, and the repository's primary language field reads as unknown because it contains only a README, a licence and a workflows directory.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zebbern-no-cost-ai)Star history chart for your README
[](https://hysenlabs.com/projects/zebbern-no-cost-ai)Was this useful?