austin: one send interface for ten delivery types
A message push platform, delivering notifications via email, SMS, WeChat official account, WeChat mini-program, WeCom and DingTalk.
At a glance
- What is it?
- austin is a Java message push platform that puts one sending interface and one set of web templates in front of email, short message, WeChat, DingTalk, WeCom and Feishu delivery. It traces every send by user, template and message, and it pays for that visibility with extra infrastructure.
- Who is it for?
- Adopt austin when a company already pushes through several of these channels and wants one place to hold templates, weight providers and watch delivery. Leave it alone when you need a hosted product with a tagged release to pin, since this repository publishes none, or when you cannot give Kafka, Flink, xxl-job and graylog their own processes.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 158 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
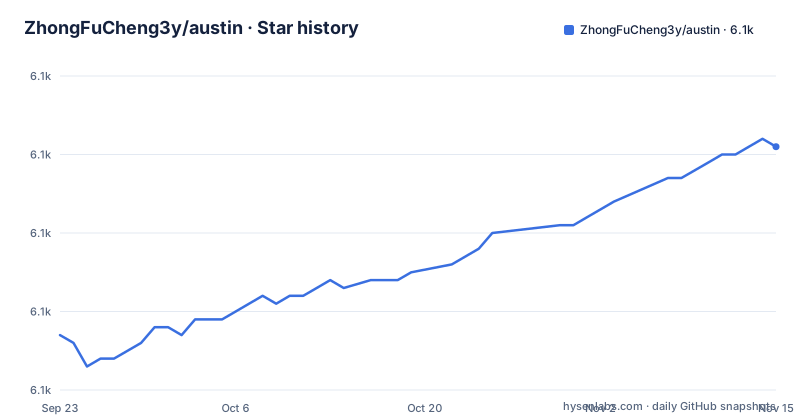
- ZhongFuCheng3y/austin6,111 ★ · +24
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| ZhongFuCheng3y/austin | 6.1k | 6.1k |
24 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One send interface for ten delivery types
austin is a Java message push platform for companies that send messages from more than one channel. The design puts a single sending interface in front of the channels and tracks the message lifecycle end to end. The delivery targets named in the project are short message, email, WeChat service account template messages, WeChat mini program subscription messages, DingTalk group robots, DingTalk work messages, Android notification bar pushes, WeCom robot messages, WeCom application messages and Feishu robot messages. Templates live in the web console rather than in code, and placeholders inside a template take variable values at send time. The stated argument for centralising this is functional: message handling is collected in one component instead of being scattered across business services, which shortens the work when a new notification is needed.
Channel isolation, traffic ratios and the hades rules engine
Isolation is described as a design property rather than a hope. The email path and the short message path do not share a channel, so a slow mail server leaves text delivery alone. The sending interface is asynchronous and accepts batches, which is what lets traffic drain after the caller returns instead of blocking it. Two controls sit above that plumbing. Traffic weighting splits outgoing short messages across providers by a configurable ratio, and the split can be changed without shipping a release. Adding a provider is handled by a rules engine called hades, with the stated goal of switching a new short message channel on without a system deployment. Copy deduplication, frequency capping, night blocking and next day sending are platform level features too, so those rules get written once instead of in every service that sends mail.
Tracing by user, template and message runs through Kafka and Flink
Delivery is observable from three angles: by user, by template and by individual message, close to real time. That view is not part of the core install. Seeing the real time data flow means deploying Flink, writing the redis and kafka host and port values into com.java3y.austin.stream.constants.AustinFlinkConstant before packaging, then submitting the austin-stream jar to the cluster. The compose file shows which topics the path depends on, and the trace log topic name comes from austin.business.log.topic.name in application.properties:
      KAFKA_ADVERTISED_LISTENERS: PLAINTEXT://austin-kafka:9092
      KAFKA_CREATE_TOPICS: "austinBusiness:1:1,austinRecall:1:1,austinTraceLog:1:1"
      KAFKA_HEAP_OPTS: -Xmx512M -Xms256M
The deployment notes are direct about this: if that topic does not exist you have to create it in advance and use Kafka as the queue. Because the step is optional, leaving Flink out does not stop messages from being sent. It removes your view of what happened to them, and you find that out after an incident rather than before one.
Cron scheduling and CSV audiences sit behind xxl-job
Scheduled sending is configured from the same template screen. You choose the scheduled task option while creating a template, upload a CSV file of the audience, and supply a cron expression. That path depends on xxl-job: start its scheduler centre as described in doc/INSTALL.md, then fill austin.xxl.job.ip and austin.xxl.job.port in the properties file. Distributed log collection has the same shape, needing graylog plus austin.graylog.ip, while system monitoring adds prometheus and grafana. One editing slip is worth knowing before you follow the list, because the later steps name the file application.properteis instead of application.properties. Apollo, if you take it as the dynamic configuration centre, wants its host and port injected into AustinApplication, and the file points you at the comments there rather than naming the keys.
The first run needs application.properties, austin.sql and a separate admin repo
The core run is short. Fill the datasource block in austin-web/src/main/resources/application.properties with ip, port, username and password, run doc/sql/austin.sql against the server to create the tables, then fill the redis block with its ip, port and password. MySQL 5.7x is the version austin is written against, and on 8.0 you are told to change both the pom.xml dependency version and the connection information. Everything else in that file is optional. The admin console is not in this repository: austin-admin is cloned from GitHub or Gitee and deployed on its own. The bundled middleware comes from the compose file, whose MySQL service reads like this.
  austin-mysql:
    environment:
      TZ: Asia/Shanghai
      MYSQL_ALLOW_EMPTY_PASSWORD: 'yes'
      MYSQL_ROOT_HOST: '%'
      MYSQL_ROOT_PASSWORD: "root123_A"
    restart: always
    container_name: austin-mysql
    image: mysql:5.7
    hostname: mysql
    volumes:
      - ./doc/sql:/docker-entrypoint-initdb.d
      - ./doc/docker/mysql/mysql.cnf:/etc/mysql/my.cnf
    ports:
      - "3306:3306"
Two details in that block matter. Mounting ./doc/sql into the init directory means austin.sql runs on first boot, so the schema step and the container step are the same action. The credentials also sit in the file rather than in something you override at run time, so treat the compose setup as a local or evaluation arrangement and not as a production credential store. Redis, ZooKeeper, Kafka and the Flink jobmanager each publish their own port in the same file, which means a machine with those services already running will collide on 3306, 6379, 2181, 9092 or 8081.
2G for the core stack, 16G when every optional service runs
Memory is where the deployment notes stop being vague. MySQL and Redis are hard dependencies and come to roughly 2G. Kafka, prometheus, graylog, flink, xxl-job, apollo and hive are weak dependencies, and deploying every service lands near 16G. Each one buys one of the features described earlier, which makes the trade explicit: tracing, scheduling, monitoring, log collection, dynamic configuration and the data warehouse are six features priced in extra processes. The web module is packaged on the openjdk:8-jre image, so the Java baseline is 8, and the container expects a jar that has already been built.
FROM openjdk:8-jre
ENV PARAMS="--spring.profiles.active=test"
WORKDIR /build
ADD ./austin-web/target/austin-web-0.0.1-SNAPSHOT.jar ./austin.jar
ENTRYPOINT ["sh","-c","java -jar $JAVA_OPTS austin.jar $PARAMS"]
Two things follow from those five lines. The build has to run before the image does, because the ADD line names a specific jar path. The default PARAMS value also activates the test profile, which is not what you want on a real deployment.
0.0.1-SNAPSHOT jars and a repository with no releases
Upgrade cost is where this project is thinnest. The repository publishes no releases, so there is no tag to pin, no changelog to read and no upgrade note telling you what moved between two points in time. The Dockerfile names austin-web-0.0.1-SNAPSHOT.jar, which carries no release date and no compatibility statement. The front end is not in the tree either: austin-admin lives in its own repository and has to be versioned and deployed separately from the Java side, so a console fix and a backend fix can arrive at different moments. The deployment notes also stay silent on rollback, on schema migration after the initial austin.sql load, and on what happens to queued messages across a restart. A team planning a production rollout is therefore choosing to run master, with the last push on 2026-06-10 as the only reference point.
Silent on retries, delivery guarantees and rate limits
Several things a push platform gets judged on are simply not written down. There is no retry policy, no statement of delivery guarantees, no per interface rate limit and no API versioning scheme. The one performance claim is that the sending interface is asynchronous, supports batch sending and carries high concurrency traffic, and no figure is attached to it. Two more gaps are visible in what the project publishes. The demo address and the homepage are plain http on port 3001 at a bare IP address, with no hostname and no certificate. Support is also arranged personally: the project group has passed two hundred members, and new people are added when the maintainer has free time, after a personal WeChat account is added with a project note.
Editorial conclusion
Adopt austin when a company already pushes through several of these channels and wants one place to hold templates, weight providers and watch delivery. Leave it alone when you need a hosted product with a tagged release to pin, since this repository publishes none, or when you cannot give Kafka, Flink, xxl-job and graylog their own processes. Before committing, check the Java 8 build of austin-web against your runtime, and read doc/INSTALL.md for the components your feature set actually needs.
Frequently asked questions
What message types can austin send?
Email, short message, WeChat service account template messages, WeChat mini program subscription messages, DingTalk group robot and work messages, Android notification bar pushes, WeCom robot and application messages, and Feishu robot messages.
What does austin need before it can start?
MySQL and Redis, which the project calls hard dependencies, together needing roughly 2G of memory. You fill spring.datasource and spring.redis in austin-web/src/main/resources/application.properties and run doc/sql/austin.sql to create the tables.
Which MySQL version does austin target?
MySQL 5.7x, and the compose file runs the mysql:5.7 image. On MySQL 8.0 the deployment notes tell you to change the pom.xml dependency version and the connection information.
Where does the austin admin console live?
In a separate repository named austin-admin, available on GitHub and Gitee, and deployed separately from the Java backend.
How does austin send scheduled messages?
You pick the scheduled task option when creating a template, upload a CSV file of the audience and set a cron expression. That path needs xxl-job running, with austin.xxl.job.ip and austin.xxl.job.port filled into application.properties.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zhongfucheng3y-austin)Star history chart for your README
[](https://hysenlabs.com/projects/zhongfucheng3y-austin)Was this useful?