book-searcher: the search half of a library you assemble yourself
Easy and blazing-fast book searcher, create and search your private library.
At a glance
- What is it?
- book-searcher turns CSV metadata that you export yourself into a folder of index files and a meta.json, then serves search on a local port. It searches what you hand it: no catalog, no downloads, no in place index update.
- Who is it for?
- book-searcher fits one shape of work: you own a set of purchased books, you can export their metadata as CSV, and you want fast local search over that list. It does not acquire books, does not fetch covers or IPFS links, and does not update an index in place, so treat it as the search half of a library system whose other half you have to build.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 8 months ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
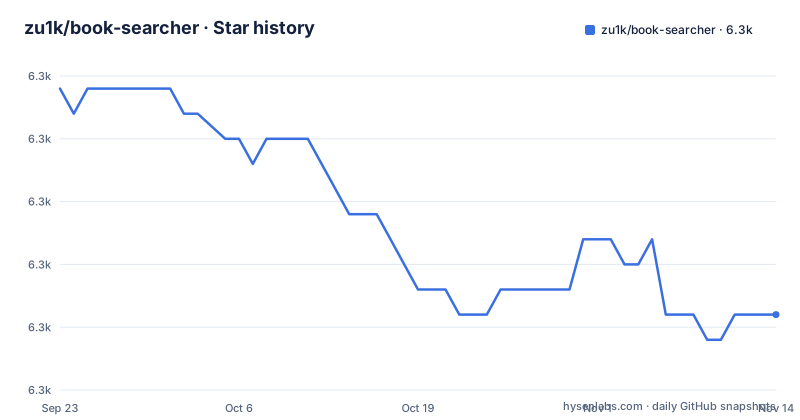
Star history
- zu1k/book-searcher6,293 ★ · -9
| Repository | 2026-09-23 | 2026-11-14 |
|---|---|---|
| zu1k/book-searcher | 6.3k | 6.3k |
-9 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One command turns CSV files into the index folder
Every route into book-searcher passes through the same artifact: an index directory holding index files and a meta.json, sitting next to the book-searcher binary. It is produced by a single command over CSV files you place in the project root.
book-searcher index -f *.csvThe project warns that you may need to rm -rf index first, so an index is not something it merges into or updates in place. Rebuilding is the documented path, which matters for the Docker setup later. The resulting layout is fixed:
book_searcher_dir
├── index
│   ├── some index files...
│   └── meta.json
└── book-searcher
Two names collide here on purpose: the working directory in the example is book_searcher_dir while the binary inside it is book-searcher. The index is bound to that directory, and both install paths point you back at it later.
It will not fetch metadata, covers or IPFS links for you
The raw data section settles the scope. A CSV needs the fields id, title, author, publisher, extension, filesize, language, year, pages, isbn, ipfs_cid, cover_url, and md5, and the project's own sentence about it is blunt: you need to export and maintain your own meta information for the books you have purchased, as this project only provides fast searching. No catalog provider, downloader, or file store appears in the repository. Two fields make the boundary concrete. ipfs_cid and cover_url are values your export has to supply, and nothing in the repository fetches either one. The hard part of running a private library, which is acquiring clean per book metadata, stays on your side of the line. What you get is the cheap part done well: the lookup after the data exists.
127.0.0.1:7070 for the CLI, 0.0.0.0:7070 once Docker owns the process
The bind address is the real difference between the two documented deployments. Running book-searcher run yourself binds to 127.0.0.1:7070, and the web interface is at http://127.0.0.1:7070/. The Docker path passes -b 0.0.0.0:7070 in the image command line, and the compose file publishes the port to the host:
mkdir book-searcher && cd book-searcher
wget https://raw.githubusercontent.com/book-searcher-org/book-searcher/master/docker-compose.yml
docker-compose run --rm -v "$PWD:$PWD" -w "$PWD" book-searcher /book-searcher index -f *.csv
docker-compose up -d
That compose file also sets restart: always and mounts ./index:/index, so the index survives a replaced container. The index command runs through compose once, before the service starts, and the working directory is mounted into the container so the CSV files land in the right place. Read the bind address twice if that service ends up reachable beyond your own machine.
filter is the default mode, explore relaxes the restrictions
The API surface is seven searchable fields: title, author, publisher, extension, language, isbn, and id. Queries carry limit and offset, and one form switches to a fielded query string:
/search?limit=30&offset=0&title=TITLE
/search?limit=30&offset=0&isbn=ISBN
/search?limit=30&offset=0&query=title:TITLE extension:epub publisher:PUBLISHER
/search?limit=30&offset=0&mode=explore&title=TITLE&author=AUTHOR
The mode parameter changes results instead of shaping them. Without it you are in filter, where a result must meet all restrictions. With mode=explore a result only needs to meet certain restrictions, which is the documented way to widen a query that returns nothing. Nothing in the project text explains how explore orders partial matches, so treat it as a loosening switch rather than a described ranking mode. Note also that a title field and a title inside query do not sit in the same syntax, which is a small trap when you copy examples.
The download steps point at book-searcher-org, not at this repository
Both install paths open by telling you to fetch a pre-compiled build from a Release page, and the link in each case belongs to the book-searcher-org repository rather than zu1k/book-searcher. This repository publishes no GitHub releases of its own. Cargo.toml also names https://github.com/book-searcher-org/book-searcher as the project's homepage and repository, so that release list is where the usage section sends you. The artifact names are explicit once you arrive. Windows is Book-Searcher-desktop_version_x64.msi, macOS is Book-Searcher-desktop_version_x64.dmg, and Linux ships as Book-Searcher-desktop_version_amd64.deb or Book-Searcher-desktop_version_amd64.AppImage. The CLI section names a pre-compiled binary without giving a filename, so that one needs a closer look before you rely on it.
The Makefile builds the frontend with pnpm, the Dockerfile with npm
Building from source means the frontend first, then Rust. The CLI sequence is two commands and a move:
make frontend_preinstall frontend
TARGET=release make
mv target/release/book-searcher .
The desktop binary comes from cargo tauri build after the same preinstall step. Behind those targets is a mismatch worth knowing. The Makefile defines frontend_preinstall as pnpm -C frontend install and frontend as pnpm -C frontend run build, while the image's frontend stage runs cd /source/frontend && npm install --legacy-peer-deps && npm run build. Two package managers for one frontend directory, and the npm path carries a legacy peer dependency flag. TARGET also defaults to debug in the Makefile, so a plain make gives you an unoptimized build and the release profile never engages.
A five crate Cargo workspace on Tantivy 0.21 with default features off
Cargo.toml describes a workspace of five crates: book-searcher, book-searcher-core, book-searcher-desktop, tantivy-meta-tokenizer, and tools, on resolver 2 and edition 2021, at version 1.3.0. The search engine dependency is written as tantivy = { version = "0.21", default-features = false }, so anything sitting behind Tantivy's default feature set is not switched on by this workspace. The release profile trades build time for output: strip, lto, opt-level 3, and codegen-units 1. The package exclusion list covers .github/, index/, and frontend/, so an index directory is never treated as part of a package. Count the members and you can see the split between the server, the core, the desktop shell, a custom tokenizer, and tooling.
Last push on 2026-03-06, with release scripts but no releases
The repository is not archived, and its last push landed on 2026-03-06, which is the date to weigh when you adopt it. There are no GitHub releases attached, so the change history is whatever the commits carry. The Makefile still defines a releases target that runs build_release.sh from the scripts directory, and Cross.toml sits at the top level for cross compilation. The frontend is split out as its own deployment unit: the documented approach sends it to Vercel or Netlify to speed up loading of static resources and provide a reverse proxy to the image service. A deployment is therefore three pieces, frontend, index, and binary, assembled by hand. With a last commit in March 2026, the latest tag in the compose file is an unpinned reference, and Cargo.lock is where the actual dependency versions live.
Editorial conclusion
book-searcher fits one shape of work: you own a set of purchased books, you can export their metadata as CSV, and you want fast local search over that list. It does not acquire books, does not fetch covers or IPFS links, and does not update an index in place, so treat it as the search half of a library system whose other half you have to build. Before adopting, check the export you already have against the thirteen required fields, decide whether the desktop build or the CLI build fits your platform, and confirm that a last commit dated 2026-03-06 leaves you comfortable with a Docker tag of latest.
Frequently asked questions
What does book-searcher need before it can search anything?
CSV files of your own book metadata, saved to the project root, with the fields id, title, author, publisher, extension, filesize, language, year, pages, isbn, ipfs_cid, cover_url and md5. The project states that you must export and maintain this information yourself, because it only provides fast searching.
Which ports does book-searcher listen on?
The command line version listens on 127.0.0.1:7070 and serves its web interface at http://127.0.0.1:7070/. The Docker deployment listens on 0.0.0.0:7070, and the compose file maps port 7070 to the host with the index directory mounted at /index.
How does book-searcher handle a query that matches too little?
There are two modes. The default filter mode requires results to meet all restrictions. Adding mode=explore to the query string relaxes that, since results then only need to meet certain restrictions. The project text does not describe how partial matches are ordered in explore mode.
Where do prebuilt book-searcher builds come from?
The usage steps link to the release page of the book-searcher-org repository, which is where the Windows msi, macOS dmg, and Linux deb and AppImage desktop files are named. This repository publishes no GitHub releases itself, so building from source is the other documented route.
What does building book-searcher from source involve?
For the CLI, run make frontend_preinstall frontend and then TARGET=release make, and move target/release/book-searcher to the project root. The desktop version uses cargo tauri build. The frontend step uses pnpm in the Makefile, while the Docker image builds that same directory with npm.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zu1k-book-searcher)Star history chart for your README
[](https://hysenlabs.com/projects/zu1k-book-searcher)Was this useful?