AuK: a 1.5B speech model whose Performance and Model Architecture sections are empty headings
AuK: An Open-Source Foundational Model for Speech Generation and Editing
At a glance
- What is it?
- An open-source foundational model for speech generation and editing, released in September 2026 with a base variant and a four-step distilled one. The details worth knowing are in the dependency comments, the environment template, and two headings the README leaves bare.
- Who is it for?
- AuK is worth a look if you want a single instruction interface covering zero-shot TTS, lyric rewriting and paralinguistic edits rather than a stack of narrow models, and if a 1.5B base plus a distilled variant fits your hardware budget. Three things to check before you plan around it.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 10, 2026, and from our analysis. They are not legal advice.
Star history
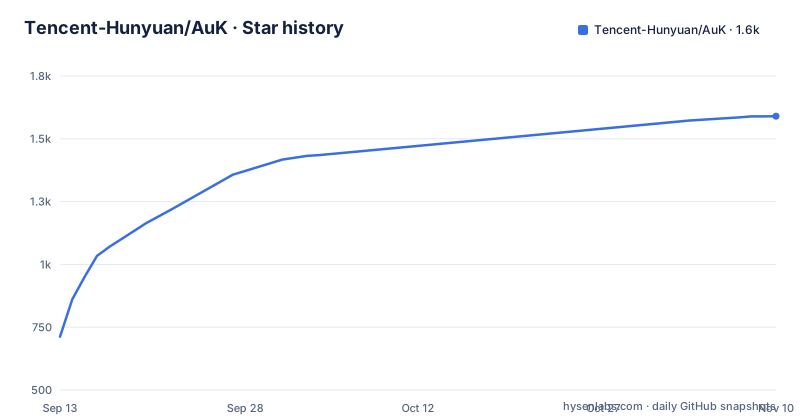
- Tencent-Hunyuan/AuK1,590 ★ · +878
| Repository | 2026-09-13 | 2026-11-10 |
|---|---|---|
| Tencent-Hunyuan/AuK | 712 | 1.6k |
878 Stars in the last 58 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two headings with nothing under them
The table of contents promises Introduction, Performance, Model Architecture and Supported Tasks, and the body delivers all four headings in a row with nothing between them. Performance is immediately followed by Model Architecture, which is immediately followed by Supported Tasks. So the two sections a reader would use to judge the model are the two that are empty. Three badges sit above that gap, each pointing at a leaderboard entry keyed to a different evaluation id, which means the results those badges represent are hosted somewhere other than in the repository. The Supported Tasks table then runs through zero-shot and instruct TTS, speech content and lyric editing, pitch, speed and volume editing, then emotion, timbre and de-accent, at which point it ends. The introduction separately claims speech enhancement and source separation, which the visible rows never reach.
Apple Silicon support sits on a branch
The news entries run from 2026-09-09, when the code and weights were open sourced, to 2026-09-20. One of them announces official MLX inference on Apple Silicon and CPU offload for CUDA, dated 2026-09-13, and the link for it points at a tree named feat/mlx-apple-silicon rather than at main. So a headline capability announced in the project's own news is presented from a feature branch. If you are on a Mac, the announcement does not tell you whether that code has landed on the default branch, and the default branch is what a plain clone gives you. Check which branch you are on before planning a local Apple Silicon deployment, because nothing in the announcement distinguishes the two states.
Five integrations in eleven days, and no releases at all
Read the news list as an integration timeline rather than a feature list. Day zero on 2026-09-09 brought SGLang-Omni support for both AuK and AuK-Flash. Two days later came vLLM-Omni, which serves them as a two-stage pipeline on a single H100 using a published recipe. On 2026-09-13 AuK became the end-to-end baseline for the Single Model Track of the ICASSP 2027 Audio Editing Challenge. On 2026-09-16 encoder memory was cut by roughly 7.5 GiB, which is what makes local inference fit on a consumer GPU, and it landed as a single pull request. On 2026-09-20 audio.cpp added GGUF offline inference behind a family flag. Meanwhile the repository has no GitHub releases, so model versions are tracked on Hugging Face and ModelScope instead of by tag.
The prompt enhancer calls a hosted endpoint
A repository that reads as fully local is not quite. The environment template asks you to copy it and choose one OpenAI-compatible text LLM provider, offering Tencent TokenHub with the base URL tokenhub.tencentmaas.com and the model name hy3, or DeepSeek V4 Flash with api.deepseek.com and deepseek-v4-flash. That provider backs the prompt enhancer. Speech recognition has its own cloud path, using Tencent Cloud secret id and key with a model type of 16k_zh_en, and the fallback is spelled out precisely: without those credentials, or if the cloud request fails, AuK lazily downloads and runs SenseVoiceSmall on CPU. So a run with no credentials configured still makes network calls for the enhancer and still pulls a model on demand, which matters if you are working offline or auditing what leaves the machine.
The license is declared three ways
There is an inconsistency here, and it is better stated than resolved. The licence field recorded for the repository is NOASSERTION, which means the platform could not classify it at all. The packaging manifest separately declares it in two places, as license text reading MIT License and as a classifier for the MIT License. A LICENSE file sits at the root of the tree. So one source says unknown, one source says MIT, and a third artifact exists whose contents are not reproduced in what is available here. Rather than pick the most convenient of those, confirm which text governs with the project before you redistribute weights or ship a fine-tuned derivative, and note that a fine-tuning section is advertised in the contents even though the release status of those scripts is not stated.
Two variants, and two different organisation names across platforms
The model ships in a base form and a distilled form. AuK is the base model for high-quality generation, and AuK-Flash is described as a distilled model for fast four-step inference, which is a different latency budget rather than a smaller copy of the same one. The training corpus is described only as millions of hours of diverse audio data, with no language breakdown, no duration split and no dataset names, so any claim about coverage has to come from elsewhere. Publishing is split across two hosts, and the organisation names do not match between them: the Hugging Face repositories sit under tencent, while the ModelScope models sit under Tencent-Hunyuan. The demo Spaces follow the same split. Expect to look in two different accounts rather than one.
A transformers floor set by a different model
The dependency list explains itself in comments, and the explanations are more useful than the pins. The PyTorch family is held to the tested 2.7 ABI line with torch, torchaudio and torchvision each capped below the next minor, and the note says users may preinstall a platform-specific CPU or CUDA build first. The transformers constraint is the interesting one: the floor of 4.52 exists because Qwen2.5-Omni support landed there, while validation happened on 4.57. So a library named qwen-omni-utils in the dependency list, plus that floor, is the reason AuK cannot move forward on transformers as fast as it might otherwise. A numpy pin is present but commented out, with the reason given: numpy is no longer imported directly and arrives transitively through transformers, gradio and librosa.
Two extras that duplicate the same support stack
The optional dependency groups overlap heavily. The gradio extra is described as covering the Gradio UI, the prompt enhancer, cloud ASR and a local SenseVoice fallback, and the comfyui extra is described as covering ComfyUI nodes, the prompt enhancer, cloud ASR and the same SenseVoice fallback. Both begin with the same entries, PyYAML, silero-vad and WeTextProcessing, and both carry the same optional stack including openai, tencentcloud-sdk-python-asr, funasr and modelscope. Installing one and later adding the other means two sets of pins for a shared stack, which is where version skew would show up. The gradio extra also needs gradio 6 or newer. For the trajectory of the package itself, note the version is a static 0.1.0 and requires Python 3.10 or above.
Editorial conclusion
AuK is worth a look if you want a single instruction interface covering zero-shot TTS, lyric rewriting and paralinguistic edits rather than a stack of narrow models, and if a 1.5B base plus a distilled variant fits your hardware budget. Three things to check before you plan around it. The README's Performance and Model Architecture headings are empty, so the numbers and the design you would want to evaluate are not in the repository and the leaderboard badges point off-site. The prompt enhancer calls a hosted OpenAI-compatible endpoint, and the ASR path falls back to downloading a model on CPU when credentials are missing or a cloud request fails. And the license is declared three different ways, so settle that with whoever owns your compliance before shipping anything.
Frequently asked questions
What is AuK and what can it do?
AuK is a 1.5B foundation model for speech generation and editing. Through one natural-language instruction interface it does zero-shot and instruct TTS, speech content editing, lyric editing, pitch, speed and volume editing, and paralinguistic changes such as emotion, timbre and de-accent.
What is the difference between AuK and AuK-Flash?
AuK is the base model for high-quality generation. AuK-Flash is a distilled model built for fast four-step inference. Both are published on Hugging Face under tencent and on ModelScope under Tencent-Hunyuan.
Does AuK need an API key to run locally?
The environment template asks you to choose one OpenAI-compatible text provider for the prompt enhancer, such as Tencent TokenHub or DeepSeek. Speech recognition falls back to downloading and running SenseVoiceSmall on CPU when Tencent Cloud credentials are absent or the cloud request fails.
Can AuK run on an Apple Silicon Mac?
MLX inference on Apple Silicon is announced as officially supported since 2026-09-13, along with CPU offload for CUDA. That announcement links to a branch named feat/mlx-apple-silicon rather than to the default branch.
What license is AuK released under?
The sources disagree. The licence field recorded for the repository is NOASSERTION, while the packaging manifest declares MIT License both as license text and as a classifier, and a LICENSE file exists at the root of the tree.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tencent-hunyuan-auk)Star history chart for your README
[](https://hysenlabs.com/projects/tencent-hunyuan-auk)Was this useful?