Airbyte: a 700-connector data movement platform with a split licence and an MCP for AI agents
Open-source data movement for ELT pipelines and AI agents — from APIs, databases & files to warehouses, lakes, and AI applications. Both self-hosted and Cloud.
At a glance
- What is it?
- Airbyte ships an open-source ELT platform, a hosted Cloud service, and now the Airbyte MCP for working with it from AI agents. The connector catalogue is the draw; the mixed MIT and ELv2 licensing and the self-hosted deployment path are what you have to check before standardising on it.
- Who is it for?
- Adopt Airbyte if you need many long-tail API and database sources landing in a warehouse or lake and you are willing to run the self-hosted platform or pay for Cloud. Do not adopt it as a general-purpose streaming engine or as a replacement for a CDC tool on a high-frequency transactional feed; the README frames it around ELT syncs, not continuous replication.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
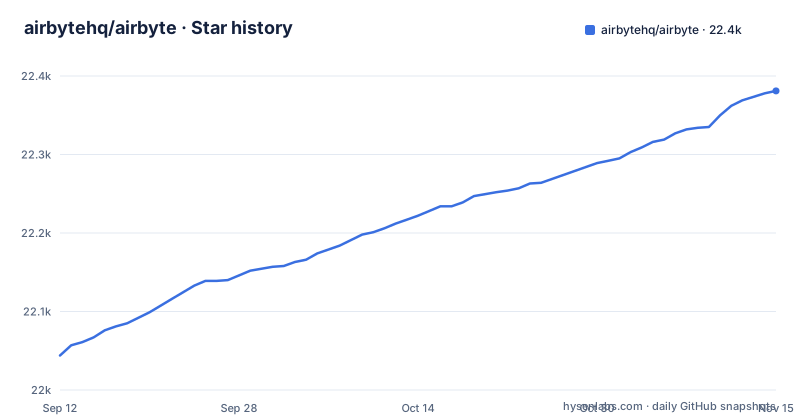
- airbytehq/airbyte22,381 ★ · +337
| Repository | 2026-09-12 | 2026-11-15 |
|---|---|---|
| airbytehq/airbyte | 22k | 22.4k |
337 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem Airbyte targets: the long tail of sources, not the top ten
Most integration work is not building the fifth Salesforce sync. It is the internal Postgres replica, the niche SaaS API with no maintained client, the CSV drop on S3 that someone has to poll. Airbyte's stated position is that only an open-source approach to data movement can cover that long tail while letting data engineers customize connectors they already depend on. The audience follows from that: data engineers and platform teams who own a warehouse or lake and keep receiving requests for new sources.
The README describes more than one job. Moving and syncing data into warehouses, lakes, and other data systems is served by self-hosted Airbyte Core or by Airbyte Cloud. Working with Airbyte from an AI agent goes through the Airbyte MCP: a hosted server at https://mcp.airbyte.com/mcp for Cloud, or a self-managed setup that runs locally against a Core deployment's API. A context layer that lets agents read live data and search it is available only in Airbyte Cloud. That split matters when you evaluate it, because the agent features differ between the self-hosted and Cloud editions.
Connectors, the CDK, and the connector registry report
The unit of work in Airbyte is the connector. The README claims a catalogue of 700+ connectors spanning APIs, databases, data warehouses, data lakes, and AI applications. For connectors that do not exist, the project offers two authoring routes: a no-code Connector Builder UI and a low-code CDK. The low-code CDK is a config-based approach, meaning a connector can be described declaratively rather than written as a full Python or Java program.
The README also points to a connector registry report at connectors.airbyte.com, described as the full list of connectors available in Airbyte or Airbyte Cloud. That distinction is worth internalising before you plan anything: the headline catalogue number and the set of connectors that are actually available in the edition you run are not necessarily the same set, and the registry is the artefact the project offers for checking.
On the language side, the repository is primarily Python but the root also carries Gradle and Maven build files (build.gradle, gradlew, spotless-maven-pom.xml), which is consistent with a codebase that has accumulated connectors and platform components in more than one runtime.
Getting it running: deploy, build a connector, orchestrate
The README's getting-started path for data movement is short and points outward. You either deploy Airbyte Core, following the quickstart at docs.airbyte.com/quickstart/deploy-airbyte, or you set up Airbyte Cloud. There is no docker compose snippet or helm command in the README's getting-started section, so the deployment specifics live in the linked quickstart rather than in the repository front page.
Once running, the documented workflow is: create connectors with the no-code Connector Builder or the low-code CDK, then orchestrate syncs. The README names four orchestration routes explicitly: Airflow via the Airbyte Airflow operator, Dagster via its integration, Kestra via its plugin, and the Airbyte API directly. It also links a demo app at demo.airbyte.io for trying the product without deploying.
For the AI path, the README points to the Airbyte MCP: an agent such as Claude, ChatGPT, Cursor or VS Code Copilot can build and manage data pipelines, troubleshoot syncs, read logs, publish and update custom connector manifests, run and cancel syncs, and change connection schedules. Airbyte Cloud users connect to the hosted server at https://mcp.airbyte.com/mcp and sign in with OAuth, while Airbyte Core deployments use a self-managed setup that runs locally against the deployment's API.
Licensing is split, and the badge says so
The repository metadata reports the licence as NOASSERTION, which is the signal that GitHub could not map the project to a single SPDX identifier. The README explains why: two licence badges appear side by side, one reading MIT and one reading ELv2, both linking to docs/project-overview/licenses in the repository. In other words, the project is not under one licence, and the directory it points to is the place where the split is documented.
For an adopter this is the single most consequential non-technical detail. MIT and ELv2 are not interchangeable. ELv2 is a source-available licence with restrictions that MIT does not carry, and the practical question for a company is which files, connectors, or components fall under which. The licence directory the badges link to is where that mapping is documented. This is not legal advice, and the right move is to have whoever handles open-source review read that directory rather than the badges.
Where Airbyte is the wrong tool
Airbyte is presented as a data movement platform for ELT pipelines and agent context, not as a streaming system. Nothing in the README's getting-started section promises sub-second latency or continuous replication semantics. If your requirement is a low-latency feed where every row must arrive in order and immediately, an ELT sync platform is a mismatch, and you should be looking at a log-based replication tool instead.
The second limitation is operational. The self-hosted path means you run the platform, and the README's getting-started section links to an external quickstart rather than describing resource requirements, upgrade procedures, or a supported version matrix. The release cadence is roughly every two months across v1.7.0, v1.8.0, and v2.0.0, which tells you upgrades are a recurring event rather than a one-off. A team without someone who owns that platform will find Cloud cheaper than the engineering time.
The third is scope creep. The README now covers both ELT and agent access, and some agent features, such as the context layer for direct reads and search, are available only in Airbyte Cloud. A team running Airbyte Core purely for warehouse loading should not assume every agent feature in the README applies to its deployment.
The alternative worth comparing: writing connectors yourself
The realistic alternative for a team with a handful of sources is a small set of hand-written Python jobs, typically scheduled by the same Airflow or Dagster instance the README already names as an orchestration target. The difference is where the work sits. With hand-written jobs you own extraction, schema drift handling, retry logic, and state; Airbyte moves that into a connector abstraction and a platform UI, at the cost of running and upgrading the platform.
The trade-off flips on connector count. For two sources, a hand-written script is less machinery. For twenty long-tail sources, the Connector Builder and the CDK are the argument, because the marginal cost of the twenty-first connector is a config file rather than a new codebase. The low-code CDK is the specific mechanism that makes that claim testable: if the source you need can be expressed in the config-based format, the trade-off favours Airbyte, and if it cannot, you are back to writing a connector anyway.
Maintenance, releases, and what to verify before you commit
The repository has three releases in roughly a year: v1.7.0 in June 2025, v1.8.0 in August 2025, and v2.0.0 in October 2025, with the repository last pushed in November 2026 and not archived. A major version bump inside that window is the thing to plan for. Anyone pinning to a v1.x release should read the v2.0.0 release notes before upgrading.
The contributing guide adds a practical detail that affects anyone planning to patch a connector upstream: pull requests must be opened from a fork in a personal GitHub account rather than an organization account, and the branch must allow edits from maintainers. That is an unusual constraint, and it means a corporate fork workflow will need adjusting if you intend to send fixes back.
What to verify first, concretely: open the connector registry report and confirm your sources are listed for the edition you intend to run; read docs/project-overview/licenses to establish which parts are MIT and which are ELv2; and read the v2.0.0 release notes if you are starting from a v1.x deployment. Those three checks are cheap and they are the ones the README leaves to external pages.
Editorial conclusion
Adopt Airbyte if you need many long-tail API and database sources landing in a warehouse or lake and you are willing to run the self-hosted platform or pay for Cloud. Do not adopt it as a general-purpose streaming engine or as a replacement for a CDC tool on a high-frequency transactional feed; the README frames it around ELT syncs, not continuous replication. Before committing, verify two things in the repository itself: which licence file covers the specific connectors you plan to use, since the badge advertises both MIT and ELv2, and whether the connectors you need appear in the connector registry report rather than only in the marketing catalogue count.
Frequently asked questions
Is Airbyte ETL or ELT?
The project describes itself as open-source data movement for ELT pipelines and AI agents, from APIs, databases and files to warehouses, lakes and AI applications. Syncs can be orchestrated with Airflow, Dagster, Kestra or the Airbyte API.
What is Airbyte vs airflow?
The README lists Airflow as one of the tools for orchestrating Airbyte syncs, alongside Dagster, Kestra and the Airbyte API. The division of labour it describes is that Airbyte moves data between sources and destinations while the orchestrator decides when the syncs run.
Is Airbyte free to use?
Airbyte Core is the self-hosted option in this repository, and Airbyte Cloud is a separate hosted offering. The repository carries LICENSE and LICENSE_SHORT at the root plus a docs/project-overview/licenses directory, while its license field reads NOASSERTION, so the terms to check live in those files rather than in a single standard label.
how to install airbyte in docker
The README's getting-started section contains no Docker or docker compose command. It links to a deployment guide at https://docs.airbyte.com/quickstart/deploy-airbyte for Airbyte Core, and the repository shows docker-images/ as a directory of build inputs.
what is airbyte used for
Airbyte is described as open-source data movement for ELT pipelines and AI agents, carrying data from APIs, databases and files to warehouses, lakes and AI applications through a catalog of 700+ connectors. It also offers the Airbyte MCP, through which AI agents can build and manage pipelines, and, in Airbyte Cloud only, a context layer that lets agents read live data from supported sources.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/airbytehq-airbyte)Star history chart for your README
[](https://hysenlabs.com/projects/airbytehq-airbyte)Was this useful?