AutoScraper: Learning Scraping Rules from a Sample Instead of Writing Selectors
A Smart, Automatic, Fast and Lightweight Web Scraper for Python
At a glance
- What is it?
- AutoScraper is an MIT-licensed Python library that takes a URL plus a list of sample values, learns matching rules from the page, and reuses them on other pages. It is a good fit for stable, server-rendered pages and a poor fit for anything that needs a parser you can reason about.
- Who is it for?
- Adopt AutoScraper when the target page is server-rendered, the fields you want can be named by pasting one real example of each, and you are willing to re-run build() whenever the site changes. Do not adopt it for JavaScript-rendered pages, for sites you must scrape at scale with retries and throttling, or where you need a selector you can read and debug by hand.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 109 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
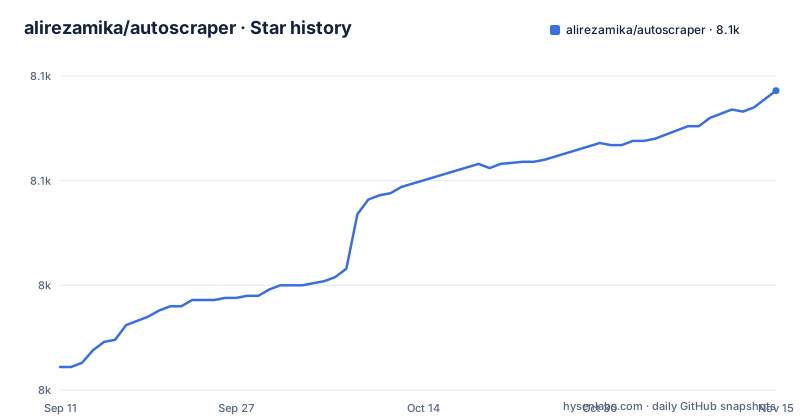
Star history
- alirezamika/autoscraper8,093 ★ · +132
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| alirezamika/autoscraper | 8k | 8.1k |
132 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem AutoScraper solves: writing selectors before you know the page
Most Python scraping starts with a manual step. You open the page, inspect the DOM, guess a CSS selector or XPath, run it, find it matches twelve extra elements, and iterate. AutoScraper inverts that. You supply one or more sample values that already exist on the page, and the library derives the matching rule for you. The README frames the input as "a list of sample data which we want to scrape from that page" and states that this data "can be text, url or any html tag value of that page." The intended user is someone who knows what the output should look like but does not want to reverse-engineer the markup to get there. That is a reasonable position for one-off extraction jobs, for internal tools, and for pages whose class names are hashed or meaningless. It is a weaker position when the page is a core dependency and you need a selector you can read, version-control and explain to a colleague.
How build() turns a sample into a rule
The flow has two phases. First, build() fetches the page (or accepts raw HTML through the html parameter, as the README notes) and searches for the sample values you passed in wanted_list. From the positions where those values were found, it infers a set of rules that describe the surrounding structure. Second, get_result_similar() or get_result_exact() applies the learned rules to a new URL. The README's Stack Overflow example is the clearest illustration: you pass a single title, "What are metaclasses in Python?", and build() returns a list of nine related question titles from the same page, including the one you supplied. The library did not just find your sample; it generalised from it to sibling elements. get_result_exact() behaves differently. In the Yahoo Finance example, the wanted_list contains a price like "124.81" and get_result_exact() is used to pull the same field from a different ticker page. The README also states that if you append more values to wanted_list, get_result_exact() "will retrieve the data as the same exact order in the wanted list," which makes it usable for building a fixed-width row of fields rather than a bag of matches.
Getting it installed and running the two-argument example
Installation is a single pip command: pip install autoscraper. The README also documents installing from the git repository with pip install git+https://github.com/alirezamika/autoscraper.git and from source with python setup.py install. The minimal script is short. Import AutoScraper, set url and wanted_list, instantiate the scraper, and call scraper.build(url, wanted_list). The README's Stack Overflow example uses exactly that shape and prints a list of question titles. To reuse the learned rules on another page, call scraper.get_result_similar('https://stackoverflow.com/questions/606191/convert-bytes-to-a-string') for sibling-style matching, or scraper.get_result_exact(...) when you need the same field position. One detail worth noting: the README warns that in the Yahoo Finance example you "should update the wanted_list if you want to copy this code, as the content of the page dynamically changes." That is not a throwaway remark. The sample value is the training signal, so a stale sample produces a rule built against content that no longer exists.
Passing proxies and headers through request_args
AutoScraper delegates fetching to the requests library and exposes its parameters. The README shows a proxies dictionary with http and https keys passed as request_args=dict(proxies=proxies) into build(). The same mechanism is how you would add custom headers. This matters more than it first appears. Many sites return different HTML to a default Python user agent, and if build() learns rules from a stripped-down or blocked response, the rules will not match the real page. Because request_args is a plain dict forwarded to requests, anything requests accepts should be passable here. The README names custom headers as a use but only shows proxies in its code example.
Saving and loading the learned model
Once a scraper is built, scraper.save('yahoo-finance') writes the learned rules to a path you choose, and scraper.load('yahoo-finance') restores them. The README gives no format details, no schema, and no versioning guidance for the saved file. That is a real gap if you plan to check the model into a repository or ship it inside a package: you have no documented way to know whether a model saved by one version of the library will load correctly in another. The practical consequence is that the saved model is a build artifact tied to the library version that produced it, and any upgrade of autoscraper should be followed by re-running build() against a live page to confirm the rules still resolve. The release history is thin on this point: the most recent release listed is v1.1.14 from July 2022, with v1.1.12 and v1.1.11 before it.
Where AutoScraper breaks: dynamic pages, scale, and unreadable rules
The library operates on HTML it can fetch with requests. It has no browser engine, so anything rendered client-side by JavaScript will not be in the response and cannot be learned from. The README's own Yahoo Finance example is a hint here: the note that page content "dynamically changes" and that wanted_list must be updated is exactly the kind of instability that makes sample-based learning fragile. A second limitation is scale. The README documents no queue, no retry policy, no rate limiting and no concurrency model. If you need to crawl thousands of pages politely, you are building that layer yourself around AutoScraper calls. A third issue is debuggability. Because the rules are inferred rather than written, a wrong result gives you a list of wrong strings and no selector to inspect. When get_result_similar() returns neighbours you did not want, the fix is usually to add more sample values to wanted_list, not to edit a rule. That is a different debugging loop from the one most engineers are used to.
Compared with BeautifulSoup and Scrapy
The nearest alternative for the extraction step is BeautifulSoup. With BeautifulSoup you write soup.select('.some-class') and you get exactly what the selector matches. With AutoScraper you pass a sample and accept whatever rule the library infers. The trade is explicit: BeautifulSoup gives you a selector you can read, test and reason about, at the cost of inspecting the markup first. AutoScraper skips the inspection but hands you a rule you cannot read. For a page you will scrape once, that is a good trade. For a page you will scrape daily for a year, a hand-written selector that breaks visibly is often easier to maintain than an inferred rule that breaks quietly by returning a slightly different list. Scrapy sits at a different level entirely: it is a crawling framework with scheduling, middleware and pipelines, and AutoScraper could in principle be used inside a Scrapy spider for the extraction step. Choosing between them is choosing between a framework and a parsing helper, not between two parsers.
Licence, maintenance and what to verify before adopting
AutoScraper is MIT-licensed, which permits commercial use, modification and redistribution provided the copyright notice and permission notice are retained. That is a permissive licence and imposes no copyleft obligation on your own code. This is a description of the licence text, not legal advice; if the licence terms matter to your organisation, have counsel review them. On maintenance: the repository is not archived, and the most recent release is v1.1.14 from July 2022, so the release cadence is slow. That is not disqualifying for a small library with a narrow job, but it does mean you should not expect the saved-model format or the inference behaviour to be actively stabilised. The concrete thing to verify before adopting is behaviour on your own target page, not the README's examples. Run build() with a single sample value and check whether the returned list contains the sample plus the neighbours you actually want. Then run get_result_exact() with a multi-value wanted_list and confirm the output order matches the input order, since the README states that ordering is guaranteed for that method. Finally, save() and load() the model and confirm the loaded object produces the same results without re-fetching the original page.
Editorial conclusion
Adopt AutoScraper when the target page is server-rendered, the fields you want can be named by pasting one real example of each, and you are willing to re-run build() whenever the site changes. Do not adopt it for JavaScript-rendered pages, for sites you must scrape at scale with retries and throttling, or where you need a selector you can read and debug by hand. Before committing, verify three things on your own target: that build() returns the sample value itself plus the neighbours you expected, that get_result_exact() returns fields in the same order as your wanted_list, and that save()/load() round-trips without the library re-fetching the page.
Frequently asked questions
How does AutoScraper work?
You hand it a page, either a URL or raw html, and a wanted list of values you know appear on it. It learns the rule that produced those values and returns similar elements from the page. The same learned object then answers new pages, with get_result_similar for neighbours and get_result_exact for the same values in the order of your wanted list.
How do I install AutoScraper?
Three ways are given: pip install autoscraper from PyPI, pip install git+https://github.com/alirezamika/autoscraper.git for the latest version from the repository, and python setup.py install from a source checkout. The package declares compatibility with Python 3 and a python_requires of 3.6 or later.
Does AutoScraper need any libraries?
Three, and they are declared in setup.py: requests, bs4 and lxml. Proxies and custom headers are passed through to the requests layer using request_args, for example build(url, wanted_list, request_args=dict(proxies=proxies)). The README mentions no retry or rate limiting option of its own.
Can I reuse an AutoScraper model?
Yes, and that is what save and load are for. scraper.save('yahoo-finance') writes the built model under a name and scraper.load('yahoo-finance') loads it back, so the learned rules survive the process instead of being rebuilt on every run. The format and any version compatibility are not described.
Why does my AutoScraper wanted list go out of date?
Because the exact-result path matches values that move. The README's own example scrapes a live stock price and notes that you should update the wanted list if you copy the code, since the page content dynamically changes. Append more values to the wanted list to get more fields back, in the same order.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/alirezamika-autoscraper)Star history chart for your README
[](https://hysenlabs.com/projects/alirezamika-autoscraper)Was this useful?