StarRocks: FE, BE, and what to verify before adopting
The world's fastest open query engine for sub-second analytics both on and off the data lakehouse. With the flexibility to support nearly any scenario, StarRocks provides best-in-class performance for multi-dimensional analytics, real-time analytics, and ad-hoc queries. A Linux Foundation project.
At a glance
- What is it?
- StarRocks is a two-module Java query engine that claims sub-second ad-hoc analytics over MySQL-protocol connections and direct reads of Hive, Iceberg, Delta Lake, and Hudi files. It is an Apache-2.0 Linux Foundation project.
- Who is it for?
- Adopt StarRocks when you want primary key upserts and lakehouse reads without copying data, and you are willing to treat automatic materialized view selection and per-cluster resource limits as things to verify rather than assume. Do not adopt it if you need resource isolation across separate clusters.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
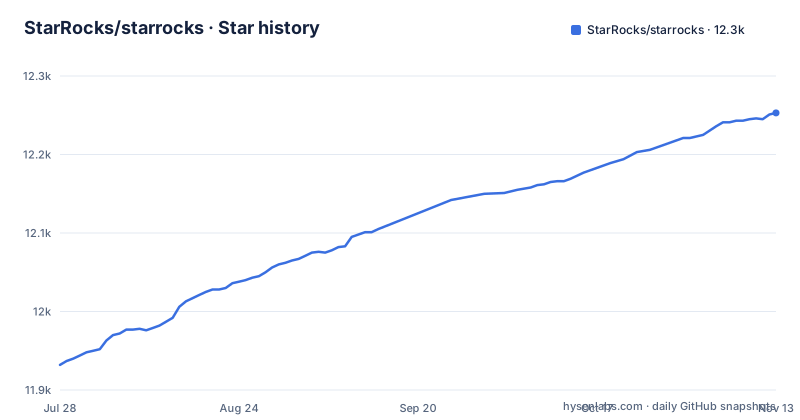
- StarRocks/starrocks12,253 ★ · +321
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| StarRocks/starrocks | 11.9k | 12.3k |
321 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two modules, and a shared-data mode that only exists from version 3.0
StarRocks describes its architecture as two modules, Frontend and Backend, and its claim of no single points of failure rests on horizontal scaling of both plus separate replication of metadata and data. Starting from version 3.0 there is also a shared-data architecture, offered as better scalability and lower cost. The recovery claim is equally qualitative: data replicas come back automatically under node failure.
ANSI SQL over the MySQL protocol, which is not a MySQL base
Two compatibility claims sit beside each other and are easy to conflate. The first is ANSI SQL, with TPC-H and TPC-DS described as fully supported. The second is the MySQL protocol, which is why various clients and BI software can reach a StarRocks cluster without a bespoke driver. Protocol compatibility is a transport statement: it explains why a client handshake succeeds and a session opens. It says nothing about dialect coverage, so SQL that leans on engine-specific MySQL behavior is not covered by the fact that a connector connects. The ANSI claim is the one that constrains what you can actually run. The consequence for a reader is that getting tools attached is the cheap half and validating statements is the real work.
Primary key upserts run while queries read the same table
Engines positioned for analytics usually treat a table as immutable and solve duplicate updates by pre-aggregating them away. StarRocks takes a different route. Its primary key model performs upsert and delete operations according to the primary key, and the project states it keeps queries efficient while concurrent updates are in flight. The README separately says StarRocks eliminates the need for denormalization.
Lakehouse tables are read in place, so the external system owns freshness
StarRocks queries Apache Hive, Apache Iceberg, Delta Lake, and Apache Hudi data directly, and the operative phrase is without importing. No copy step means files stay where they are and StarRocks reads them, which removes both the ingest job and the duplicate storage a mirrored serving table would demand. The consequence of choosing no copy is that some costs move outside StarRocks. Correctness then depends on the lakehouse side, where partition layout, file compaction, and schema evolution all happen. Plan connector configuration as its own project rather than a config line.
Materialized views refresh on import and the optimizer picks them for you
The materialized view here is not something you remember to refresh. It is updated during data import, and at query time it is selected automatically, which means the optimizer can route a query to a view you never named in the statement. That is convenient when an expensive dashboard query has a matching view, and it is a surprise while profiling, because the plan you wrote and the plan that ran may differ in shape, and the view also consumes storage that someone must size and monitor.
Resource isolation is scoped to one cluster
Resource management is stated as two capabilities: limiting resource consumption for queries, and isolating resources between tenants in the same cluster. Read that scope literally, because the word doing the work is same. Isolation is a within-cluster property, so it separates one team's queries from another's on shared hardware, and it does nothing for two separate clusters. There is a scale interaction the feature list leaves implicit as well, since the system is said to balance resources when the cluster is scaled in or out: a query admitted under one cluster size can meet a different resource picture after a resize. Get the accounting model in writing before promising isolation to a tenant.
The speed numbers name no baseline
Two performance claims appear in the README and neither states what it was measured against. One says average query performance runs 3x faster than other popular alternatives, and a feature entry says vectorization delivers sub-second multi-dimensional analysis at 5 to 10 times the speed of previous systems. Neither ratio is tied to a dataset, a hardware shape, a concurrency level, or a named competitor. The comparison material lives off the code, at starrocks.io/blog/benchmark-test, with a separate demo repository offered as StarRocks/demo, so checking a claim means leaving the source tree. Treat the multiples as unverified until a published benchmark shape matches your own data. The mechanisms underneath them are at least concrete: vectorized execution that uses the parallel computing power of the CPU, and a cost based optimizer that rewrites complex queries, both of which you can read in the source.
Two release lines ship at once, and the build lives in script files
Recent releases show more than one line advancing: 3.5.21 on 2026-08-31, then 4.1.6 and 4.1.7 on 2026-11-03, with the most recent push landing 2026-11-02. Choose a line deliberately instead of inheriting one. Building is likewise handed to files instead of inline instructions. The top level carries build.sh, build-in-docker.sh, Makefile.docker, docker-dev.sh, and docker-compose.dev.yml for development, plus run-fe-ut.sh, run-be-ut.sh, and run-java-exts-ut.sh for frontend, backend, and Java extension unit tests. Three documented entry points exist: an IDE setup guide, a build inside Docker, and a manual deployment guide. Supporting structure surrounds them, including thirdparty/, gensrc/, nix/ with flake.nix, an .envrc, format-sdk/, packaging/, webroot/, and both .clang-format and .clang-tidy.
Editorial conclusion
Adopt StarRocks when you want primary key upserts and lakehouse reads without copying data, and you are willing to treat automatic materialized view selection and per-cluster resource limits as things to verify rather than assume. Do not adopt it if you need resource isolation across separate clusters. Before deploying, pin a release line, read the deployment docs for the 3.0 shared-data mode, and reproduce the benchmark claims against your own data.
Frequently asked questions
What are StarRocks used for?
Sub-second ad-hoc analytics on and off the data lakehouse, covering multi-dimensional analysis, real-time analysis, and ad-hoc queries. It reads Apache Hive, Apache Iceberg, Delta Lake, and Apache Hudi data directly, without importing it.
Is StarRocks better than ClickHouse?
The project claims average query performance 3x faster than other popular alternatives without naming them, and hosts its comparison material at starrocks.io/blog/benchmark-test.
Is StarRocks based on MySQL?
It speaks the MySQL protocol and supports ANSI SQL with fully supported TPC-H and TPC-DS, which is how clients and BI software connect.
what is tablet in starrocks
The README architecture section says the system has Frontend and Backend modules, replicates metadata and data, supports horizontal scaling of both, and recovers a data replica automatically under node failure.
is starrocks open source
Yes. It is licensed under the Apache License 2.0, the repository carries LICENSE.txt and NOTICE.txt alongside licenses/ and licenses-binary/, and the project is described as a Linux Foundation project.
how to install starrocks
The README points to the community download page at starrocks.io/download/community, to the deployment documentation at docs.starrocks.io, and to a manual deployment guide.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/starrocks-starrocks)Star history chart for your README
[](https://hysenlabs.com/projects/starrocks-starrocks)Was this useful?